
mparticle-android-sdk
mParticle
68stars
mParticle SDK for Android apps
Store, explore, and understand your data.
mParticle
mParticle SDK for Android apps

nao1215
loads CSV, TSV, LTSV, JSON, JSONL, Parquet, XLSX, ACH, and Fedwire files into SQLite; includes prep and frame for cleanup and in-memory transforms

ndrean
A bidirectional, local-first sync engine between Postgres and edge SQLite/PGLITE/Postgres/DuckDB clients over NATS

nestjs
Sequelize module for Nest framework (node.js) 🍈

NeuroVision-Studio
NeuraVision — AI content generation platform (PHP backend engine: auth, credits, generation, analytics)

NoelDeMartin
Javascript Active Record library

notesjor
Korpuslinguistik war noch nie so einfach...

nunomaduro
💨 Provides a good starting point for production-ready SQLite databases

OgreTitansmith
Agentic video editing engine/skill/plugin

openfoodfacts
An open database of prices 🧾💸💰🏷️🤑🍽️

opensearch-project
Query your data using familiar SQL or intuitive Piped Processing Language (PPL)

opensnowcat
OpenSnowcat Collector, an open source fork of Snowplow (Apache 2.0 License)
opensnowcat
OpenSnowcat Enricher (Apache 2.0 License)

orlandos-nl
Native MongoDB driver for Swift, written in Swift

OWOX
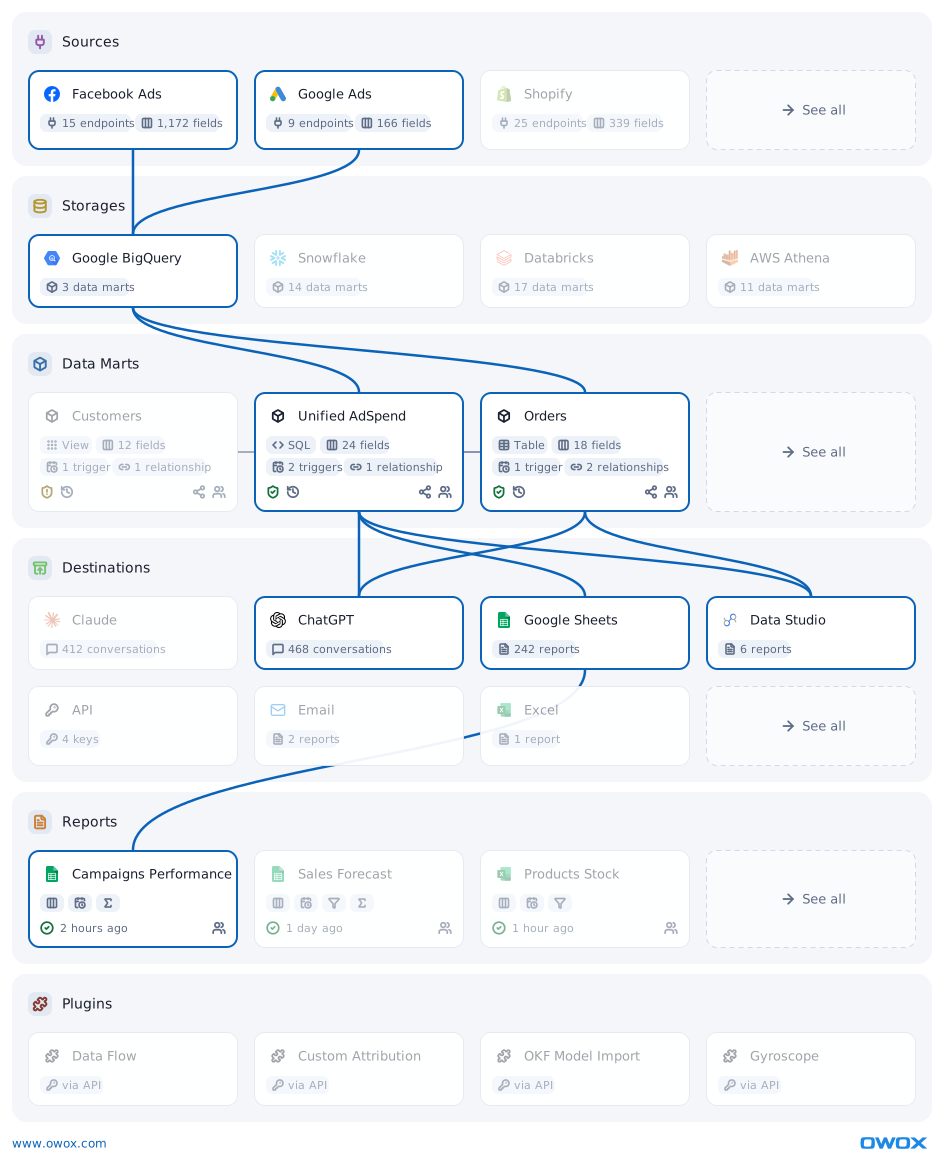
Open-Source Self-Service Analytics Platform

pganalyze

pganalyze statistics collector for gathering PostgreSQL metrics and log data

pivotlake
Pivot is a high-performance real time analytics database on open data formats.

pnyn96
MindAct: Community-Driven AI Agent for Claude, Obsidian, and RAG Knowledge Graphs

pudo
Easy-to-use data handling for SQL data stores with support for implicit table creation, bulk loading, and transactions.

raphaelmansuy
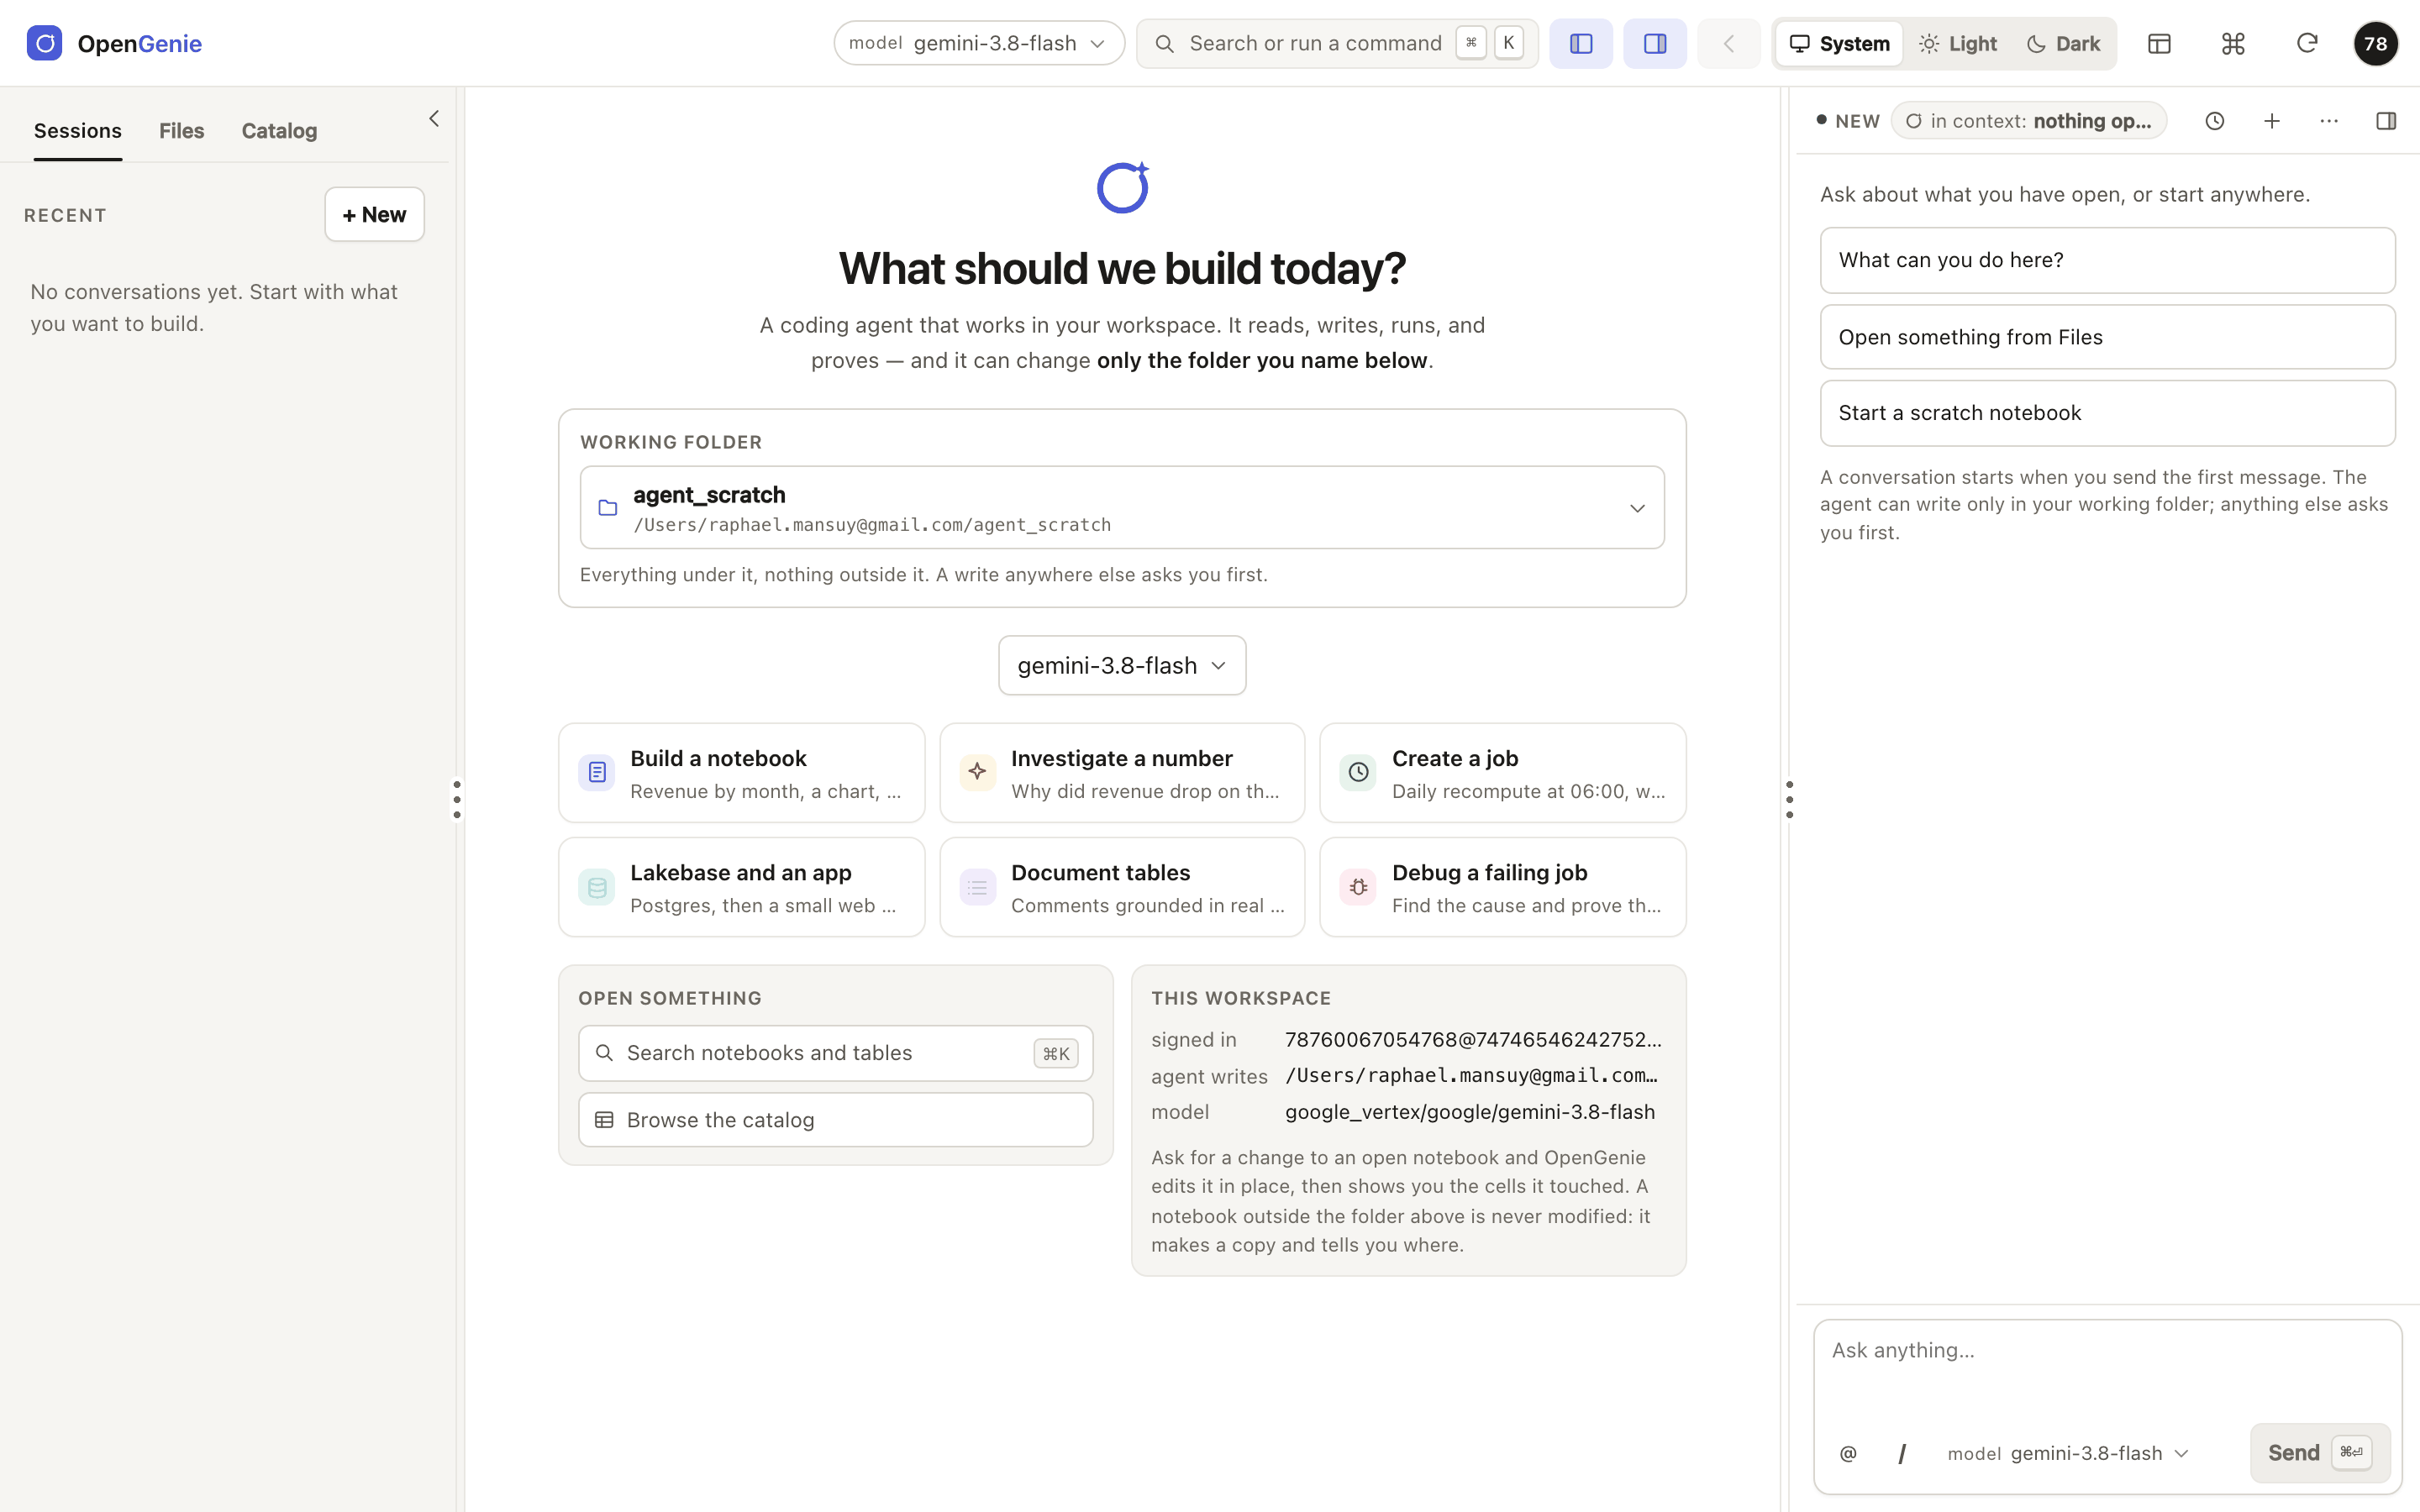
Open-source Databricks App hosting a coding agent that sees your workspace — Unity Catalog, SQL warehouses, notebooks, jobs — on the model you choose. Genie Code's context, your choice of model and bill.

raptodb
For engineers seeking an in-memory key-value database, Rapto provides predictable performance, cache-aware design, and low memory usage through an event-driven runtime.

rasinmuhammed
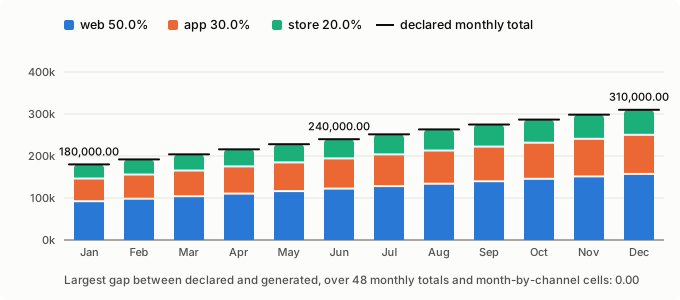
Declarative synthetic data for Python. State the facts a dataset must hold (monthly revenue, channel shares, balanced ledgers, foreign keys, state machines) and get multi-table data that holds them exactly, with a DuckDB certificate anyone can rerun. From YAML, SQL DDL or a sentence. CLI and MCP server.

realdatadriven
ETL / ELT / Reverse ETL Framework powered by DuckDB, designed to seamlessly integrate and process data from diverse sources. It leverages Markdown as a configuration medium, where YAML blocks define metadata for each data source, and embedded SQL blocks specify the extraction, transformation, and loading logic.

rezer-bleede
Open-source, self-hosted dbt control plane for data lineage, orchestration, and catalog management. Built for local, on-prem, and air-gapped deployments.