
pivotlake/pivot
pivotlake/pivot has 174 GitHub stars and 12 forks. Star changes are not measured yet. Last checked 2026-11-12 08:07 UTC. Last push 2026-11-11.
Pivot is a high-performance real time analytics database on open data formats.
What you can do
- Fast - Written in Rust and built on state-of-the-art columnar execution techniques, including morsel-driven parallelism, SIMD, NUMA-aware execution, and cache-conscious aggregation and joins, in addition to a few novel additions.
- Scalable - With object storage as its backing store, Pivot can be scaled up, down, or to zero almost instantly.
- Portable - Pivot can run both as a server serving backends and clients, or as a local engine where users and agents query the source of truth directly—allowing local ad-hoc and agentic analytics to share the same engine and architecture as traditional dashboards and in-app analytics
- Open - Pivot is open source and built on open data formats (Delta Lake and Iceberg). This means you can use Pivot with data already stored in your data warehouse, while data ingested by Pivot remains accessible to other query engines.
Measured star growth
- in 24h
- Collecting history
- in 7 days
- Collecting history
- in 15 days
- Collecting history
- in 1 month
- Collecting history
Net star changes over overlapping periods, not daily totals. Missing measurements are left blank. Stars measure attention, not software quality.
README.md
Original


Pivot is a high-performance analytics database that runs on open data formats. It delivers low-latency queries and high concurrency without replicating data into a dedicated real-time analytics database such as ClickHouse / Druid.
Key features
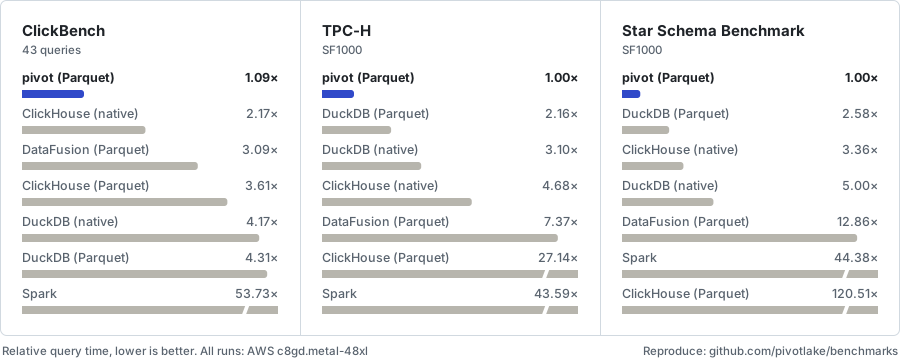
- Fast - Written in Rust and built on state-of-the-art columnar execution techniques, including morsel-driven parallelism, SIMD, NUMA-aware execution, and cache-conscious aggregation and joins, in addition to a few novel additions.
- Scalable - With object storage as its backing store, Pivot can be scaled up, down, or to zero almost instantly.
- Portable - Pivot can run both as a server serving backends and clients, or as a local engine where users and agents query the source of truth directly—allowing local ad-hoc and agentic analytics to share the same engine and architecture as traditional dashboards and in-app analytics
- Open - Pivot is open source and built on open data formats (Delta Lake and Iceberg). This means you can use Pivot with data already stored in your data warehouse, while data ingested by Pivot remains accessible to other query engines.
Getting started
curl https://pivotlake.io | sh
See the Quickstart for Docker, the Debian package and a first query.
[!NOTE] Pivot is in early development and not yet production ready. Expect breaking changes between releases.
Contributing
Contributions are welcome! See CONTRIBUTING.md, and ask questions in Discussions.
License
Licensed under either of the Apache License, Version 2.0 or the MIT license, at your option.
Explore related projects
Asabeneh/30-Days-Of-Python
The 30 Days of Python programming challenge is a step-by-step guide to learn the Python programming language in 30 days. This challenge may take more than 100 days. Follow your own pace. These videos may help too: https://www.youtube.com/channel/UC7PNRuno1rzYPb1xLa4yktw
78,560 starsgrafana/grafana
The open and composable observability and data visualization platform. Visualize metrics, logs, and traces from multiple sources like Prometheus, Loki, Elasticsearch, InfluxDB, Postgres and many more.
77,830 starsredis/redis
For developers, who are building real-time data-driven applications, Redis is the preferred, fastest, and most feature-rich cache, data structure server, and document and vector query engine.
77,395 starsapache/superset
Apache Superset is a Data Visualization and Data Exploration Platform
75,473 stars