
couchdb
apache
7,011스타
Seamless multi-primary syncing database with an intuitive HTTP/JSON API, designed for reliability
데이터베이스, 분석, SQL, 데이터 엔지니어링 프로젝트를 비교하세요.
apache
Seamless multi-primary syncing database with an intuitive HTTP/JSON API, designed for reliability
apache
Apache DataFusion Ballista Distributed Query Engine
apache
Apache DataFusion Iceberg Integration
apache
Extensible SQL Lexer and Parser for Rust
apache
Apache Doris Website
apache
Apache Drill is a distributed MPP query layer for self describing data
apache
Apache flink
apache
Apache flink
apache
Apache flink
Apache flink
apache
Apache flink
apache

Gluten is a middle layer responsible for offloading JVM-based SQL engines' execution to native engines.
apache
Apache Hamilton helps data scientists and engineers define testable, modular, self-documenting dataflows, that encode lineage/tracing and metadata. Runs and scales everywhere python does.
apache
Apache HBase Connectors
apache
Apache Hive
apache
A graph database that supports more than 100+ billion data, high performance and scalability (Include OLTP Engine & REST-API & Backends)
apache
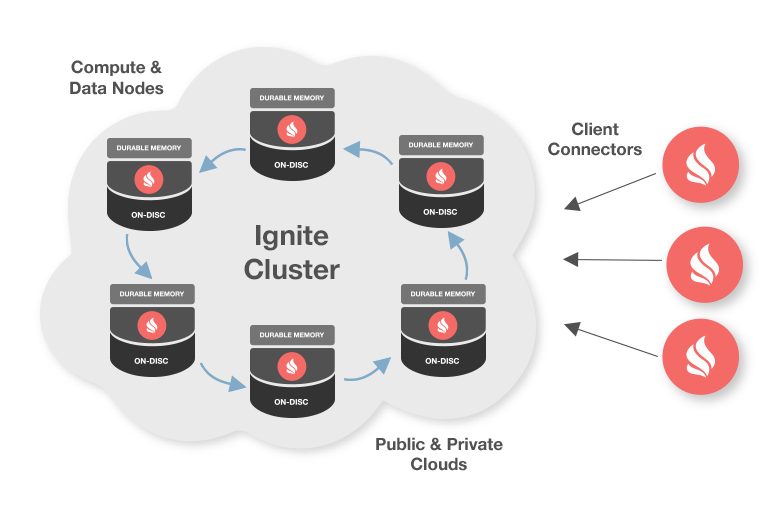
Apache Ignite
apache
Apache Ignite 3
apache
Apache Jackrabbit Oak
apache

Apache Kyuubi is a distributed and multi-tenant gateway to provide serverless SQL on data warehouses and lakehouses.
apache

Apache Linkis builds a computation middleware layer to facilitate connection, governance and orchestration between the upper applications and the underlying data engines.
apache
Apache Phoenix
apache
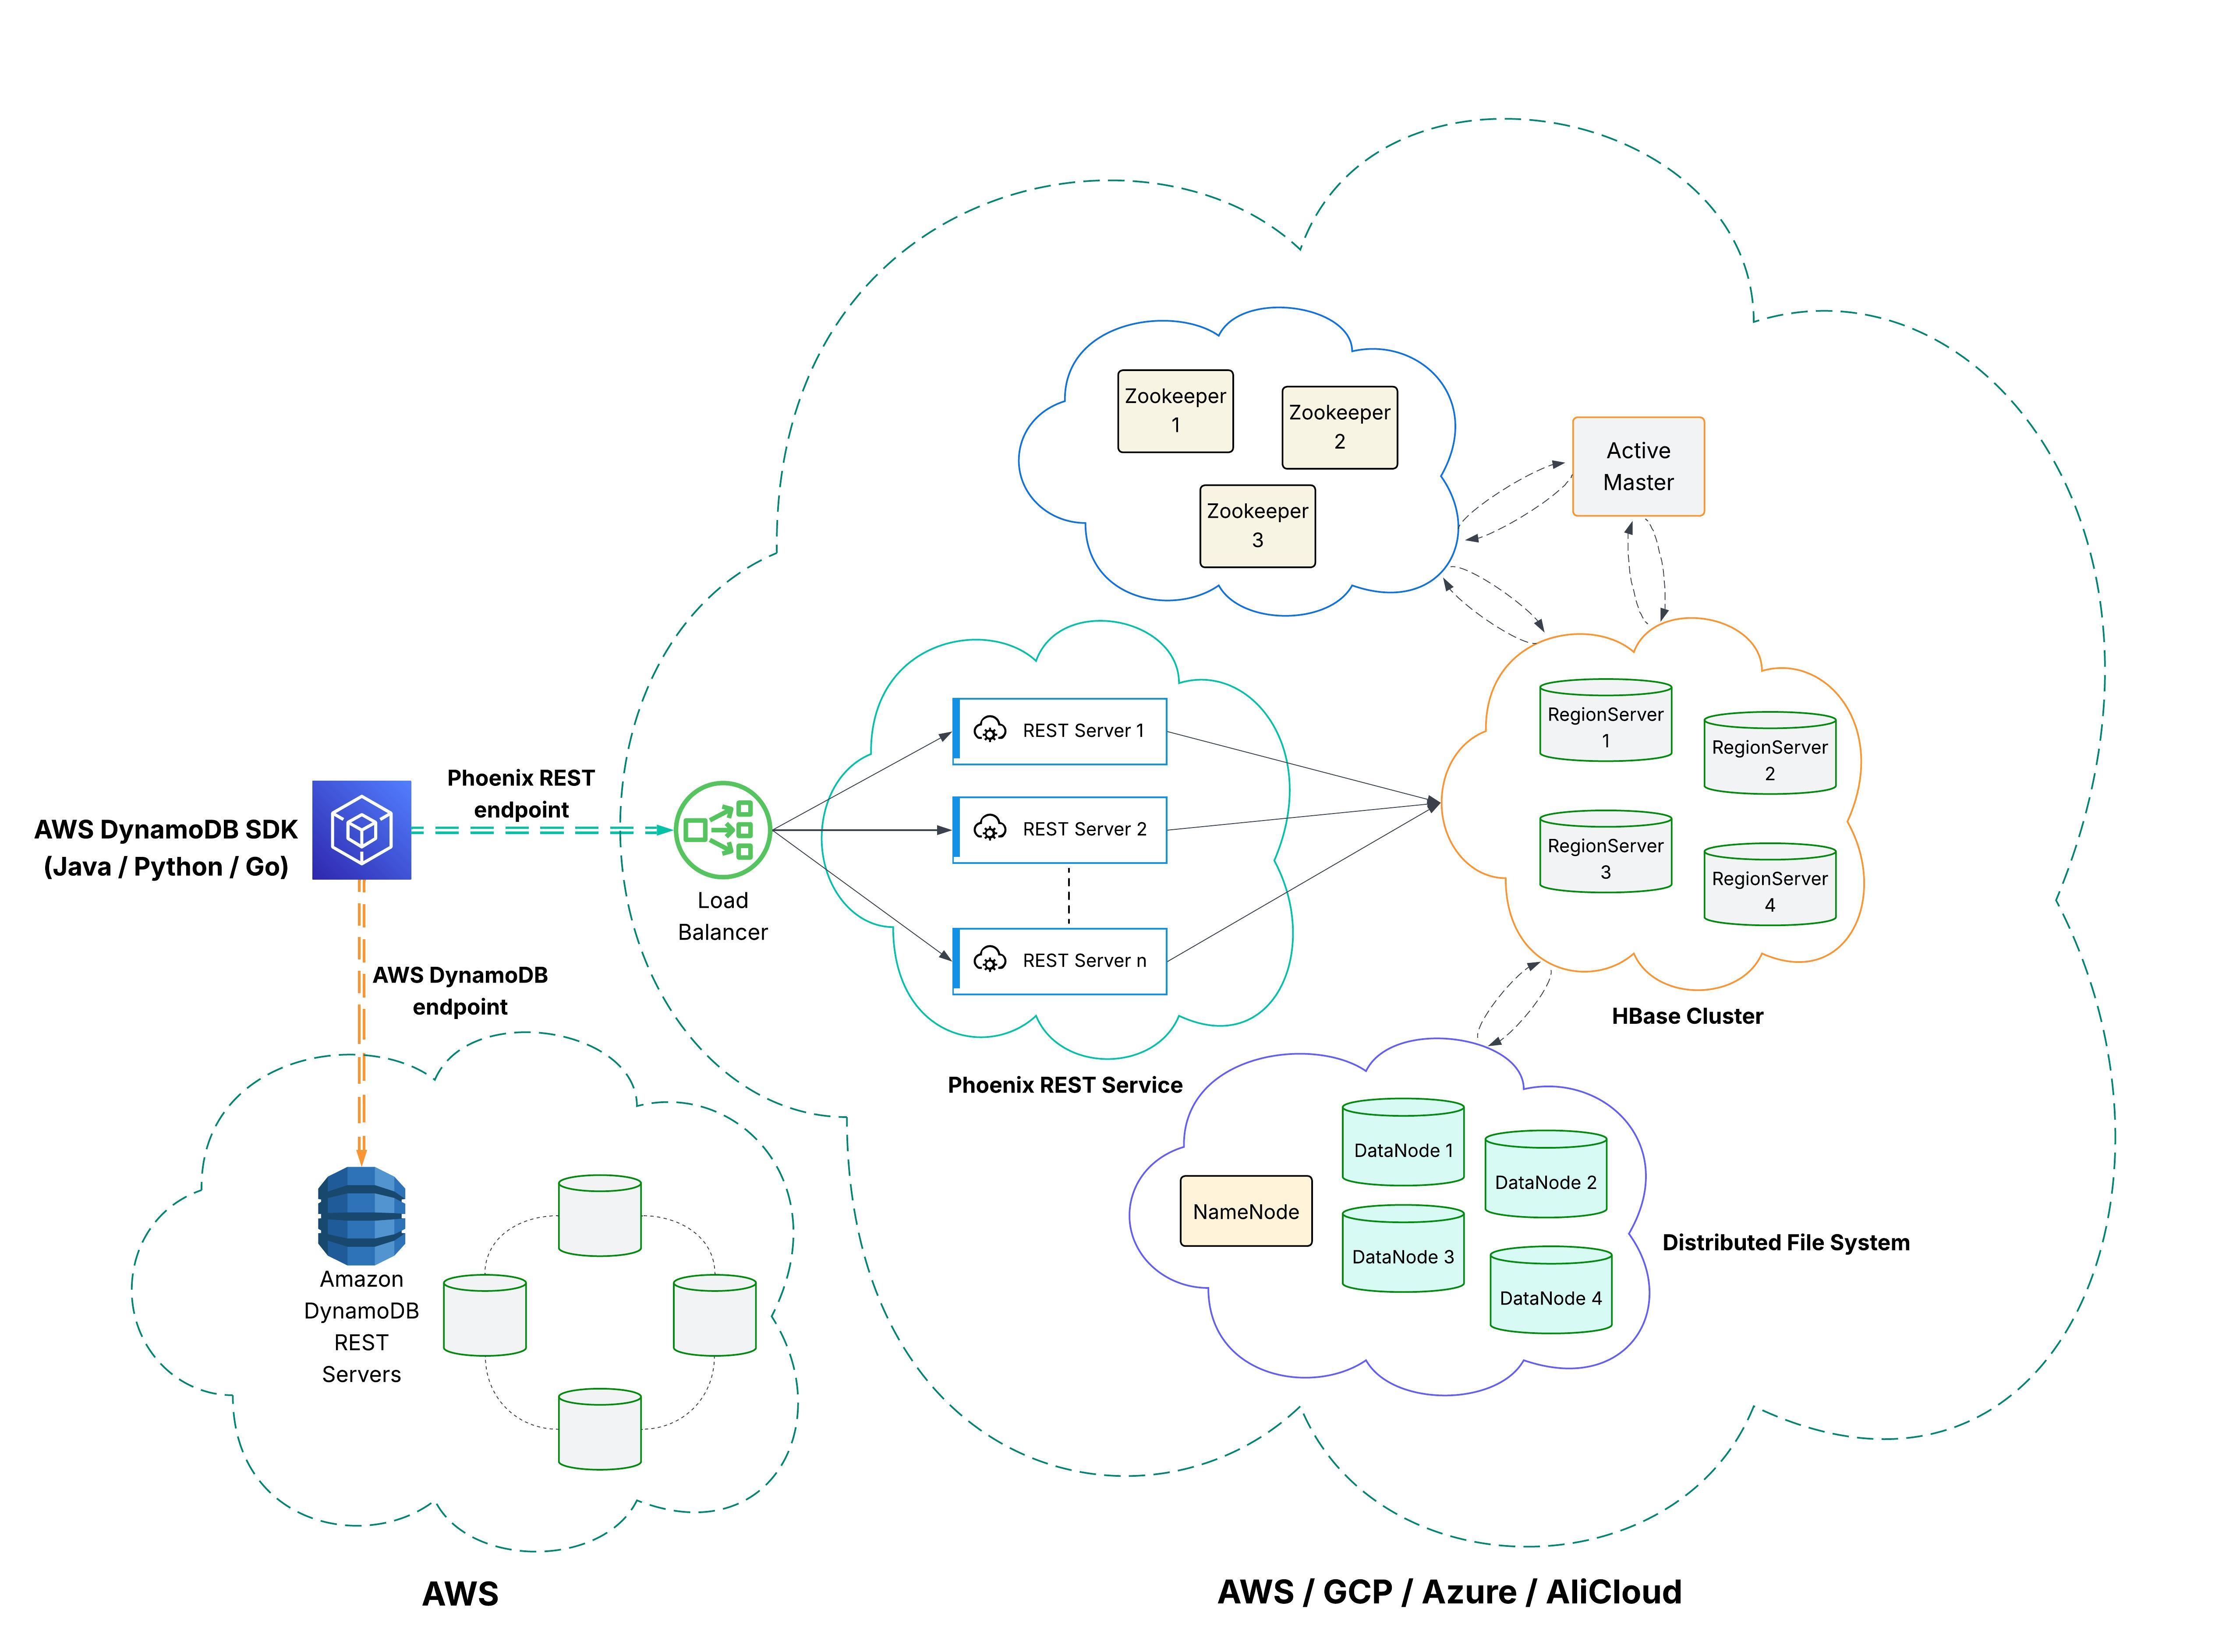
Apache Phoenix Adapters
apache
Apache Phoenix Query Server