
vaexio/vaex
vaexio/vaex has 8,518 GitHub stars and 600 forks. GitHot measured 0 stars in 24 hours and +2 in 7 days. Last checked 2026-11-13 18:42 UTC. Last push 2026-11-06.
What you can do
- Remote DataFrames (documentation coming soon)
- Integration into Jupyter and Voila for interactive notebooks and dashboards
- Machine Learning without (explicit) pipelines
측정된 스타 증가
- in 24h
- 0
- in 7 days
- +2
- in 15 days
- 기록 수집 중
- in 1 month
- 기록 수집 중
서로 겹치는 기간의 순증가량이며 일별 합계가 아닙니다. 측정값이 없으면 비워 둡니다. 스타는 관심도를 나타내며 품질을 보장하지 않습니다.
소개
Out-of-Core hybrid Apache Arrow/NumPy DataFrame for Python, ML, visualization and exploration of big tabular data at a billion rows per second 🚀
머신러닝README.md
Original

What is Vaex?
Vaex is a high performance Python library for lazy Out-of-Core DataFrames
(similar to Pandas), to visualize and explore big tabular datasets. It
calculates statistics such as mean, sum, count, standard deviation etc, on an
N-dimensional grid for more than a billion (10^9) samples/rows per
second. Visualization is done using histograms, density plots and 3d
volume rendering, allowing interactive exploration of big data. Vaex uses
memory mapping, zero memory copy policy and lazy computations for best
performance (no memory wasted).
Installing
With pip:
$ pip install vaex
Or conda:
$ conda install -c conda-forge vaex
For more details, see the documentation
Key features
Instant opening of Huge data files (memory mapping)
HDF5 and Apache Arrow supported.

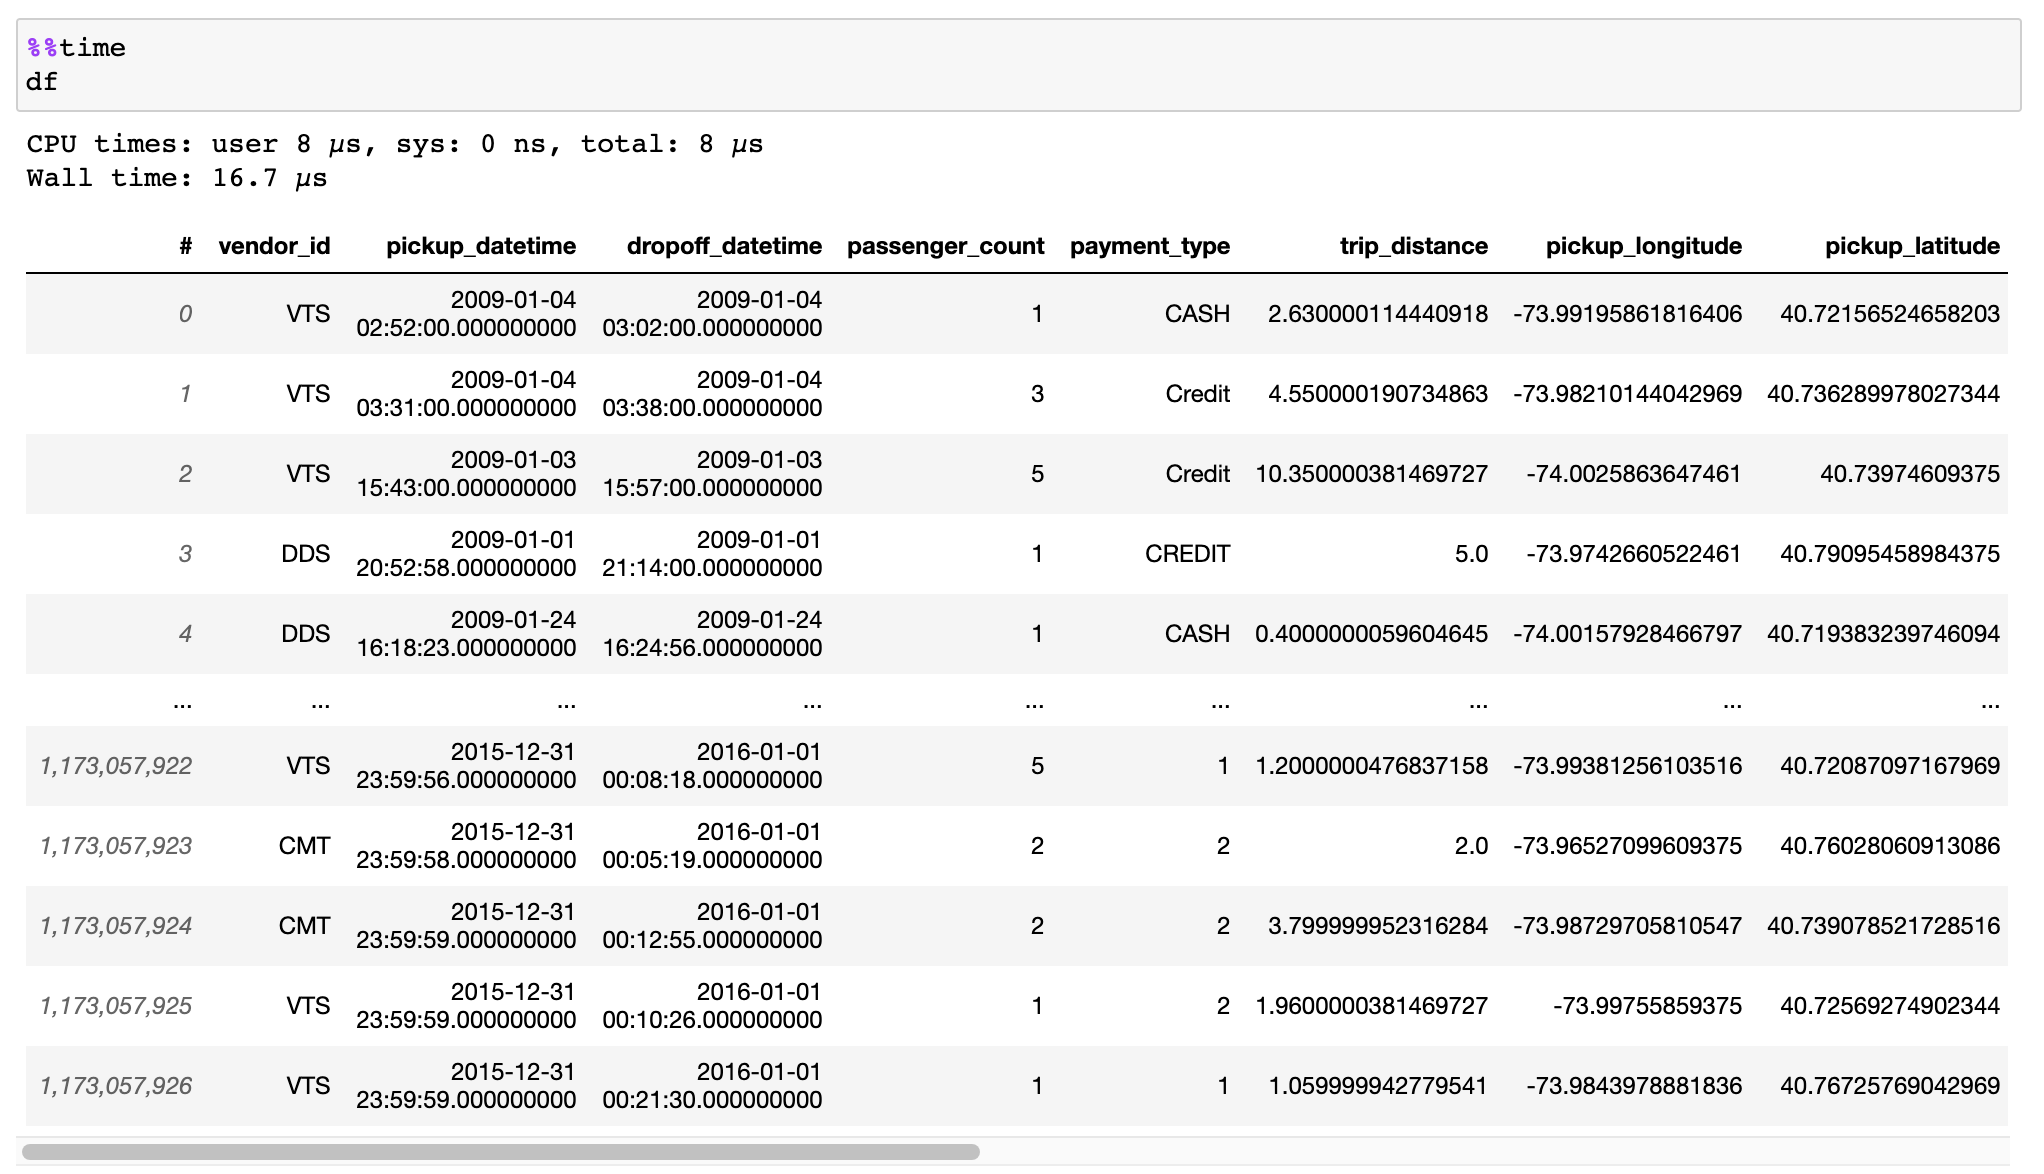
Read the documentation on how to efficiently convert your data from CSV files, Pandas DataFrames, or other sources.
Lazy streaming from S3 supported in combination with memory mapping.

Expression system
Don't waste memory or time with feature engineering, we (lazily) transform your data when needed.
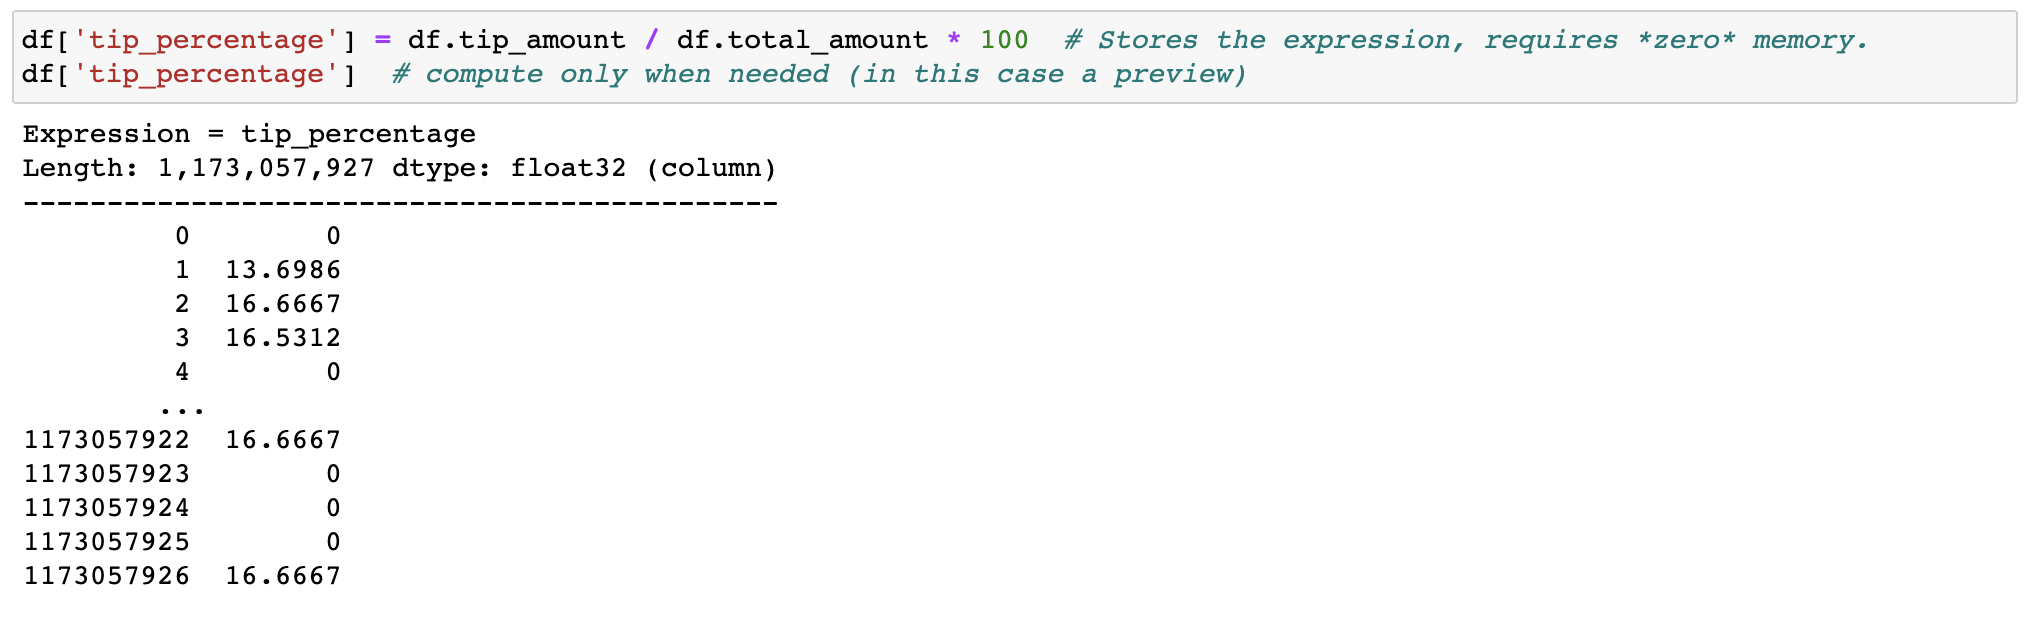
Out-of-core DataFrame
Filtering and evaluating expressions will not waste memory by making copies; the data is kept untouched on disk, and will be streamed only when needed. Delay the time before you need a cluster.

Fast groupby / aggregations
Vaex implements parallelized, highly performant groupby operations, especially when using categories (>1 billion/second).
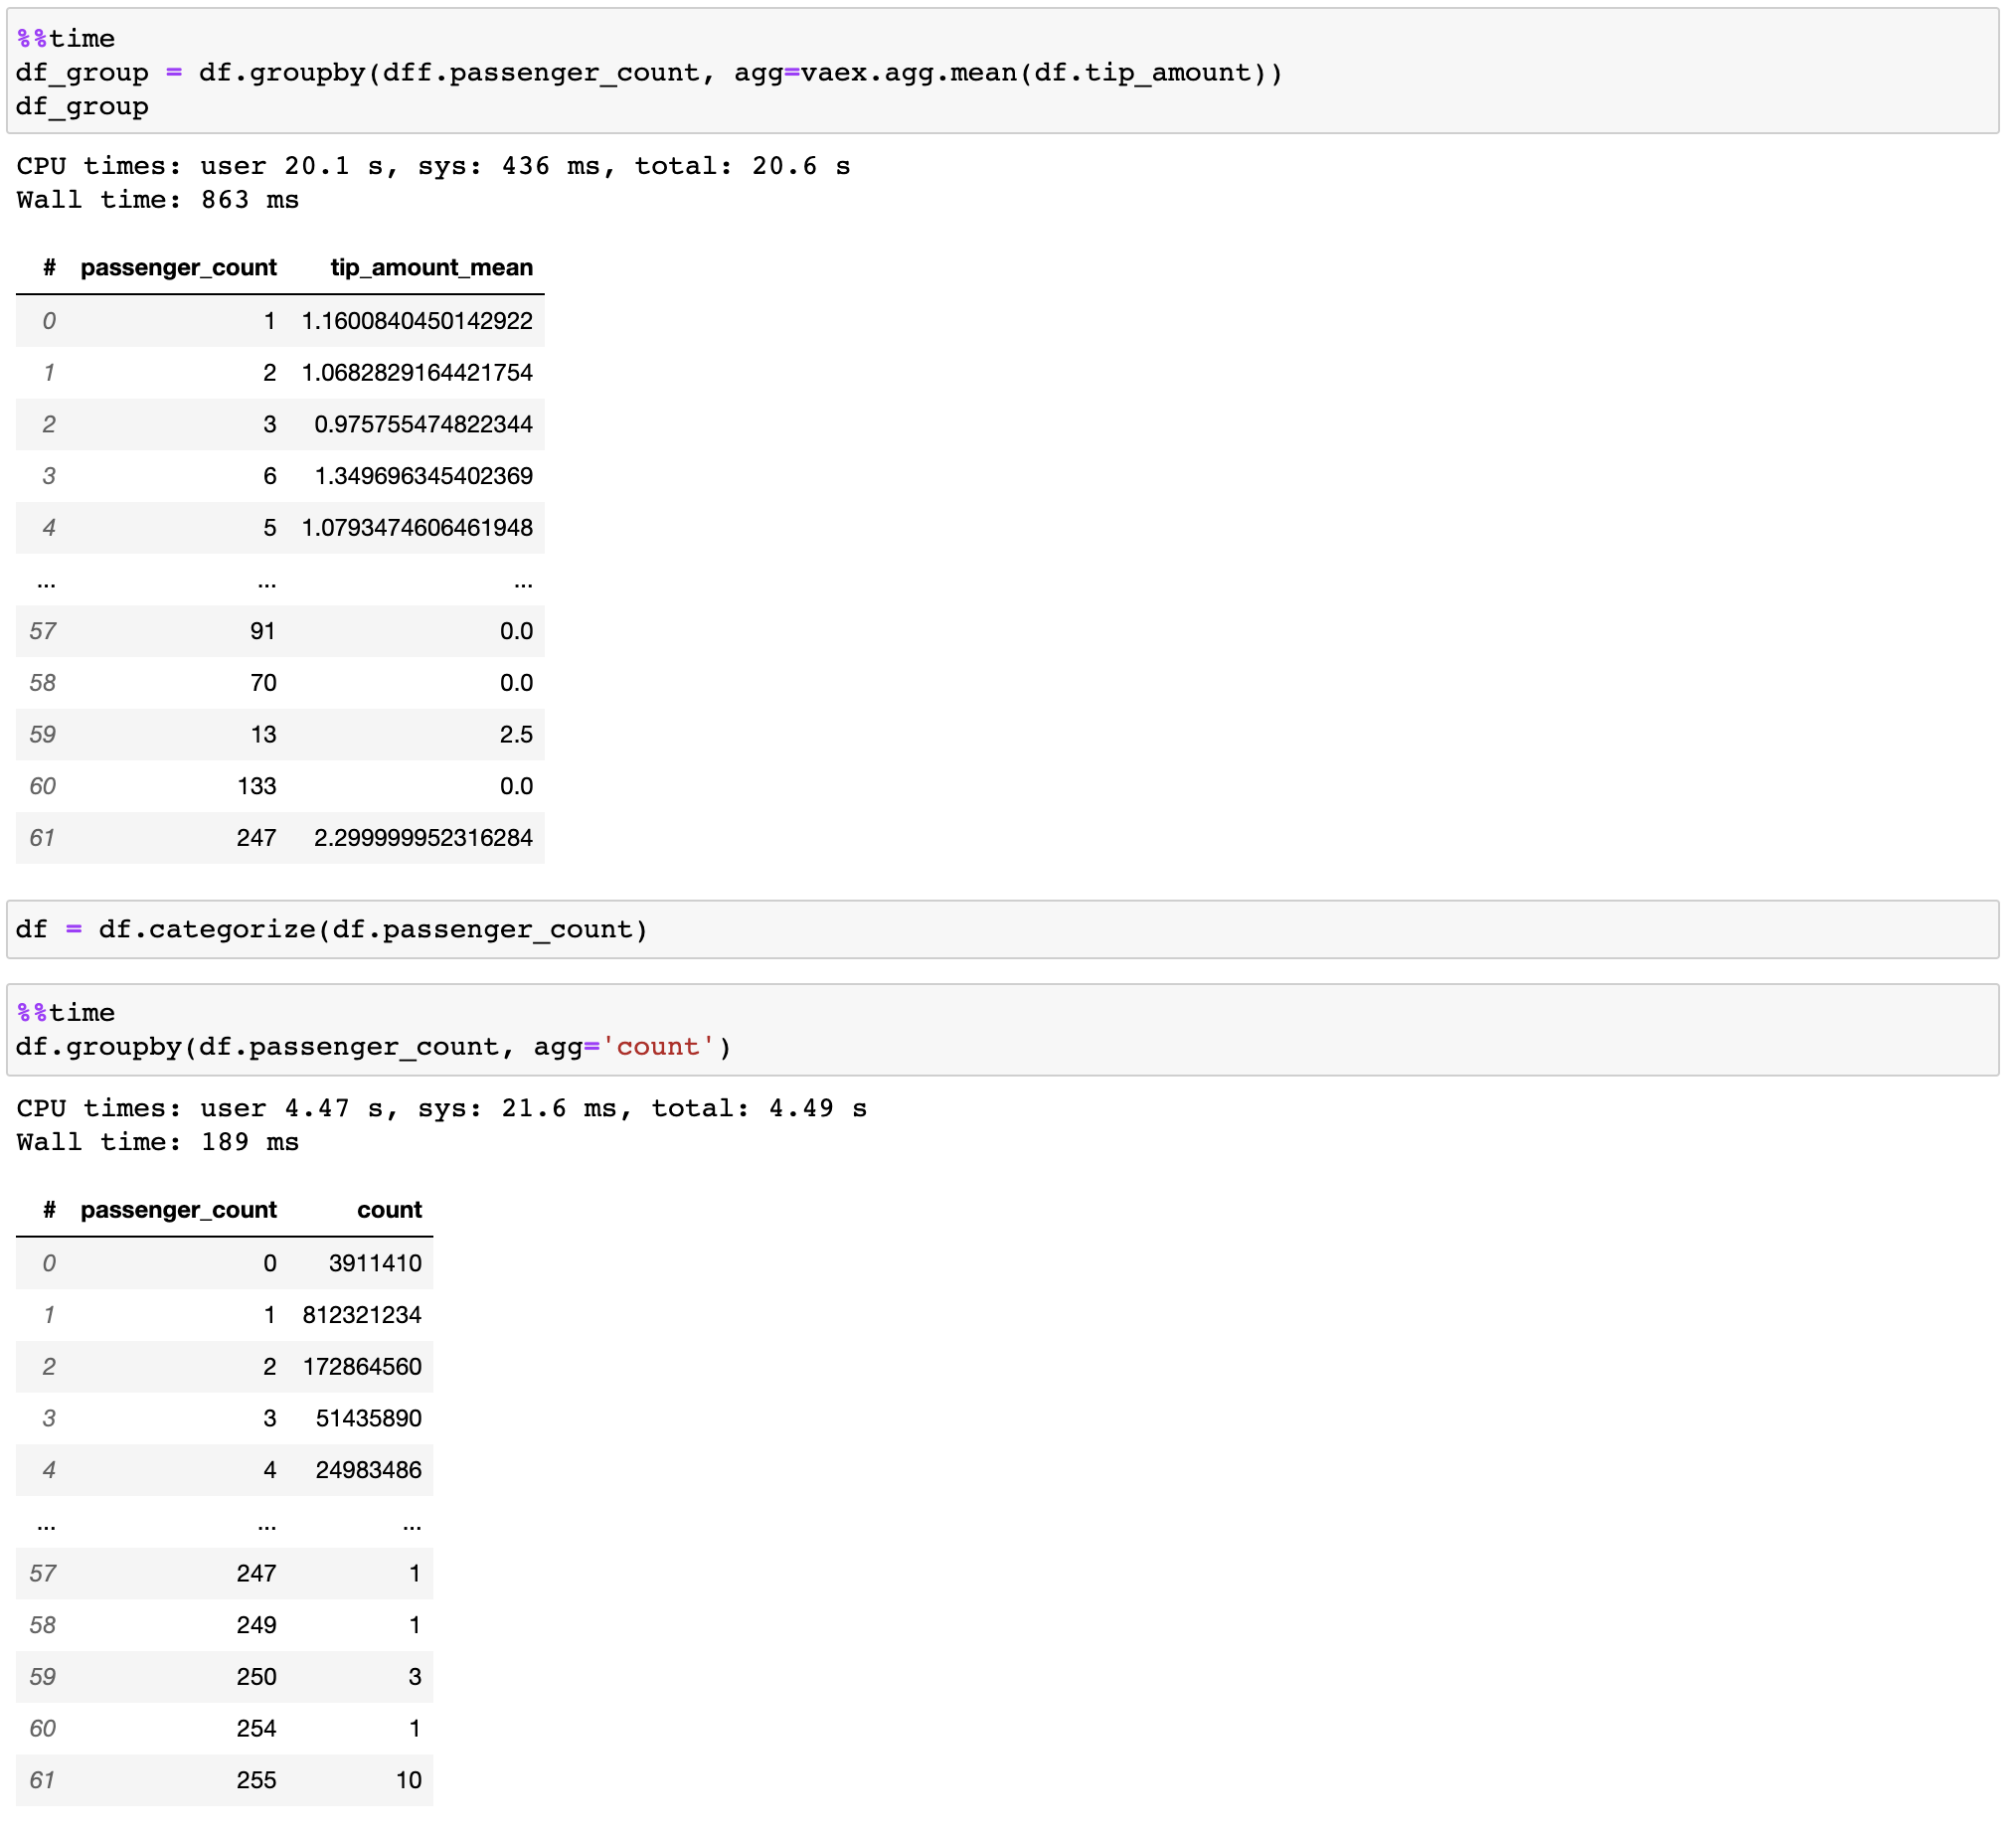
Fast and efficient join
Vaex doesn't copy/materialize the 'right' table when joining, saving gigabytes of memory. With subsecond joining on a billion rows, it's pretty fast!
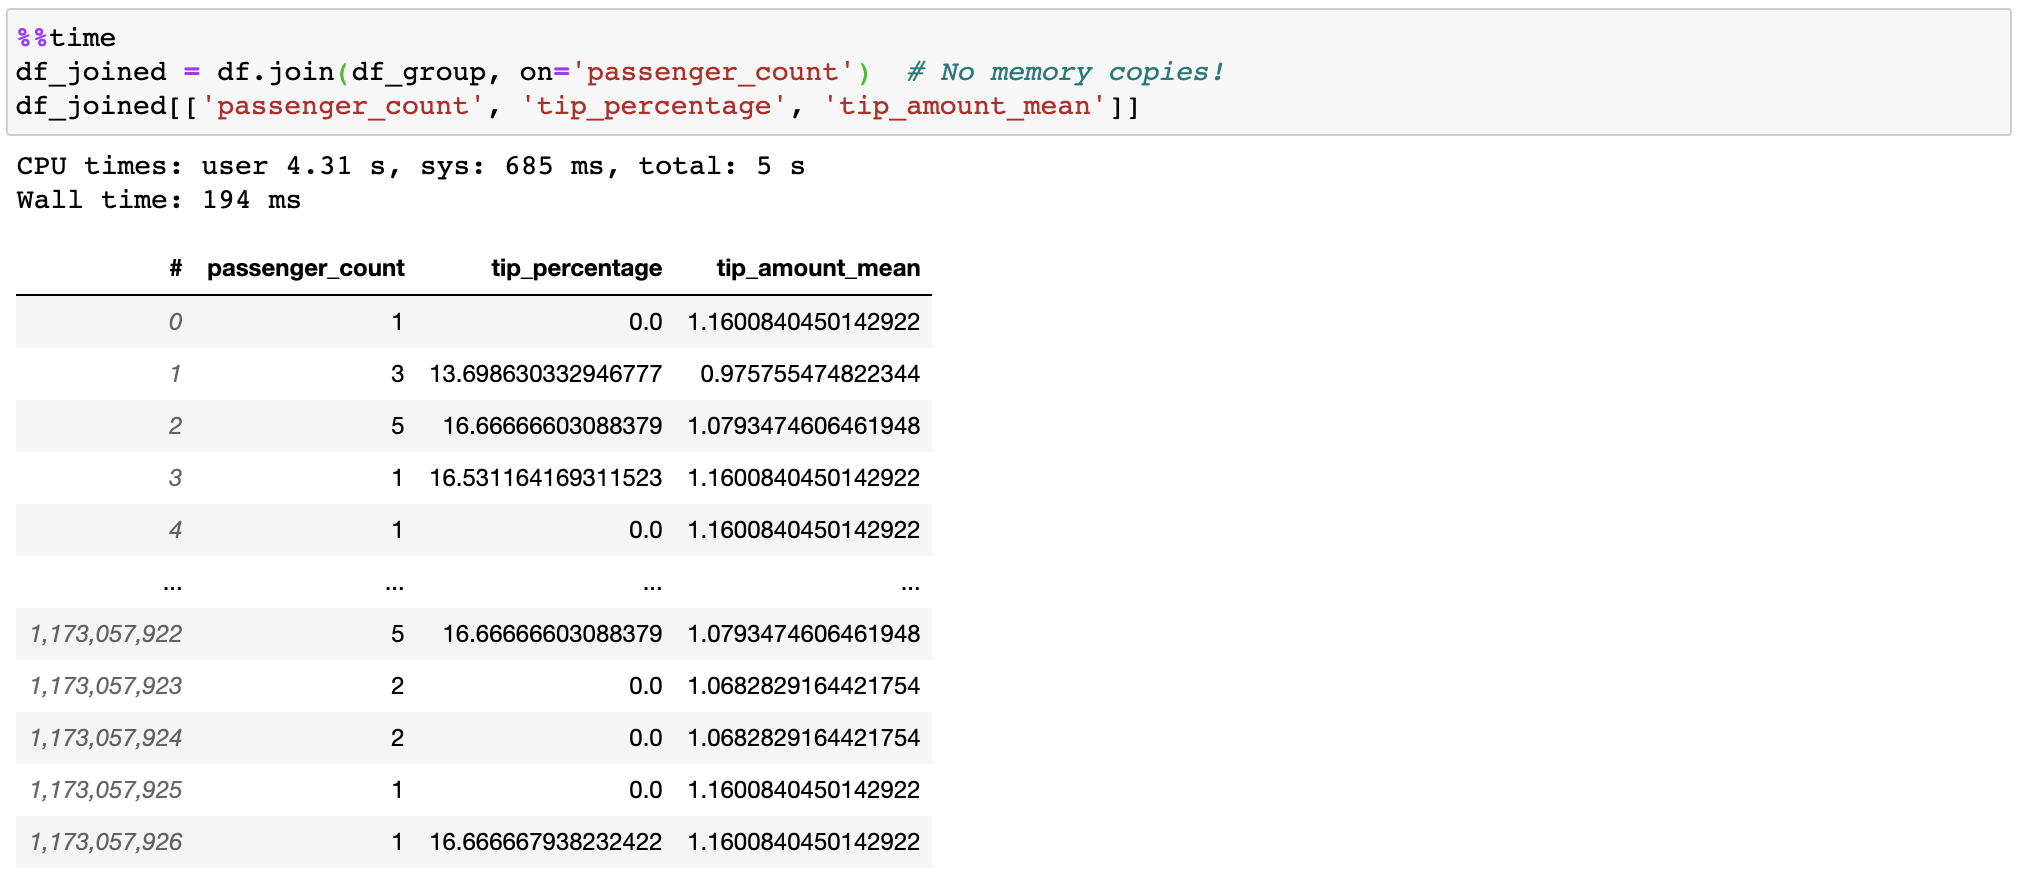
More features
- Remote DataFrames (documentation coming soon)
- Integration into Jupyter and Voila for interactive notebooks and dashboards
- Machine Learning without (explicit) pipelines
Contributing
See contributing page.
Slack
Join the discussion in our Slack channel!
Learn more about Vaex
Articles
- Beyond Pandas: Spark, Dask, Vaex and other big data technologies battling head to head (includes benchmarks)
- 7 reasons why I love Vaex for data science (tips and tricks)
- ML impossible: Train 1 billion samples in 5 minutes on your laptop using Vaex and Scikit-Learn
- How to analyse 100 GB of data on your laptop with Python
- Flying high with Vaex: analysis of over 30 years of flight data in Python
- Vaex: A DataFrame with super strings - Speed up your text processing up to a 1000x
- Vaex: Out of Core Dataframes for Python and Fast Visualization - 1 billion row datasets on your laptop
Watch our more recent talks:
Contact us for data science solutions, training, or enterprise support at https://vaex.io/
관련 프로젝트 살펴보기
tensorflow/tensorflow
모두를 위한 오픈소스 머신러닝 프레임워크
201,593 스타huggingface/transformers
🤗 Transformers: 텍스트, 비전, 오디오, 멀티모달 분야의 최첨단 머신러닝 모델을 위한 모델 정의 프레임워크로, 추론과 학습을 모두 지원합니다.
168,951 스타AUTOMATIC1111/stable-diffusion-webui
Stable Diffusion 웹 UI
165,306 스타Comfy-Org/ComfyUI
그래프와 노드로 구성된 인터페이스를 갖춘, 가장 강력하고 모듈성이 뛰어난 확산 모델 GUI, API, 백엔드입니다. 세계에서 가장 빠른 로컬 추론 엔진입니다.
146,692 스타