
suyukun666/UFO has 302 GitHub stars and 49 forks. GitHot measured 0 stars in 24 hours, 0 in 7 days, and 0 in 15 days. Last checked 2026-11-20 00:08 UTC. Last push 2023-04-02.
측정된 스타 증가
- in 24h
- 0
- in 7 days
- 0
- in 15 days
- 0
- in 1 month
- 기록 수집 중
서로 겹치는 기간의 순증가량이며 일별 합계가 아닙니다. 측정값이 없으면 비워 둡니다. 스타는 관심도를 나타내며 품질을 보장하지 않습니다.
소개
Official PyTorch implementation of the “A Unified Transformer Framework for Co-Segmentation, Co-Saliency Detection and Video Salient Object Detection”. (TMM2023)
머신러닝README.md
Original
A Unified Transformer Framework for Group-based Segmentation: Co-Segmentation, Co-Saliency Detection and Video Salient Object Detection


Update
08/09/2022 Video Inpainting script and model coming soon!
22/07/2022 Add demo to Huggingface Spaces with Gradio.
| Paper Link | Huggingface Demo |
|---|---|
| [paper] |  |
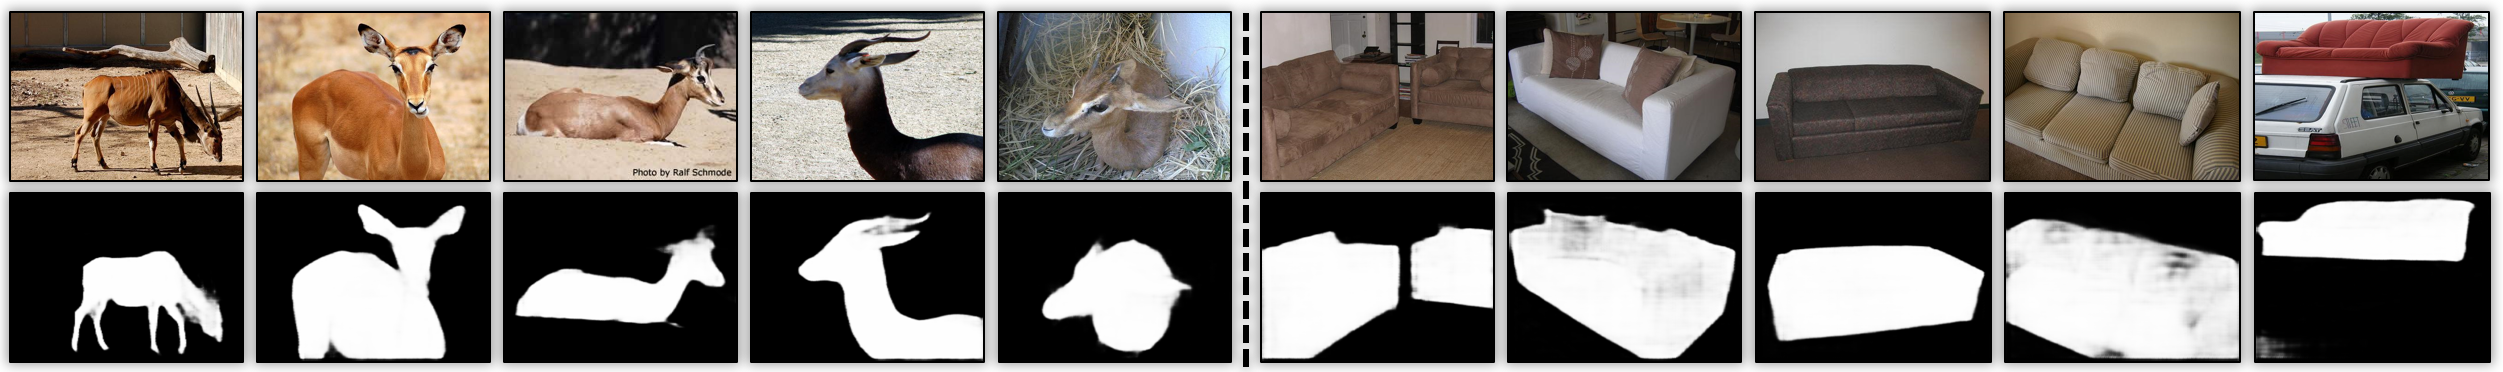
UFO is a simple and Unified framework for addressing Co-Object Segmentation tasks: Co-Segmentation, Co-Saliency Detection and Video Salient Object Detection. Humans tend to mine objects by learning from a group of images or a several frames of video since we live in a dynamic world. In computer vision area, many researches focus on co-segmentation (CoS), co-saliency detection (CoSD) and video salient object detection (VSOD) to discover the co-occurrent objects. However, previous approaches design different networks on these tasks separately, which lower the upper bound on the ease of use of deep learning frameworks. In this paper, we introduce a unified framework to tackle these issues, term as UFO (Unified Framework for Co-Object Segmentation). All tasks share the same framework.
Task & Framework

Usage
Requirement
torch >= 1.7.0
torchvision >= 0.7.0
python3
Training
Training on group-based images. We use COCO2017 train set with the provided group split dict.npy.
python main.py
Training on video (w/o flow) . We load the weight pre-trained on the static image dataset, and use DAVIS and FBMS to train our framework.
python finetune.py --model=models/image_best.pth --use_flow=False
Training on video (w/ flow). The same as above, then we use DAVIS_flow and FBMS_flow to train our network.
python finetune.py --model=models/image_best.pth --use_flow=True
Inference
Generate the image results [checkpoint]
python test.py --model=models/image_best.pth --data_path=CoSdatasets/MSRC7/ --output_dir=CoS_results/MSRC7 --task=CoS_CoSD
Generate the video results [checkpoint]
python test.py --model=models/video_best.pth --data_path=VSODdatasets/DAVIS/ --output_dir=VSOD_results/wo_optical_flow/DAVIS --task=VSOD
Generate the video results with optical flow [checkpoint]
python test.py --model=models/video_flow_best.pth --data_path=VSODdatasets/DAVIS_flow/ --output_dir=VSOD_results/w_optical_flow/w_optical_flow --use_flow=True --task=VSOD
Evaluation
- Pre-Computed Results: Please download the prediction results of our framework form the Results section.
- Evaluation Toolbox: We use the standard evaluation toolbox from COCA benchmark.
Result
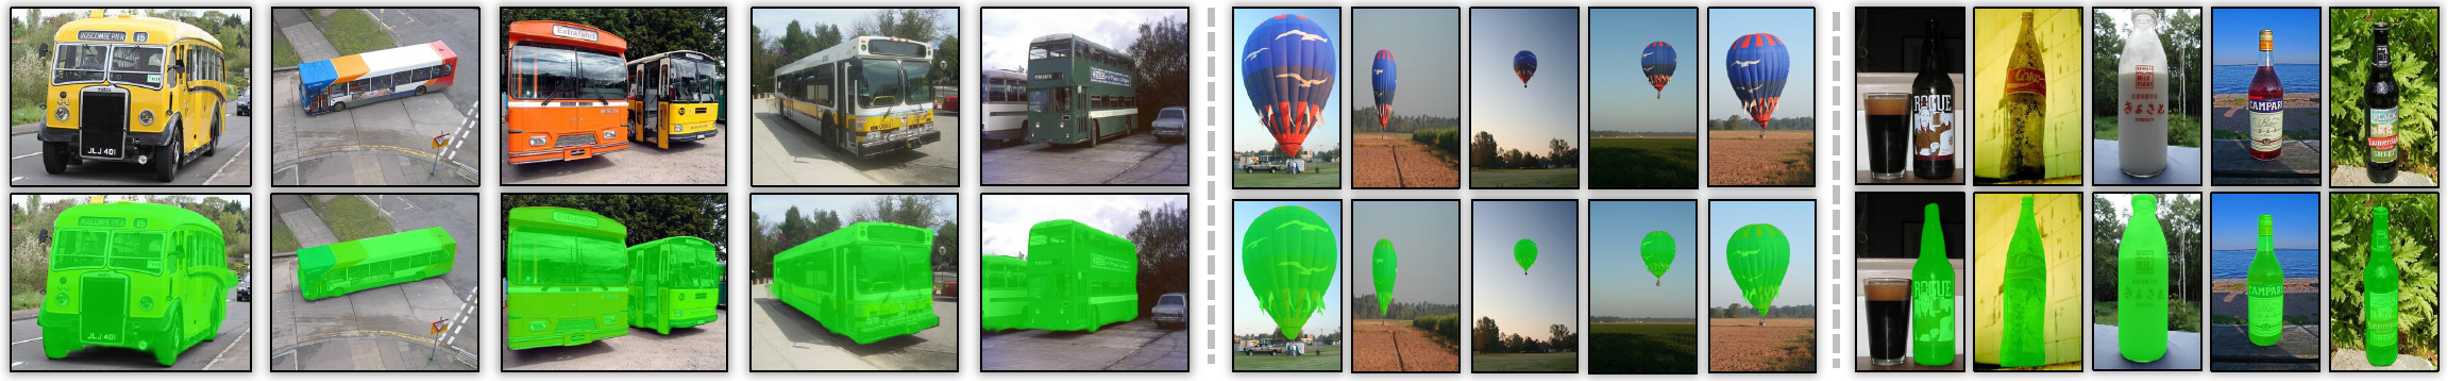
- Co-Segmentation (CoS) on PASCAL-VOC, iCoseg, Internet and MSRC [Pre-computed Results]
- Co-Saliency Detection(CoSD) on CoCA,CoSOD3k and CoSal2015 [Pre-computed Results]
- Video Salient Object Detection (VSOD) on DAVIS16 val set [Pre-computed Results]
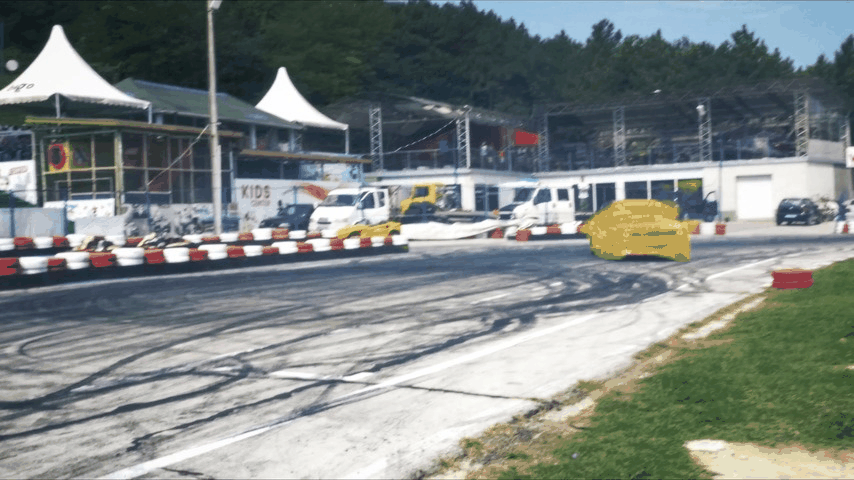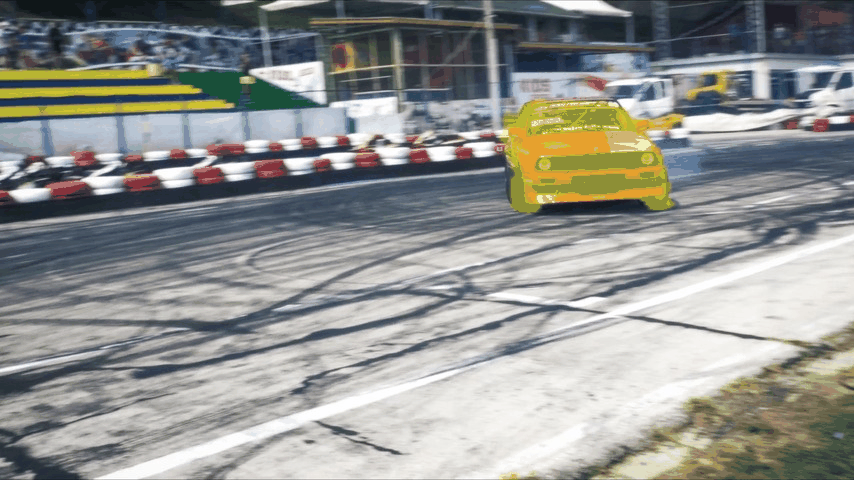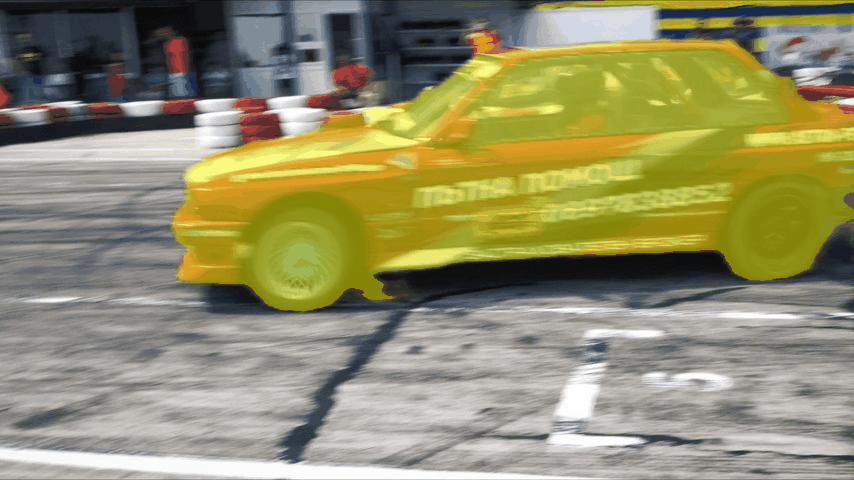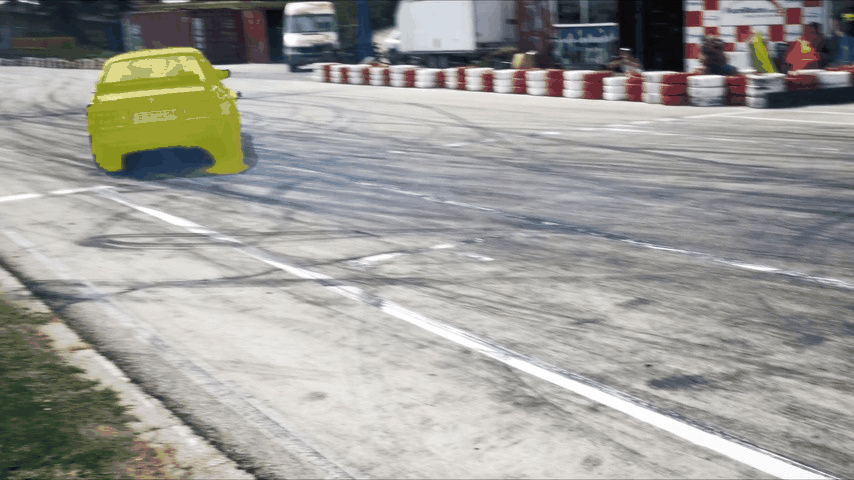
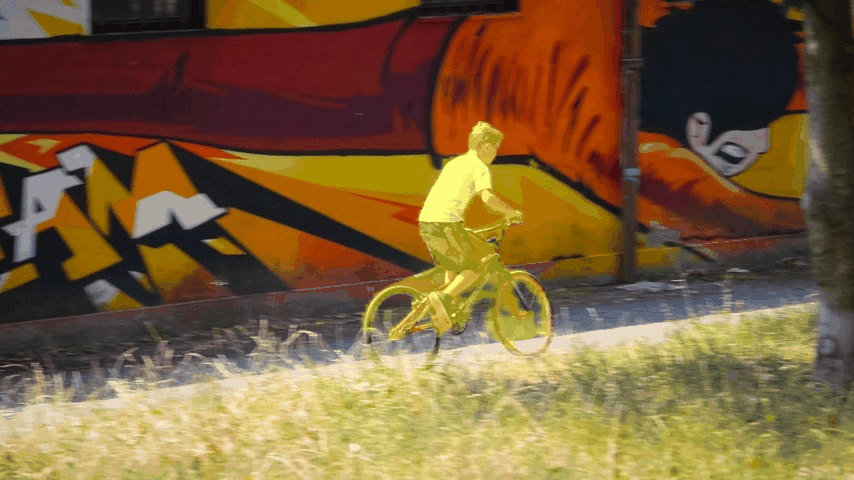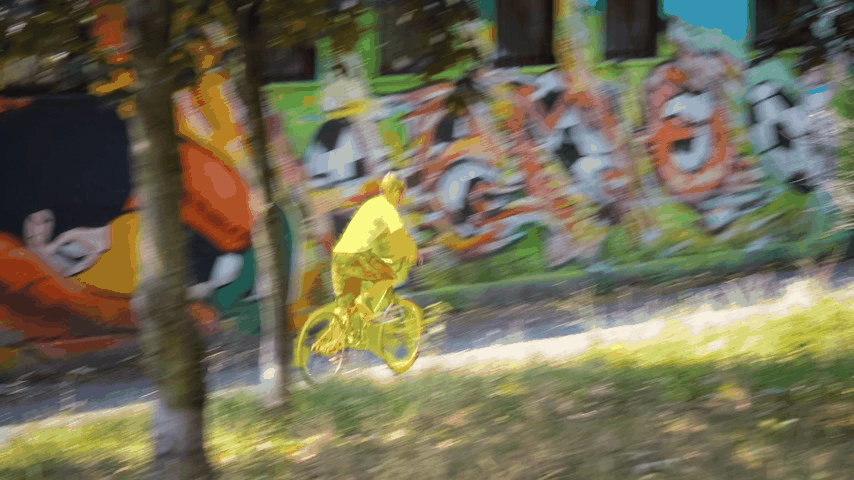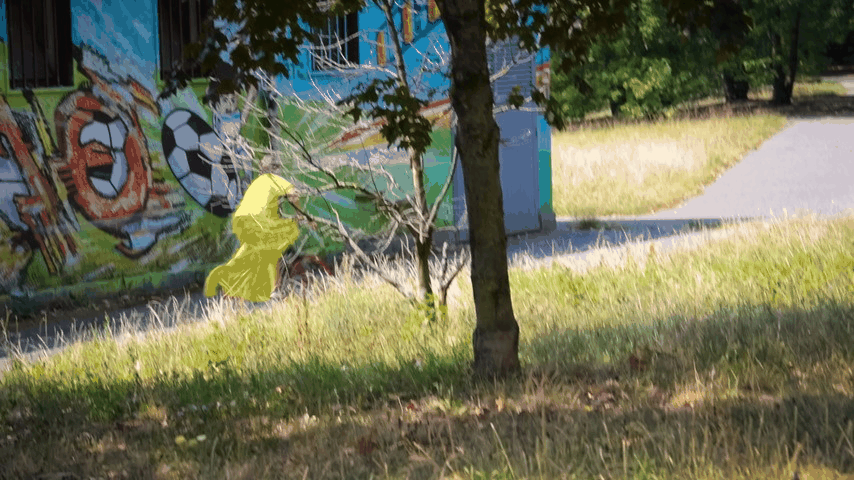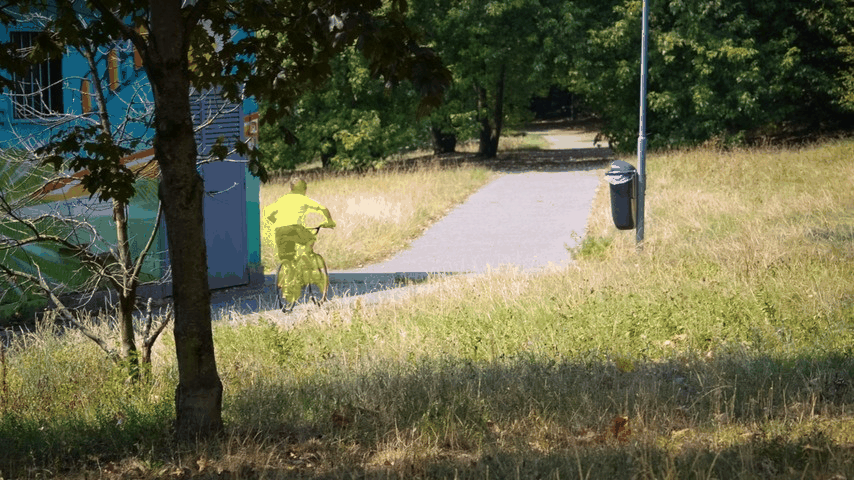
- [Optional] Single Object Tracking (SOT) on GOT-10k val set
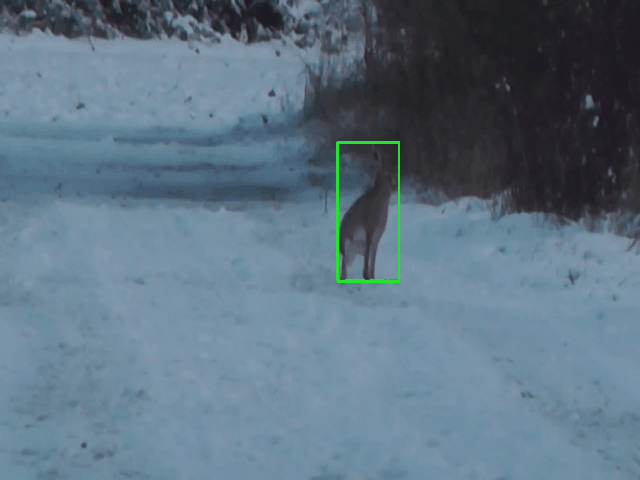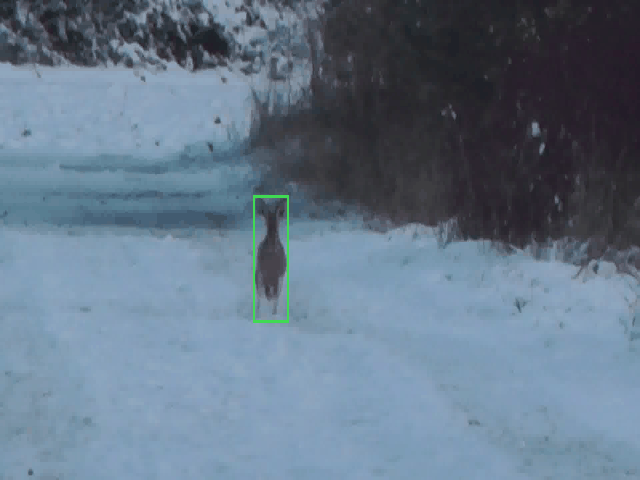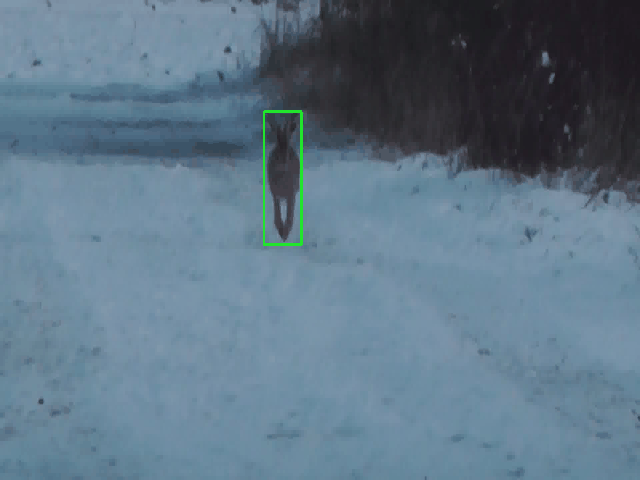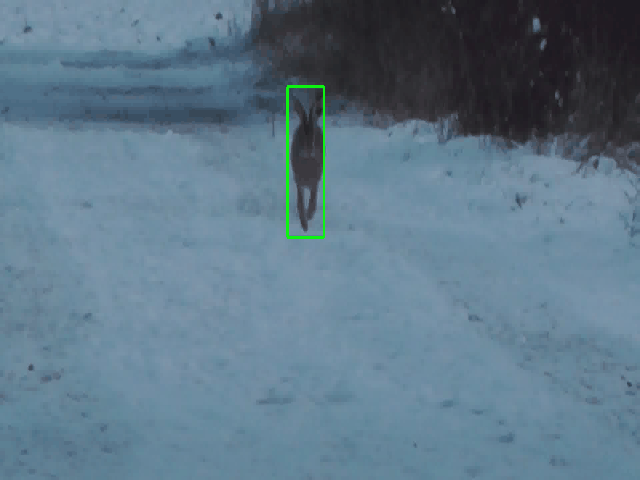
- Video inpainting on YouTube-VOS test set (Currently not fully trained)
Demo
python demo.py --data_path=./demo_mp4/video/kobe.mp4 --output_dir=./demo_mp4/result
bash demo_bullet_chat.sh
Citation
If you find the code useful, please consider citing our paper using the following BibTeX entry.
@misc{2203.04708,
Author = {Yukun Su and Jingliang Deng and Ruizhou Sun and Guosheng Lin and Qingyao Wu},
Title = {A Unified Transformer Framework for Group-based Segmentation: Co-Segmentation, Co-Saliency Detection and Video Salient Object Detection},
Year = {2022},
Eprint = {arXiv:2203.04708},
}

@article{su2023unified,
title = {A Unified Transformer Framework for Group-based Segmentation: Co-Segmentation, Co-Saliency Detection and Video Salient Object Detection},
author = {Yukun Su and Jingliang Deng and Ruizhou Sun and Guosheng Lin and Qingyao Wu},
journal = {IEEE Transactions on Multimedia},
year = {2023},
publisher = {IEEE}
}
Acknowledgement
Our project references the codes in the following repos.