
soobinseo/Transformer-TTS
soobinseo/Transformer-TTS has 695 GitHub stars and 140 forks. Star changes are not measured yet. Last checked 2026-11-14 05:50 UTC. Last push 2023-11-08.
측정된 스타 증가
- in 24h
- 기록 수집 중
- in 7 days
- 기록 수집 중
- in 15 days
- 기록 수집 중
- in 1 month
- 기록 수집 중
서로 겹치는 기간의 순증가량이며 일별 합계가 아닙니다. 측정값이 없으면 비워 둡니다. 스타는 관심도를 나타내며 품질을 보장하지 않습니다.
소개
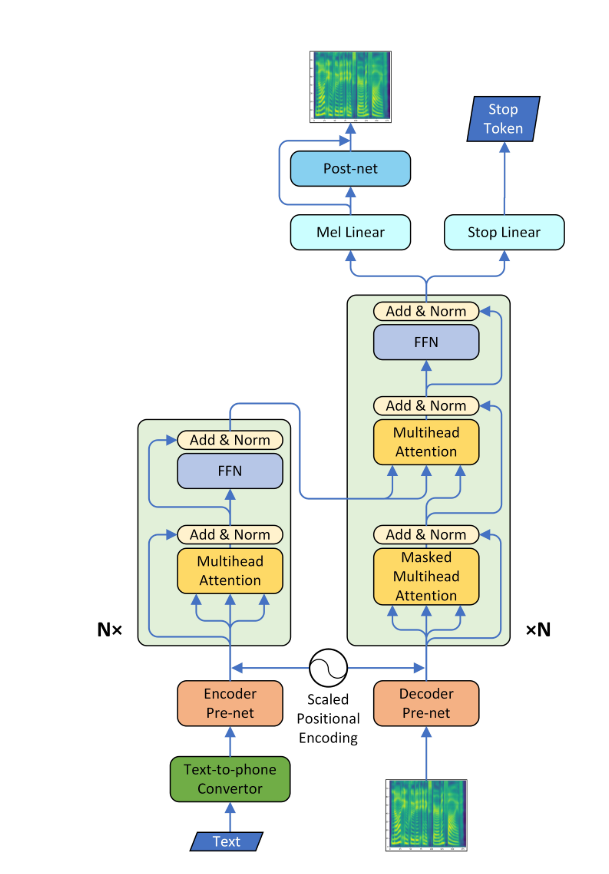
A Pytorch Implementation of "Neural Speech Synthesis with Transformer Network"
머신러닝README.md
OriginalTransformer-TTS
- A Pytorch Implementation of Neural Speech Synthesis with Transformer Network
- This model can be trained about 3 to 4 times faster than the well known seq2seq model like tacotron, and the quality of synthesized speech is almost the same. It was confirmed through experiment that it took about 0.5 second per step.
- I did not use the wavenet vocoder but learned the post network using CBHG model of tacotron and converted the spectrogram into raw wave using griffin-lim algorithm.
Requirements
- Install python 3
- Install pytorch == 0.4.0
- Install requirements:
pip install -r requirements.txt
Data
- I used LJSpeech dataset which consists of pairs of text script and wav files. The complete dataset (13,100 pairs) can be downloaded here. I referred https://github.com/keithito/tacotron and https://github.com/Kyubyong/dc_tts for the preprocessing code.
Pretrained Model
- you can download pretrained model here (160K for AR model / 100K for Postnet)
- Locate the pretrained model at checkpoint/ directory.
Attention plots
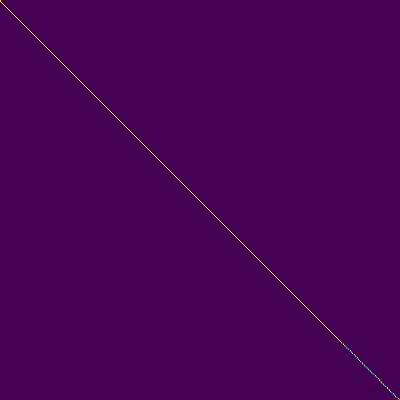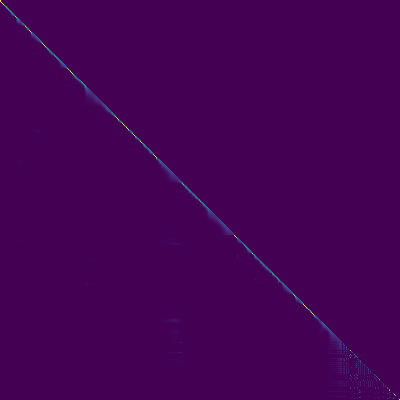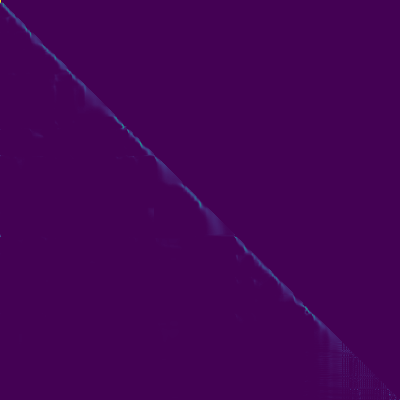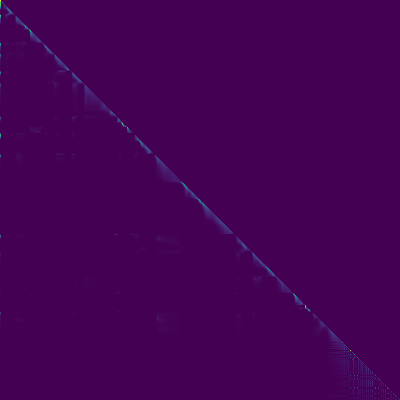
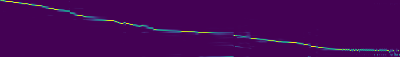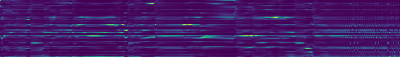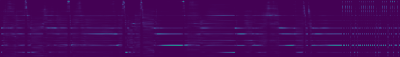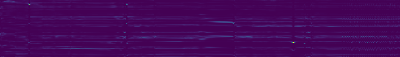
- A diagonal alignment appeared after about 15k steps. The attention plots below are at 160k steps. Plots represent the multihead attention of all layers. In this experiment, h=4 is used for three attention layers. Therefore, 12 attention plots were drawn for each of the encoder, decoder and encoder-decoder. With the exception of the decoder, only a few multiheads showed diagonal alignment.
Self Attention encoder

Self Attention decoder
Attention encoder-decoder
Learning curves & Alphas
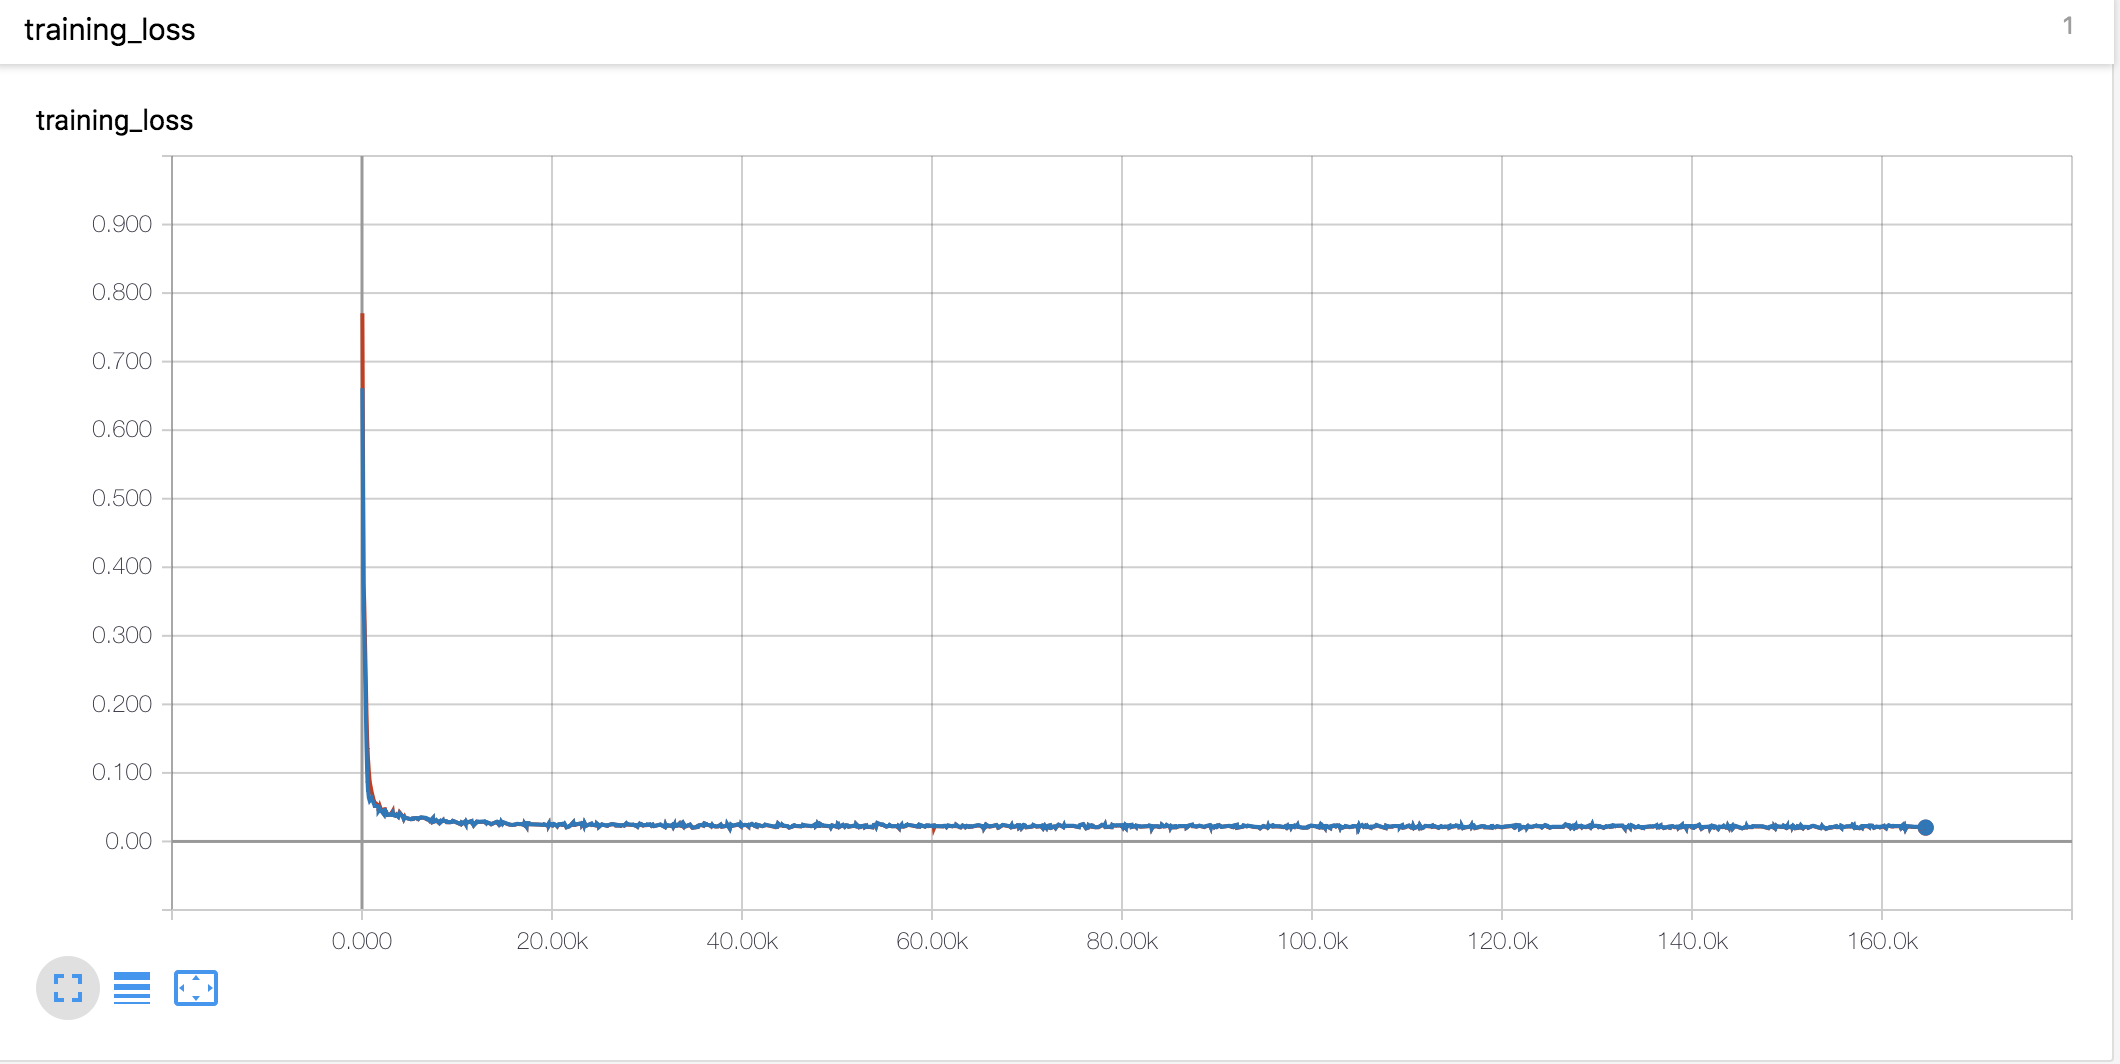
- I used Noam style warmup and decay as same as Tacotron
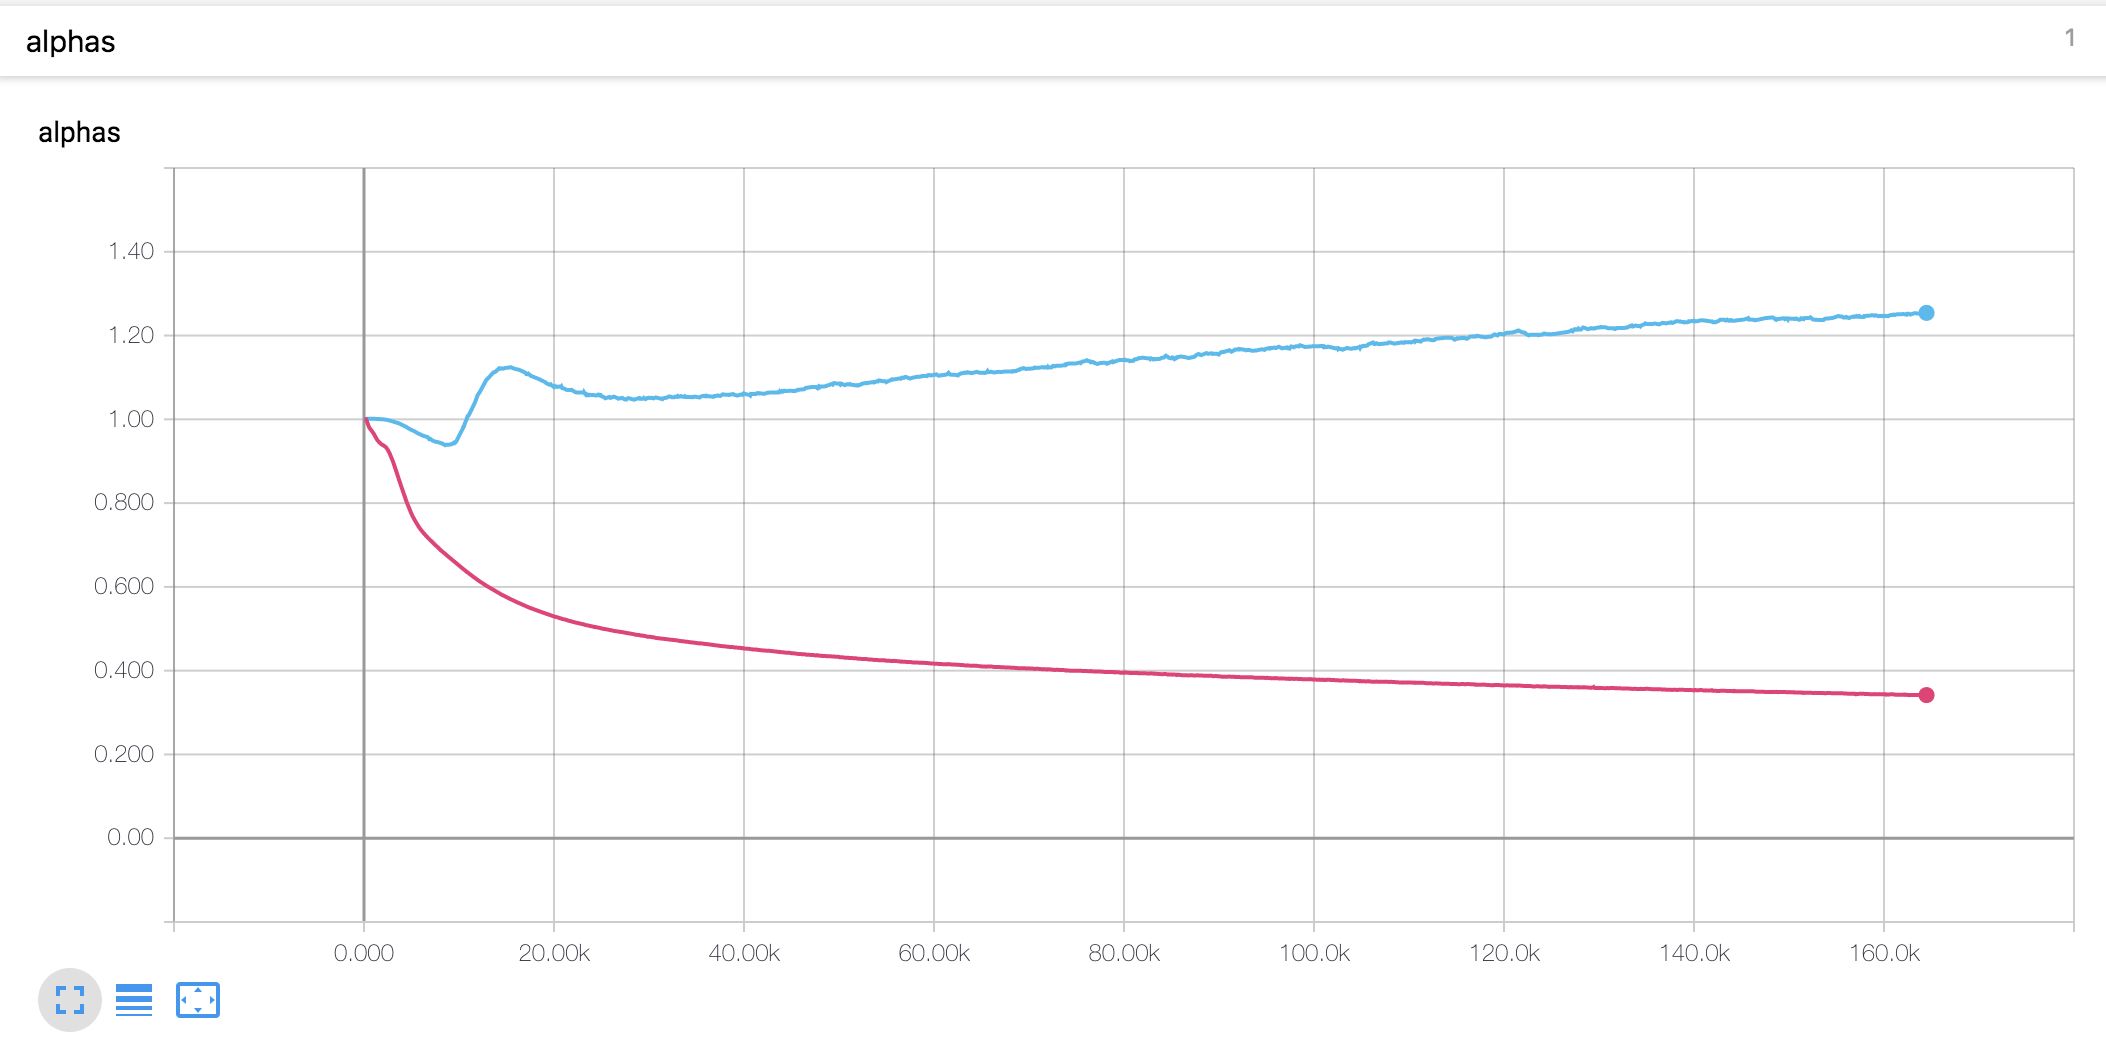
- The alpha value for the scaled position encoding is different from the thesis. In the paper, the alpha value of the encoder is increased to 4, whereas in the present experiment, it slightly increased at the beginning and then decreased continuously. The decoder alpha has steadily decreased since the beginning.
Experimental notes
- The learning rate is an important parameter for training. With initial learning rate of 0.001 and exponentially decaying doesn't work.
- The gradient clipping is also an important parameter for training. I clipped the gradient with norm value 1.
- With the stop token loss, the model did not training.
- It was very important to concatenate the input and context vectors in the Attention mechanism.
Generated Samples
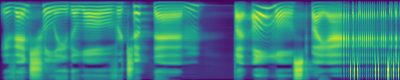
You can check some generated samples below. All samples are step at 160k, so I think the model is not converged yet. This model seems to be lower performance in long sentences.
The first plot is the predicted mel spectrogram, and the second is the ground truth.

File description
hyperparams.pyincludes all hyper parameters that are needed.prepare_data.pypreprocess wav files to mel, linear spectrogram and save them for faster training time. Preprocessing codes for text is in text/ directory.preprocess.pyincludes all preprocessing codes when you loads data.module.pycontains all methods, including attention, prenet, postnet and so on.network.pycontains networks including encoder, decoder and post-processing network.train_transformer.pyis for training autoregressive attention network. (text --> mel)train_postnet.pyis for training post network. (mel --> linear)synthesis.pyis for generating TTS sample.
Training the network
- STEP 1. Download and extract LJSpeech data at any directory you want.
- STEP 2. Adjust hyperparameters in
hyperparams.py, especially 'data_path' which is a directory that you extract files, and the others if necessary. - STEP 3. Run
prepare_data.py. - STEP 4. Run
train_transformer.py. - STEP 5. Run
train_postnet.py.
Generate TTS wav file
- STEP 1. Run
synthesis.py. Make sure the restore step.
Reference
- Keith ito: https://github.com/keithito/tacotron
- Kyubyong Park: https://github.com/Kyubyong/dc_tts
- jadore801120: https://github.com/jadore801120/attention-is-all-you-need-pytorch/
Comments
- Any comments for the codes are always welcome.
관련 프로젝트 살펴보기
tensorflow/tensorflow
모두를 위한 오픈소스 머신러닝 프레임워크
201,590 스타huggingface/transformers
🤗 Transformers: 텍스트, 비전, 오디오, 멀티모달 분야의 최첨단 머신러닝 모델을 위한 모델 정의 프레임워크로, 추론과 학습을 모두 지원합니다.
168,957 스타AUTOMATIC1111/stable-diffusion-webui
Stable Diffusion 웹 UI
165,307 스타Comfy-Org/ComfyUI
그래프와 노드로 구성된 인터페이스를 갖춘, 가장 강력하고 모듈성이 뛰어난 확산 모델 GUI, API, 백엔드입니다. 세계에서 가장 빠른 로컬 추론 엔진입니다.
146,728 스타