
qubvel-org/segmentation_models.pytorch
qubvel-org/segmentation_models.pytorch has 11,799 GitHub stars and 1,851 forks. GitHot measured +1 stars in 24 hours, +8 in 7 days, and +21 in 15 days. Last checked 2026-11-08 18:08 UTC. Last push 2026-11-02.
500개 이상의 사전 학습된 합성곱 및 트랜스포머 기반 백본을 갖춘 시맨틱 세그멘테이션 모델.
측정된 스타 증가
- in 24h
- +1
- in 7 days
- +8
- in 15 days
- +21
- in 1 month
- 업데이트 지연
서로 겹치는 기간의 순증가량이며 일별 합계가 아닙니다. 측정값이 없으면 비워 둡니다. 스타는 관심도를 나타내며 품질을 보장하지 않습니다.
README.md
Original Python library with Neural Networks for Image Semantic
Segmentation based on PyTorch.


The main features of the library are:
- Super simple high-level API (just two lines to create a neural network)
- 12 encoder-decoder model architectures (Unet, Unet++, Segformer, DPT, ...)
- 800+ pretrained convolution- and transform-based encoders, including timm support
- Popular metrics and losses for training routines (Dice, Jaccard, Tversky, ...)
- ONNX export and torch script/trace/compile friendly
🤝 Sponsor: withoutBG
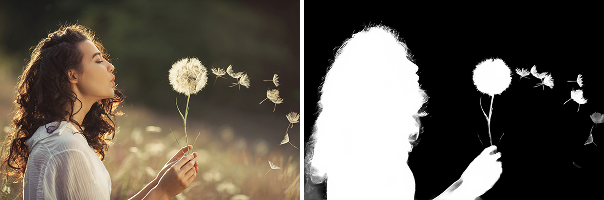
withoutBG is a high-quality background removal tool. They built their open-source image matting and refiner models using smp.Unet and are proudly sponsoring this project.
📚 Project Documentation 📚
Visit Read The Docs Project Page or read the following README to know more about Segmentation Models Pytorch (SMP for short) library
📋 Table of content
- Quick start
- Examples
- Models and encoders
- Models API
- Installation
- Competitions won with the library
- Contributing
- Citing
- License
⏳ Quick start
1. Create your first Segmentation model with SMP
The segmentation model is just a PyTorch torch.nn.Module, which can be created as easy as:
import segmentation_models_pytorch as smp

model = smp.Unet(
    encoder_name="resnet34",        # choose encoder, e.g. mobilenet_v2 or efficientnet-b7
    encoder_weights="imagenet",     # use `imagenet` pre-trained weights for encoder initialization
    in_channels=1,                  # model input channels (1 for gray-scale images, 3 for RGB, etc.)
    classes=3,                      # model output channels (number of classes in your dataset)
)
- see table with available model architectures
- see table with available encoders and their corresponding weights
2. Configure data preprocessing
All encoders have pretrained weights. Preparing your data the same way as during weights pre-training may give you better results (higher metric score and faster convergence). It is not necessary in case you train the whole model, not only the decoder.
from segmentation_models_pytorch.encoders import get_preprocessing_fn

preprocess_input = get_preprocessing_fn('resnet18', pretrained='imagenet')
Congratulations! You are done! Now you can train your model with your favorite framework!
💡 Examples
| Name | Link | Colab |
|---|---|---|
| Train pets binary segmentation on OxfordPets | Notebook |  |
| Train cars binary segmentation on CamVid | Notebook | |
| Train multiclass segmentation on CamVid | Notebook | |
| Train clothes binary segmentation by @ternaus | Repo | |
| Load and inference pretrained Segformer | Notebook | |
| Load and inference pretrained DPT | Notebook | |
| Load and inference pretrained UPerNet | Notebook | |
| Save and load models locally / to HuggingFace Hub | Notebook | |
| Export trained model to ONNX | Notebook | |
📦 Models and encoders
Architectures
| Architecture | Paper | Documentation | Checkpoints |
|---|---|---|---|
| Unet | paper | docs | |
| Unet++ | paper | docs | |
| MAnet | paper | docs | |
| Linknet | paper | docs | |
| FPN | paper | docs | |
| PSPNet | paper | docs | |
| PAN | paper | docs | |
| DeepLabV3 | paper | docs | |
| DeepLabV3+ | paper | docs | |
| UPerNet | paper | docs | checkpoints |
| Segformer | paper | docs | checkpoints |
| DPT | paper | docs | checkpoints |
Encoders
The library provides a wide range of pretrained encoders (also known as backbones) for segmentation models. Instead of using features from the final layer of a classification model, we extract intermediate features and feed them into the decoder for segmentation tasks.
All encoders come with pretrained weights, which help achieve faster and more stable convergence when training segmentation models.
Given the extensive selection of supported encoders, you can choose the best one for your specific use case, for example:
- Lightweight encoders for low-latency applications or real-time inference on edge devices (mobilenet/mobileone).
- High-capacity architectures for complex tasks involving a large number of segmented classes, providing superior accuracy (convnext/swin/mit).
By selecting the right encoder, you can balance efficiency, performance, and model complexity to suit your project needs.
All encoders and corresponding pretrained weight are listed in the documentation:
🔁 Models API
Input channels
The input channels parameter allows you to create a model that can process a tensor with an arbitrary number of channels. If you use pretrained weights from ImageNet, the weights of the first convolution will be reused:
- For the 1-channel case, it would be a sum of the weights of the first convolution layer.
- Otherwise, channels would be populated with weights like
new_weight[:, i] = pretrained_weight[:, i % 3], and then scaled withnew_weight * 3 / new_in_channels.
model = smp.FPN('resnet34', in_channels=1)
mask = model(torch.ones([1, 1, 64, 64]))
Auxiliary classification output
All models support aux_params parameters, which is default set to None.
If aux_params = None then classification auxiliary output is not created, else
model produce not only mask, but also label output with shape NC.
Classification head consists of GlobalPooling->Dropout(optional)->Linear->Activation(optional) layers, which can be
configured by aux_params as follows:
aux_params=dict(
    pooling='avg',             # one of 'avg', 'max'
    dropout=0.5,               # dropout ratio, default is None
    activation='sigmoid',      # activation function, default is None
    classes=4,                 # define number of output labels
)
model = smp.Unet('resnet34', classes=4, aux_params=aux_params)
mask, label = model(x)
Depth
Depth parameter specify a number of downsampling operations in encoder, so you can make
your model lighter if specify smaller depth.
model = smp.Unet('resnet34', encoder_depth=4)
🛠 Installation
PyPI version:
$ pip install segmentation-models-pytorch
The latest version from GitHub:
$ pip install git+https://github.com/qubvel/segmentation_models.pytorch
🏆 Competitions won with the library
Segmentation Models package is widely used in image segmentation competitions.
Here you can find competitions, names of the winners and links to their solutions.
🛠 Projects built with SMP
- withoutBG: An open-source background removal tool that uses
smp.Unetfor its image matting and refinement models. Check withoutBG Focus on HuggingFace.
🤝 Contributing
- Install SMP in dev mode
make install_dev # Create .venv, install SMP in dev mode
- Run tests and code checks
make test          # Run tests suite with pytest
make fixup         # Ruff for formatting and lint checks
- Update a table (in case you added an encoder)
make table # Generates a table with encoders and print to stdout
📝 Citing
@misc{Iakubovskii:2019,
  Author = {Pavel Iakubovskii},
  Title = {Segmentation Models Pytorch},
  Year = {2019},
  Publisher = {GitHub},
  Journal = {GitHub repository},
  Howpublished = {\url{https://github.com/qubvel/segmentation_models.pytorch}}
}
🛡️ License
The project is primarily distributed under MIT License, while some files are subject to other licenses. Please refer to LICENSES and license statements in each file for careful check, especially for commercial use.
관련 프로젝트 살펴보기
tensorflow/tensorflow
모두를 위한 오픈소스 머신러닝 프레임워크
201,400 스타huggingface/transformers
🤗 Transformers: 텍스트, 비전, 오디오, 멀티모달 분야의 최첨단 머신러닝 모델을 위한 모델 정의 프레임워크로, 추론과 학습을 모두 지원합니다.
168,668 스타AUTOMATIC1111/stable-diffusion-webui
Stable Diffusion 웹 UI
165,261 스타Comfy-Org/ComfyUI
그래프와 노드로 구성된 인터페이스를 갖춘, 가장 강력하고 모듈성이 뛰어난 확산 모델 GUI, API, 백엔드입니다. 세계에서 가장 빠른 로컬 추론 엔진입니다.
145,835 스타