
promptslab/Promptify
promptslab/Promptify has 4,647 GitHub stars and 361 forks. GitHot measured 0 stars in 24 hours and +2 in 7 days. Last checked 2026-11-08 14:43 UTC. Last push 2026-03-27.
프롬프트 엔지니어링 | 프롬프트 버전 관리 | GPT 또는 다른 프롬프트 기반 모델을 사용해 구조화된 출력을 얻으세요. Discord에 참여해 프롬프트 엔지니어링, LLM 및 기타 최신 연구에 대해 알아보세요
What you can do
- 2-3 lines of code for any NLP task -no training data required
- Pydantic structured outputs -type-safe results, not raw strings
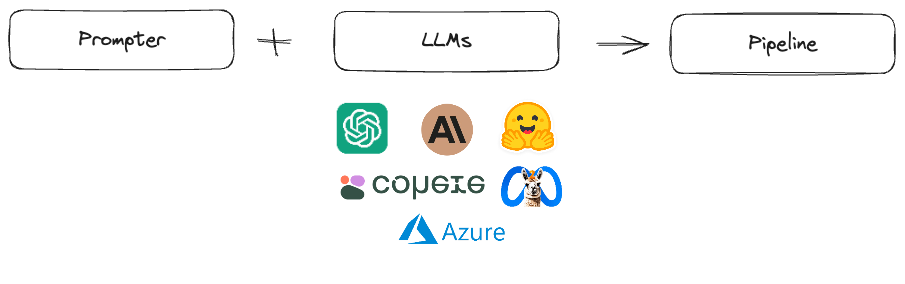
- Any LLM provider via LiteLLM -OpenAI, Anthropic, Google, Ollama, Azure, and 100+ more
- Built-in tasks -NER, Classification (binary/multiclass/multilabel), QA, Summarization, Relation Extraction, SQL Generation, and more
측정된 스타 증가
- in 24h
- 0
- in 7 days
- +2
- in 15 days
- 기록 수집 중
- in 1 month
- 기록 수집 중
서로 겹치는 기간의 순증가량이며 일별 합계가 아닙니다. 측정값이 없으면 비워 둡니다. 스타는 관심도를 나타내며 품질을 보장하지 않습니다.
README.md
Original
Promptify
Task-based NLP engine with Pydantic structured outputs, built-in evaluation, and LiteLLM as the universal LLM backend. Think "scikit-learn for LLM-powered NLP".



Installation
With pip
Requires Python 3.9+.
pip install promptify
or
pip install git+https://github.com/promptslab/Promptify.git
For evaluation metrics support:
pip install promptify[eval]
Quick Tour
3-Line NER
from promptify import NER

ner = NER(model="gpt-4o-mini", domain="medical")
result = ner("The patient is a 93-year-old female with a medical history of chronic right hip pain, osteoporosis, hypertension, depression, and chronic atrial fibrillation admitted for evaluation and management of severe nausea and vomiting and urinary tract infection")
Output:
NERResult(entities=[
    Entity(text="93-year-old", label="AGE"),
    Entity(text="chronic right hip pain", label="CONDITION"),
    Entity(text="osteoporosis", label="CONDITION"),
    Entity(text="hypertension", label="CONDITION"),
    Entity(text="depression", label="CONDITION"),
    Entity(text="chronic atrial fibrillation", label="CONDITION"),
    Entity(text="severe nausea and vomiting", label="SYMPTOM"),
    Entity(text="urinary tract infection", label="CONDITION"),
])
Classification
from promptify import Classify

clf = Classify(model="gpt-4o-mini", labels=["positive", "negative", "neutral"])
result = clf("Amazing product! Best purchase I've ever made.")
# Classification(label="positive", confidence=0.95)
Question Answering
from promptify import QA

qa = QA(model="gpt-4o-mini")
answer = qa("Einstein was born in Ulm in 1879.", question="Where was Einstein born?")
# Answer(answer="Ulm", evidence="Einstein was born in Ulm", confidence=0.98)
Custom Task with Any Pydantic Schema
from promptify import Task
from pydantic import BaseModel

class MovieReview(BaseModel):
    sentiment: str
    rating: float
    key_themes: list[str]

task = Task(model="gpt-4o", output_schema=MovieReview, instruction="Analyze this movie review.")
review = task("Nolan's best work. Stunning visuals but the plot drags.")
# MovieReview(sentiment="mostly positive", rating=7.5, key_themes=["visuals", "pacing"])
Any Provider - Just Change the Model String
ner_openai = NER(model="gpt-4o-mini")
ner_claude = NER(model="claude-sonnet-4-20250514")
ner_local  = NER(model="ollama/llama3")
Batch Processing
results = ner.batch(["text1", "text2", "text3"], max_concurrent=10)
Async Support
result = await ner.acall("Patient has diabetes")
Built-in Evaluation
from promptify.eval import evaluate

scores = evaluate(task=ner, dataset=labeled_data, metrics=["precision", "recall", "f1"])
# {"precision": 0.92, "recall": 0.88, "f1": 0.90}
Features
- 2-3 lines of code for any NLP task -no training data required
- Pydantic structured outputs -type-safe results, not raw strings
- Any LLM provider via LiteLLM -OpenAI, Anthropic, Google, Ollama, Azure, and 100+ more
- Built-in tasks -NER, Classification (binary/multiclass/multilabel), QA, Summarization, Relation Extraction, SQL Generation, and more
- Custom tasks -bring your own Pydantic schema for any structured output
- Few-shot examples -easily add examples to improve accuracy
- Domain specialization -pass
domain="medical"or any domain for context-aware prompts - Batch processing -async concurrency under the hood for processing multiple texts
- Async support -native
awaitsupport withacall() - Evaluation framework -precision, recall, F1, accuracy, exact match, ROUGE metrics
- Safe parser -fallback JSON completion for providers without native structured outputs (no
eval()) - Cost tracking -built-in token usage and cost monitoring via
get_cost_summary()
Supported NLP Tasks
| Task | Class | Output Schema |
|---|---|---|
| Named Entity Recognition | NER |
NERResult (list of Entity) |
| Binary Classification | Classify |
Classification |
| Multiclass Classification | Classify |
Classification |
| Multilabel Classification | Classify(multi_label=True) |
MultiLabelResult |
| Question Answering | QA |
Answer |
| Summarization | Summarize |
Summary |
| Relation Extraction | ExtractRelations |
ExtractionResult |
| Tabular Extraction | ExtractTable |
ExtractionResult |
| Question Generation | GenerateQuestions |
list of GeneratedQuestion |
| SQL Generation | GenerateSQL |
SQLQuery |
| Text Normalization | NormalizeText |
normalized text |
| Topic Modelling | ExtractTopics |
list of topics |
| Custom Task | Task |
any Pydantic BaseModel |
Community

@misc{Promptify2022,
  title = {Promptify: Structured Output from LLMs},
  author = {Pal, Ankit},
  year = {2022},
  howpublished = {\url{https://github.com/promptslab/Promptify}},
  note = {Prompt-Engineering components for NLP tasks in Python}
}
💁 Contributing
We welcome any contributions to our open source project, including new features, improvements to infrastructure, and more comprehensive documentation. Please see the contributing guidelines
관련 프로젝트 살펴보기
tensorflow/tensorflow
모두를 위한 오픈소스 머신러닝 프레임워크
201,388 스타huggingface/transformers
🤗 Transformers: 텍스트, 비전, 오디오, 멀티모달 분야의 최첨단 머신러닝 모델을 위한 모델 정의 프레임워크로, 추론과 학습을 모두 지원합니다.
168,636 스타AUTOMATIC1111/stable-diffusion-webui
Stable Diffusion 웹 UI
165,251 스타Comfy-Org/ComfyUI
그래프와 노드로 구성된 인터페이스를 갖춘, 가장 강력하고 모듈성이 뛰어난 확산 모델 GUI, API, 백엔드입니다. 세계에서 가장 빠른 로컬 추론 엔진입니다.
145,629 스타