
omerbt/Text2LIVE
omerbt/Text2LIVE has 884 GitHub stars and 74 forks. GitHot measured 0 stars in 24 hours and 0 in 7 days. Last checked 2026-11-21 23:42 UTC. Last push 2023-03-09.
측정된 스타 증가
- in 24h
- 0
- in 7 days
- 0
- in 15 days
- 기록 수집 중
- in 1 month
- 기록 수집 중
서로 겹치는 기간의 순증가량이며 일별 합계가 아닙니다. 측정값이 없으면 비워 둡니다. 스타는 관심도를 나타내며 품질을 보장하지 않습니다.
소개
Official Pytorch Implementation for "Text2LIVE: Text-Driven Layered Image and Video Editing" (ECCV 2022 Oral)
머신러닝README.md
OriginalText2LIVE: Text-Driven Layered Image and Video Editing (ECCV 2022 - Oral)
[Project Page]


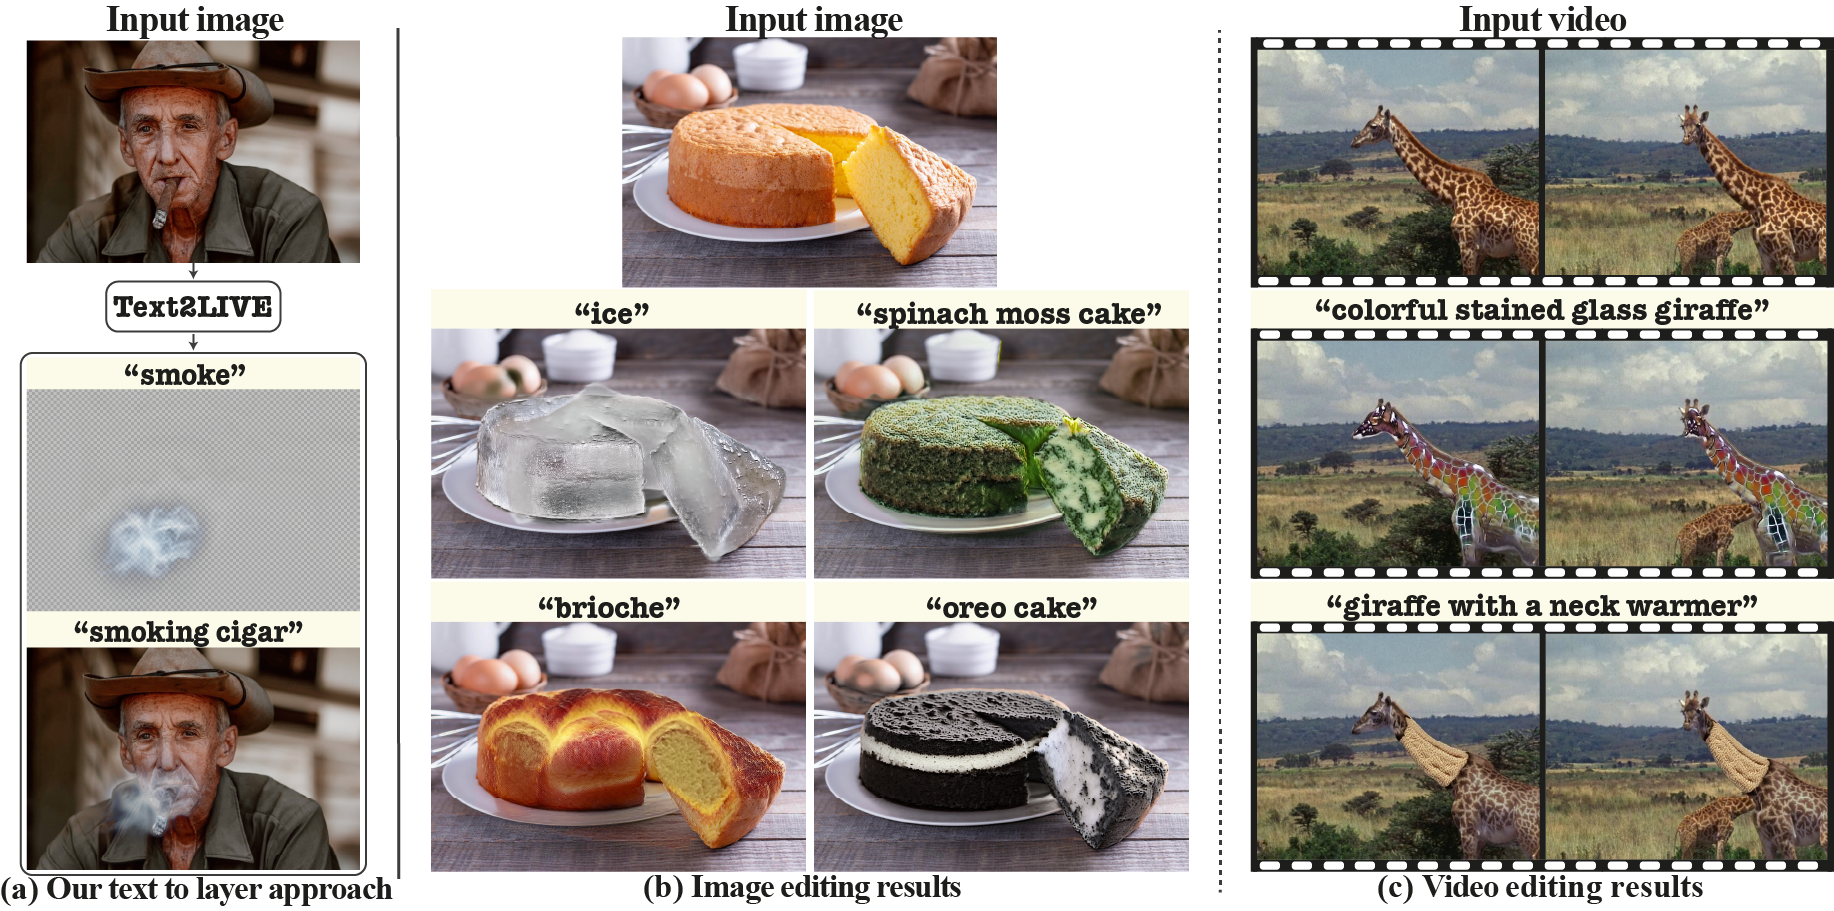
Text2LIVE is a method for text-driven editing of real-world images and videos, as described in (link to paper).
We present a method for zero-shot, text-driven appearance manipulation in natural images and videos. Specifically, given an input image or video and a target text prompt, our goal is to edit the appearance of existing objects (e.g., object's texture) or augment the scene with new visual effects (e.g., smoke, fire) in a semantically meaningful manner. Our framework trains a generator using an internal dataset of training examples, extracted from a single input (image or video and target text prompt), while leveraging an external pre-trained CLIP model to establish our losses. Rather than directly generating the edited output, our key idea is to generate an edit layer (color+opacity) that is composited over the original input. This allows us to constrain the generation process and maintain high fidelity to the original input via novel text-driven losses that are applied directly to the edit layer. Our method neither relies on a pre-trained generator nor requires user-provided edit masks. Thus, it can perform localized, semantic edits on high-resolution natural images and videos across a variety of objects and scenes.
Getting Started
Installation
git clone https://github.com/omerbt/Text2LIVE.git
conda create --name text2live python=3.9
conda activate text2live
pip install -r requirements.txt
Download sample images and videos
Download sample images and videos from the DAVIS dataset:
cd Text2LIVE
gdown https://drive.google.com/uc?id=1osN4PlPkY9uk6pFqJZo8lhJUjTIpa80J&export=download
unzip data.zip
It will create a folder data:
Text2LIVE
├── ...
├── data
│   ├── pretrained_nla_models # NLA models are stored here
│   ├── images # sample images
│   └── videos # sample videos from DAVIS dataset
│         ├── car-turn # contains video frames
│         ├── ...
└── ...
To enforce temporal consistency in video edits, we utilize the Neural Layered Atlases (NLA). Pretrained NLA models are taken from here, and are already inside the data folder.
Run examples
- Our method is designed to change textures of existing objects / augment the scene with semi-transparent effects (e.g., smoke, fire). It is not designed for adding new objects or significantly deviating from the original spatial layout.
- Training Text2LIVE multiple times with the same inputs can lead to slightly different results.
- CLIP sometimes exhibits bias towards specific solutions (see figure 9 in the paper), thus slightly different text prompts may lead to different flavors of edits.
The required GPU memory depends on the input image/video size, but you should be good with a Tesla V100 32GB :). Currently mixed precision introduces some instability in the training process, but it could be added later.
Video Editing
Run the following command to start training
python train_video.py --example_config car-turn_winter.yaml
Image Editing
Run the following command to start training
python train_image.py --example_config golden_horse.yaml
Intermediate results will be saved to results during optimization. The frequency of saving intermediate results is indicated in the log_images_freq flag of the configuration.
Sample Results
For more see the supplementary material.
Citation
@inproceedings{bar2022text2live,
  title={Text2live: Text-driven layered image and video editing},
  author={Bar-Tal, Omer and Ofri-Amar, Dolev and Fridman, Rafail and Kasten, Yoni and Dekel, Tali},
  booktitle={European Conference on Computer Vision},
  pages={707--723},
  year={2022},
  organization={Springer}
}
관련 프로젝트 살펴보기
불러오는 중…