
mizorewww/laya-mlx
mizorewww/laya-mlx has 7,093 GitHub stars and 576 forks. GitHot measured +2 stars in 24 hours and +24 in 7 days. Last checked 2026-11-12 19:13 UTC. Last push 2026-10-29.
Laya 타입 결정 모델을 위한 네이티브 MLX 런타임 — M3 Max에서 짧은 결정을 7~14ms에 처리합니다. 텍스트 생성, PyTorch 또는 클라우드 API는 지원하지 않습니다.
측정된 스타 증가
- in 24h
- +2
- in 7 days
- +24
- in 15 days
- 업데이트 지연
- in 1 month
- 업데이트 지연
서로 겹치는 기간의 순증가량이며 일별 합계가 아닙니다. 측정값이 없으면 비워 둡니다. 스타는 관심도를 나타내며 품질을 보장하지 않습니다.
README.md
OriginalLaya-MLX
Open-weight typed decisions, running natively on Apple Silicon.
中文 · Usage reference · Benchmarks · Hugging Face weights · Changelog
Laya answers constrained questions (pick an option, score against a rubric, judge true or false) with calibrated probabilities from one bidirectional forward pass. It generates no tokens and returns no JSON to parse. This package runs the original Laya weights in MLX, without PyTorch, Transformers or a cloud API.
13.4 ms median for a short English decision, 7.4 ms with the multilingual checkpoint (M3 Max, FP16).
Quick start
Requires Apple Silicon, macOS 14+ and Python 3.11+.
pip install laya-mlx
import laya_mlx as laya

agent = laya.load("aac6fef/laya-mlx")
result = agent.predict(
    "I was billed twice. Please refund the duplicate.",
    {
        "department": {
            "type": "choice",
            "instructions": "Which department should handle this request?",
            "criteria": {
                "billing": "Payments, invoices, refunds, and duplicate charges.",
                "technical": "Broken features, errors, and product troubleshooting.",
                "sales": "Pricing, upgrades, and new purchases.",
            },
        },
        "refund": {
            "type": "noul",
            "instructions": "Does the customer ask for money back?",
        },
    },
)
print(result["answers"]["department"]["choice"])  # billing
Describing each option, as above, works much better than bare labels. The first load downloads the checkpoint; later inference is fully local.
Question types
| Type | You provide | You get |
|---|---|---|
choice |
Named options, as a list or a label → description dict | Probability per option |
score |
Ordered rubric levels | Probability per level and the expected level |
noul |
A yes/no proposition | P(true) |
States can be text, JSON-like dicts or conversation lists. Each answer carries calibrated probabilities and confidence fields; confidence does not guarantee accuracy on a new task.
Checkpoints
| Pre-converted MLX (FP16) | Original | Parameters | Context | Use |
|---|---|---|---|---|
aac6fef/laya-mlx |
convaiinnovations/laya |
421M | 512 | English |
aac6fef/laya-multilingual-mlx |
convaiinnovations/laya-multilingual |
322M | 1,024 | Multilingual input |
aac6fef/laya-typed-decisions-mlx |
convaiinnovations/laya-typed-decisions |
421M | 1,024 | Upstream typed-decisions workflows |
laya.load accepts either column. Context counts instructions, options and state together.
Each published checkpoint includes its model card, validation results, provenance and
checksums (pinned revisions and hashes).
What else it does
All of these are covered in the usage reference:
- Language routing:
Router()detects the language, picks a checkpoint and keeps up to two resident. You can register your own checkpoints. - Batches and long documents:
predict_batchshares forward passes across identical question schemas, and long-text scanning keeps answer attribution. - Confidence gate:
min_confidence=marks low-confidence answers for review without changing them. - Large choice sets:
predict_shortlist(embedding pre-filter) andpredict_tournament(no embedder). - Throughput options:
compile=True,pad_to_multiple=16andcache_prompts=Truefor repeated workloads. - Tools and services: CLI (
laya-mlx predict), HTTP (laya-mlx-serve), MCP (laya-mlx-mcp-server), evaluation and calibration, and LangChain/LlamaIndex/CrewAI/Agno integrations, installed as extras. - Export:
laya-mlx convertwrites a standalone MLX checkpoint.
Performance
M3 Max (40-core GPU, 128 GiB), FP16, end to end:
| Laya 421M | Multilingual 322M | |
|---|---|---|
| One short question, P50 / P95 | 13.42 / 13.92 ms | 7.39 / 7.79 ms |
| 50-question throughput | 146.8 q/s | 395.0 q/s |
| Peak MLX allocation, one question | 943.6 MiB | 687.6 MiB |
Timings include prompt preparation, tokenization, inference, calibration and formatting;
model loading is excluded. The throughput row uses batch_size=64 (the default is 16).
Latency varies with input length, question count and system load.
All three checkpoints matched upstream's selected answer on 63/63 validation questions in FP32 and FP16 (378/378 comparisons), with deterministic repeated calls and no measured memory growth. That measures port fidelity on those fixtures, not task accuracy. Method, every timing sample and probability errors.
Snake demo
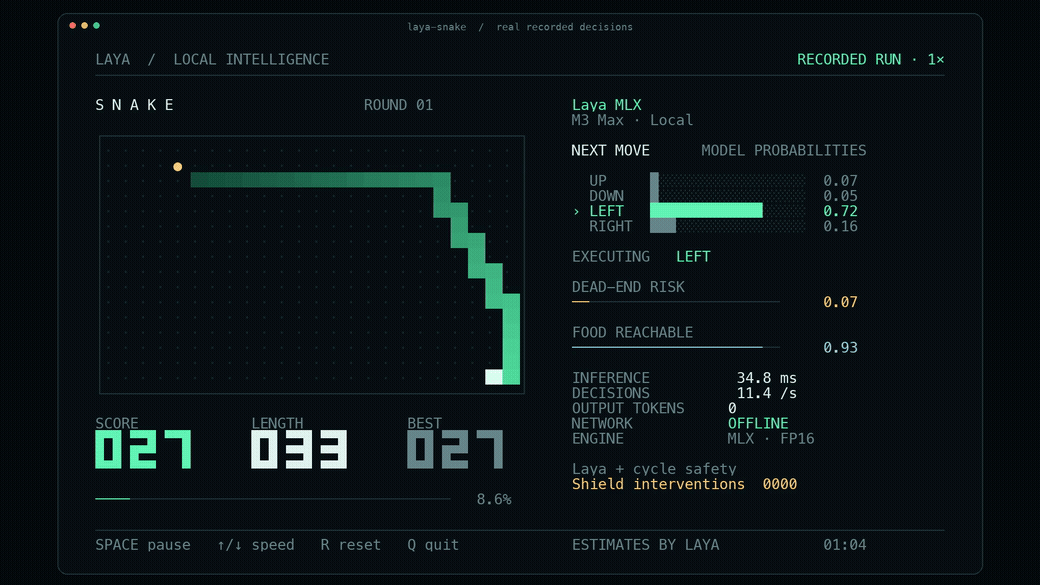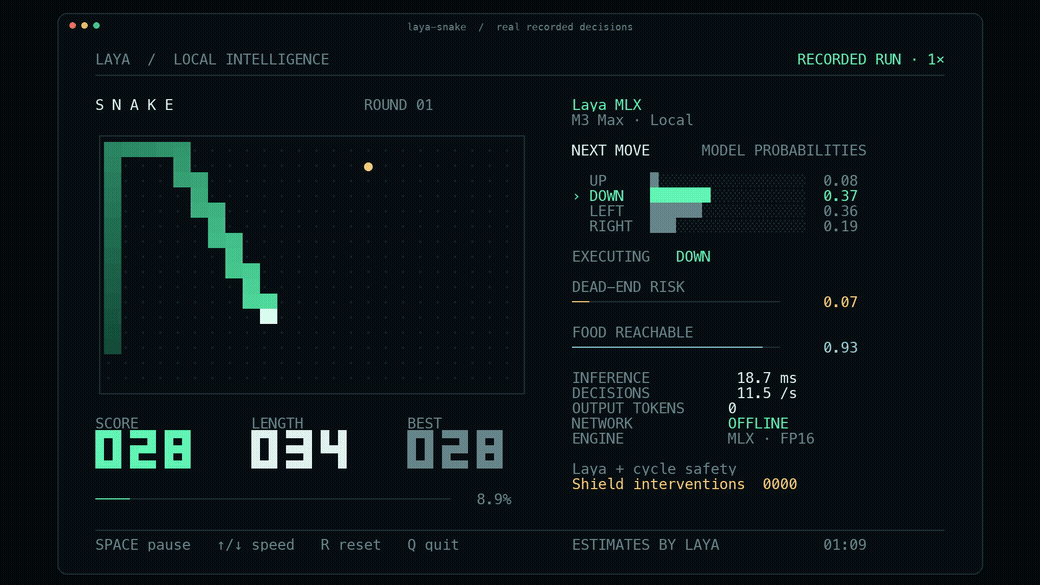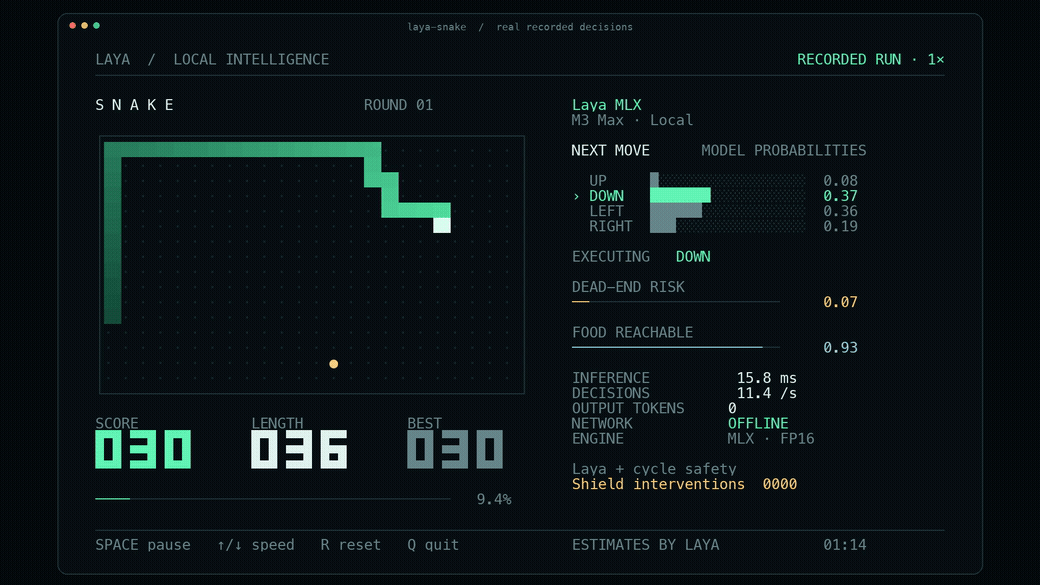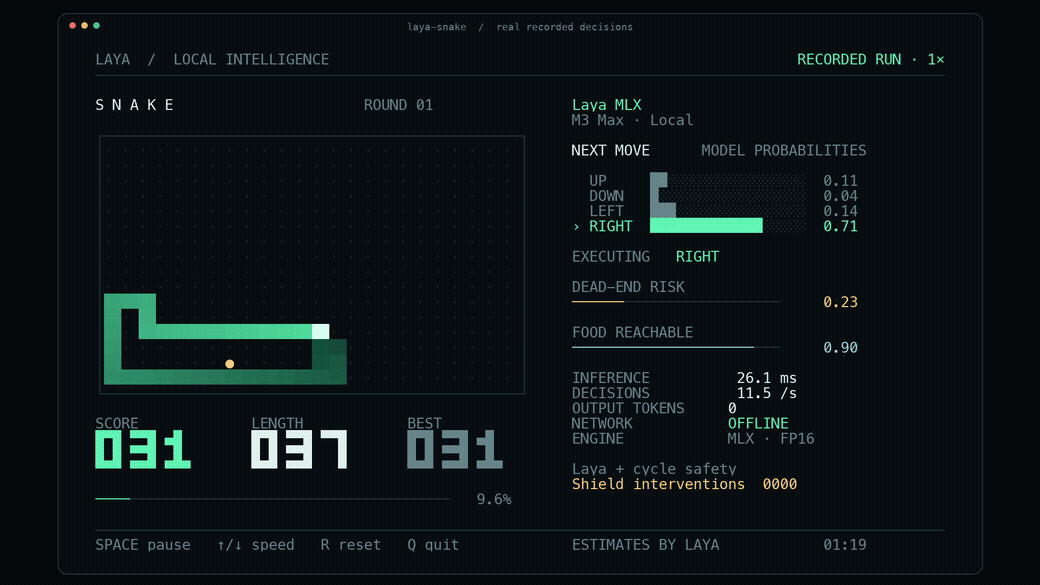
The GIF above is a real local run at original speed: every move asks Laya three questions, and a visible safety layer can override unsafe moves.
pip install 'laya-mlx[demo]'
hf download aac6fef/laya-multilingual-mlx
laya-snake                      # paced; add --max-speed to remove pacing
laya-snake --optimize --max-speed
The terminal must be at least 104 × 35. Space pauses, ↑/↓ changes speed, R resets, Q quits.
With --optimize, the measured M3 Max run reached 75.4 moves/s over 2,400 moves with zero
deaths. Demo guide ·
speed and stability ·
optimization.
Relationship to upstream
This is an independent port, not an official Convai Innovations release. Prompt formatting, calibration, routing, output schema and host APIs follow NandhaKishorM/laya v0.4.17; the encoder and decision heads are reimplemented in MLX. CUDA, ONNX, PyTorch backend controls and training are out of scope. RLCD training and fine-tuning stay upstream. Native boundaries · v0.4.17 migration record · all documentation.
Contributing
Bug reports and pull requests are welcome. Upstream-compatible fixes take priority over new features. See CONTRIBUTING.md for the development setup, tests, benchmarks and release process.
License
Apache-2.0; see LICENSE and NOTICE. Laya and its pretrained weights are by Convai Innovations and upstream contributors. The neural architecture follows Laya and Hugging Face ModernBERT.
관련 프로젝트 살펴보기
tensorflow/tensorflow
모두를 위한 오픈소스 머신러닝 프레임워크
201,584 스타huggingface/transformers
🤗 Transformers: 텍스트, 비전, 오디오, 멀티모달 분야의 최첨단 머신러닝 모델을 위한 모델 정의 프레임워크로, 추론과 학습을 모두 지원합니다.
168,917 스타AUTOMATIC1111/stable-diffusion-webui
Stable Diffusion 웹 UI
165,300 스타Comfy-Org/ComfyUI
그래프와 노드로 구성된 인터페이스를 갖춘, 가장 강력하고 모듈성이 뛰어난 확산 모델 GUI, API, 백엔드입니다. 세계에서 가장 빠른 로컬 추론 엔진입니다.
146,472 스타