
google-research-datasets/Objectron
google-research-datasets/Objectron has 2,360 GitHub stars and 268 forks. GitHot measured -1 stars in 24 hours, 0 in 7 days, and +2 in 15 days. Last checked 2026-11-10 19:01 UTC. Last push 2026-03-06.
Objectron is a dataset of short, object-centric video clips. In addition, the videos also contain AR session metadata including camera poses, sparse point-clouds and planes. In each video, the camera moves around and above the object and captures it from different views. Each object is annotated with a 3D bounding box. The 3D bounding box describes the object’s position, orientation, and dimensions. The dataset contains about 15K annotated video clips and 4M annotated images in the following categories: bikes, books, bottles, cameras, cereal boxes, chairs, cups, laptops, and shoes
What you can do
- 15000 annotated videos and 4M annotated images
- All samples include high-res images, object pose, camera pose, point-cloud, and surface planes.
- Ready to use examples in various tf.record formats, which can be used in Tensorflow/PyTorch.
- Object-centric multi-views, observing the same object from different angles.
측정된 스타 증가
- in 24h
- -1
- in 7 days
- 0
- in 15 days
- +2
- in 1 month
- 업데이트 지연
서로 겹치는 기간의 순증가량이며 일별 합계가 아닙니다. 측정값이 없으면 비워 둡니다. 스타는 관심도를 나타내며 품질을 보장하지 않습니다.
README.md
OriginalObjectron Dataset
Objectron is a dataset of short object centric video clips with pose annotations.
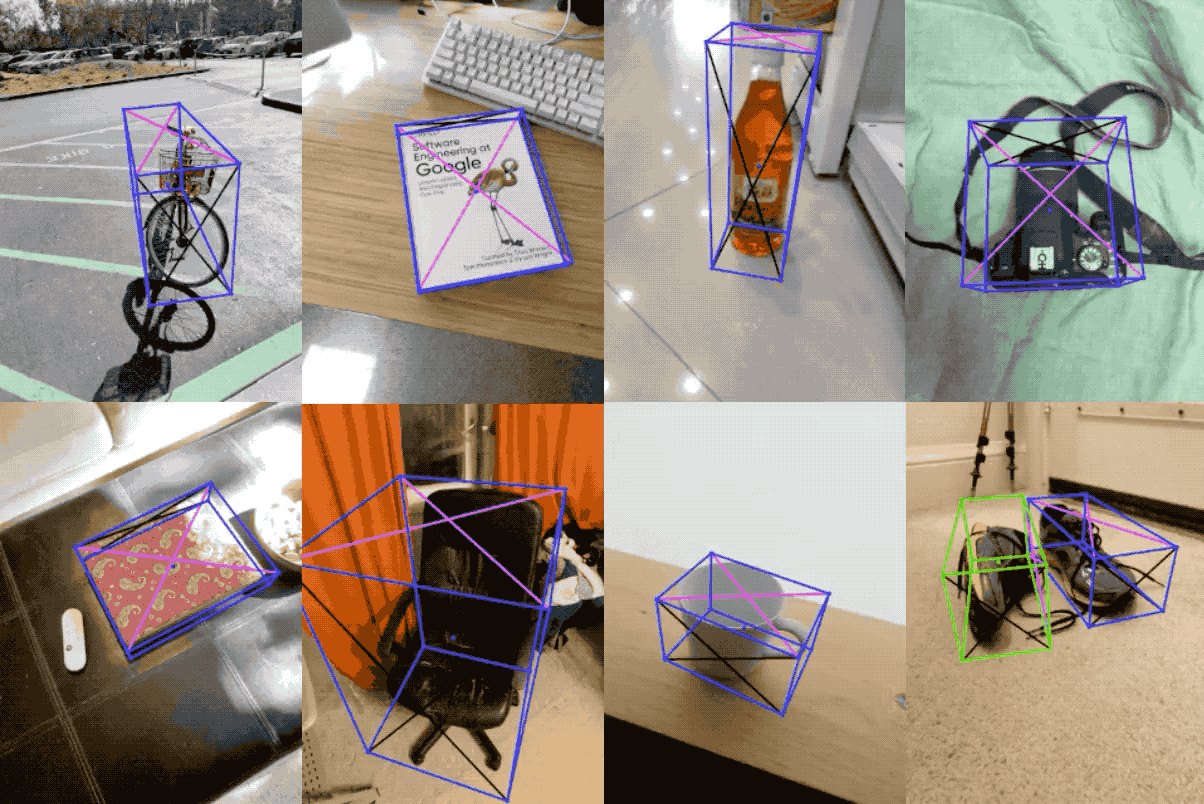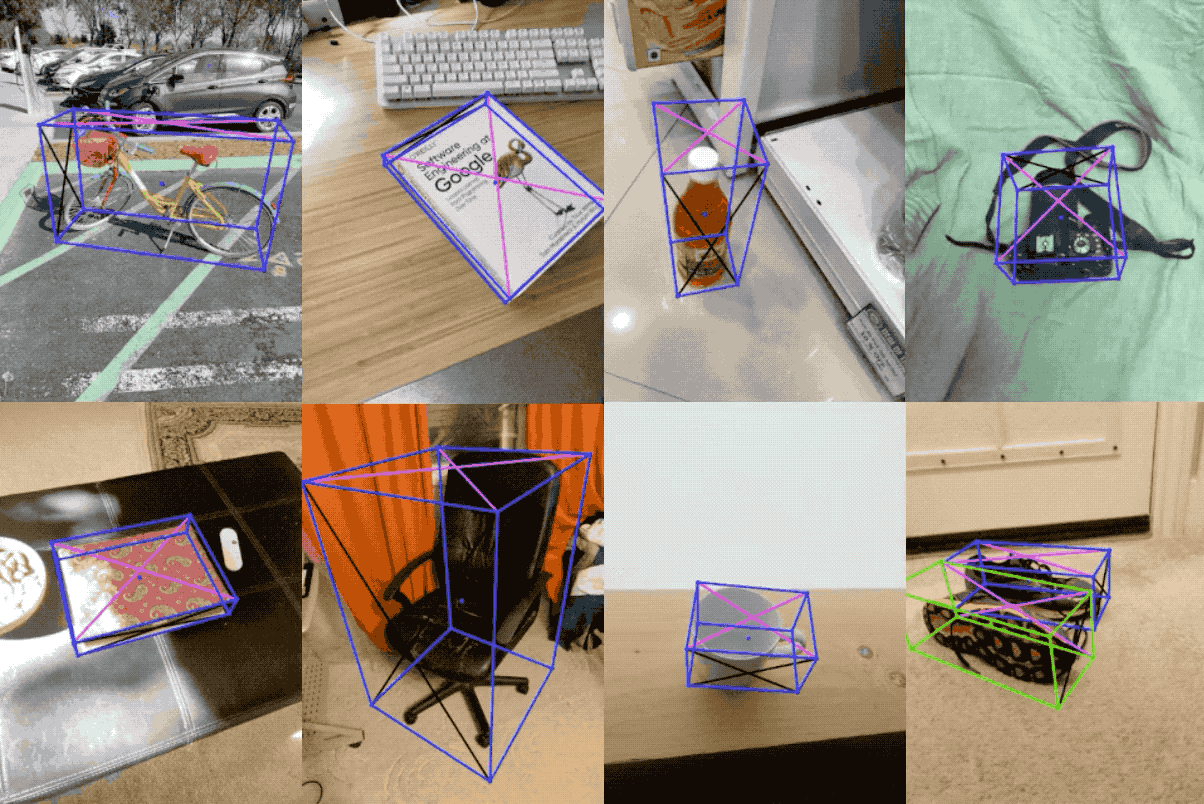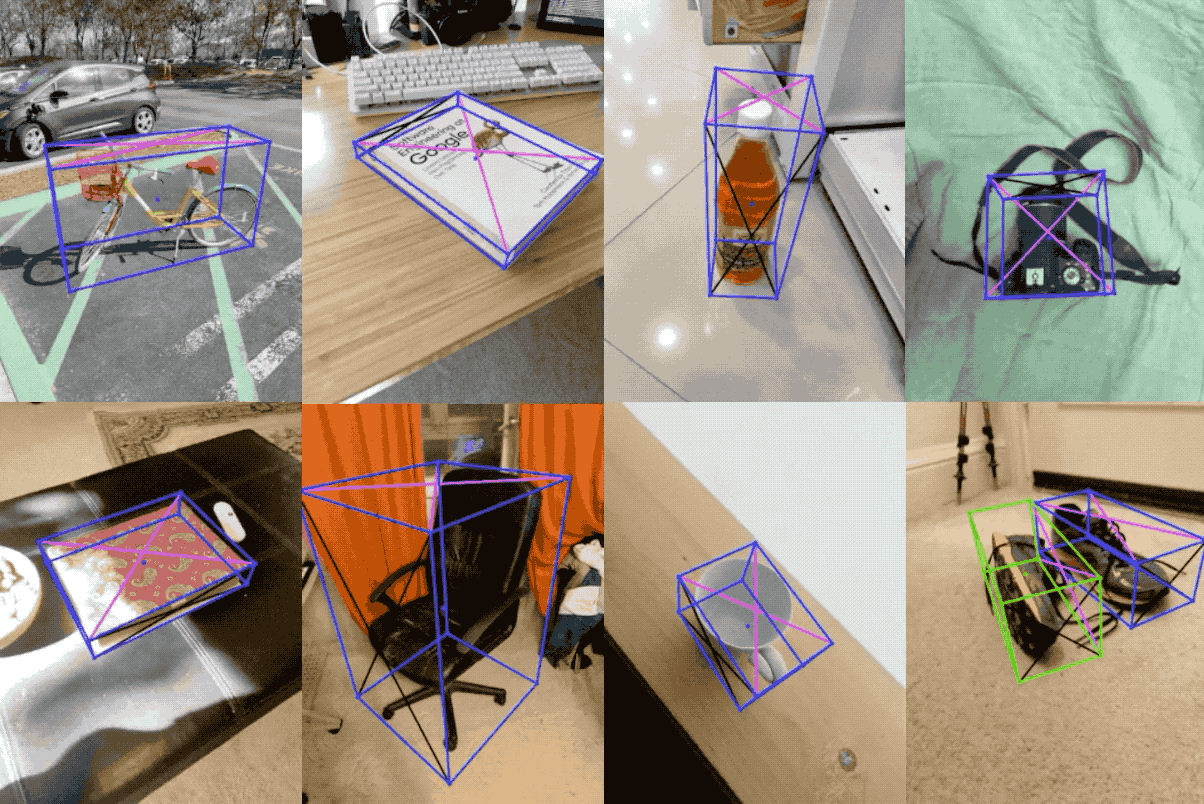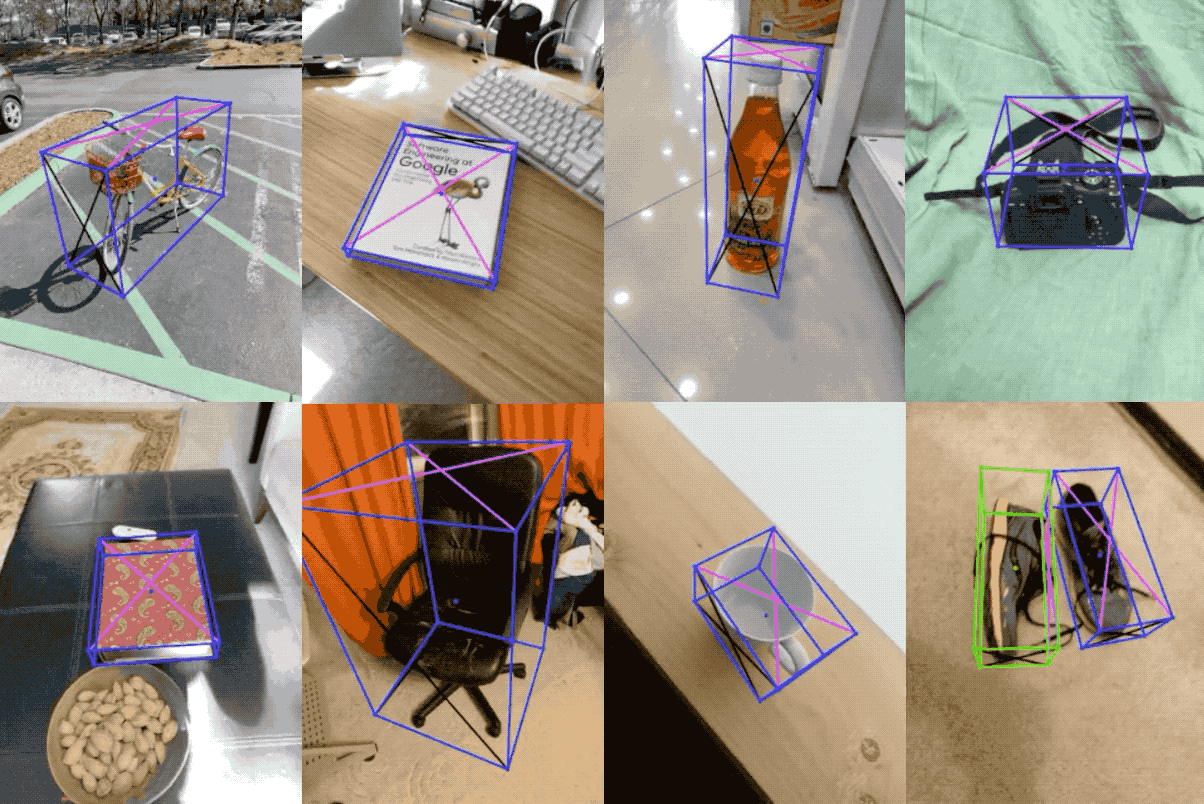
The Objectron dataset is a collection of short, object-centric video clips, which are accompanied by AR session metadata that includes camera poses, sparse point-clouds and characterization of the planar surfaces in the surrounding environment. In each video, the camera moves around the object, capturing it from different angles. The data also contain manually annotated 3D bounding boxes for each object, which describe the object’s position, orientation, and dimensions. The dataset consists of 15K annotated video clips supplemented with over 4M annotated images in the following categories: bikes, books, bottles, cameras, cereal boxes, chairs, cups, laptops, and shoes. In addition, to ensure geo-diversity, our dataset is collected from 10 countries across five continents. Along with the dataset, we are also sharing a 3D object detection solution for four categories of objects — shoes, chairs, mugs, and cameras. These models are trained using this dataset, and are released in MediaPipe, Google's open source framework for cross-platform customizable ML solutions for live and streaming media.
Key Features
- 15000 annotated videos and 4M annotated images
- All samples include high-res images, object pose, camera pose, point-cloud, and surface planes.
- Ready to use examples in various tf.record formats, which can be used in Tensorflow/PyTorch.
- Object-centric multi-views, observing the same object from different angles.
- Accurate evaluation metrics, like 3D IoU for oriented 3D bounding boxes.
Dataset Format
The data is stored in the objectron bucket on Google Cloud storage. Check out the Download Data notebook for a quick review of how to download/access the dataset. The following assets are available:
- The video sequences (located in
/videos/class/batch-i/j/video.MOVfiles) - The annotation labels containing the 3D bounding boxes for objects. The annotation protobufs are located in
/videos/class/batch-i/j/geometry.pbdatafiles. They are formatted using the object.proto. See [example] on how to parse the annotation files. - AR metadata (such as camera poses, point clouds, and planar surfaces). They are based on a_r_capture_metadata.proto. See example on how to parse these files.
- Processed dataset: sharded and shuffled
tf.recordsof the annotated frames, in tf.example format and videos intf.SequenceExampleformat. These are used for creating the input data pipeline to your models. These files are located in/v1/records_shuffled/class/and/v1/sequences/class/. - Supporting scripts to run evaluation based on the 3D IoU metric.
- Supporting scripts to load the data into Tensorflow, Jax and Pytorch and visualize the dataset, including “Hello World” examples.
- Supporting Apache Beam jobs to process the datasets on Google Cloud infrastructure.
- The index of all available samples, as well as train/test splits for easy access and download.
Raw dataset size is 1.9TB (including videos and their annotations). Total dataset size is 4.4TB (including videos, records, sequences, etc.). This repository provides the required schemas and tools to parse the dataset.
| class | bike | book | bottle | camera | cereal_box | chair | cup | laptop | shoe |
|---|---|---|---|---|---|---|---|---|---|
| #videos | 476 | 2024 | 1928 | 815 | 1609 | 1943 | 2204 | 1473 | 2116 |
| #frames | 150k | 576k | 476k | 233k | 396k | 488k | 546k | 485k | 557k |
Tutorials
- Downloading the dataset
- Hello, World example: Loading examples in Tensorflow
- Loading data in PyTorch
- Parsing raw annotation files
- Parsing the AR metadata
- Evaluating the model performance with 3D IoU
- SequenceExample tutorial
- Training a NeRF model
License
Objectron is released under Computational Use of Data Agreement 1.0 (C-UDA-1.0). A copy of the license is available in this repository.
BibTeX
If you found this dataset useful, please cite our paper.
@article{objectron2021,
  title={Objectron: A Large Scale Dataset of Object-Centric Videos in the Wild with Pose Annotations},
  author={Adel Ahmadyan, Liangkai Zhang, Artsiom Ablavatski, Jianing Wei, Matthias Grundmann},
  journal={Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition},
  year={2021}
}
This is not an officially supported Google product. If you have any question, you can email us at [email protected] or join our mailing list at [email protected]
관련 프로젝트 살펴보기
tensorflow/tensorflow
모두를 위한 오픈소스 머신러닝 프레임워크
201,505 스타huggingface/transformers
🤗 Transformers: 텍스트, 비전, 오디오, 멀티모달 분야의 최첨단 머신러닝 모델을 위한 모델 정의 프레임워크로, 추론과 학습을 모두 지원합니다.
168,815 스타AUTOMATIC1111/stable-diffusion-webui
Stable Diffusion 웹 UI
165,289 스타Comfy-Org/ComfyUI
그래프와 노드로 구성된 인터페이스를 갖춘, 가장 강력하고 모듈성이 뛰어난 확산 모델 GUI, API, 백엔드입니다. 세계에서 가장 빠른 로컬 추론 엔진입니다.
146,271 스타