
YudongGuo/AD-NeRF
YudongGuo/AD-NeRF has 1,072 GitHub stars and 177 forks. GitHot measured 0 in 7 days. Last checked 2026-11-11 01:09 UTC. Last push 2023-10-27.
This repository contains a PyTorch implementation of "AD-NeRF: Audio Driven Neural Radiance Fields for Talking Head Synthesis".
측정된 스타 증가
- in 24h
- 업데이트 지연
- in 7 days
- 0
- in 15 days
- 기록 수집 중
- in 1 month
- 기록 수집 중
서로 겹치는 기간의 순증가량이며 일별 합계가 아닙니다. 측정값이 없으면 비워 둡니다. 스타는 관심도를 나타내며 품질을 보장하지 않습니다.
README.md
OriginalAD-NeRF: Audio Driven Neural Radiance Fields for Talking Head Synthesis
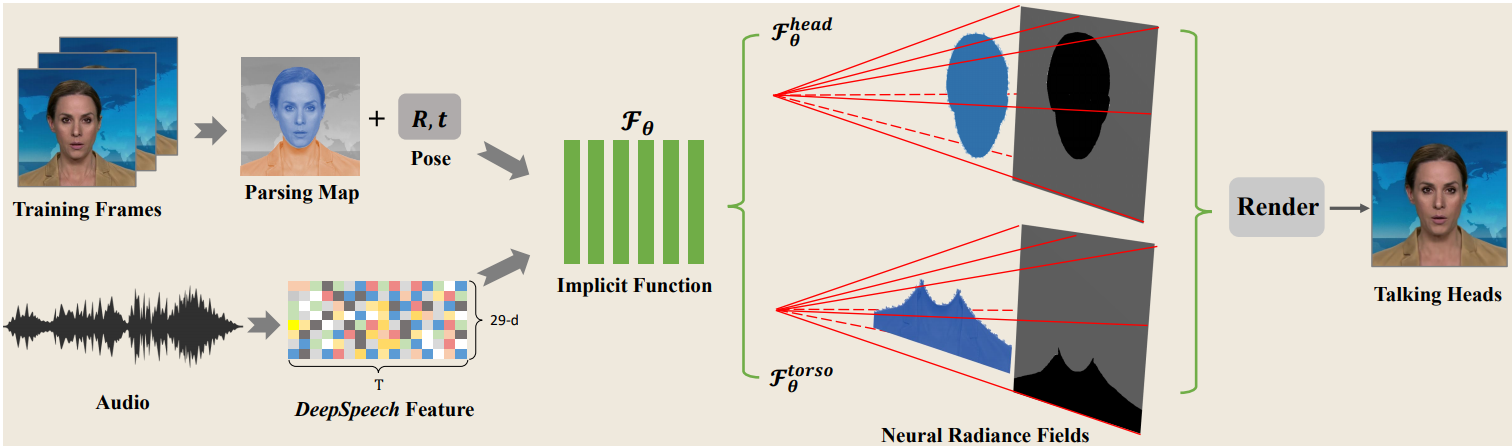
PyTorch implementation for the paper "AD-NeRF: Audio Driven Neural Radiance Fields for Talking Head Synthesis (ICCV 2021)".
Authors: Yudong Guo, Keyu Chen, Sen Liang, Yong-Jin Liu, Hujun Bao and Juyong Zhang.
Prerequisites
You can create an anaconda environment called adnerf with:
conda env create -f environment.yml conda activate adnerf-
Recommend install from a local clone
git clone https://github.com/facebookresearch/pytorch3d.git cd pytorch3d && pip install -e . -
Put "01_MorphableModel.mat" to data_util/face_tracking/3DMM/; cd data_util/face_tracking; run
python convert_BFM.py
Train AD-NeRF
Data Preprocess ($id Obama for example)
bash process_data.sh Obama- Input: A portrait video at 25fps containing voice audio. (dataset/vids/$id.mp4)
- Output: folder dataset/$id that contains all files for training
Train Two NeRFs (Head-NeRF and Torso-NeRF)
- Train Head-NeRF with command
python NeRFs/HeadNeRF/run_nerf.py --config dataset/$id/HeadNeRF_config.txt - Copy latest trainied model from dataset/$id/logs/$id_head to dataset/$id/logs/$id_com
- Train Torso-NeRF with command
python NeRFs/TorsoNeRF/run_nerf.py --config dataset/$id/TorsoNeRF_config.txt - You may need the pretrained models to avoid bad initialization. #3
- Train Head-NeRF with command
Run AD-NeRF for rendering
- Reconstruct original video with audio input
python NeRFs/TorsoNeRF/run_nerf.py --config dataset/$id/TorsoNeRFTest_config.txt --aud_file=dataset/$id/aud.npy --test_size=300 - Drive the target person with another audio input
python NeRFs/TorsoNeRF/run_nerf.py --config dataset/$id/TorsoNeRFTest_config.txt --aud_file=${deepspeechfile.npy} --test_size=-1
Citation
If you find our work useful in your research, please consider citing our paper:
@inproceedings{guo2021adnerf,
  title={AD-NeRF: Audio Driven Neural Radiance Fields for Talking Head Synthesis},
  author={Yudong Guo and Keyu Chen and Sen Liang and Yongjin Liu and Hujun Bao and Juyong Zhang},
  booktitle={IEEE/CVF International Conference on Computer Vision (ICCV)},
  year={2021}
}
If you have questions, feel free to contact [email protected].
Acknowledgments
We use face-parsing.PyTorch for parsing head and torso maps, and DeepSpeech for audio feature extraction. The NeRF model is implemented based on NeRF-pytorch.
관련 프로젝트 살펴보기
tensorflow/tensorflow
모두를 위한 오픈소스 머신러닝 프레임워크
201,427 스타huggingface/transformers
🤗 Transformers: 텍스트, 비전, 오디오, 멀티모달 분야의 최첨단 머신러닝 모델을 위한 모델 정의 프레임워크로, 추론과 학습을 모두 지원합니다.
168,711 스타AUTOMATIC1111/stable-diffusion-webui
Stable Diffusion 웹 UI
165,289 스타Comfy-Org/ComfyUI
그래프와 노드로 구성된 인터페이스를 갖춘, 가장 강력하고 모듈성이 뛰어난 확산 모델 GUI, API, 백엔드입니다. 세계에서 가장 빠른 로컬 추론 엔진입니다.
146,271 스타