
XinJingHao/DRL-Pytorch
XinJingHao/DRL-Pytorch has 3,463 GitHub stars and 389 forks. GitHot measured +3 in 7 days. Last checked 2026-11-09 13:44 UTC. Last push 2025-06-11.
널리 사용되는 심층 강화 학습(DRL) 알고리즘(Q-learning, Duel DDQN, PER, C51, Noisy DQN, PPO, DDPG, TD3, SAC, ASL)을 깔끔하고 견고하게 통합한 PyTorch 구현
측정된 스타 증가
- in 24h
- 업데이트 지연
- in 7 days
- +3
- in 15 days
- 업데이트 지연
- in 1 month
- 업데이트 지연
서로 겹치는 기간의 순증가량이며 일별 합계가 아닙니다. 측정값이 없으면 비워 둡니다. 스타는 관심도를 나타내며 품질을 보장하지 않습니다.
README.md
Original


0.Star History
1.Dependencies
This repository uses the following python dependencies unless explicitly stated:
gymnasium==0.29.1
numpy==1.26.1
pytorch==2.1.0

python==3.11.5
2.How to use my code
Enter the folder of the algorithm that you want to use, and run the main.py to train from scratch:
python main.py
For more details, please check the README.md file in the corresponding algorithm folder.
3. Separate links of the code
- 1.Q-learning
- 2.1Duel Double DQN
- 2.2Noisy Duel DDQN on Atari Game
- 2.3Prioritized Experience Replay(PER) DQN/DDQN
- 2.4Categorical DQN (C51)
- 2.5NoisyNet DQN
- 3.1Proximal Policy Optimization(PPO) for Discrete Action Space
- 3.2Proximal Policy Optimization(PPO) for Continuous Action Space
- 4.1Deep Deternimistic Policy Gradient(DDPG)
- 4.2Twin Delayed Deep Deterministic Policy Gradient(TD3)
- 5.1Soft Actor Critic(SAC) for Discrete Action Space
- 5.2Soft Actor Critic(SAC) for Continuous Action Space
- 6.Actor-Sharer-Learner(ASL)
4. Recommended Resources for DRL
4.1 Simulation Environments:
- Isaac Sim (NVIDIA’s physics simulation environment; GPU accelerated; Superfast):
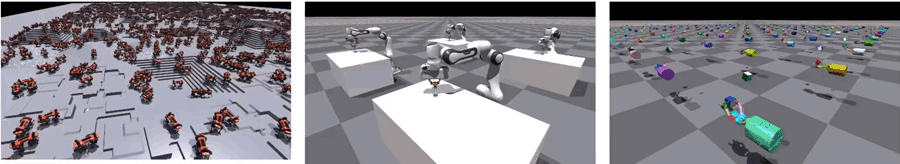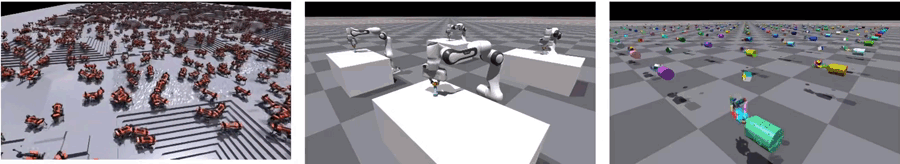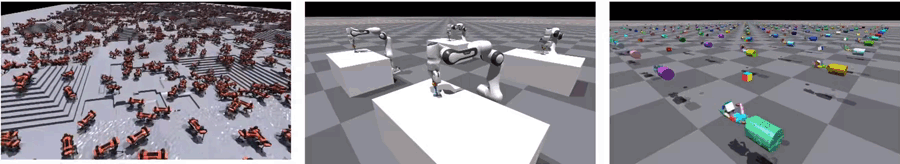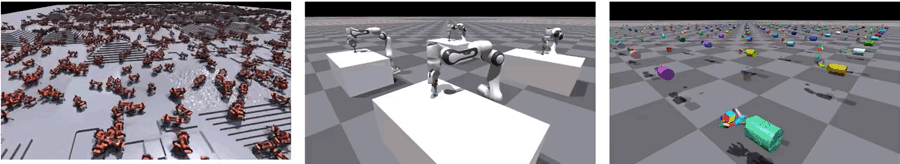
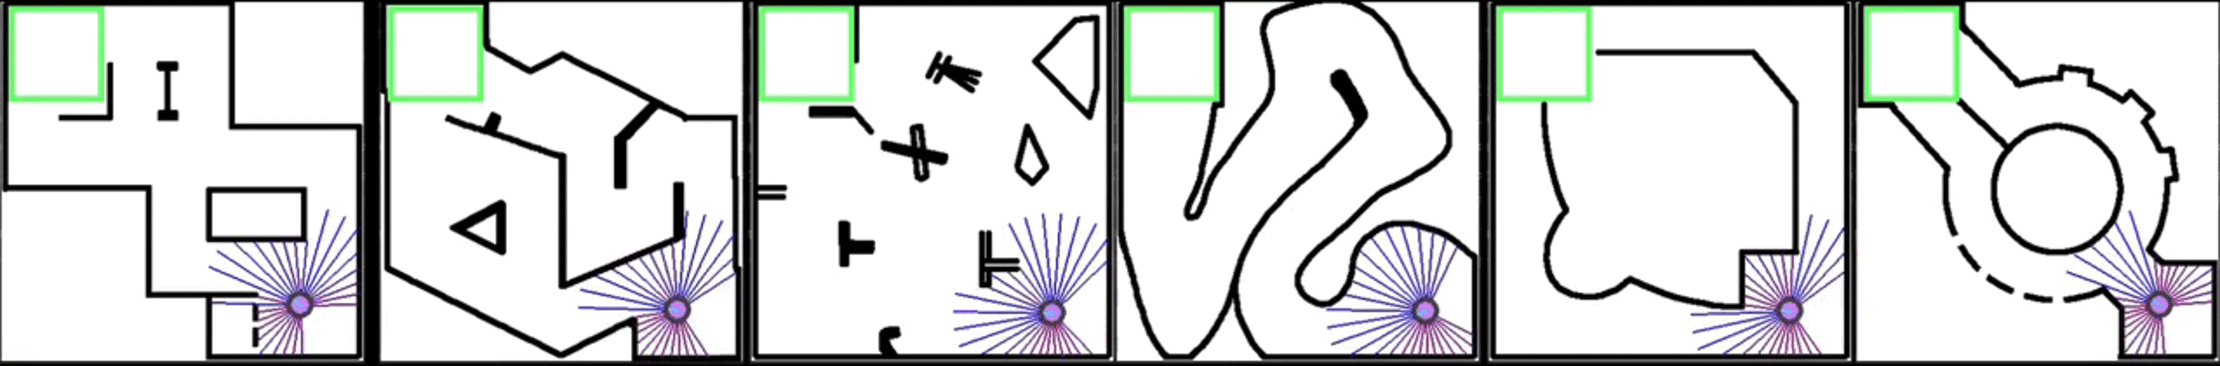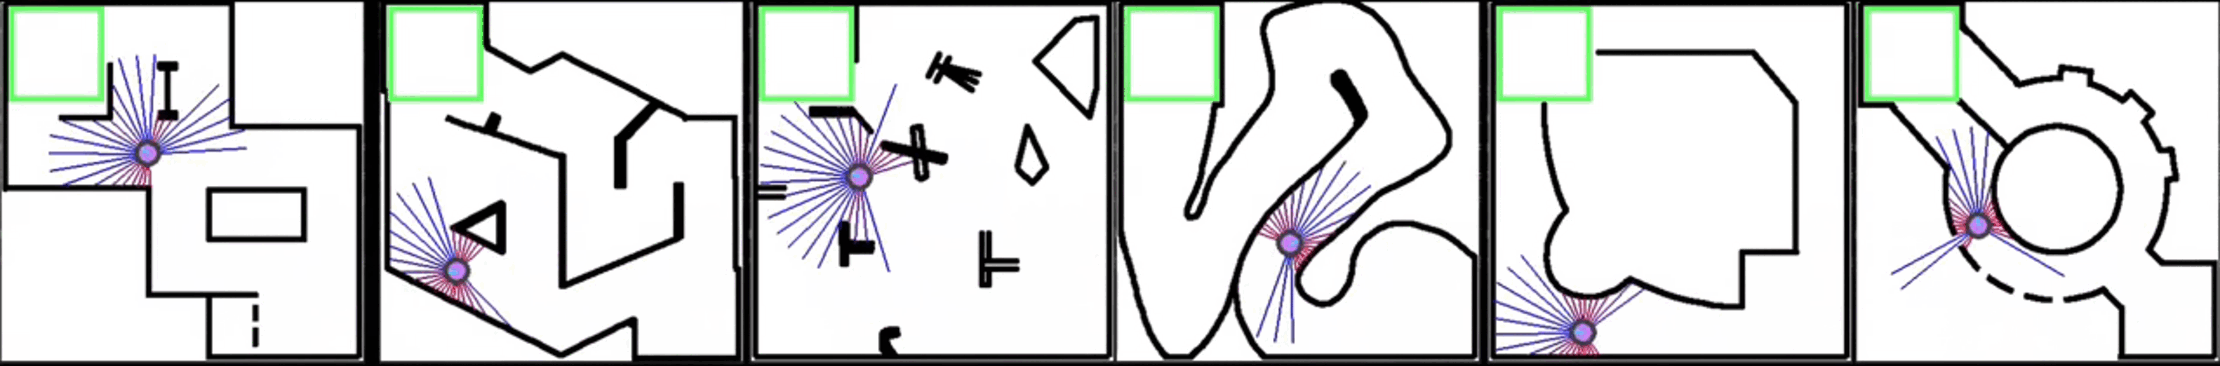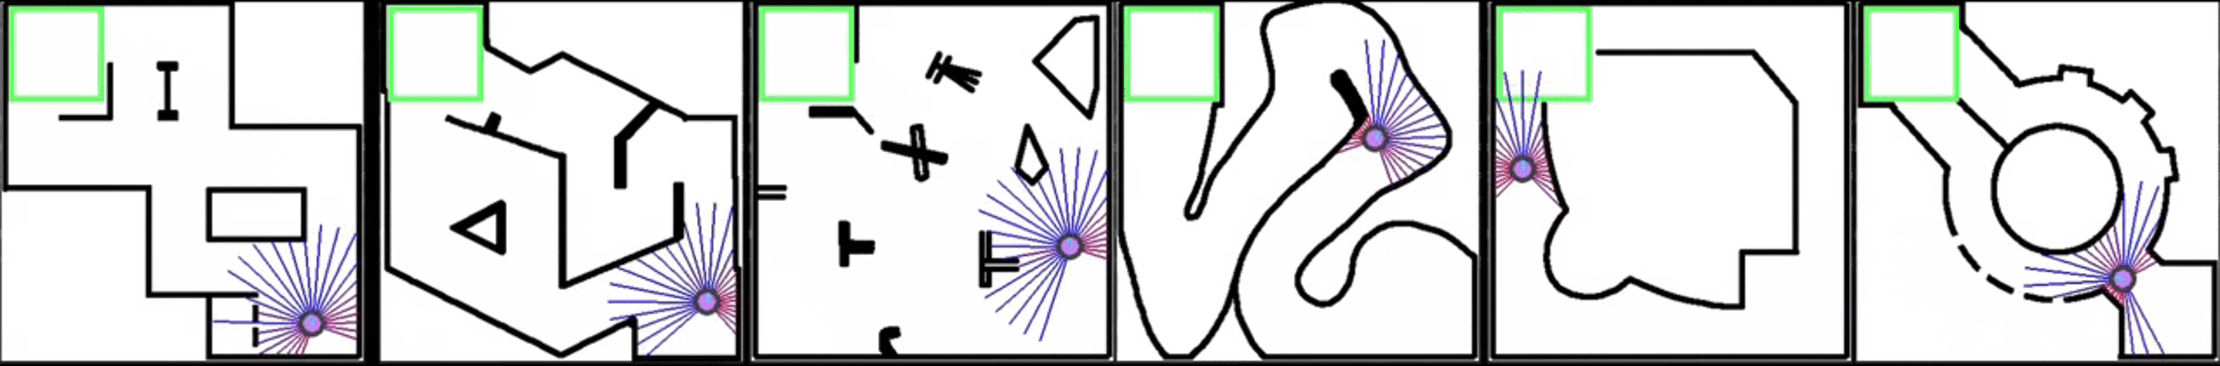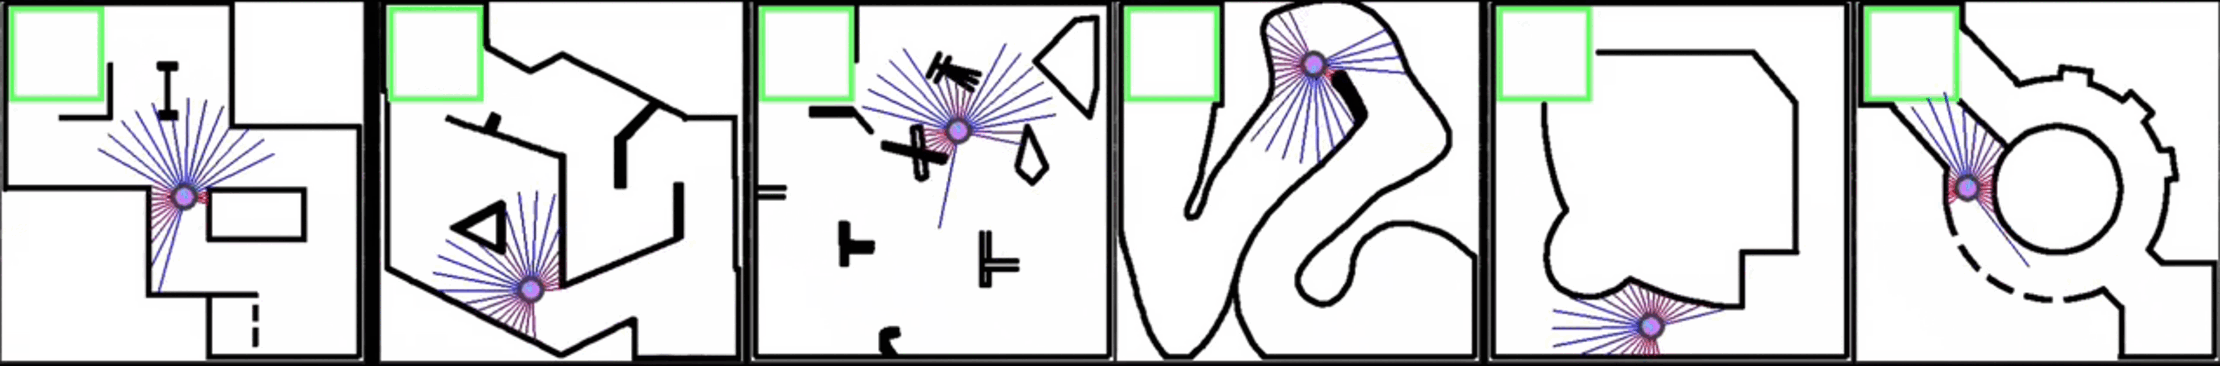
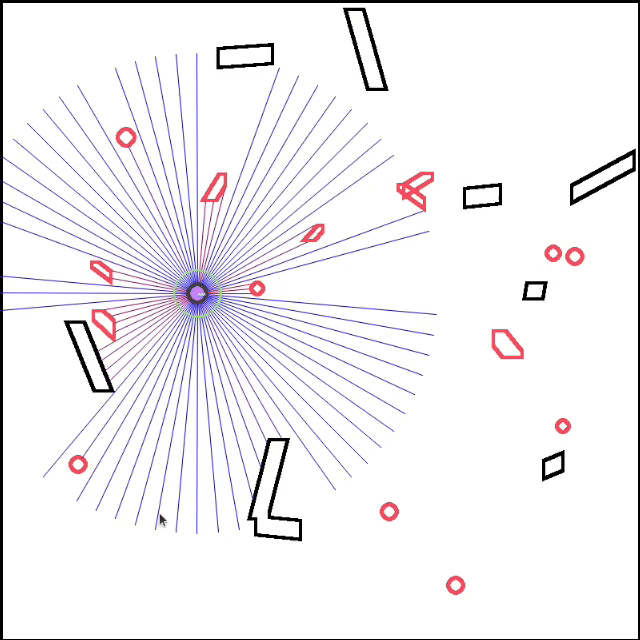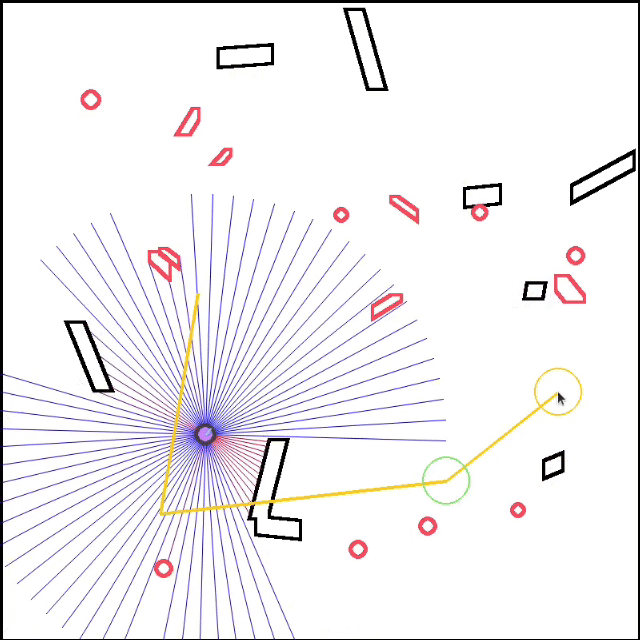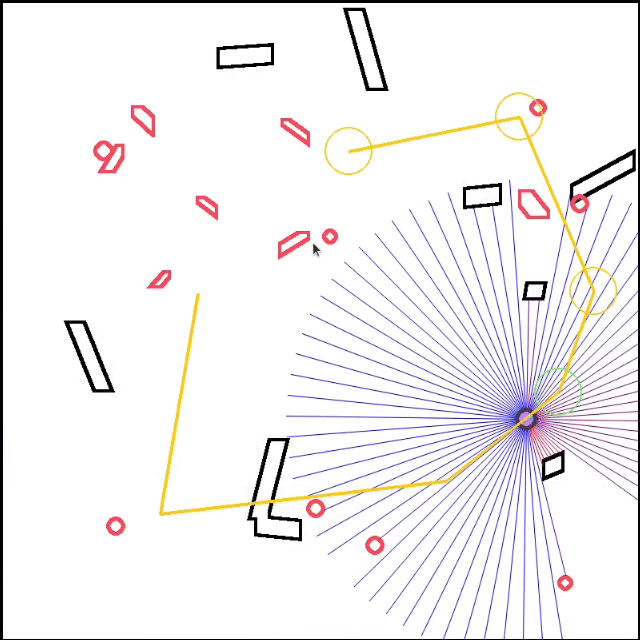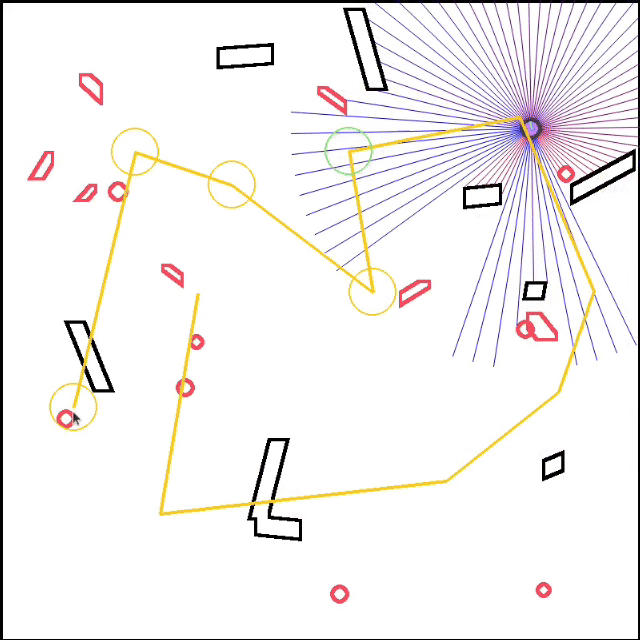
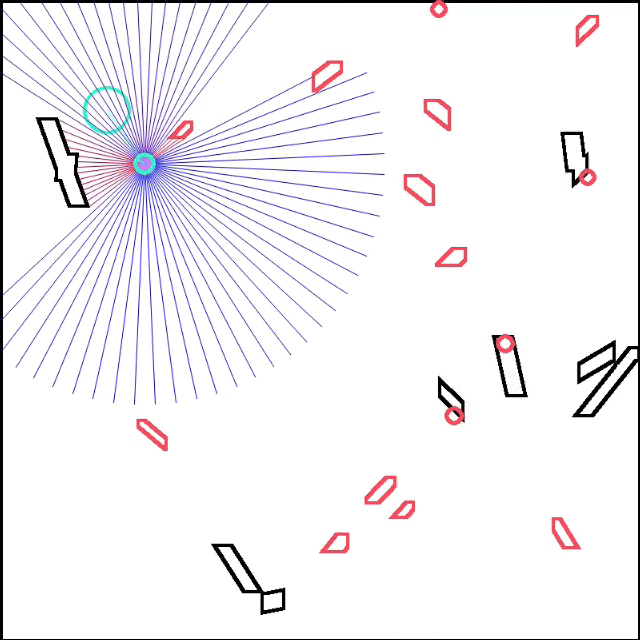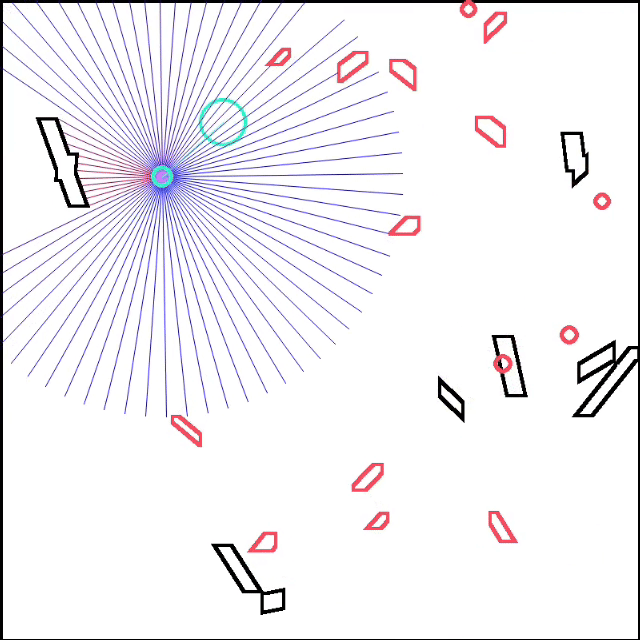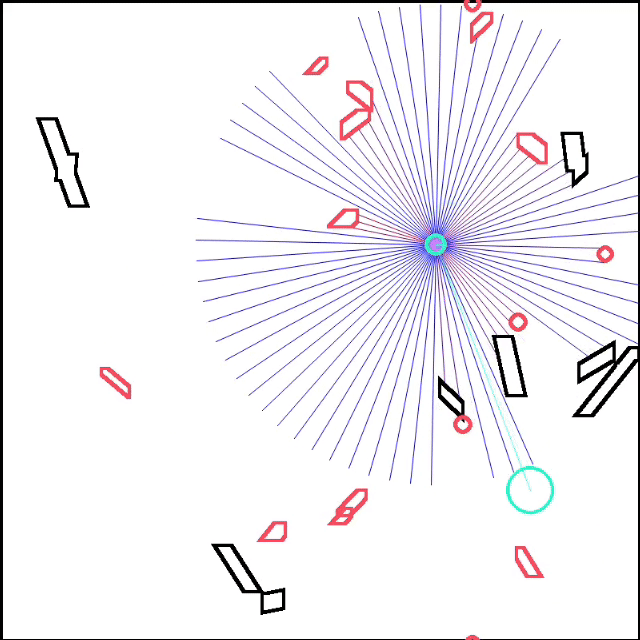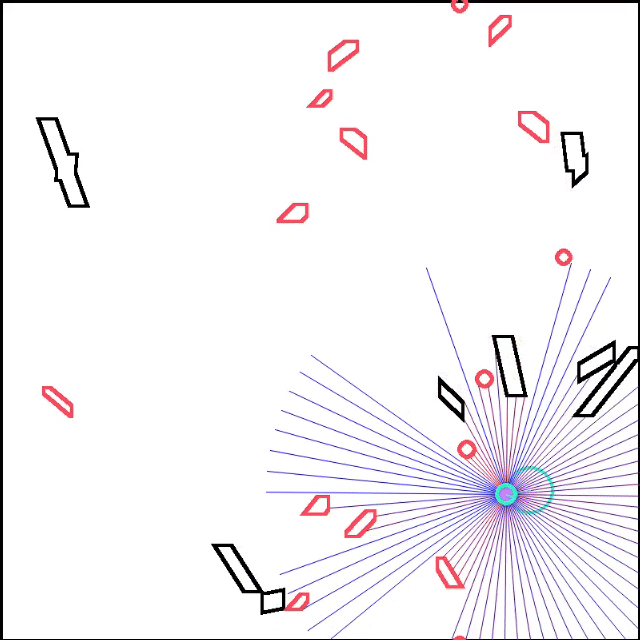
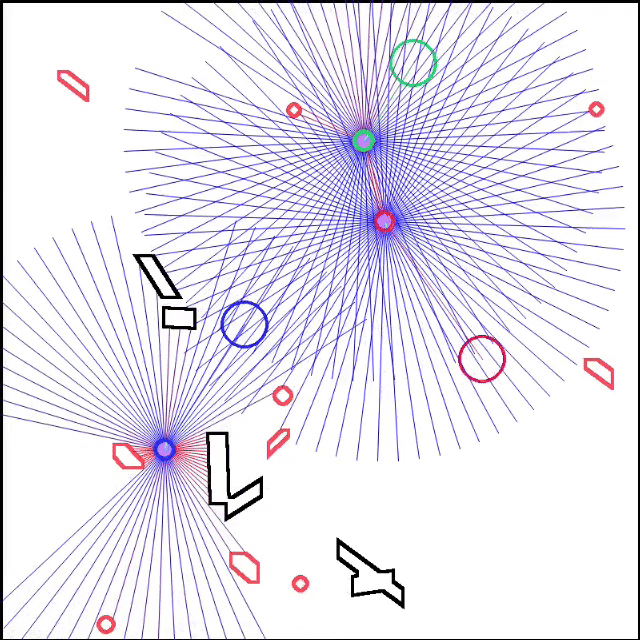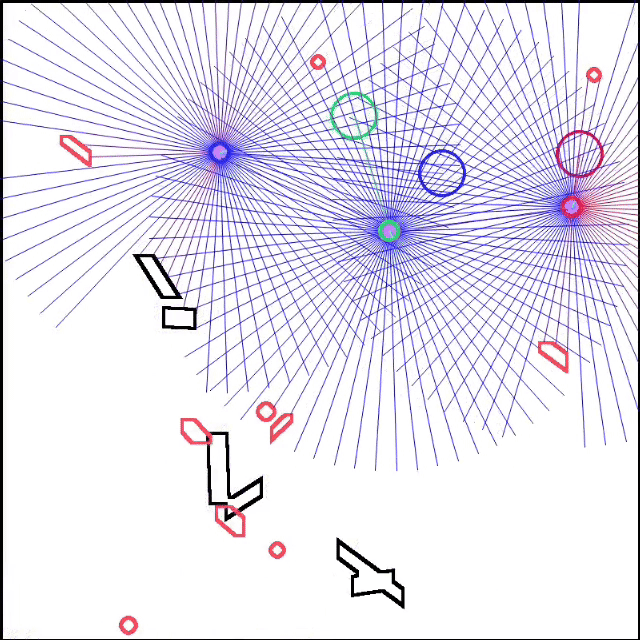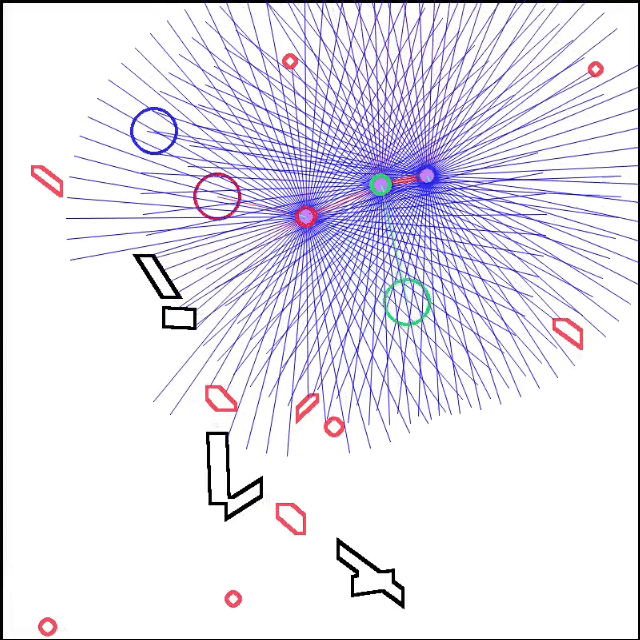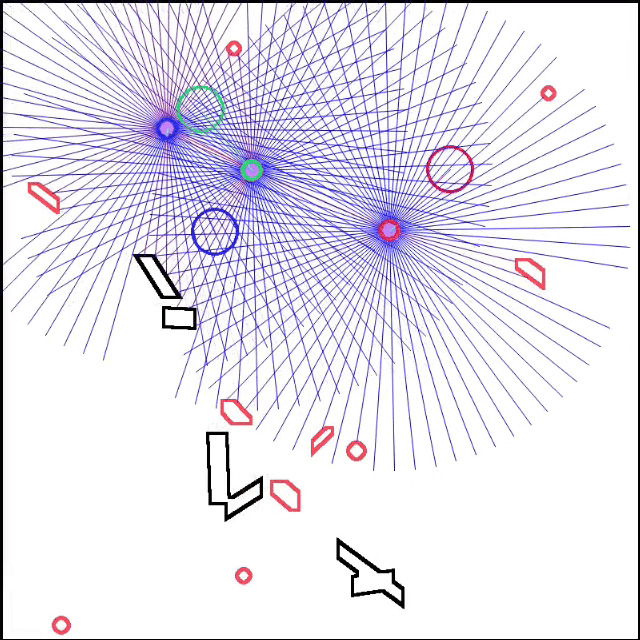
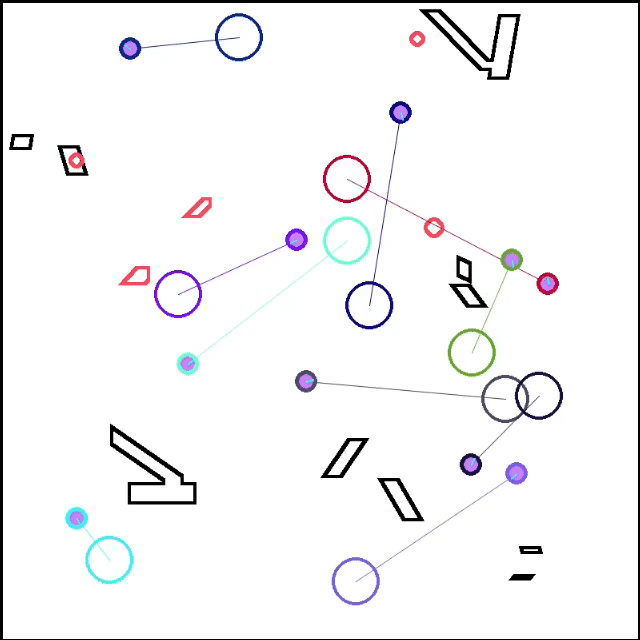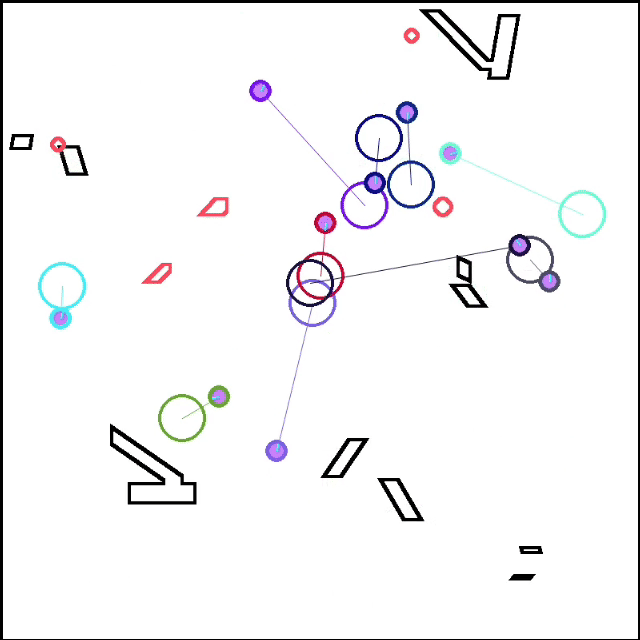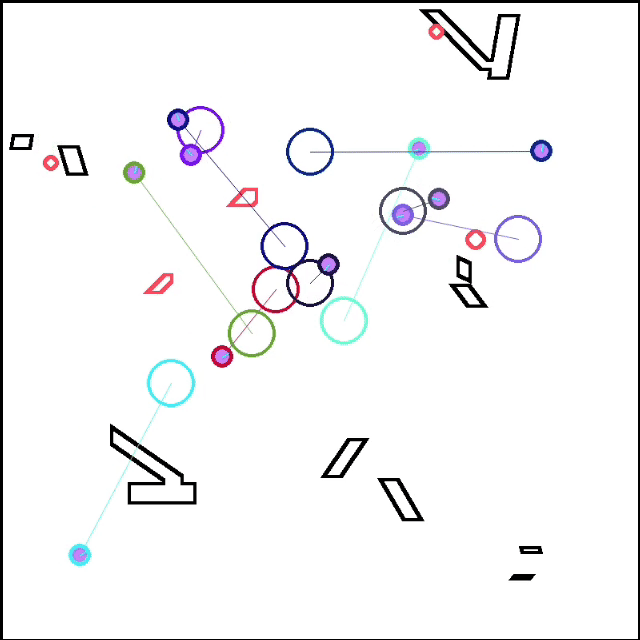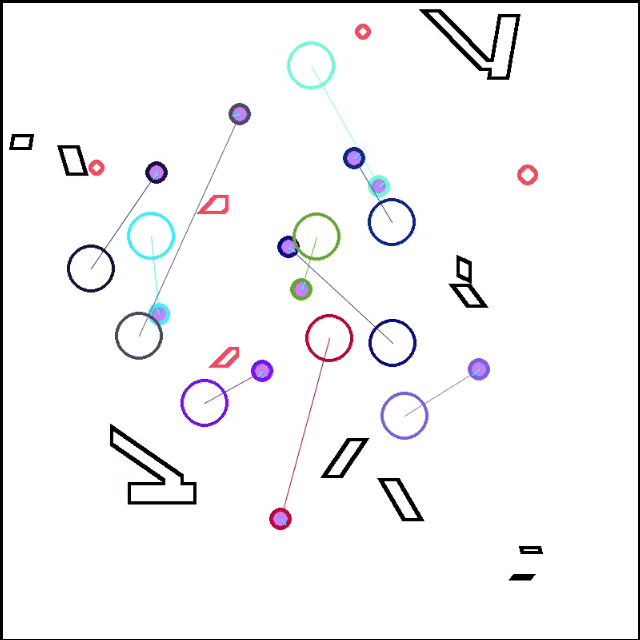
- Sparrow (Light Weight Simulator for Mobile Robot; DRL friendly):
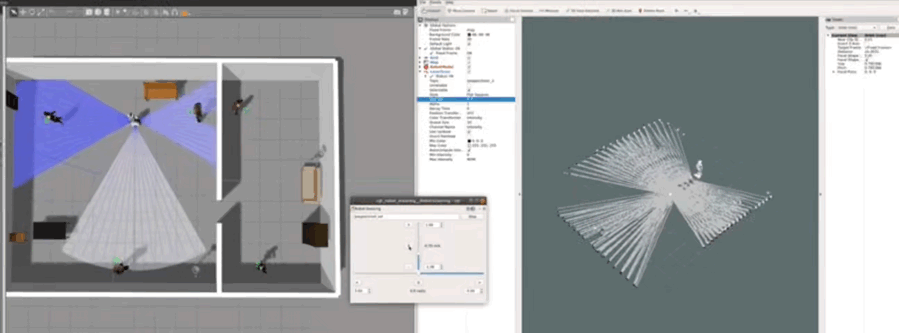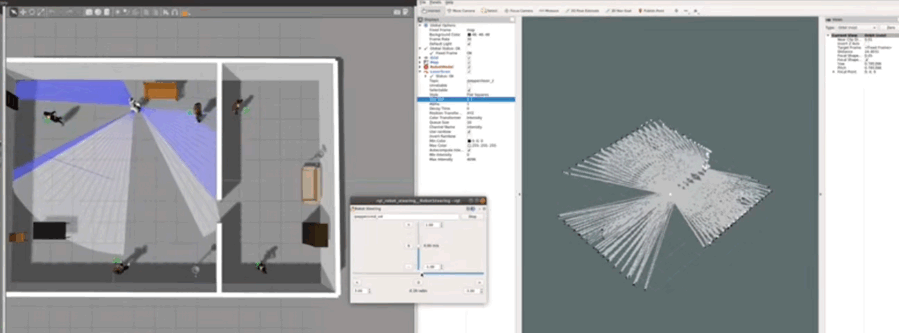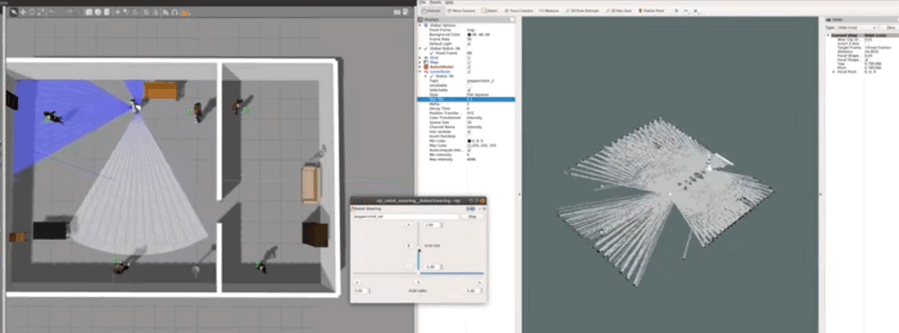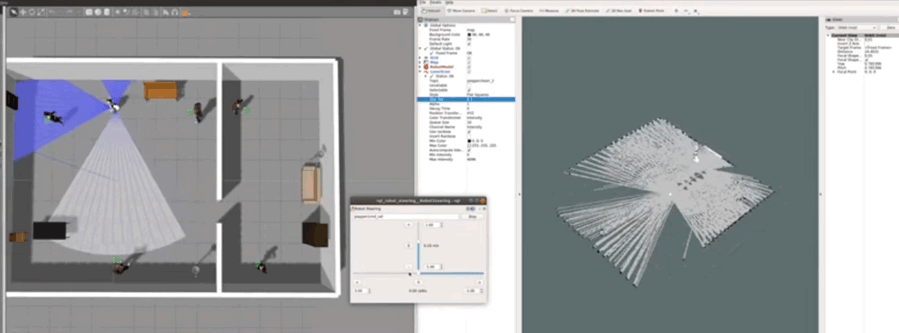
- ROS (Popular & Comprehensive physical simulator for robots; Heavy and Slow):
- Webots (Popular physical simulator for robots; Faster than ROS; Less realistic):
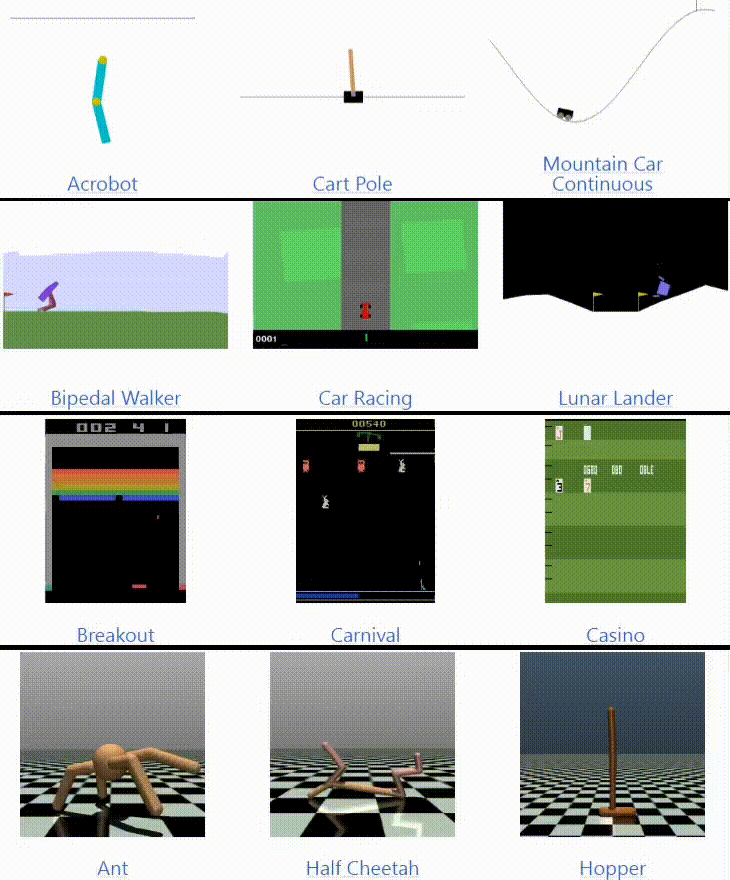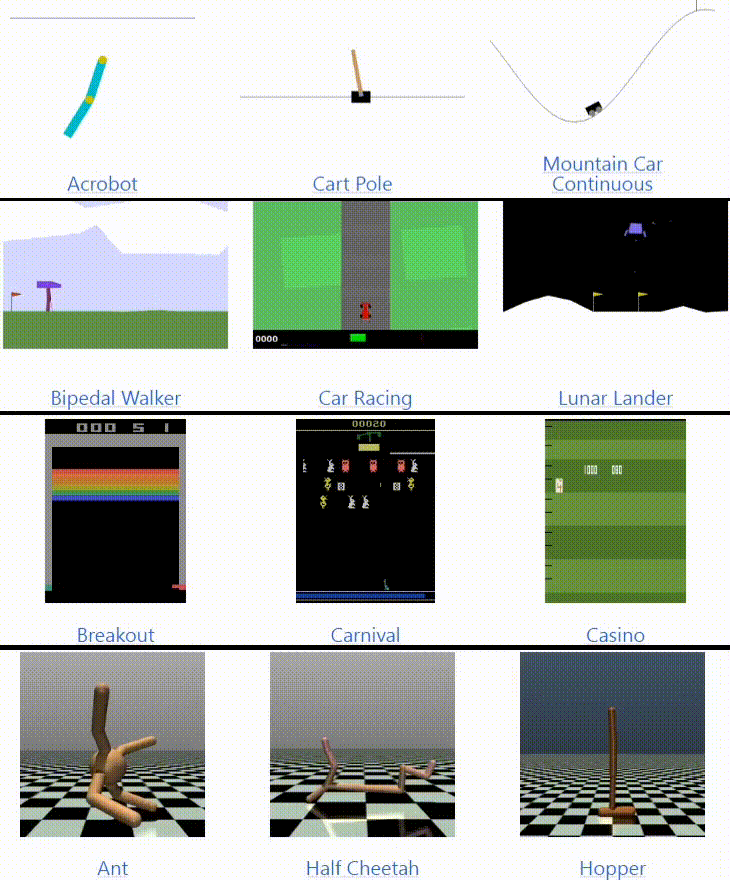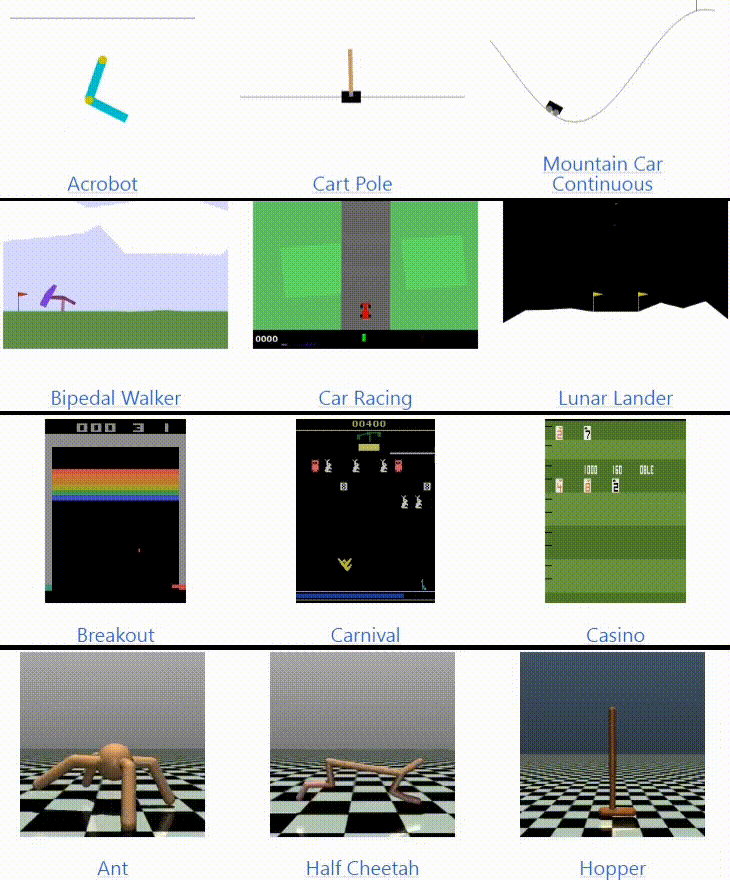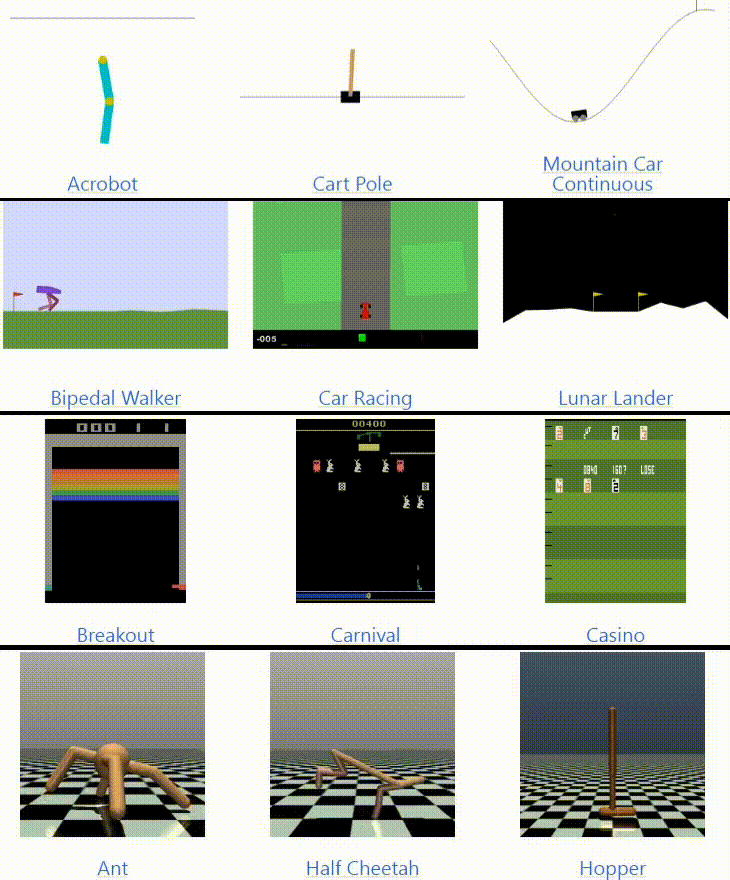
- Envpool (Fast Vectorized Env)
- Other Popular Envs
4.2 Books:
- 《Reinforcement learning: An introduction》--Richard S. Sutton
- 《深度学习入门:基于Python的理论与实现》--斋藤康毅
4.3 Online Courses:
- RL Courses(bilibili)--李宏毅(Hongyi Li)
- RL Courses(Youtube)--李宏毅(Hongyi Li)
- UCL Course on RL--David Silver
- 动手强化学习--上海交通大学
- DRL Courses--Shusen Wang
4.4 Blogs:
- OpenAI Spinning Up
- Policy Gradient Theorem --Cangxi
- Policy Gradient Algorithms --Lilian
- Theorem of PPO
- The 37 Implementation Details of Proximal Policy Optimization
- Prioritized Experience Replay
- Soft Actor Critic
- A (Long) Peek into Reinforcement Learning --Lilian
- Introduction to TD3
5. Important Papers
NoisyNet DQN: Fortunato M, Azar M G, Piot B, et al. Noisy networks for exploration[J]. arXiv preprint arXiv:1706.10295, 2017.
ColorDynamic: Generalizable, Scalable, Real-time, End-to-end Local Planner for Unstructured and Dynamic Environments
6. Citation
@misc{DRL-Pytorch,
  author = {Jinghao Xin},
  title = {DRL-Pytorch},
  year = {2022},
  publisher = {GitHub},
  journal = {GitHub Repository},
  howpublished = {\url{https://github.com/XinJingHao/DRL-Pytorch}},
}
7. Training Curves of my Code:
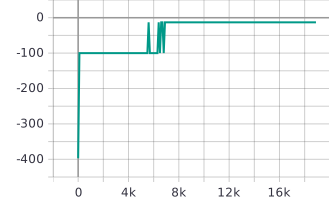
Q-learning:
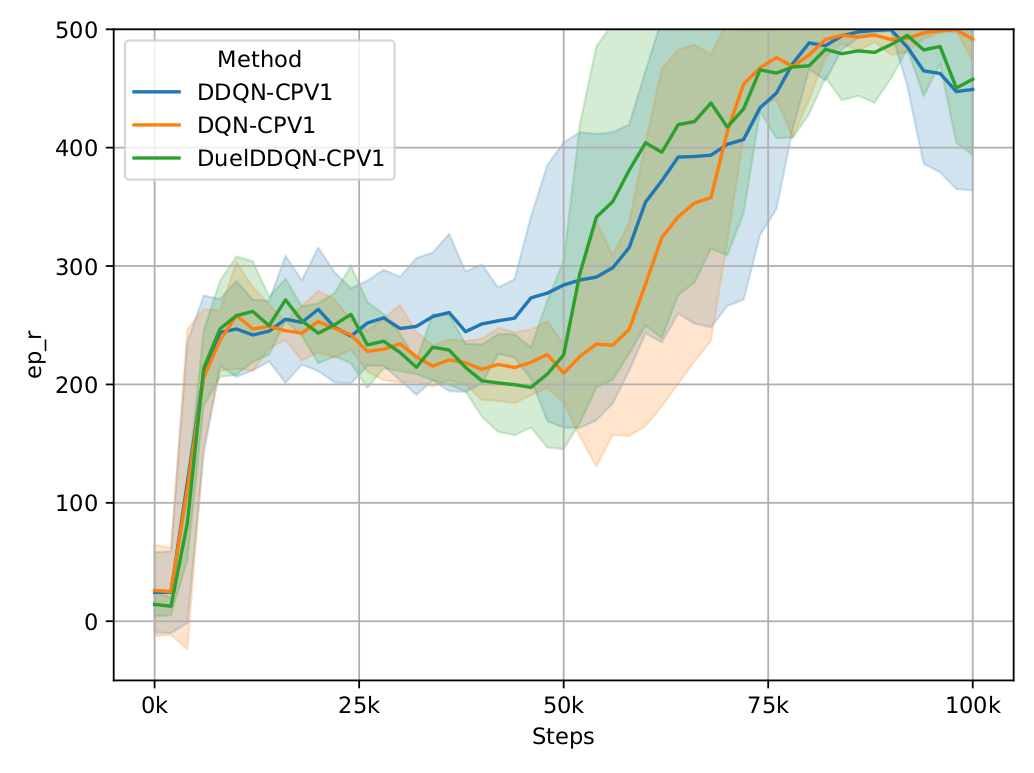
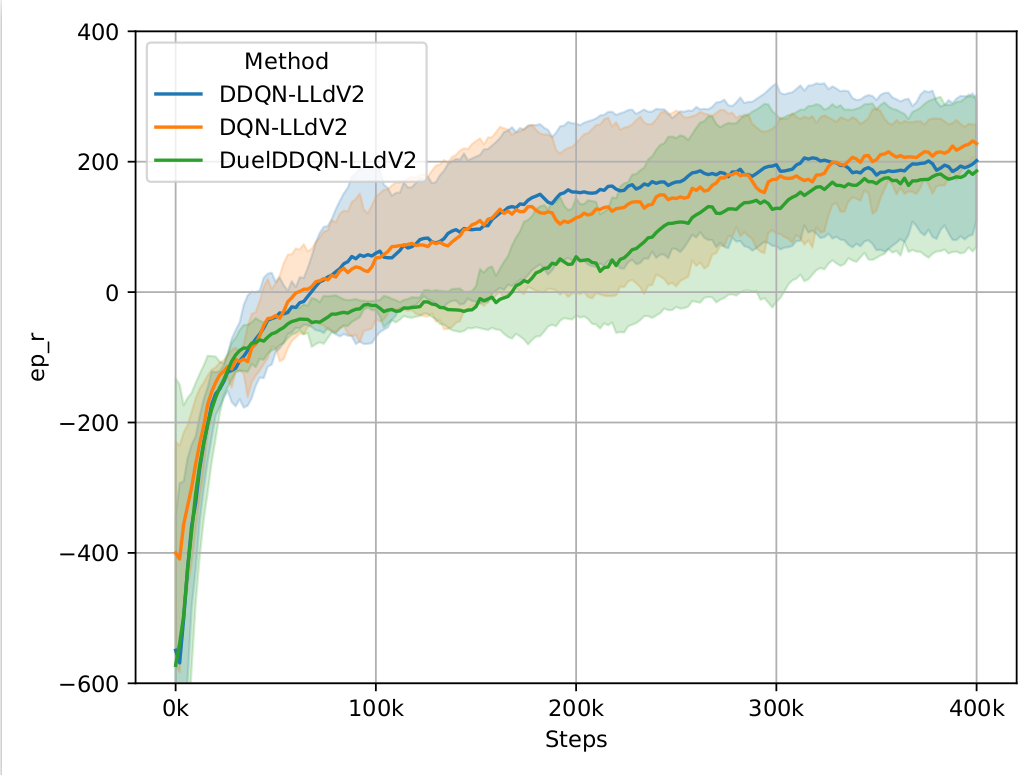
Duel Double DQN:
| CartPole | LunarLander |
|---|---|
 |
 |
Noisy Duel DDQN on Atari Game:
| Pong | Enduro |
|---|---|
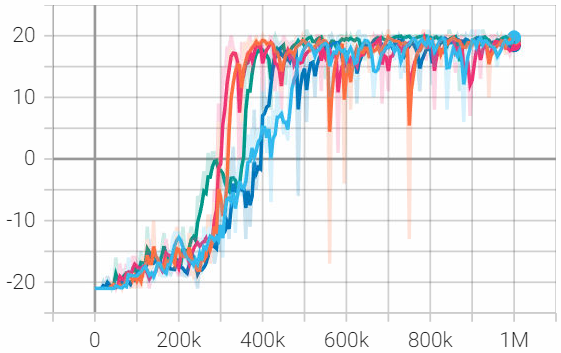 |
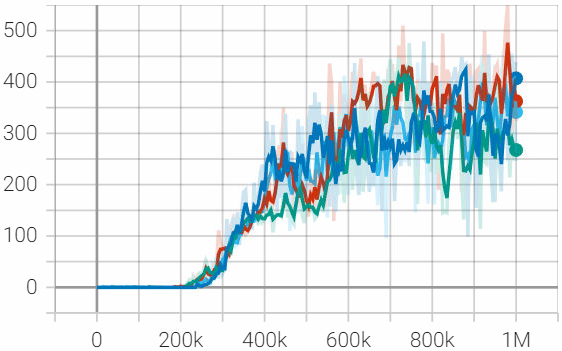 |
Prioritized DQN/DDQN:
| CartPole | LunarLander |
|---|---|
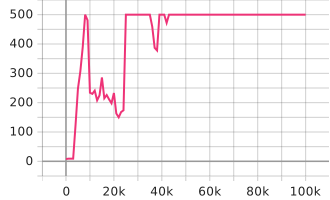 |
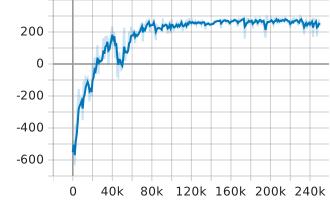 |
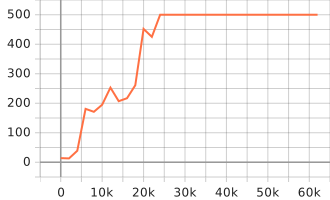
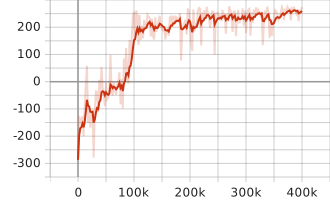
Categorical DQN:
| CartPole | LunarLander |
|---|---|
 |
 |
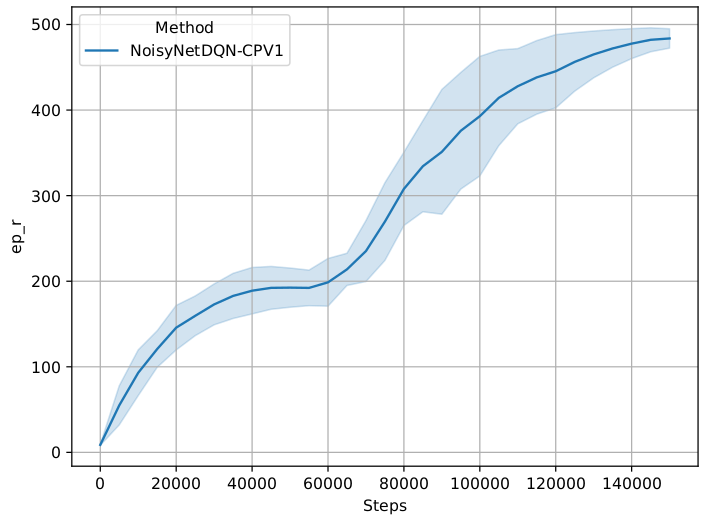
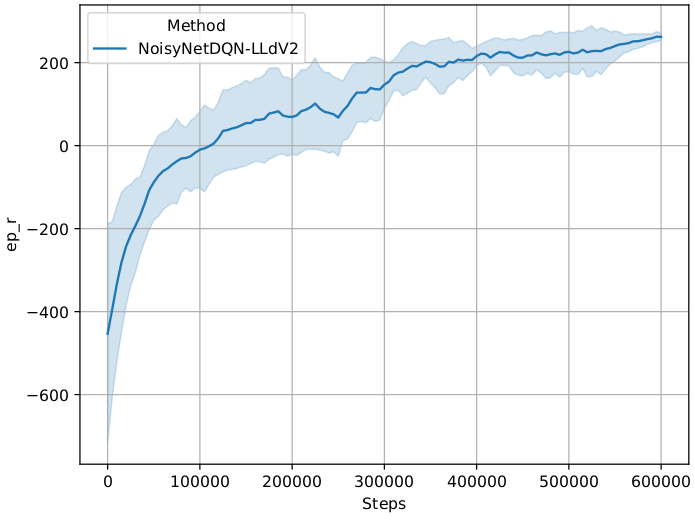
NoisyNet DQN:
| CartPole | LunarLander |
|---|---|
 |
 |
PPO Discrete:
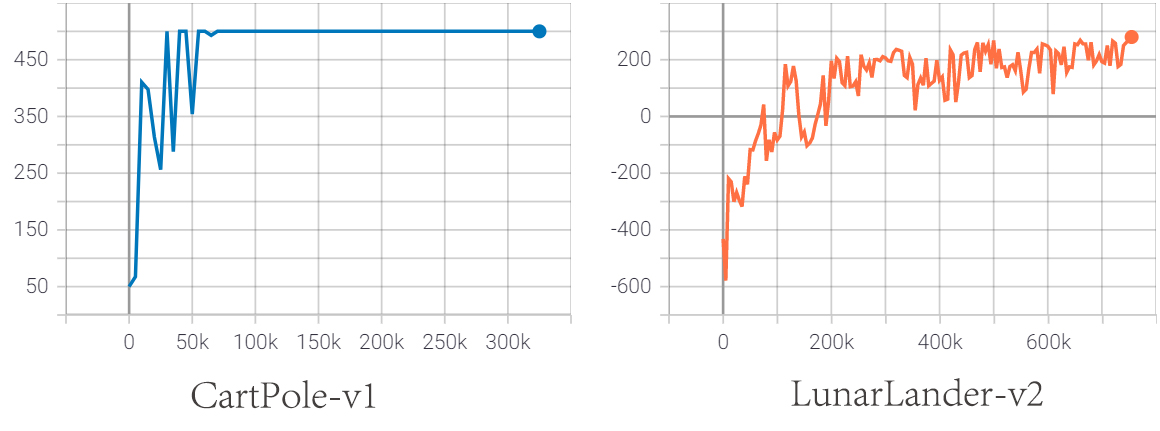
PPO Continuous:
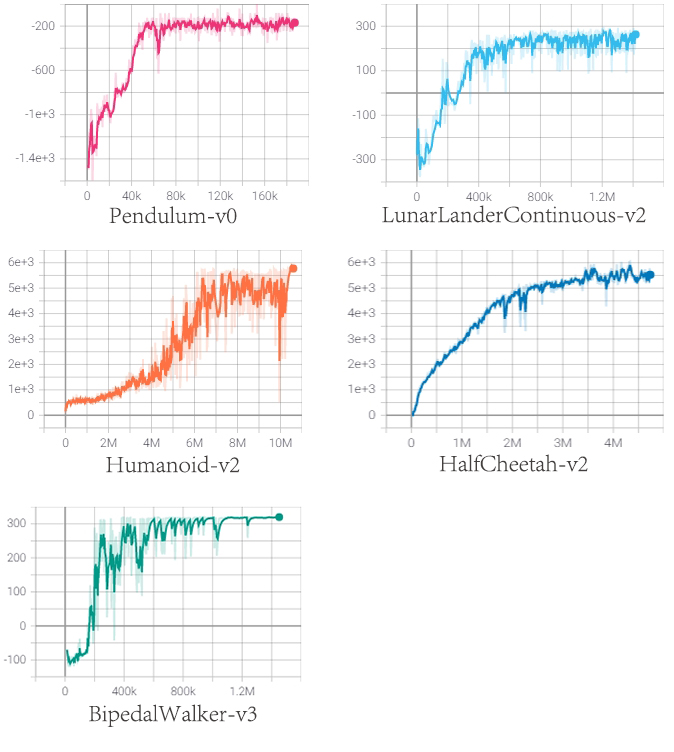
DDPG:
| Pendulum | LunarLanderContinuous |
|---|---|
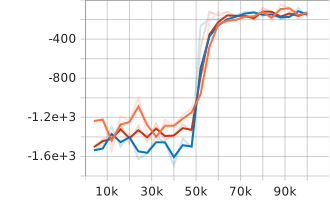 |
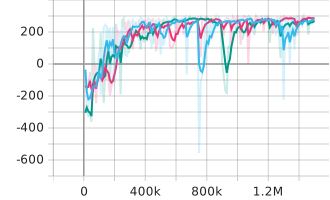 |
TD3:
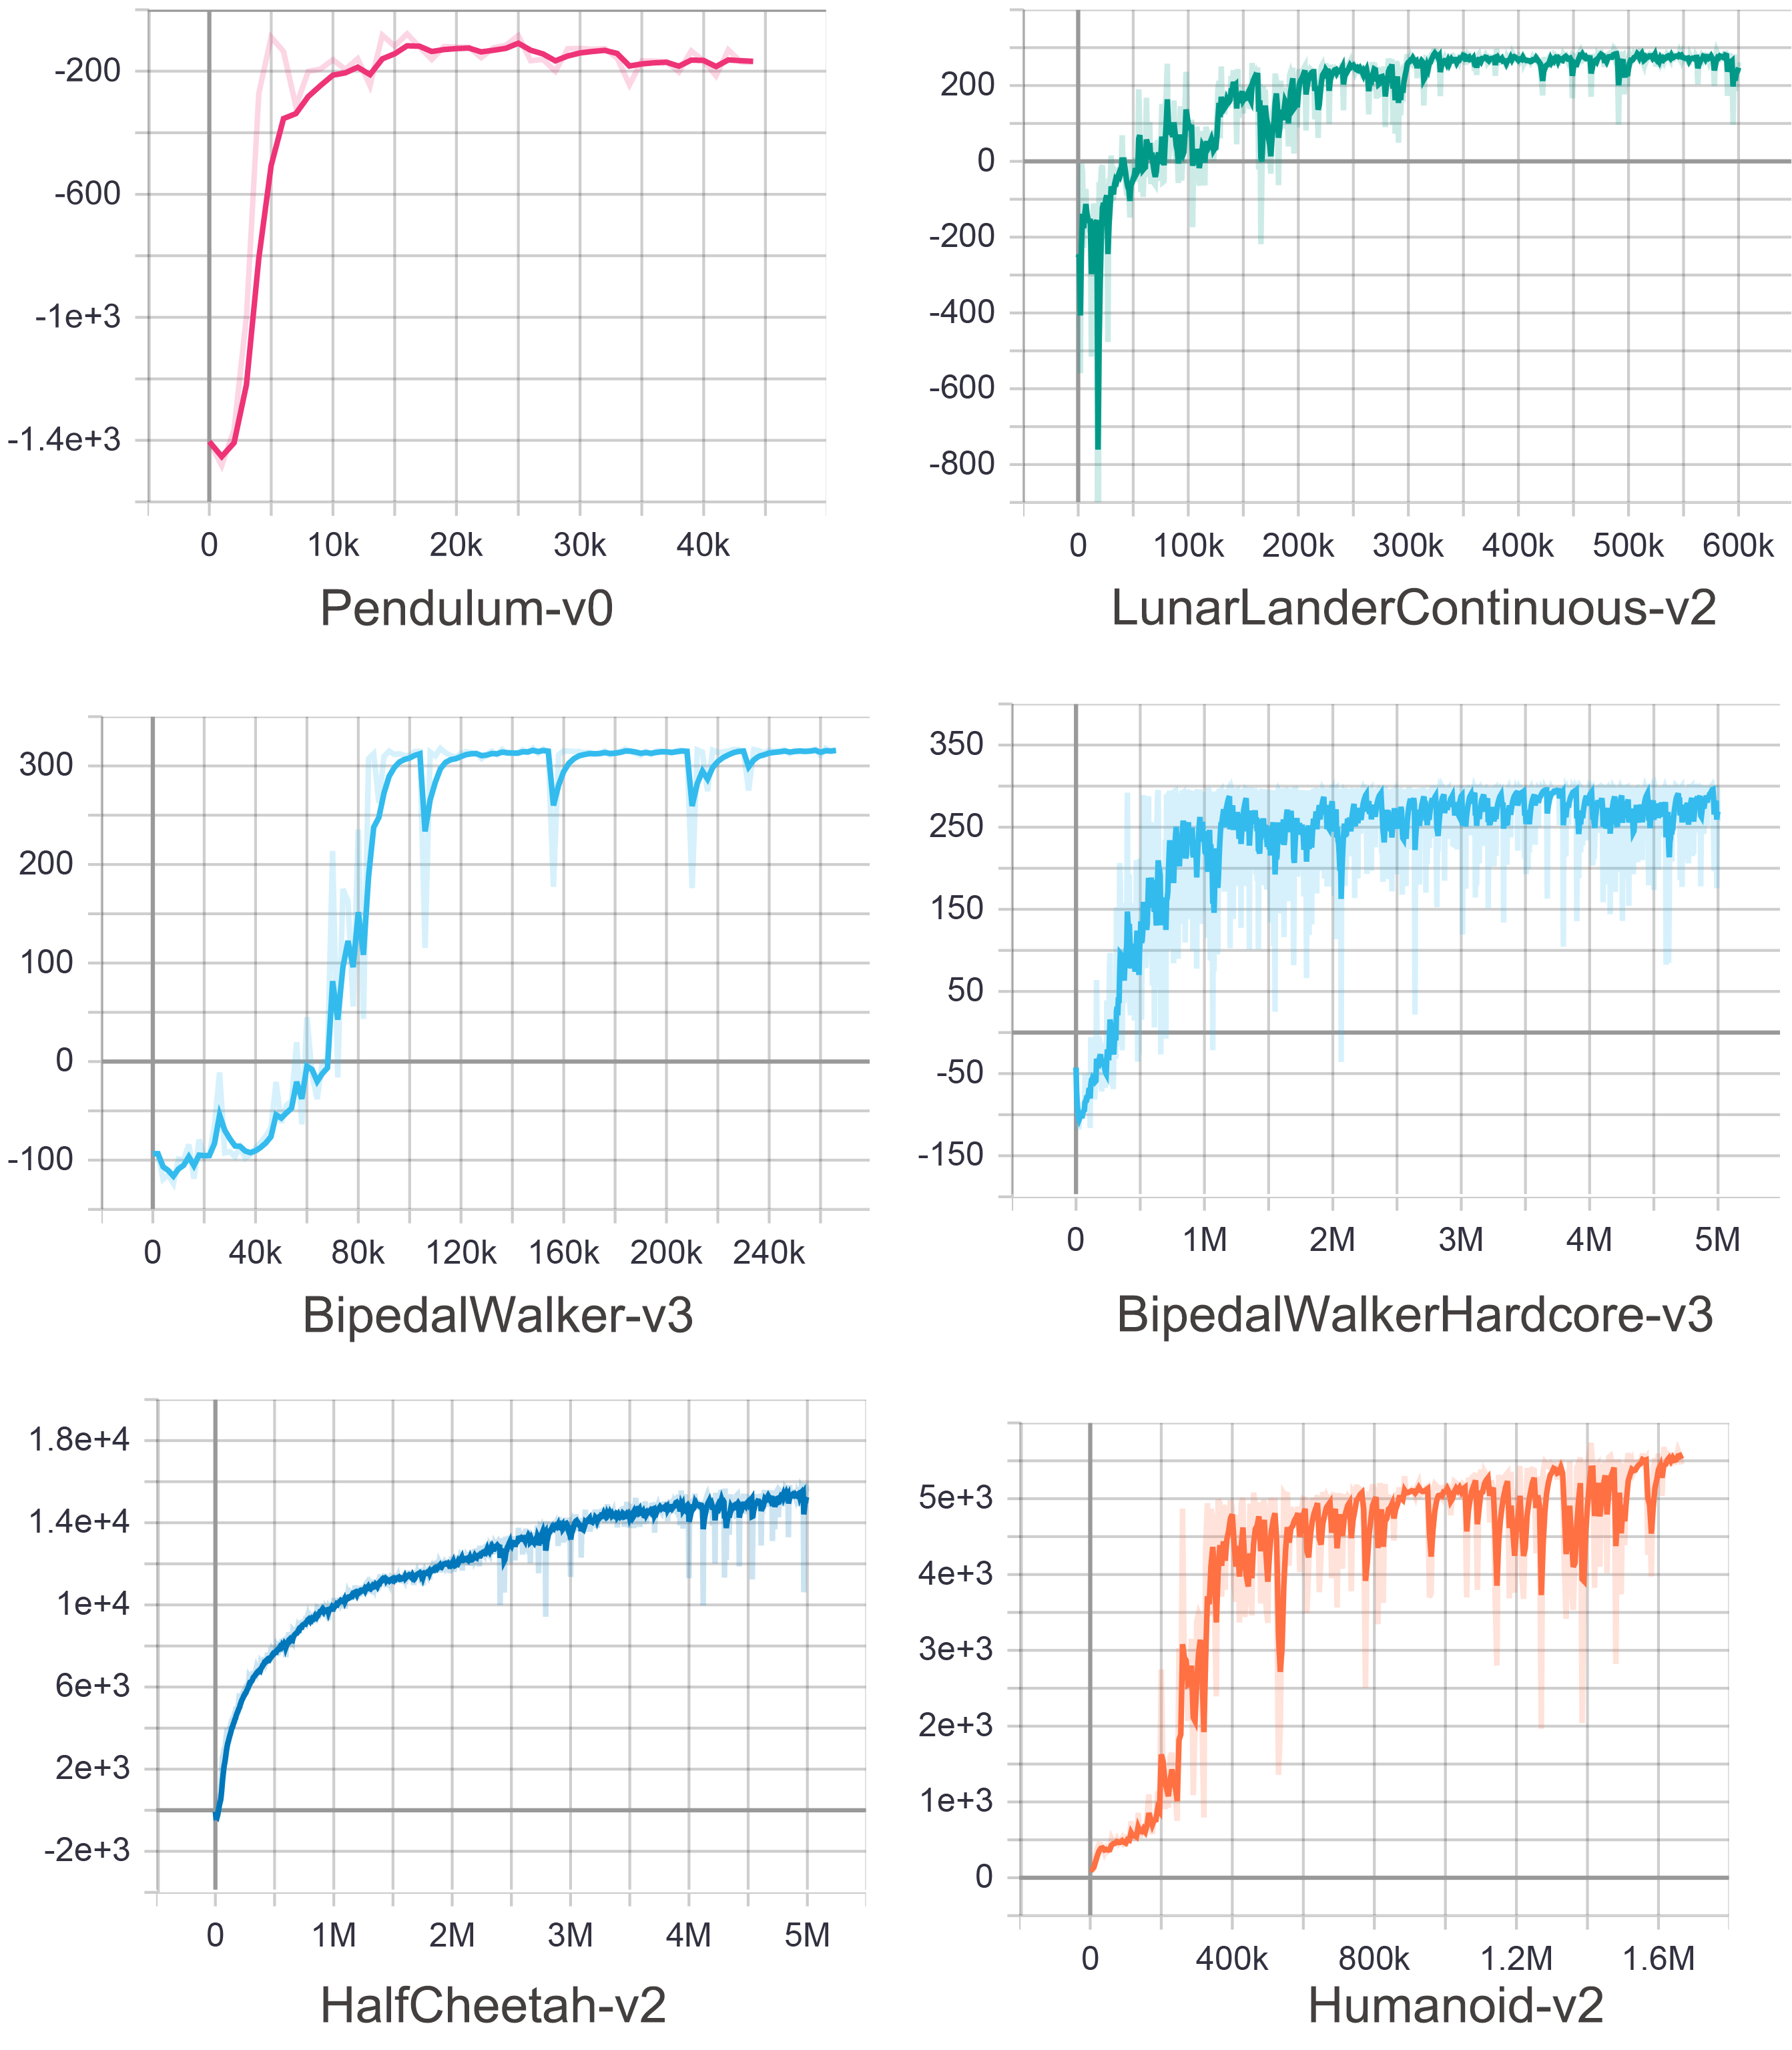
SAC Continuous:
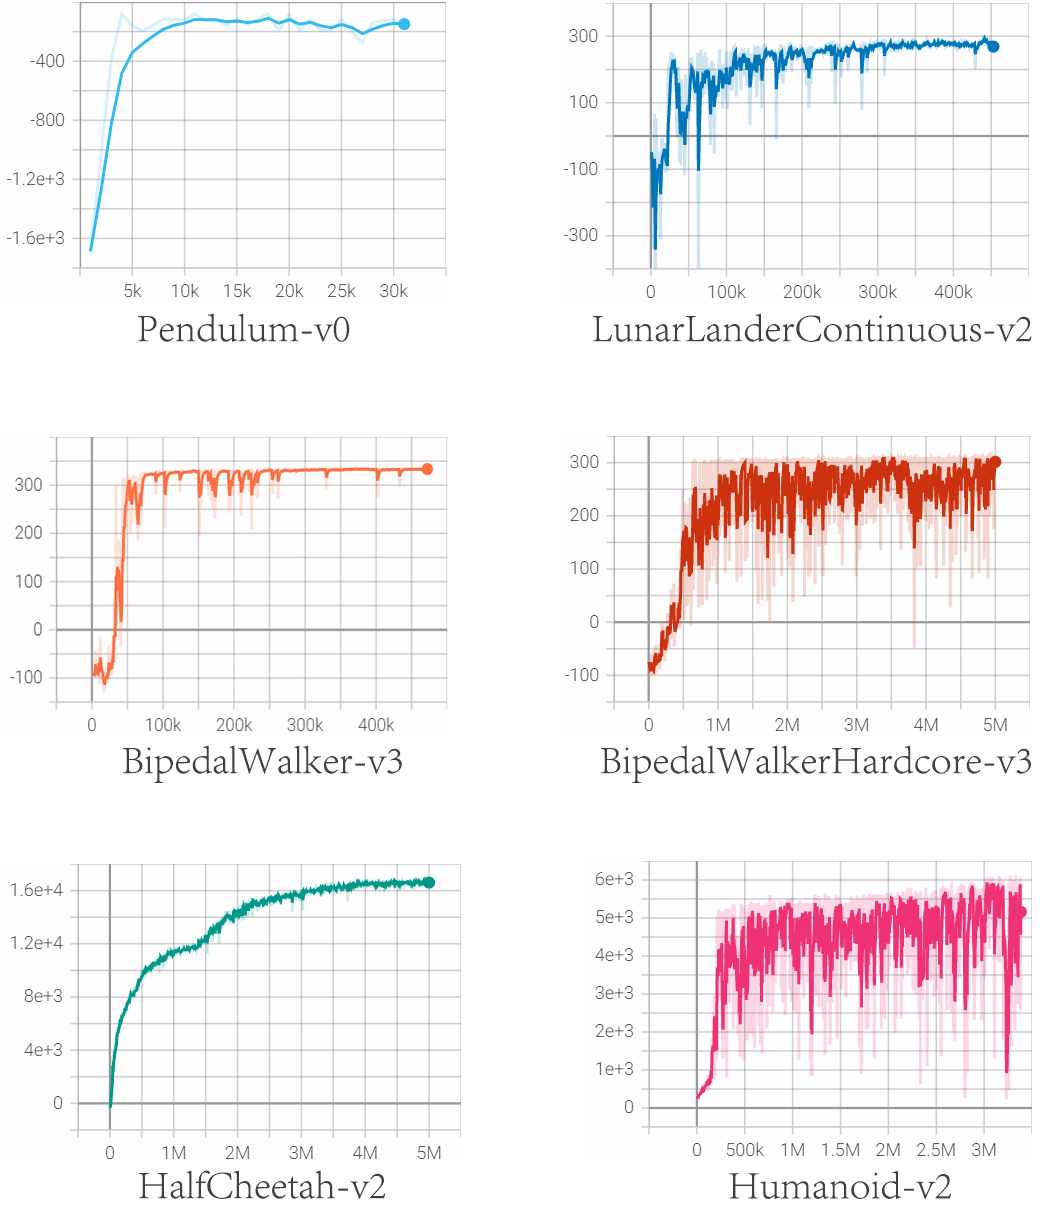
SAC Discrete:
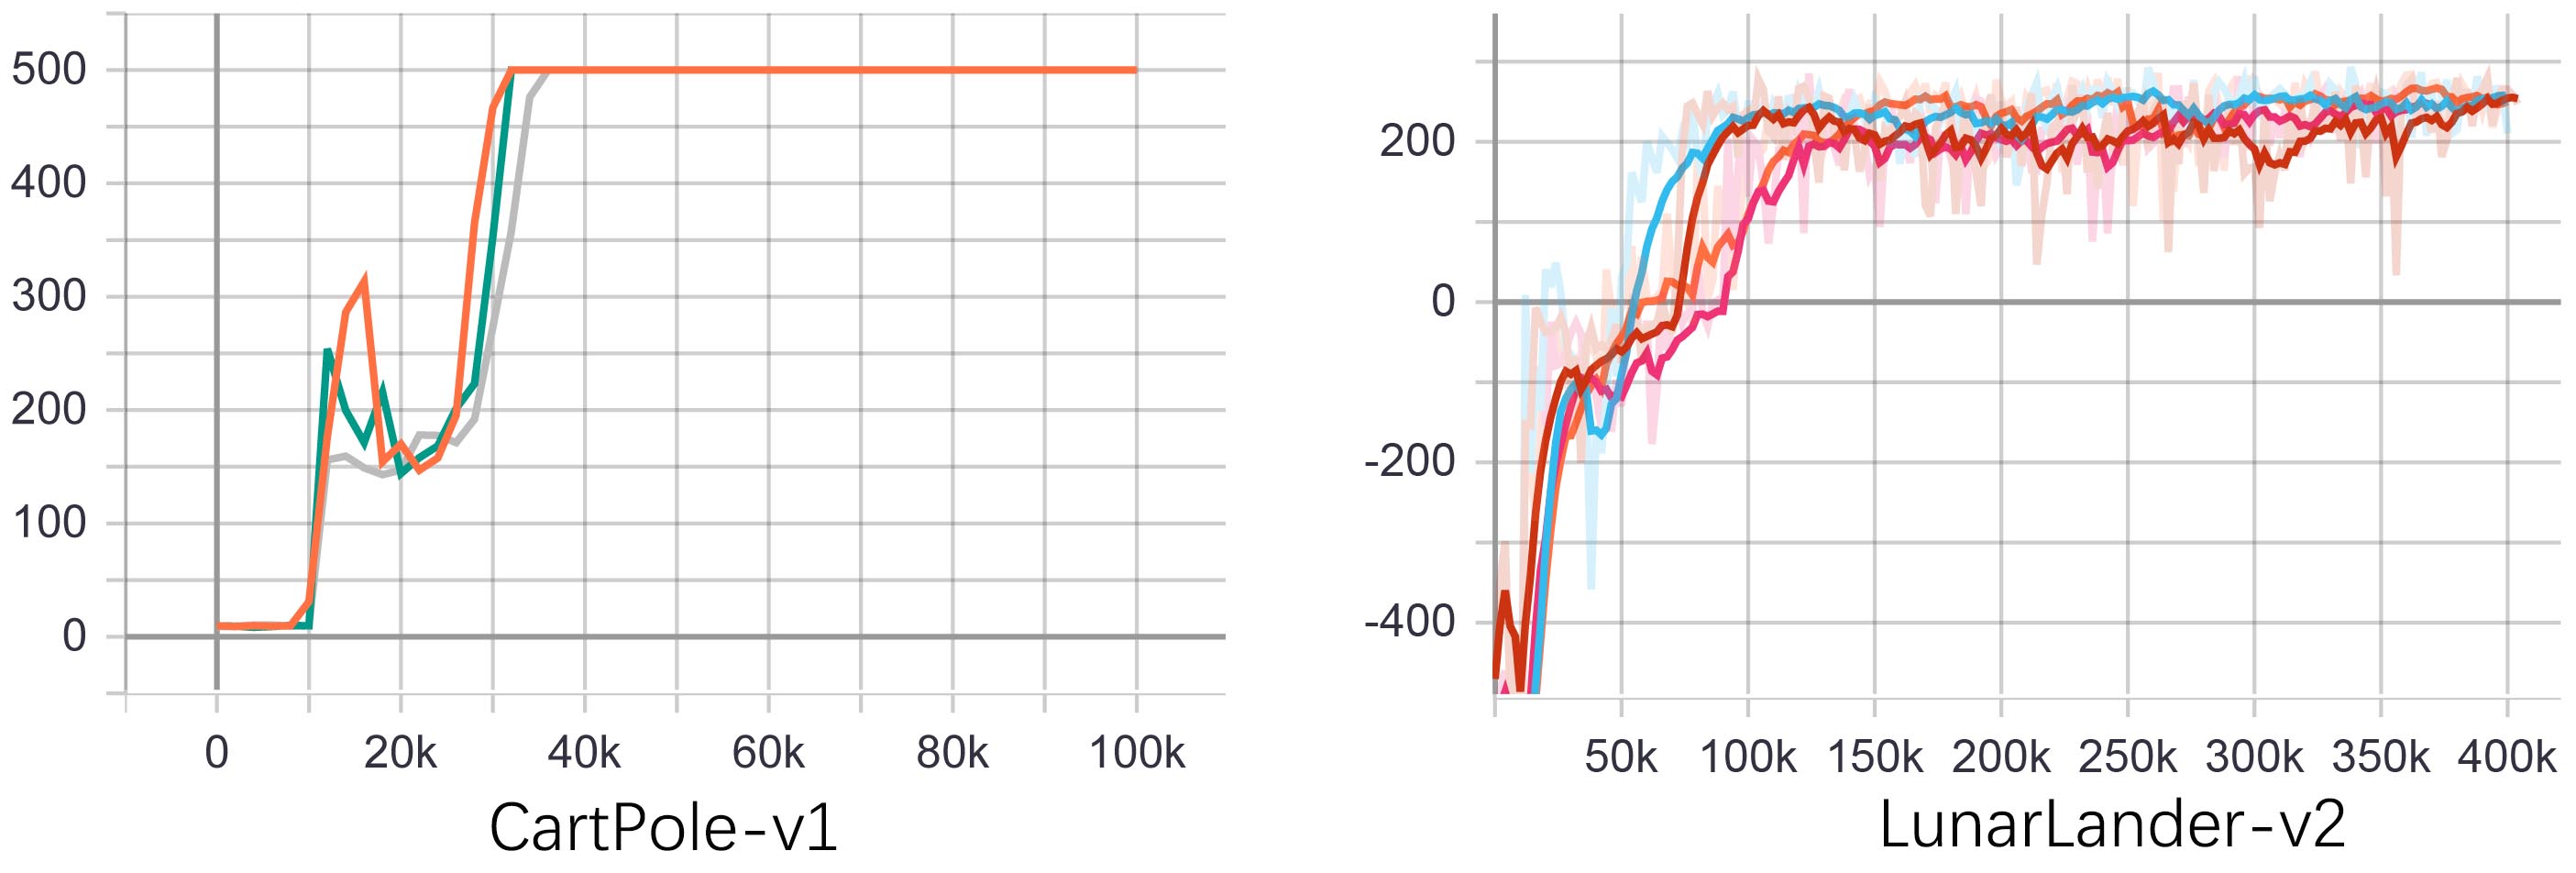
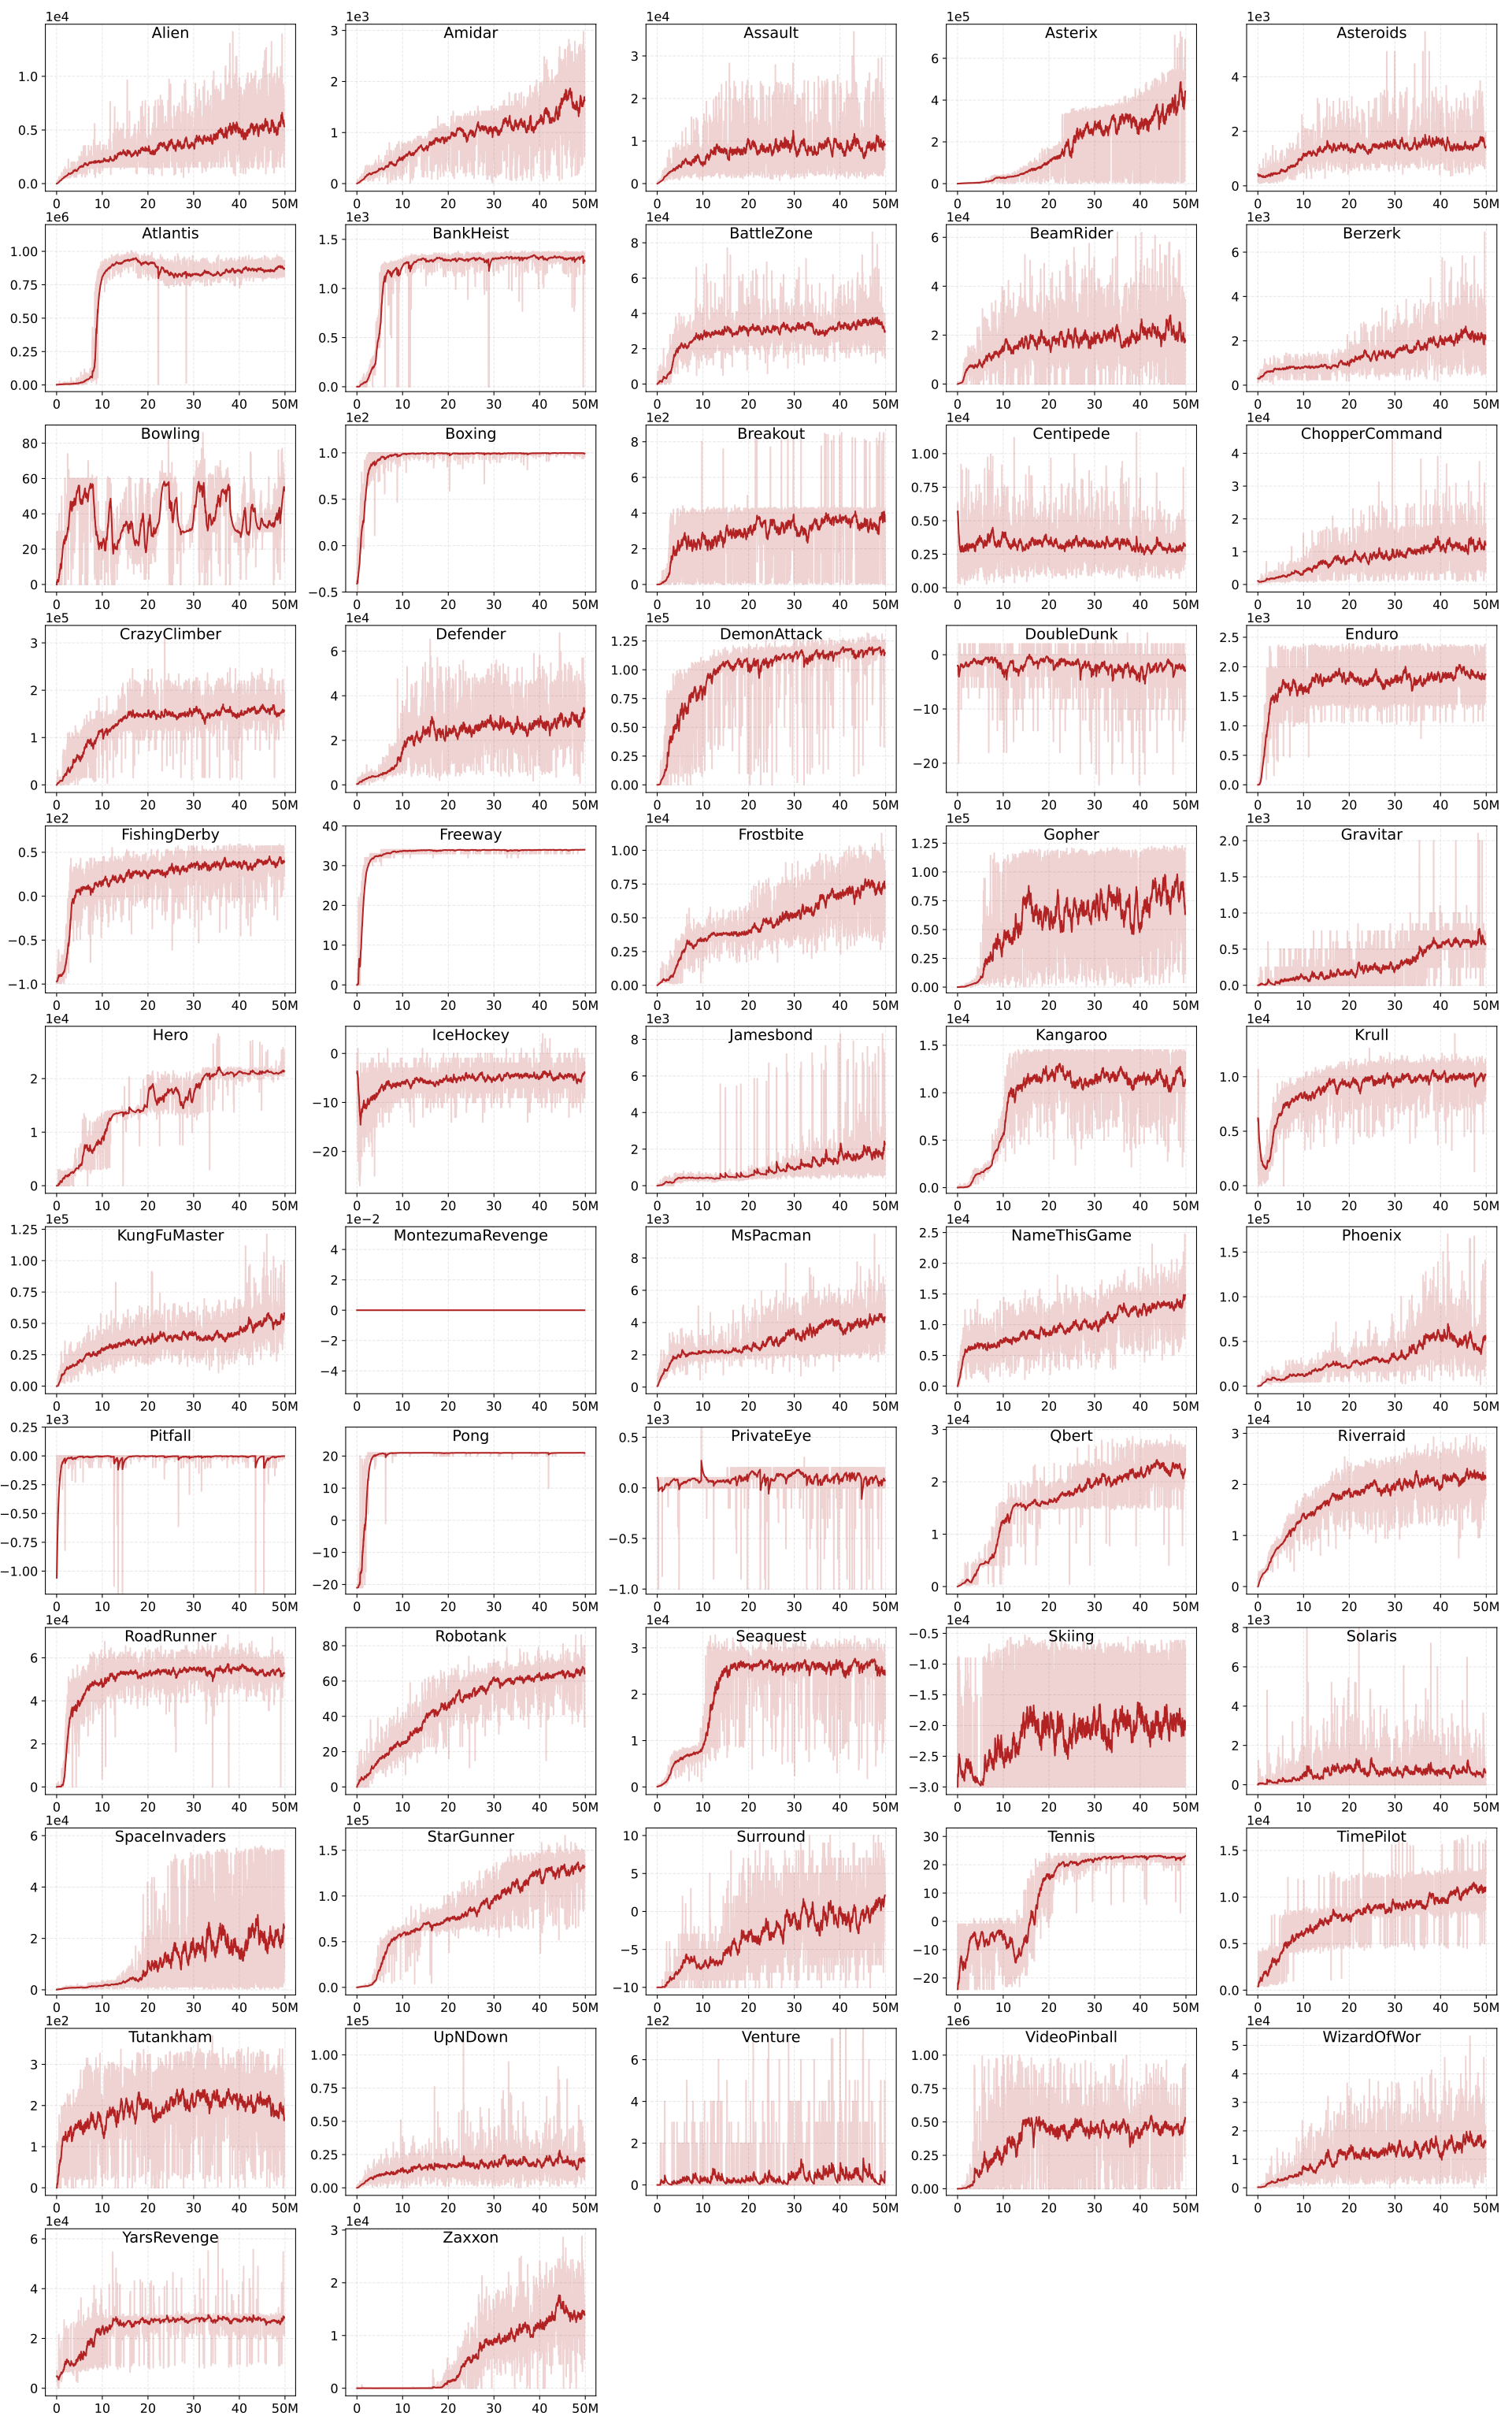
Actor-Sharer-Learner (ASL):
관련 프로젝트 살펴보기
tensorflow/tensorflow
모두를 위한 오픈소스 머신러닝 프레임워크
201,427 스타huggingface/transformers
🤗 Transformers: 텍스트, 비전, 오디오, 멀티모달 분야의 최첨단 머신러닝 모델을 위한 모델 정의 프레임워크로, 추론과 학습을 모두 지원합니다.
168,711 스타AUTOMATIC1111/stable-diffusion-webui
Stable Diffusion 웹 UI
165,274 스타Comfy-Org/ComfyUI
그래프와 노드로 구성된 인터페이스를 갖춘, 가장 강력하고 모듈성이 뛰어난 확산 모델 GUI, API, 백엔드입니다. 세계에서 가장 빠른 로컬 추론 엔진입니다.
146,024 스타