
WenjieDu/TSDB
WenjieDu/TSDB has 242 GitHub stars and 22 forks. GitHot measured 0 stars in 24 hours and 0 in 7 days. Last checked 2026-11-15 13:59 UTC. Last push 2026-10-26.
측정된 스타 증가
- in 24h
- 0
- in 7 days
- 0
- in 15 days
- 기록 수집 중
- in 1 month
- 기록 수집 중
서로 겹치는 기간의 순증가량이며 일별 합계가 아닙니다. 측정값이 없으면 비워 둡니다. 스타는 관심도를 나타내며 품질을 보장하지 않습니다.
소개
a Python toolbox loads 173 public time series datasets for machine/deep learning with a single line of code. Datasets from multiple domains including healthcare, financial, power, traffic, weather, and etc.
머신러닝README.md
Original
Welcome to TSDB
load 173 public time-series datasets with a single line of code ;-)






 TSDB is a part of
PyPOTS

TSDB is created to help researchers and engineers get rid of data collecting and downloading, and focus back on data processing details. TSDB provides all-in-one-stop convenience for downloading and loading open-source time-series datasets (available datasets listed below).
❗️Please note that due to people have very different requirements for data processing, data-loading functions in TSDB only contain the most general steps (e.g. removing invalid samples) and won't process the data (not even normalize it). So, no worries, TSDB won't affect your data preprocessing. If you only want the raw datasets, TSDB can help you download and save raw datasets as well (take a look at Usage Examples below).
🤝 If you need TSDB to integrate an open-source dataset or want to add it into TSDB yourself, please feel free to request for it by creating an issue or make a PR to merge your code.
🤗 Please star this repo to help others notice TSDB if you think it is a useful toolkit. Please properly cite TSDB and PyPOTS in your publications if it helps with your research. This really means a lot to our open-source research. Thank you!
❖ Usage Examples
[!IMPORTANT] TSDB is available on both
and
❗️
Install via pip:
pip install tsdb
or install from source code:
pip install
https://github.com/WenjieDu/TSDB/archive/main.zipor install via conda:
conda install tsdb -c conda-forge
import tsdb

# list all available datasets in TSDB
tsdb.list()
# ['physionet_2012',
#  'physionet_2019',
#  'electricity_load_diagrams',
#  'beijing_multisite_air_quality',
#  'italy_air_quality',
#  'vessel_ais',
#  'electricity_transformer_temperature',
#  'pems_traffic',
#  'solar_alabama',
#  'ucr_uea_ACSF1',
#  'ucr_uea_Adiac',
#  ...

# select the dataset you need and load it, TSDB will download, extract, and process it automatically
data = tsdb.load('physionet_2012')
# if you need the raw data, use download_and_extract()
tsdb.download_and_extract('physionet_2012', './save_it_here')
# datasets you once loaded are cached, and you can check them with list_cached_data()
tsdb.list_cache()
# you can delete only one specific dataset's pickled cache
tsdb.delete_cache(dataset_name='physionet_2012', only_pickle=True)
# you can delete only one specific dataset raw files and preserve others
tsdb.delete_cache(dataset_name='physionet_2012')
# or you can delete all cache with delete_cached_data() to free disk space
tsdb.delete_cache()

# The default cache directory is ~/.pypots/tsdb under the user's home directory.
# To avoid taking up too much space if downloading many datasets ,
# TSDB cache directory can be migrated to an external disk
tsdb.migrate_cache("/mnt/external_disk/TSDB_cache")
That's all. Simple and efficient. Enjoy it! 😃
❖ List of Available Datasets
| Name | Main Tasks |
|---|---|
| PhysioNet Challenge 2012 | Forecasting, Imputation, Classification |
| PhysioNet Challenge 2019 | Forecasting, Imputation, Classification |
| Beijing Multi-Site Air-Quality | Forecasting, Imputation |
| Italy Air Quality | Forecasting, Imputation |
| Electricity Load Diagrams | Forecasting, Imputation |
| Electricity Transformer Temperature (ETT) | Forecasting, Imputation |
| Vessel AIS | Forecasting, Imputation, Classification |
| PeMS Traffic | Forecasting, Imputation |
| Solar Alabama | Forecasting, Imputation |
| TSQA | LLM training |
| UCR & UEA Datasets (all 163 datasets) | Classification |
❖ Citing TSDB/PyPOTS
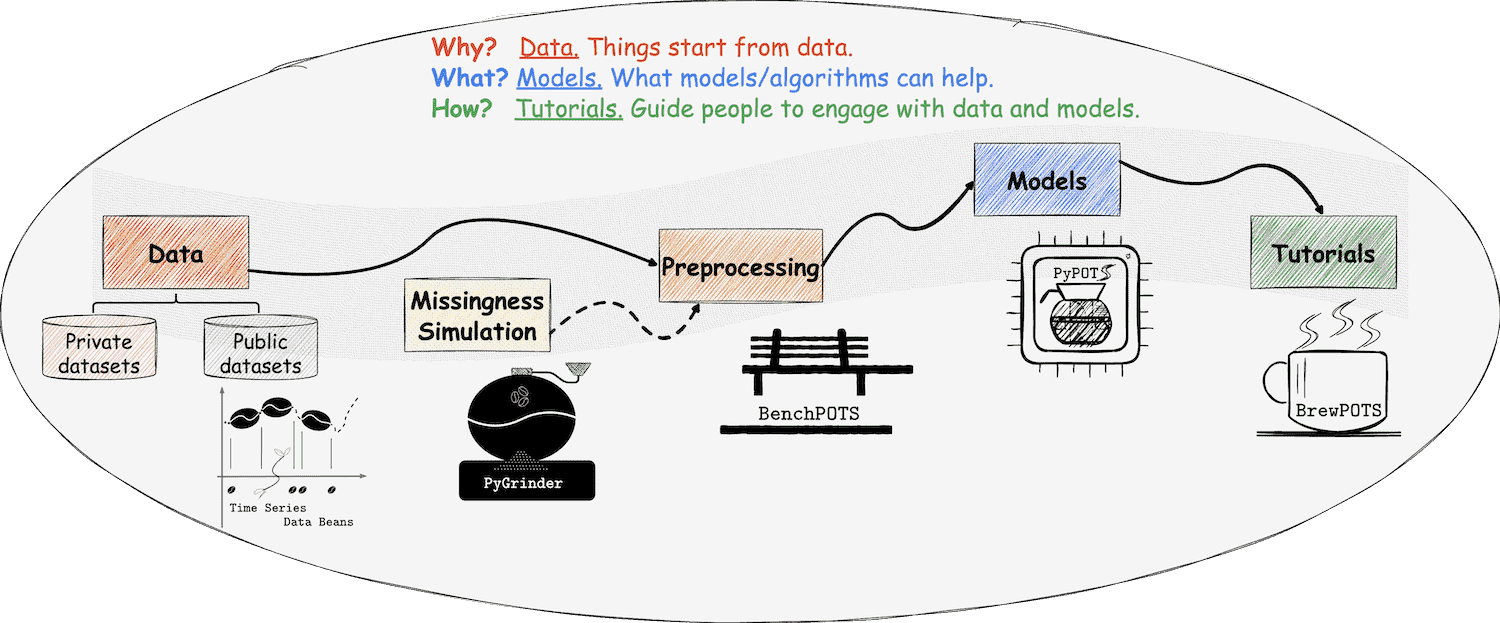
The paper introducing PyPOTS is available on arXiv, A short version of it is accepted by the 9th SIGKDD international workshop on Mining and Learning from Time Series (MiLeTS'23)). Additionally, PyPOTS has been included as a PyTorch Ecosystem project. We are pursuing to publish it in prestigious academic venues, e.g. JMLR (track for Machine Learning Open Source Software). If you use PyPOTS in your work, please cite it as below and 🌟star this repository to make others notice this library. 🤗
There are scientific research projects using PyPOTS and referencing in their papers. Here is an incomplete list of them.
@article{du2023pypots,
title = {{PyPOTS: A Python Toolkit for Data Mining on Partially-Observed Time Series}},
author = {Wenjie Du},
journal = {SIGKDD MiLeTS Workshop},
year = {2023},
}
@article{du2025pypots,
title = {{PyPOTS v1: A Python Toolkit for Machine Learning on Partially-Observed Time Series}},
author = {Wenjie Du, Yiyuan Yang, Linglong Qian, Jun Wang, and Qingsong Wen},
year = {2025},
}