
VainF/DeepLabV3Plus-Pytorch
VainF/DeepLabV3Plus-Pytorch has 2,709 GitHub stars and 522 forks. GitHot measured -1 stars in 24 hours and 0 in 7 days. Last checked 2026-11-13 20:24 UTC. Last push 2022-11-15.
측정된 스타 증가
- in 24h
- -1
- in 7 days
- 0
- in 15 days
- 기록 수집 중
- in 1 month
- 기록 수집 중
서로 겹치는 기간의 순증가량이며 일별 합계가 아닙니다. 측정값이 없으면 비워 둡니다. 스타는 관심도를 나타내며 품질을 보장하지 않습니다.
소개
Pretrained DeepLabv3 and DeepLabv3+ for Pascal VOC & Cityscapes
머신러닝README.md
OriginalDeepLabv3Plus-Pytorch
Pretrained DeepLabv3, DeepLabv3+ for Pascal VOC & Cityscapes.
Quick Start
1. Available Architectures
| DeepLabV3 | DeepLabV3+ |
|---|---|
| deeplabv3_resnet50 | deeplabv3plus_resnet50 |
| deeplabv3_resnet101 | deeplabv3plus_resnet101 |
| deeplabv3_mobilenet | deeplabv3plus_mobilenet |
| deeplabv3_hrnetv2_48 | deeplabv3plus_hrnetv2_48 |
| deeplabv3_hrnetv2_32 | deeplabv3plus_hrnetv2_32 |
| deeplabv3_xception | deeplabv3plus_xception |
please refer to network/modeling.py for all model entries.
Download pretrained models: Dropbox, Tencent Weiyun
Note: The HRNet backbone was contributed by @timothylimyl. A pre-trained backbone is available at google drive.
2. Load the pretrained model:
model = network.modeling.__dict__[MODEL_NAME](num_classes=NUM_CLASSES, output_stride=OUTPUT_SRTIDE)
model.load_state_dict( torch.load( PATH_TO_PTH )['model_state']  )
3. Visualize segmentation outputs:
outputs = model(images)
preds = outputs.max(1)[1].detach().cpu().numpy()
colorized_preds = val_dst.decode_target(preds).astype('uint8') # To RGB images, (N, H, W, 3), ranged 0~255, numpy array
# Do whatever you like here with the colorized segmentation maps
colorized_preds = Image.fromarray(colorized_preds[0]) # to PIL Image
4. Atrous Separable Convolution
Note: All pre-trained models in this repo were trained without atrous separable convolution.
Atrous Separable Convolution is supported in this repo. We provide a simple tool network.convert_to_separable_conv to convert nn.Conv2d to AtrousSeparableConvolution. Please run main.py with '--separable_conv' if it is required. See 'main.py' and 'network/_deeplab.py' for more details.
5. Prediction
Single image:
python predict.py --input datasets/data/cityscapes/leftImg8bit/train/bremen/bremen_000000_000019_leftImg8bit.png --dataset cityscapes --model deeplabv3plus_mobilenet --ckpt checkpoints/best_deeplabv3plus_mobilenet_cityscapes_os16.pth --save_val_results_to test_results
Image folder:
python predict.py --input datasets/data/cityscapes/leftImg8bit/train/bremen --dataset cityscapes --model deeplabv3plus_mobilenet --ckpt checkpoints/best_deeplabv3plus_mobilenet_cityscapes_os16.pth --save_val_results_to test_results
6. New backbones
Please refer to this commit (Xception) for more details about how to add new backbones.
7. New datasets
You can train deeplab models on your own datasets. Your torch.utils.data.Dataset should provide a decoding method that transforms your predictions to colorized images, just like the VOC Dataset:
class MyDataset(data.Dataset):
    ...
    @classmethod
    def decode_target(cls, mask):
        """decode semantic mask to RGB image"""
        return cls.cmap[mask]
Results
1. Performance on Pascal VOC2012 Aug (21 classes, 513 x 513)
Training: 513x513 random crop
validation: 513x513 center crop
| Model | Batch Size | FLOPs | train/val OS | mIoU | Dropbox | Tencent Weiyun |
|---|---|---|---|---|---|---|
| DeepLabV3-MobileNet | 16 | 6.0G | 16/16 | 0.701 | Download | Download |
| DeepLabV3-ResNet50 | 16 | 51.4G | 16/16 | 0.769 | Download | Download |
| DeepLabV3-ResNet101 | 16 | 72.1G | 16/16 | 0.773 | Download | Download |
| DeepLabV3Plus-MobileNet | 16 | 17.0G | 16/16 | 0.711 | Download | Download |
| DeepLabV3Plus-ResNet50 | 16 | 62.7G | 16/16 | 0.772 | Download | Download |
| DeepLabV3Plus-ResNet101 | 16 | 83.4G | 16/16 | 0.783 | Download | Download |
2. Performance on Cityscapes (19 classes, 1024 x 2048)
Training: 768x768 random crop
validation: 1024x2048
| Model | Batch Size | FLOPs | train/val OS | mIoU | Dropbox | Tencent Weiyun |
|---|---|---|---|---|---|---|
| DeepLabV3Plus-MobileNet | 16 | 135G | 16/16 | 0.721 | Download | Download |
| DeepLabV3Plus-ResNet101 | 16 | N/A | 16/16 | 0.762 | Download | N/A |
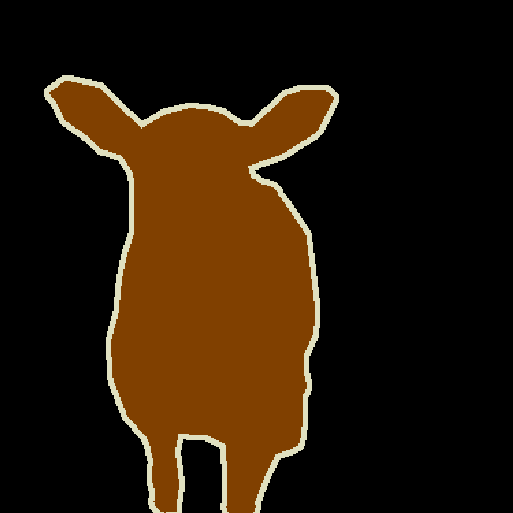
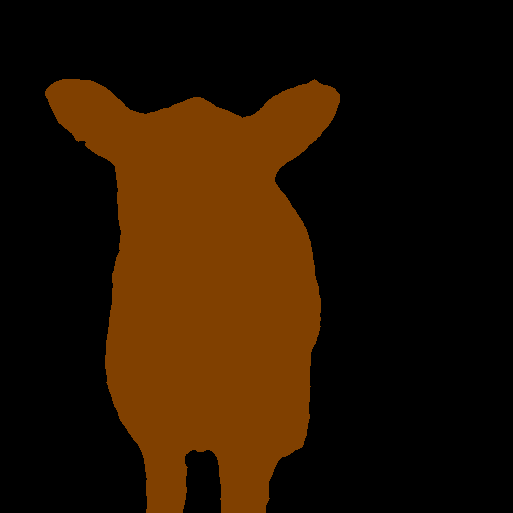
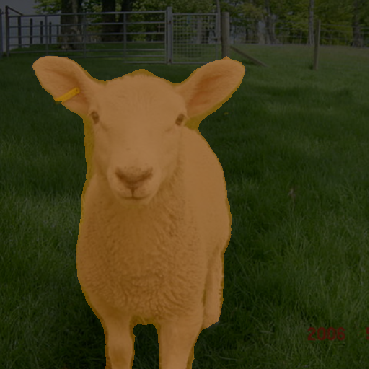
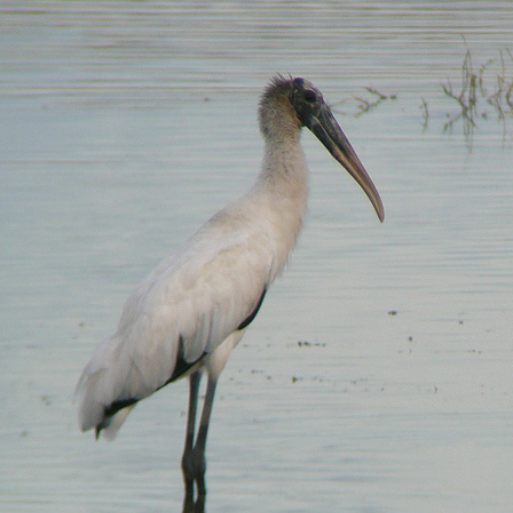
Segmentation Results on Pascal VOC2012 (DeepLabv3Plus-MobileNet)
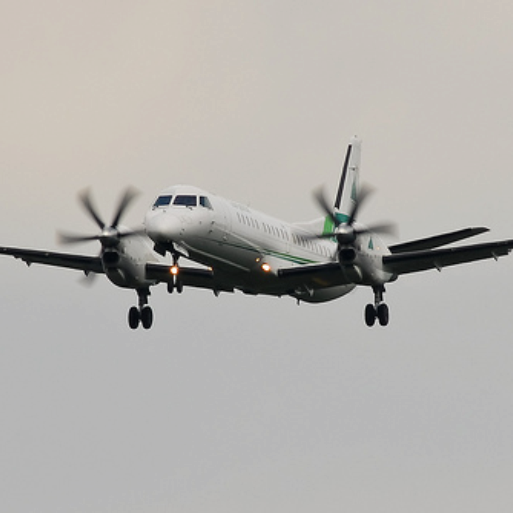
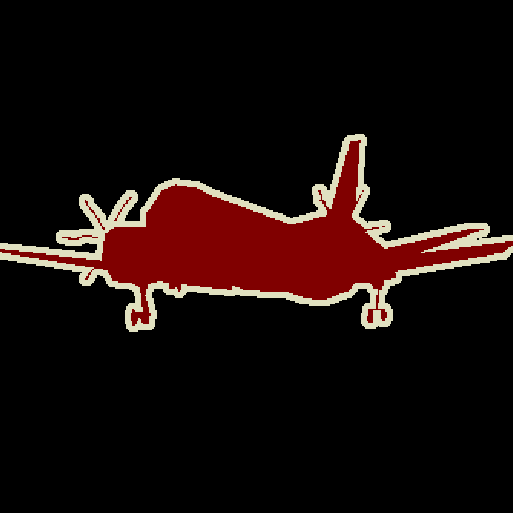
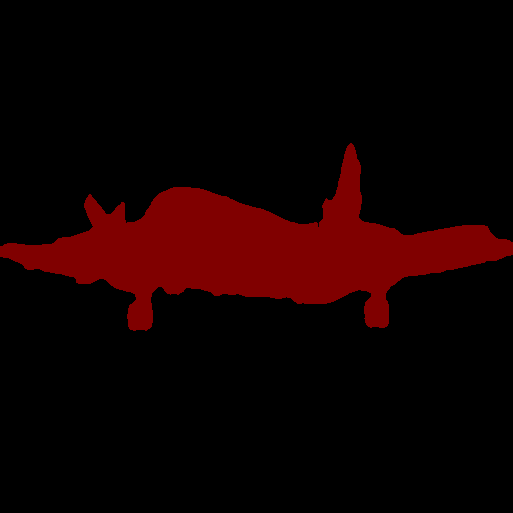
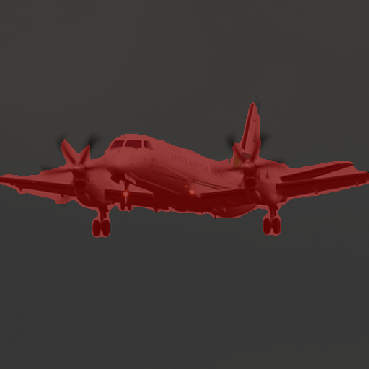

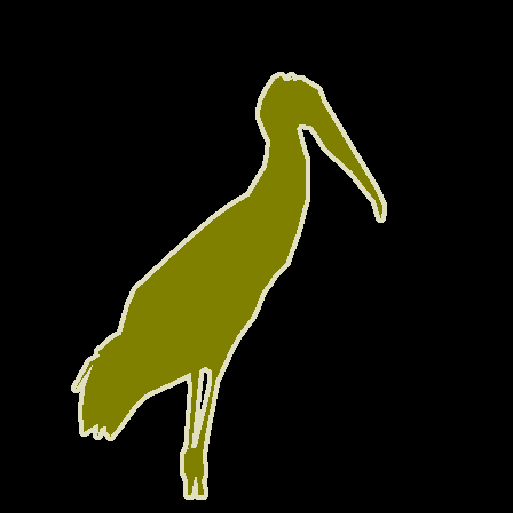
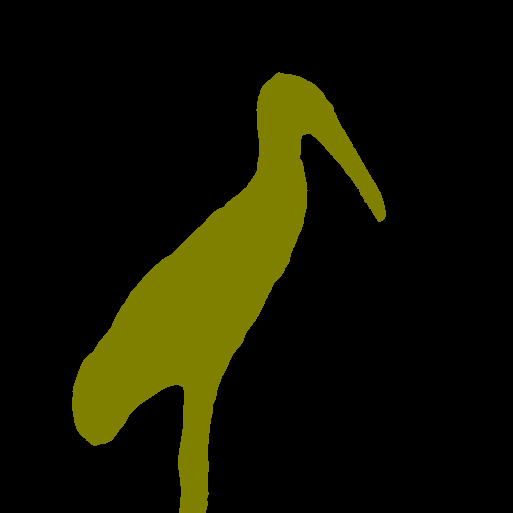
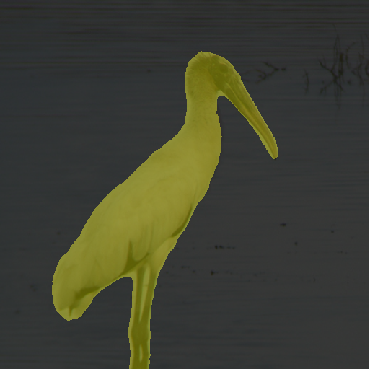
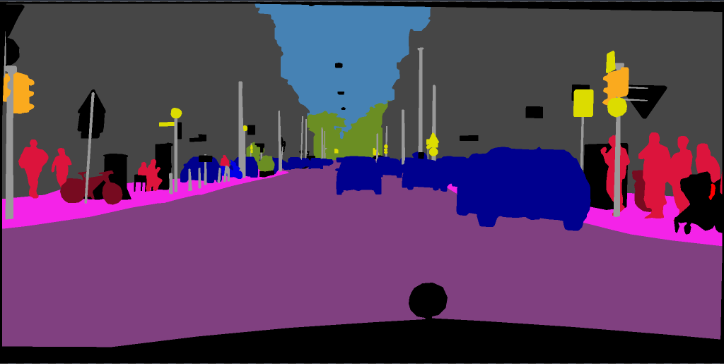
Segmentation Results on Cityscapes (DeepLabv3Plus-MobileNet)
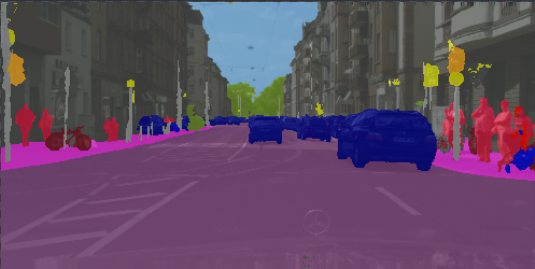
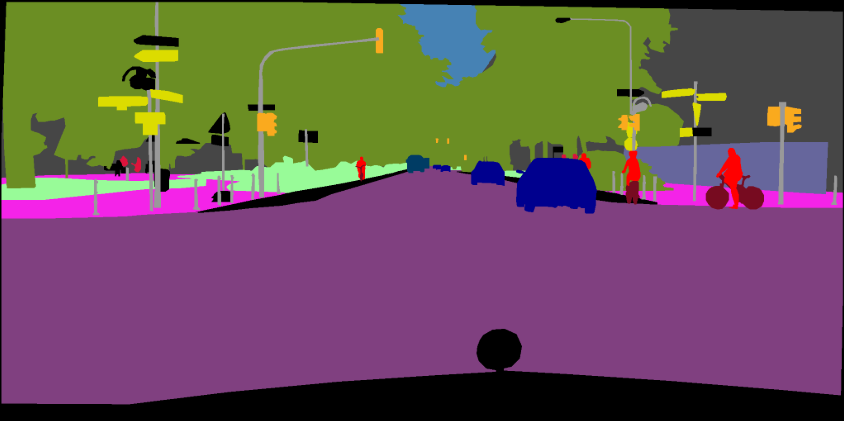
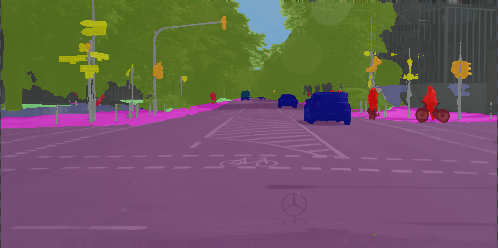
Visualization of training
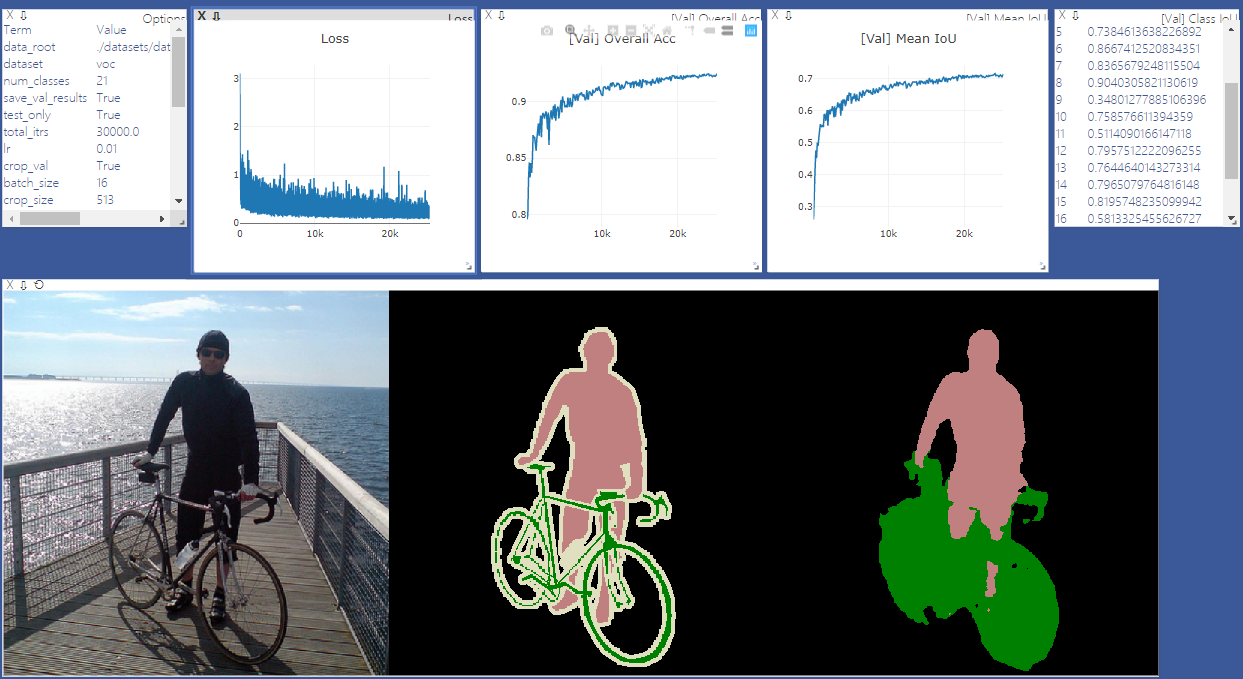
Pascal VOC
1. Requirements
pip install -r requirements.txt
2. Prepare Datasets
2.1 Standard Pascal VOC
You can run train.py with "--download" option to download and extract pascal voc dataset. The defaut path is './datasets/data':
/datasets
    /data
        /VOCdevkit
            /VOC2012
                /SegmentationClass
                /JPEGImages
                ...
            ...
        /VOCtrainval_11-May-2012.tar
        ...
2.2 Pascal VOC trainaug (Recommended!!)
See chapter 4 of [2]
The original dataset contains 1464 (train), 1449 (val), and 1456 (test) pixel-level annotated images. We augment the dataset by the extra annotations provided by [76], resulting in 10582 (trainaug) training images. The performance is measured in terms of pixel intersection-over-union averaged across the 21 classes (mIOU).
./datasets/data/train_aug.txt includes the file names of 10582 trainaug images (val images are excluded). Please to download their labels from Dropbox or Tencent Weiyun. Those labels come from DrSleep's repo.
Extract trainaug labels (SegmentationClassAug) to the VOC2012 directory.
/datasets
    /data
        /VOCdevkit
            /VOC2012
                /SegmentationClass
                /SegmentationClassAug  # <= the trainaug labels
                /JPEGImages
                ...
            ...
        /VOCtrainval_11-May-2012.tar
        ...
3. Training on Pascal VOC2012 Aug
3.1 Visualize training (Optional)
Start visdom sever for visualization. Please remove '--enable_vis' if visualization is not needed.
# Run visdom server on port 28333
visdom -port 28333
3.2 Training with OS=16
Run main.py with "--year 2012_aug" to train your model on Pascal VOC2012 Aug. You can also parallel your training on 4 GPUs with '--gpu_id 0,1,2,3'
Note: There is no SyncBN in this repo, so training with multple GPUs and small batch size may degrades the performance. See PyTorch-Encoding for more details about SyncBN
python main.py --model deeplabv3plus_mobilenet --enable_vis --vis_port 28333 --gpu_id 0 --year 2012_aug --crop_val --lr 0.01 --crop_size 513 --batch_size 16 --output_stride 16
3.3 Continue training
Run main.py with '--continue_training' to restore the state_dict of optimizer and scheduler from YOUR_CKPT.
python main.py ... --ckpt YOUR_CKPT --continue_training
3.4. Testing
Results will be saved at ./results.
python main.py --model deeplabv3plus_mobilenet --enable_vis --vis_port 28333 --gpu_id 0 --year 2012_aug --crop_val --lr 0.01 --crop_size 513 --batch_size 16 --output_stride 16 --ckpt checkpoints/best_deeplabv3plus_mobilenet_voc_os16.pth --test_only --save_val_results
Cityscapes
1. Download cityscapes and extract it to 'datasets/data/cityscapes'
/datasets
    /data
        /cityscapes
            /gtFine
            /leftImg8bit
2. Train your model on Cityscapes
python main.py --model deeplabv3plus_mobilenet --dataset cityscapes --enable_vis --vis_port 28333 --gpu_id 0 --lr 0.1 --crop_size 768 --batch_size 16 --output_stride 16 --data_root ./datasets/data/cityscapes
Reference
[1] Rethinking Atrous Convolution for Semantic Image Segmentation
[2] Encoder-Decoder with Atrous Separable Convolution for Semantic Image Segmentation
관련 프로젝트 살펴보기
tensorflow/tensorflow
모두를 위한 오픈소스 머신러닝 프레임워크
201,593 스타huggingface/transformers
🤗 Transformers: 텍스트, 비전, 오디오, 멀티모달 분야의 최첨단 머신러닝 모델을 위한 모델 정의 프레임워크로, 추론과 학습을 모두 지원합니다.
168,951 스타AUTOMATIC1111/stable-diffusion-webui
Stable Diffusion 웹 UI
165,305 스타Comfy-Org/ComfyUI
그래프와 노드로 구성된 인터페이스를 갖춘, 가장 강력하고 모듈성이 뛰어난 확산 모델 GUI, API, 백엔드입니다. 세계에서 가장 빠른 로컬 추론 엔진입니다.
146,688 스타