
ShangtongZhang/DeepRL
ShangtongZhang/DeepRL has 3,457 GitHub stars and 694 forks. GitHot measured 0 in 7 days. Last checked 2026-11-09 13:44 UTC. Last push 2024-04-16.
PyTorch 기반 심층 강화학습 알고리즘의 모듈화 구현
측정된 스타 증가
- in 24h
- 업데이트 지연
- in 7 days
- 0
- in 15 days
- 업데이트 지연
- in 1 month
- 업데이트 지연
서로 겹치는 기간의 순증가량이며 일별 합계가 아닙니다. 측정값이 없으면 비워 둡니다. 스타는 관심도를 나타내며 품질을 보장하지 않습니다.
README.md
OriginalDeepRL
If you have any question or want to report a bug, please open an issue instead of emailing me directly.
Modularized implementation of popular deep RL algorithms in PyTorch.
Easy switch between toy tasks and challenging games.
Implemented algorithms:
- (Double/Dueling/Prioritized) Deep Q-Learning (DQN)
- Categorical DQN (C51)
- Quantile Regression DQN (QR-DQN)
- (Continuous/Discrete) Synchronous Advantage Actor Critic (A2C)
- Synchronous N-Step Q-Learning (N-Step DQN)
- Deep Deterministic Policy Gradient (DDPG)
- Proximal Policy Optimization (PPO)
- The Option-Critic Architecture (OC)
- Twined Delayed DDPG (TD3)
- Off-PAC-KL/TruncatedETD/DifferentialGQ/MVPI/ReverseRL/COF-PAC/GradientDICE/Bi-Res-DDPG/DAC/Geoff-PAC/QUOTA/ACE
The DQN agent, as well as C51 and QR-DQN, has an asynchronous actor for data generation and an asynchronous replay buffer for transferring data to GPU. Using 1 RTX 2080 Ti and 3 threads, the DQN agent runs for 10M steps (40M frames, 2.5M gradient updates) for Breakout within 6 hours.
Dependency
- PyTorch v1.5.1
- See
Dockerfileandrequirements.txtfor more details
Usage
examples.py contains examples for all the implemented algorithms.Dockerfile contains the environment for generating the curves below.
Please use this bibtex if you want to cite this repo
@misc{deeprl,
  author = {Zhang, Shangtong},
  title = {Modularized Implementation of Deep RL Algorithms in PyTorch},
  year = {2018},
  publisher = {GitHub},
  journal = {GitHub Repository},
  howpublished = {\url{https://github.com/ShangtongZhang/DeepRL}},
}
Curves (commit 9e811e)
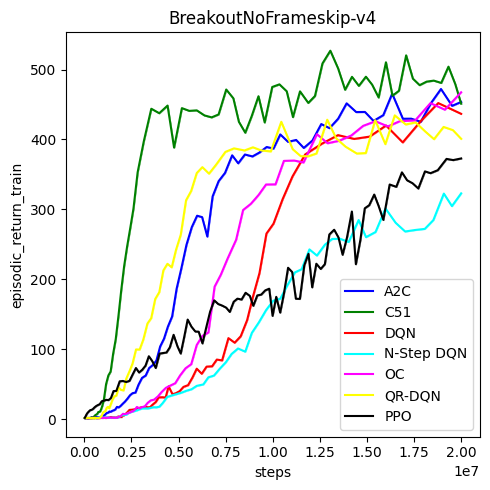
BreakoutNoFrameskip-v4 (1 run)
Mujoco
DDPG/TD3 evaluation performance.
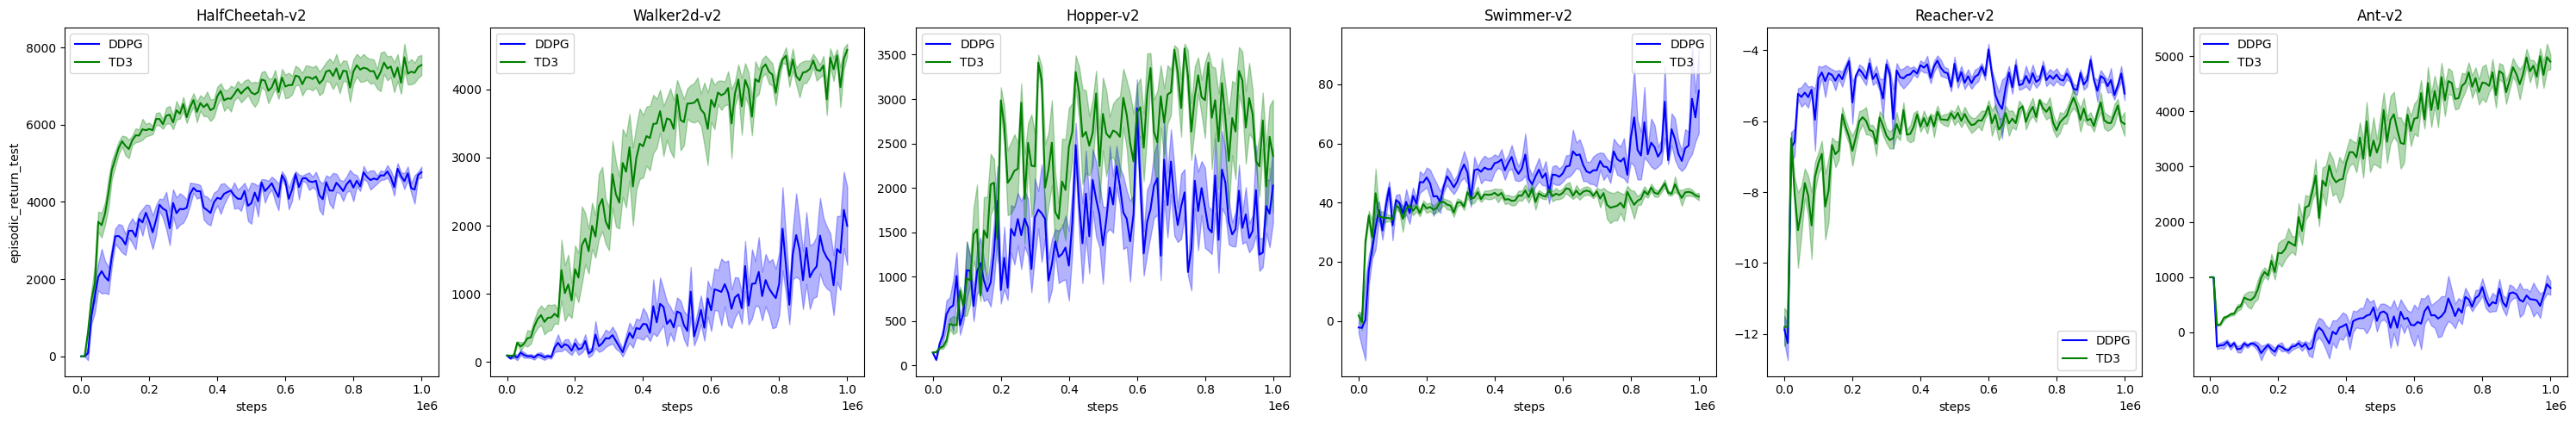 (5 runs, mean + standard error)
PPO online performance.
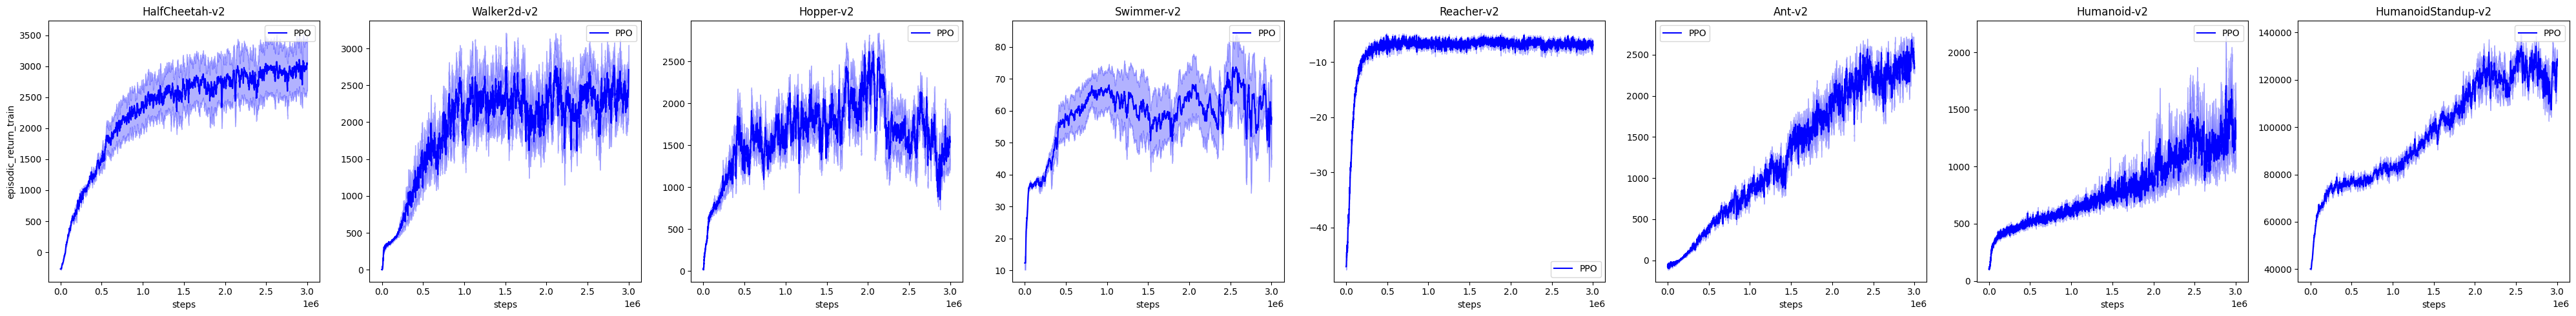 (5 runs, mean + standard error, smoothed by a window of size 10)
References
- Human Level Control through Deep Reinforcement Learning
- Asynchronous Methods for Deep Reinforcement Learning
- Deep Reinforcement Learning with Double Q-learning
- Dueling Network Architectures for Deep Reinforcement Learning
- Playing Atari with Deep Reinforcement Learning
- HOGWILD!: A Lock-Free Approach to Parallelizing Stochastic Gradient Descent
- Deterministic Policy Gradient Algorithms
- Continuous control with deep reinforcement learning
- High-Dimensional Continuous Control Using Generalized Advantage Estimation
- Hybrid Reward Architecture for Reinforcement Learning
- Trust Region Policy Optimization
- Proximal Policy Optimization Algorithms
- Emergence of Locomotion Behaviours in Rich Environments
- Action-Conditional Video Prediction using Deep Networks in Atari Games
- A Distributional Perspective on Reinforcement Learning
- Distributional Reinforcement Learning with Quantile Regression
- The Option-Critic Architecture
- Addressing Function Approximation Error in Actor-Critic Methods
- Some hyper-parameters are from DeepMind Control Suite, OpenAI Baselines and Ilya Kostrikov
Code of My Papers
They are located in other branches of this repo and seem to be good examples for using this codebase.
- Global Optimality and Finite Sample Analysis of Softmax Off-Policy Actor Critic under State Distribution Mismatch [Off-PAC-KL]
- Truncated Emphatic Temporal Difference Methods for Prediction and Control [TruncatedETD]
- A Deeper Look at Discounting Mismatch in Actor-Critic Algorithms [Discounting]
- Breaking the Deadly Triad with a Target Network [TargetNetwork]
- Average-Reward Off-Policy Policy Evaluation with Function Approximation [DifferentialGQ]
- Mean-Variance Policy Iteration for Risk-Averse Reinforcement Learning [MVPI]
- Learning Retrospective Knowledge with Reverse Reinforcement Learning [ReverseRL]
- Provably Convergent Two-Timescale Off-Policy Actor-Critic with Function Approximation [COF-PAC, TD3-random]
- GradientDICE: Rethinking Generalized Offline Estimation of Stationary Values [GradientDICE]
- Deep Residual Reinforcement Learning [Bi-Res-DDPG]
- Generalized Off-Policy Actor-Critic [Geoff-PAC, TD3-random]
- DAC: The Double Actor-Critic Architecture for Learning Options [DAC]
- QUOTA: The Quantile Option Architecture for Reinforcement Learning [QUOTA-discrete, QUOTA-continuous]
- ACE: An Actor Ensemble Algorithm for Continuous Control with Tree Search [ACE]
관련 프로젝트 살펴보기
tensorflow/tensorflow
모두를 위한 오픈소스 머신러닝 프레임워크
201,427 스타huggingface/transformers
🤗 Transformers: 텍스트, 비전, 오디오, 멀티모달 분야의 최첨단 머신러닝 모델을 위한 모델 정의 프레임워크로, 추론과 학습을 모두 지원합니다.
168,711 스타AUTOMATIC1111/stable-diffusion-webui
Stable Diffusion 웹 UI
165,274 스타Comfy-Org/ComfyUI
그래프와 노드로 구성된 인터페이스를 갖춘, 가장 강력하고 모듈성이 뛰어난 확산 모델 GUI, API, 백엔드입니다. 세계에서 가장 빠른 로컬 추론 엔진입니다.
146,024 스타