
SakanaAI/evo-memory
SakanaAI/evo-memory has 363 GitHub stars and 39 forks. GitHot measured -1 stars in 24 hours. Last checked 2026-11-20 04:06 UTC. Last push 2024-10-22.
측정된 스타 증가
- in 24h
- -1
- in 7 days
- 기록 수집 중
- in 15 days
- 기록 수집 중
- in 1 month
- 기록 수집 중
서로 겹치는 기간의 순증가량이며 일별 합계가 아닙니다. 측정값이 없으면 비워 둡니다. 스타는 관심도를 나타내며 품질을 보장하지 않습니다.
소개
Code to train and evaluate Neural Attention Memory Models to obtain universally-applicable memory systems for transformers.
머신러닝README.md
Original
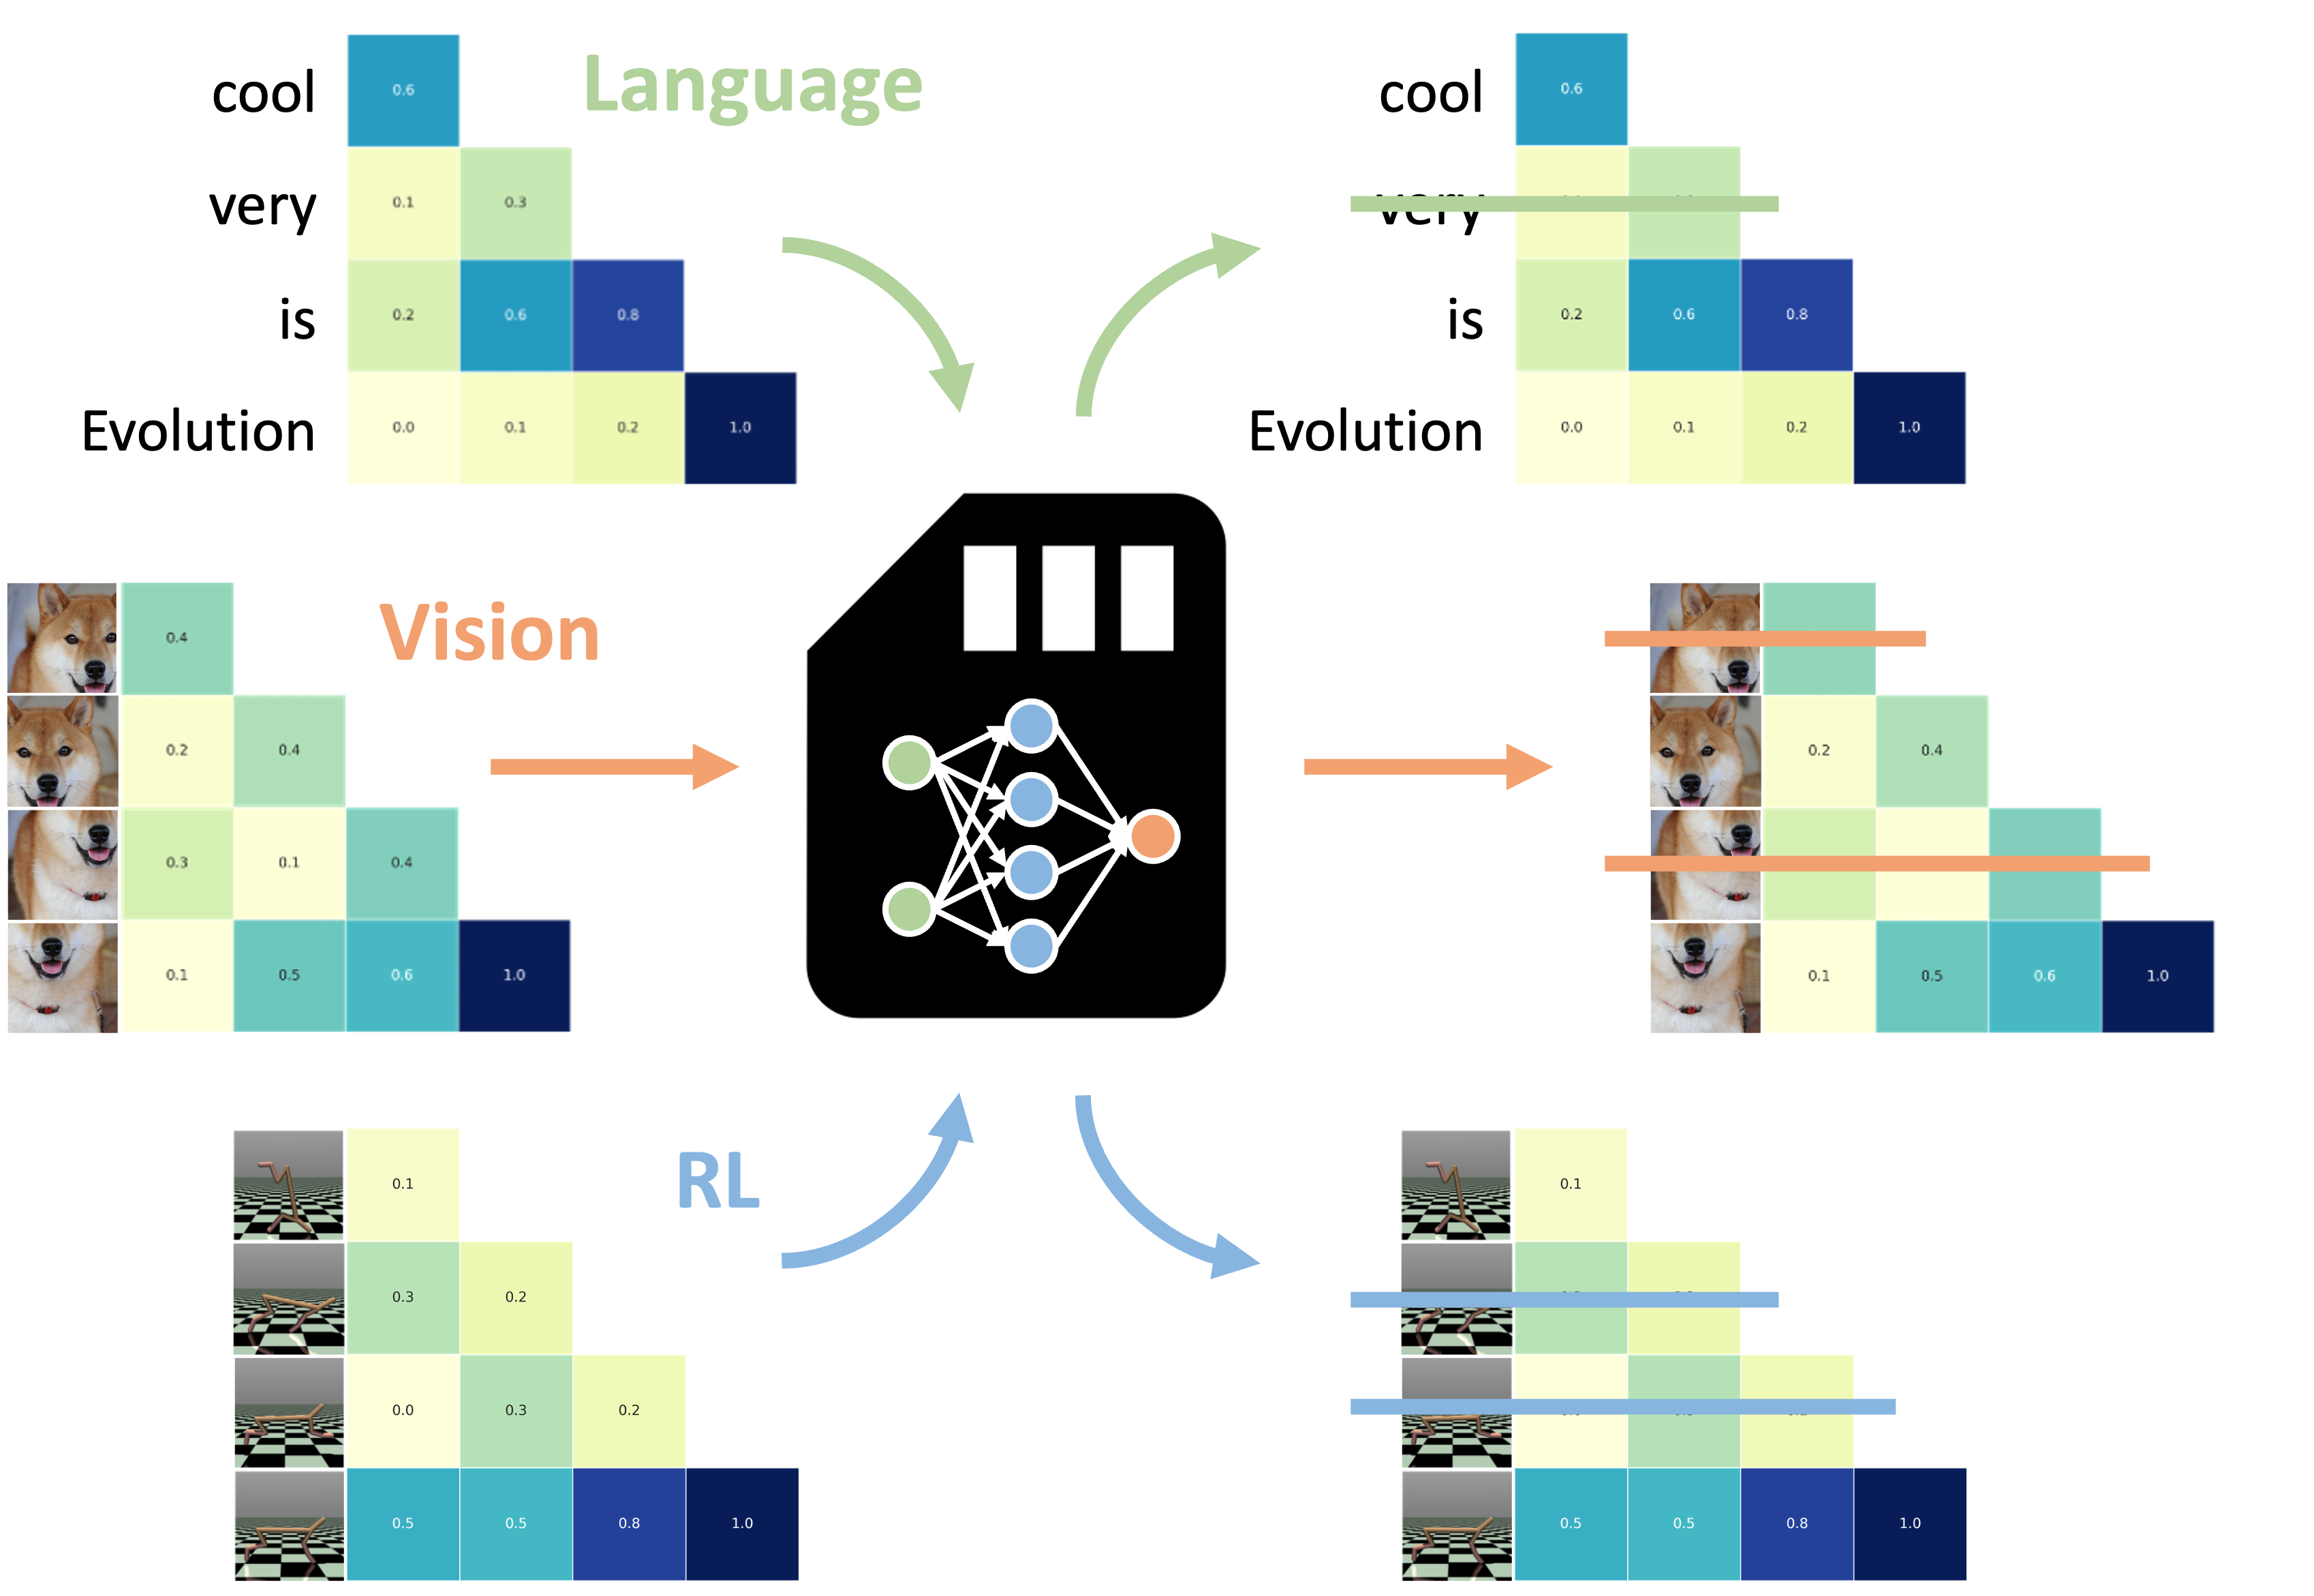
An Evolved Universal Transformer Memory
📄 [Paper] | 🤗 [Hugging Face] 📁 [Dataset]
Installation
We provide means to install this repository with conda:
For the full set of dependencies with fixed versions (provided to ensure some level of long-term reproducibility):
conda env create --file=env.yaml
For a more minimal and less constrained set of dependencies (for future development/extensions):
conda env create --file=env_minimal.yaml
Usage
Training
Training following the incremental setup described in our work can be replicated via the following hydra commands:
stage 1 training:
torchrun --standalone --nproc_per_node=$NUM_OF_GPUs main.py run@_global_=namm_bam_i1.yaml
stage 2 training:
torchrun --standalone --nproc_per_node=$NUM_OF_GPUs main.py run@_global_=namm_bam_i2.yaml init_from='path/to/stage1/results/ckpt.pt'
stage 3 training:
torchrun --standalone --nproc_per_node=$NUM_OF_GPUs main.py run@_global_=namm_bam_i3.yaml init_from='path/to/stage2/results/ckpt.pt'
Evaluation
Evaluating trained NAMMs on the full set of LongBench tasks can be replicated for both NAMMs with the following command:
torchrun --standalone --nproc_per_node=$NUM_OF_GPUs main.py run@_global_=namm_bam_eval.yaml init_from='path/to/results/ckpt.pt'
Evaluating trained NAMMs on the full set of ChouBun tasks can be replicated with the following command:
torchrun --standalone --nproc_per_node=$NUM_OF_GPUs main.py run@_global_=namm_bam_eval_choubun.yaml init_from='path/to/results/ckpt.pt'
Additional notes
Using wandb to log the results (through the hydra setting wandb_log=true) requires authenticating to the wandb server via the following command:
wandb login
and using your account's API key (which you should be able to find here)
Gated models (e.g., Llama)
Using gated models requires authenticating to the hugging face hub by running:
huggingface-cli login
and using your account's access tokens (which you should be able to find here)
Bibtex
To cite our work, you can use the following:
@article{sakana2024memory,
title={An Evolved Universal Transformer Memory},
       author={Edoardo Cetin and Qi Sun and Tianyu Zhao and Yujin Tang},
       year={2024},
       eprint={2410.13166},
       archivePrefix={arXiv},
       primaryClass={cs.LG},
       url={https://arxiv.org/abs/2410.13166},
}