JiahuiYu/generative_inpainting
JiahuiYu/generative_inpainting has 3,469 GitHub stars and 796 forks. GitHot measured -1 stars in 24 hours and -1 in 7 days. Last checked 2026-11-12 11:38 UTC. Last push 2024-06-27.
DeepFill v1/v2 with Contextual Attention and Gated Convolution, CVPR 2018, and ICCV 2019 Oral
측정된 스타 증가
- in 24h
- -1
- in 7 days
- -1
- in 15 days
- 기록 수집 중
- in 1 month
- 기록 수집 중
서로 겹치는 기간의 순증가량이며 일별 합계가 아닙니다. 측정값이 없으면 비워 둡니다. 스타는 관심도를 나타내며 품질을 보장하지 않습니다.
README.md
OriginalGenerative Image Inpainting


An open source framework for generative image inpainting task, with the support of Contextual Attention (CVPR 2018) and Gated Convolution (ICCV 2019 Oral).
For the code of previous version (DeepFill v1), please checkout branch v1.0.0.
CVPR 2018 Paper | ICCV 2019 Oral Paper | Project | Demo | YouTube v1 | YouTube v2 | BibTex
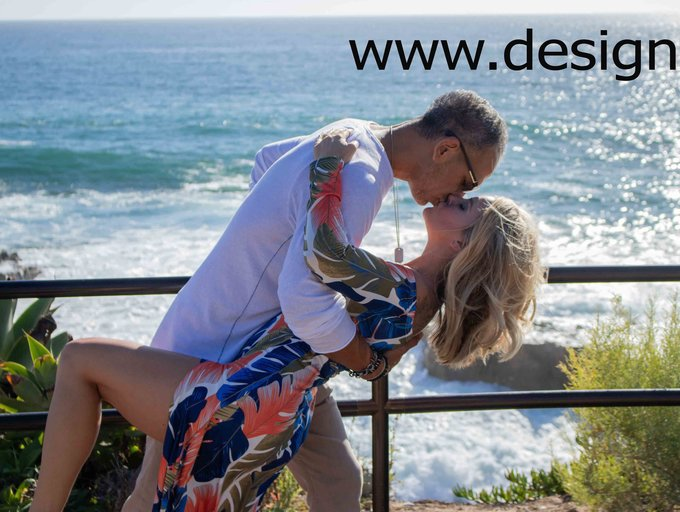
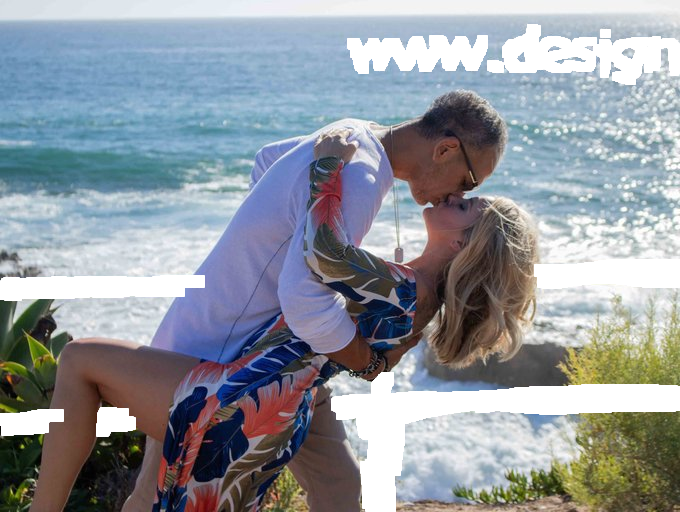
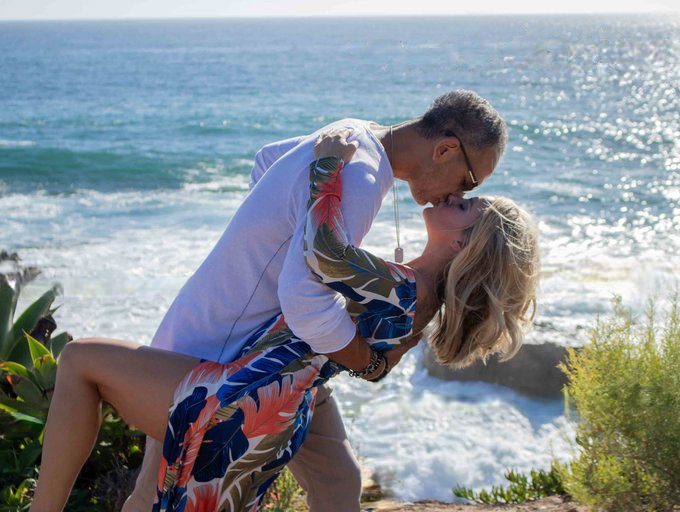
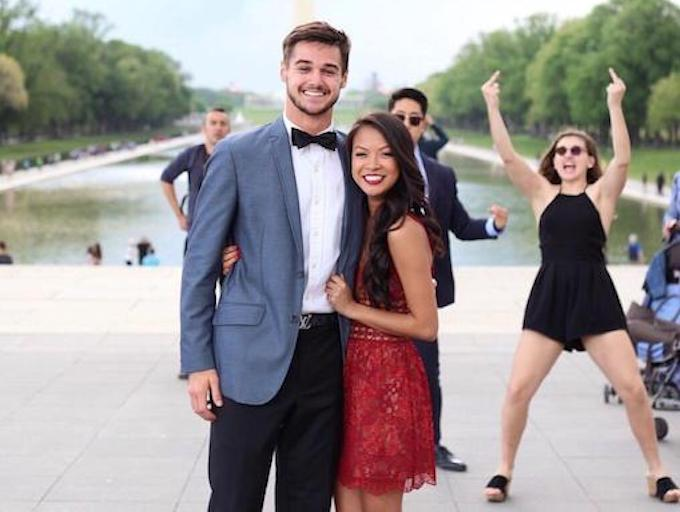
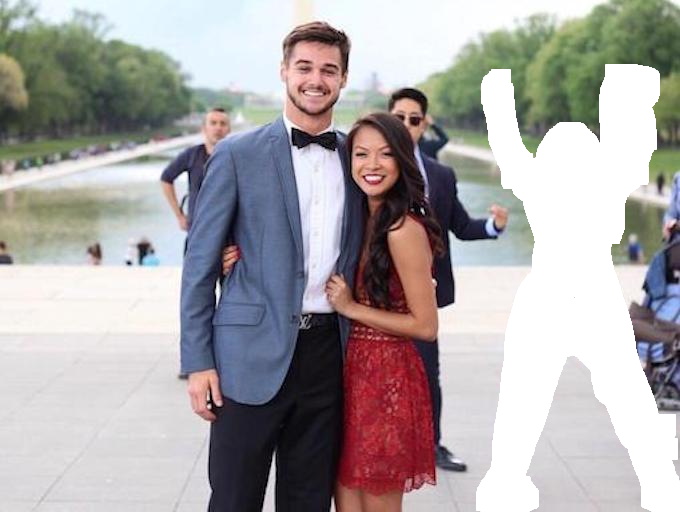
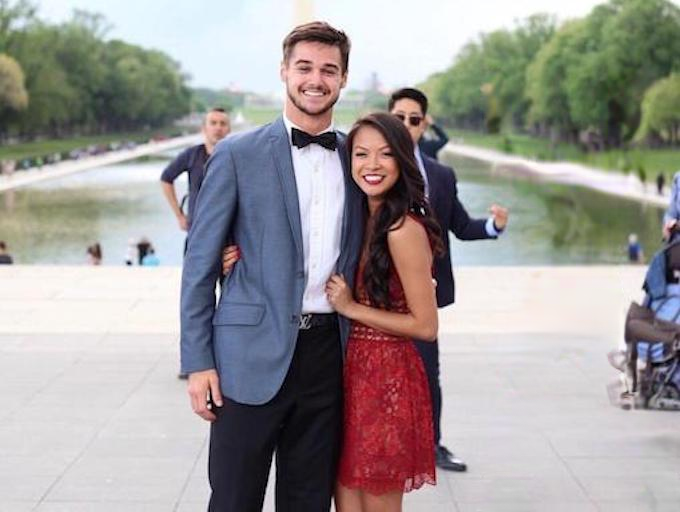
Free-form image inpainting results by our system built on gated convolution. Each triad shows original image, free-form input and our result from left to right.
Run
- Requirements:
- Install python3.
- Install tensorflow (tested on Release 1.3.0, 1.4.0, 1.5.0, 1.6.0, 1.7.0).
- Install tensorflow toolkit neuralgym (run
pip install git+https://github.com/JiahuiYu/neuralgym).
- Training:
- Prepare training images filelist and shuffle it (example).
- Modify inpaint.yml to set DATA_FLIST, LOG_DIR, IMG_SHAPES and other parameters.
- Run
python train.py.
- Resume training:
- Modify MODEL_RESTORE flag in inpaint.yml. E.g., MODEL_RESTORE: 20180115220926508503_places2_model.
- Run
python train.py.
- Testing:
- Run
python test.py --image examples/input.png --mask examples/mask.png --output examples/output.png --checkpoint model_logs/your_model_dir.
- Run
- Still have questions?
- If you still have questions (e.g.: How filelist looks like? How to use multi-gpus? How to do batch testing?), please first search over closed issues. If the problem is not solved, please open a new issue.
Pretrained models
Download the model dirs and put it under model_logs/ (rename checkpoint.txt to checkpoint because google drive automatically add ext after download). Run testing or resume training as described above. All models are trained with images of resolution 256x256 and largest hole size 128x128, above which the results may be deteriorated. We provide several example test cases. Please run:
# Places2 512x680 input
python test.py --image examples/places2/case1_input.png --mask examples/places2/case1_mask.png --output examples/places2/case1_output.png --checkpoint_dir model_logs/release_places2_256
# CelebA-HQ 256x256 input
# Please visit CelebA-HQ demo at: jhyu.me/deepfill
Note: Please make sure the mask file completely cover the masks in input file. You may check it with saving a new image to visualize cv2.imwrite('new.png', img - mask).
TensorBoard
Visualization on TensorBoard for training and validation is supported. Run tensorboard --logdir model_logs --port 6006 to view training progress.
License
CC 4.0 Attribution-NonCommercial International
The software is for educational and academic research purposes only.
Citing
@article{yu2018generative,
  title={Generative Image Inpainting with Contextual Attention},
  author={Yu, Jiahui and Lin, Zhe and Yang, Jimei and Shen, Xiaohui and Lu, Xin and Huang, Thomas S},
  journal={arXiv preprint arXiv:1801.07892},
  year={2018}
}

@article{yu2018free,
  title={Free-Form Image Inpainting with Gated Convolution},
  author={Yu, Jiahui and Lin, Zhe and Yang, Jimei and Shen, Xiaohui and Lu, Xin and Huang, Thomas S},
  journal={arXiv preprint arXiv:1806.03589},
  year={2018}
}
관련 프로젝트 살펴보기
tensorflow/tensorflow
모두를 위한 오픈소스 머신러닝 프레임워크
201,584 스타huggingface/transformers
🤗 Transformers: 텍스트, 비전, 오디오, 멀티모달 분야의 최첨단 머신러닝 모델을 위한 모델 정의 프레임워크로, 추론과 학습을 모두 지원합니다.
168,917 스타AUTOMATIC1111/stable-diffusion-webui
Stable Diffusion 웹 UI
165,300 스타Comfy-Org/ComfyUI
그래프와 노드로 구성된 인터페이스를 갖춘, 가장 강력하고 모듈성이 뛰어난 확산 모델 GUI, API, 백엔드입니다. 세계에서 가장 빠른 로컬 추론 엔진입니다.
146,472 스타