
HarryVolek/PyTorch_Speaker_Verification
HarryVolek/PyTorch_Speaker_Verification has 600 GitHub stars and 162 forks. GitHot measured 0 stars in 24 hours and 0 in 7 days. Last checked 2026-11-21 06:06 UTC. Last push 2022-01-20.
측정된 스타 증가
- in 24h
- 0
- in 7 days
- 0
- in 15 days
- 기록 수집 중
- in 1 month
- 기록 수집 중
서로 겹치는 기간의 순증가량이며 일별 합계가 아닙니다. 측정값이 없으면 비워 둡니다. 스타는 관심도를 나타내며 품질을 보장하지 않습니다.
소개
PyTorch implementation of "Generalized End-to-End Loss for Speaker Verification" by Wan, Li et al.
머신러닝README.md
OriginalPyTorch_Speaker_Verification
PyTorch implementation of speech embedding net and loss described here: https://arxiv.org/pdf/1710.10467.pdf.
Also contains code to create embeddings compatible as input for the speaker diarization model found at https://github.com/google/uis-rnn
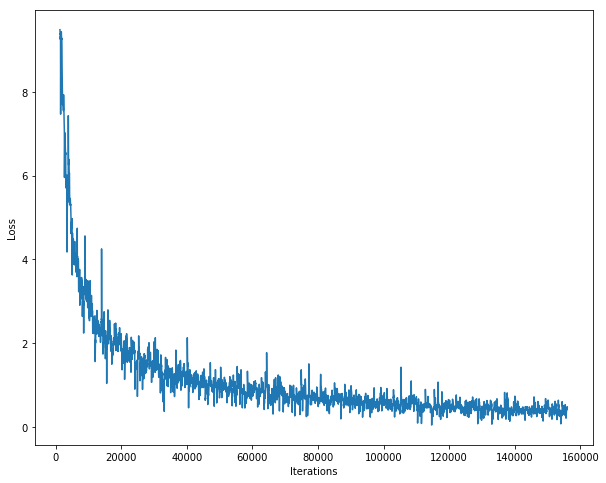
The TIMIT speech corpus was used to train the model, found here: https://catalog.ldc.upenn.edu/LDC93S1, or here, https://github.com/philipperemy/timit
Dependencies
- PyTorch 0.4.1
- python 3.5+
- numpy 1.15.4
- librosa 0.6.1
The python WebRTC VAD found at https://github.com/wiseman/py-webrtcvad is required to create run dvector_create.py, but not to train the neural network.
Preprocessing
Change the following config.yaml key to a regex containing all .WAV files in your downloaded TIMIT dataset. The TIMIT .WAV files must be converted to the standard format (RIFF) for the dvector_create.py script, but not for training the neural network.
unprocessed_data: './TIMIT/*/*/*/*.wav'
Run the preprocessing script:
./data_preprocess.py
Two folders will be created, train_tisv and test_tisv, containing .npy files containing numpy ndarrays of speaker utterances with a 90%/10% training/testing split.
Training
To train the speaker verification model, run:
./train_speech_embedder.py
with the following config.yaml key set to true:
training: !!bool "true"
for testing, set the key value to:
training: !!bool "false"
The log file and checkpoint save locations are controlled by the following values:
log_file: './speech_id_checkpoint/Stats'
checkpoint_dir: './speech_id_checkpoint'
Only TI-SV is implemented.
Performance
EER across 10 epochs: 0.0377
D vector embedding creation
After training and testing the model, run dvector_create.py to create the numpy files train_sequence.npy, train_cluster_ids.npy, test_sequence.npy, and test_cluster_ids.npy.
These files can be loaded and used to train the uis-rnn model found at https://github.com/google/uis-rnn