
CVHub520/X-AnyLabeling
CVHub520/X-AnyLabeling has 10,892 GitHub stars and 1,207 forks. GitHot measured +5 stars in 24 hours and +48 in 7 days. Last checked 2026-11-05 22:09 UTC. Last push 2026-11-02.
X-AnyLabeling: 텍스트, 이미지, 동영상, 포인트 클라우드 및 멀티모달 데이터를 라벨링하는 가볍고 효율적이며 통합된 크로스 플랫폼 데스크톱 애플리케이션으로, 다양한 내장 도구와 최첨단 AI 모델, 유연한 다중 형식 내보내기를 결합합니다.
What you can do
- Unified support for annotating and processing text, image, video, point cloud, and multimodal data.
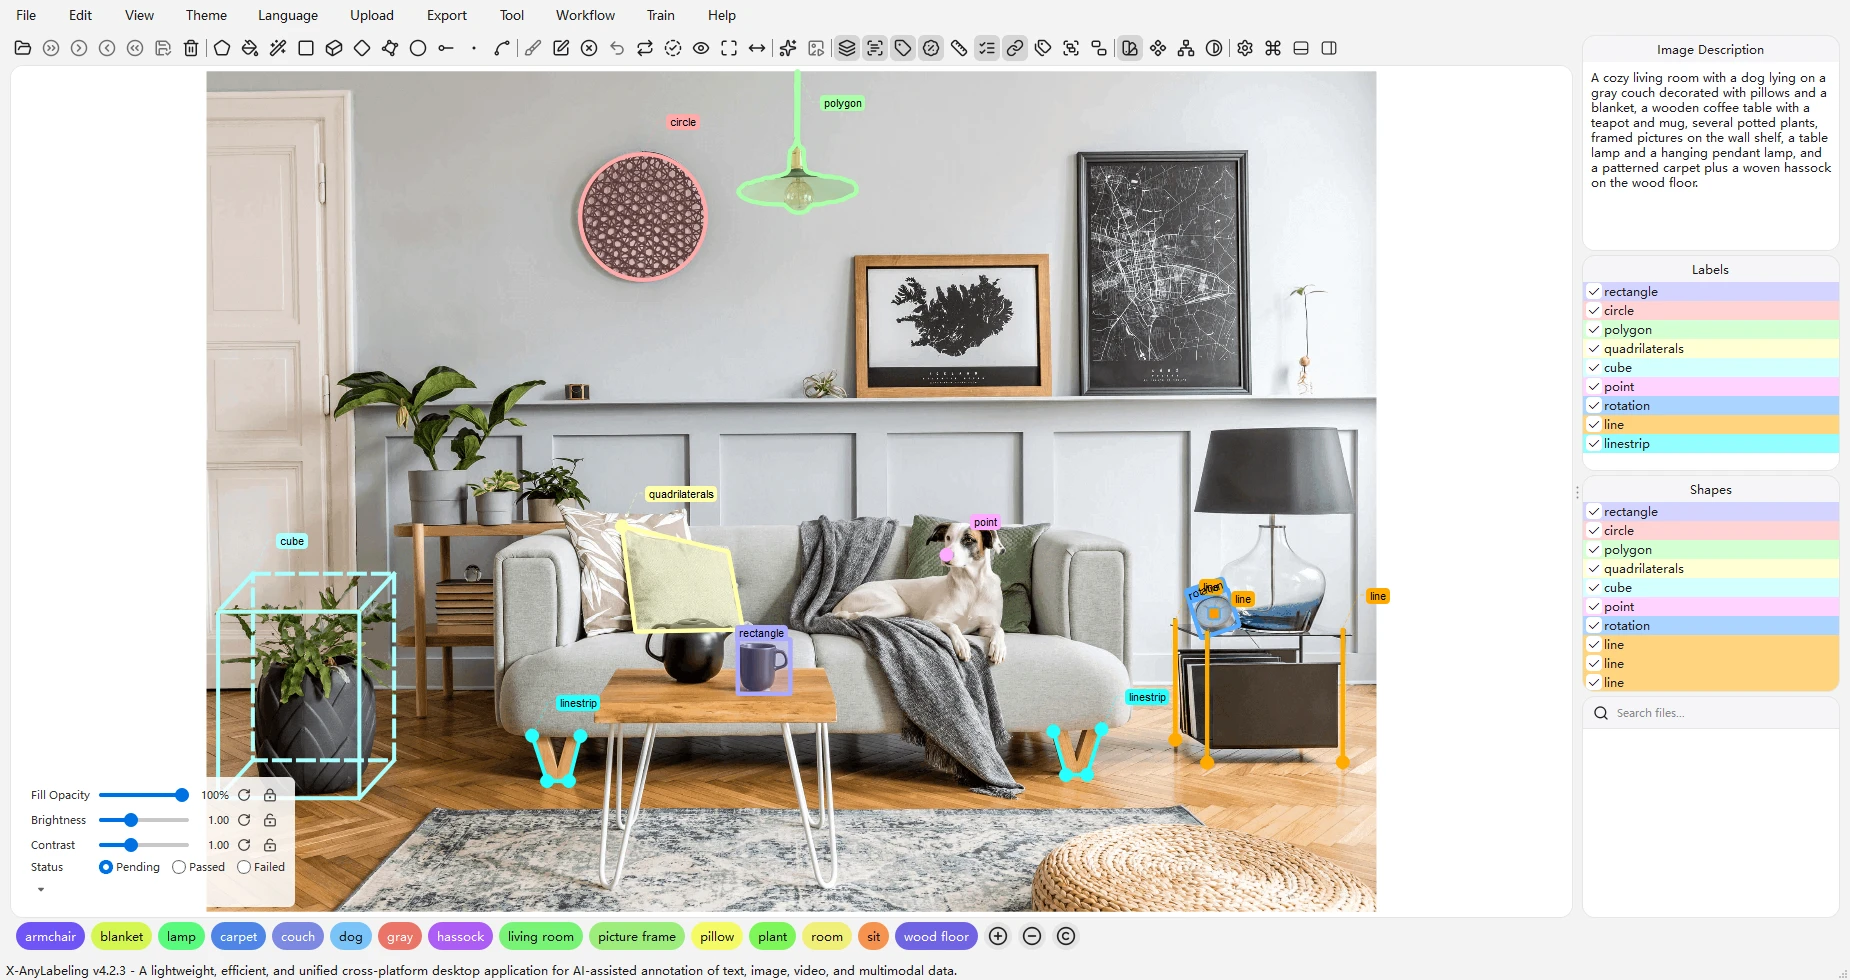
- Covers tasks such as 2D image classification, object detection, instance segmentation, pose estimation, oriented object detection, multi-object tracking, optical character recognition, lane annotation, image captioning, visual question answering, document parsing, and 3D point clouds.
- Provides polygons, rectangles, cuboids, rotated boxes, quadrilaterals, circles, lines, polylines, points, masks, and task-specific tools for text detection, text recognition, relation recognition, and KIE.
- Integrates a wide range of state-of-the-art deep learning models for AI-assisted annotation, automated labeling, and batch dataset prediction.
측정된 스타 증가
- in 24h
- +5
- in 7 days
- +48
- in 15 days
- 업데이트 지연
- in 1 month
- 업데이트 지연
서로 겹치는 기간의 순증가량이며 일별 합계가 아닙니다. 측정값이 없으면 비워 둡니다. 스타는 관심도를 나타내며 품질을 보장하지 않습니다.
README.md
Original



🥳 What's New
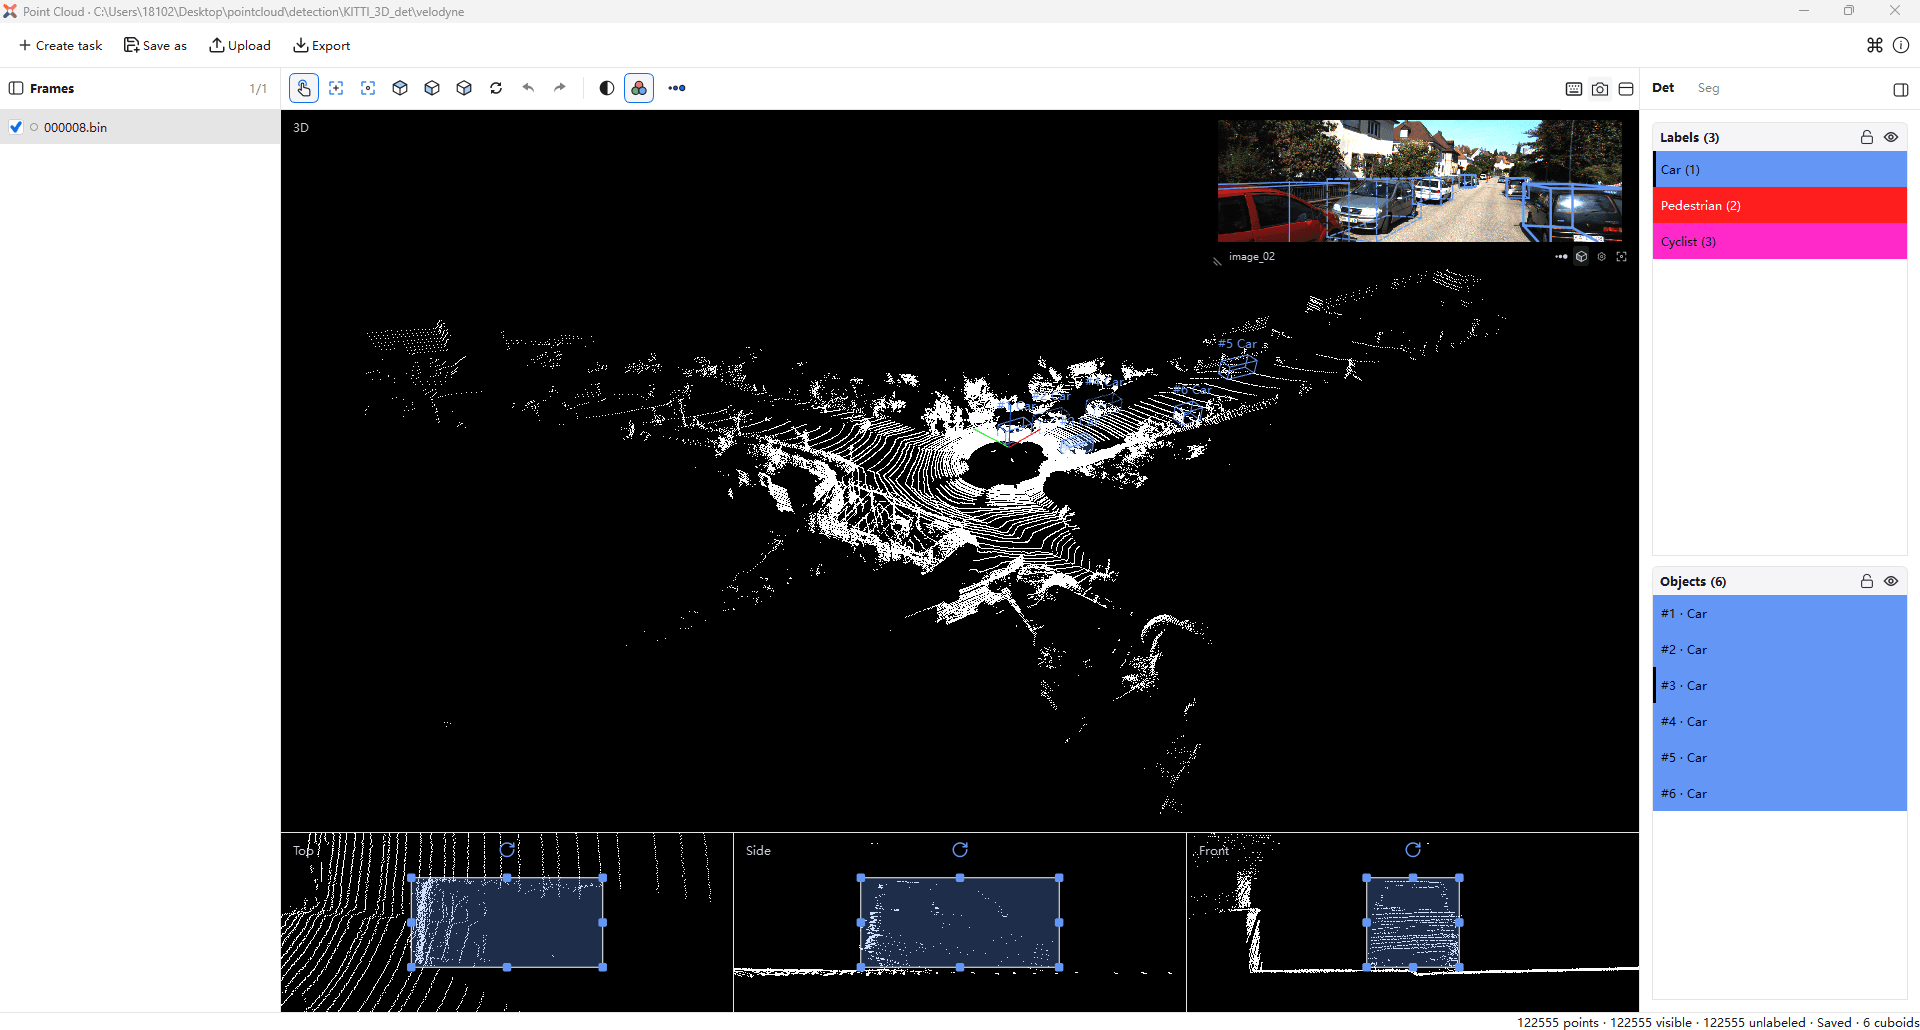
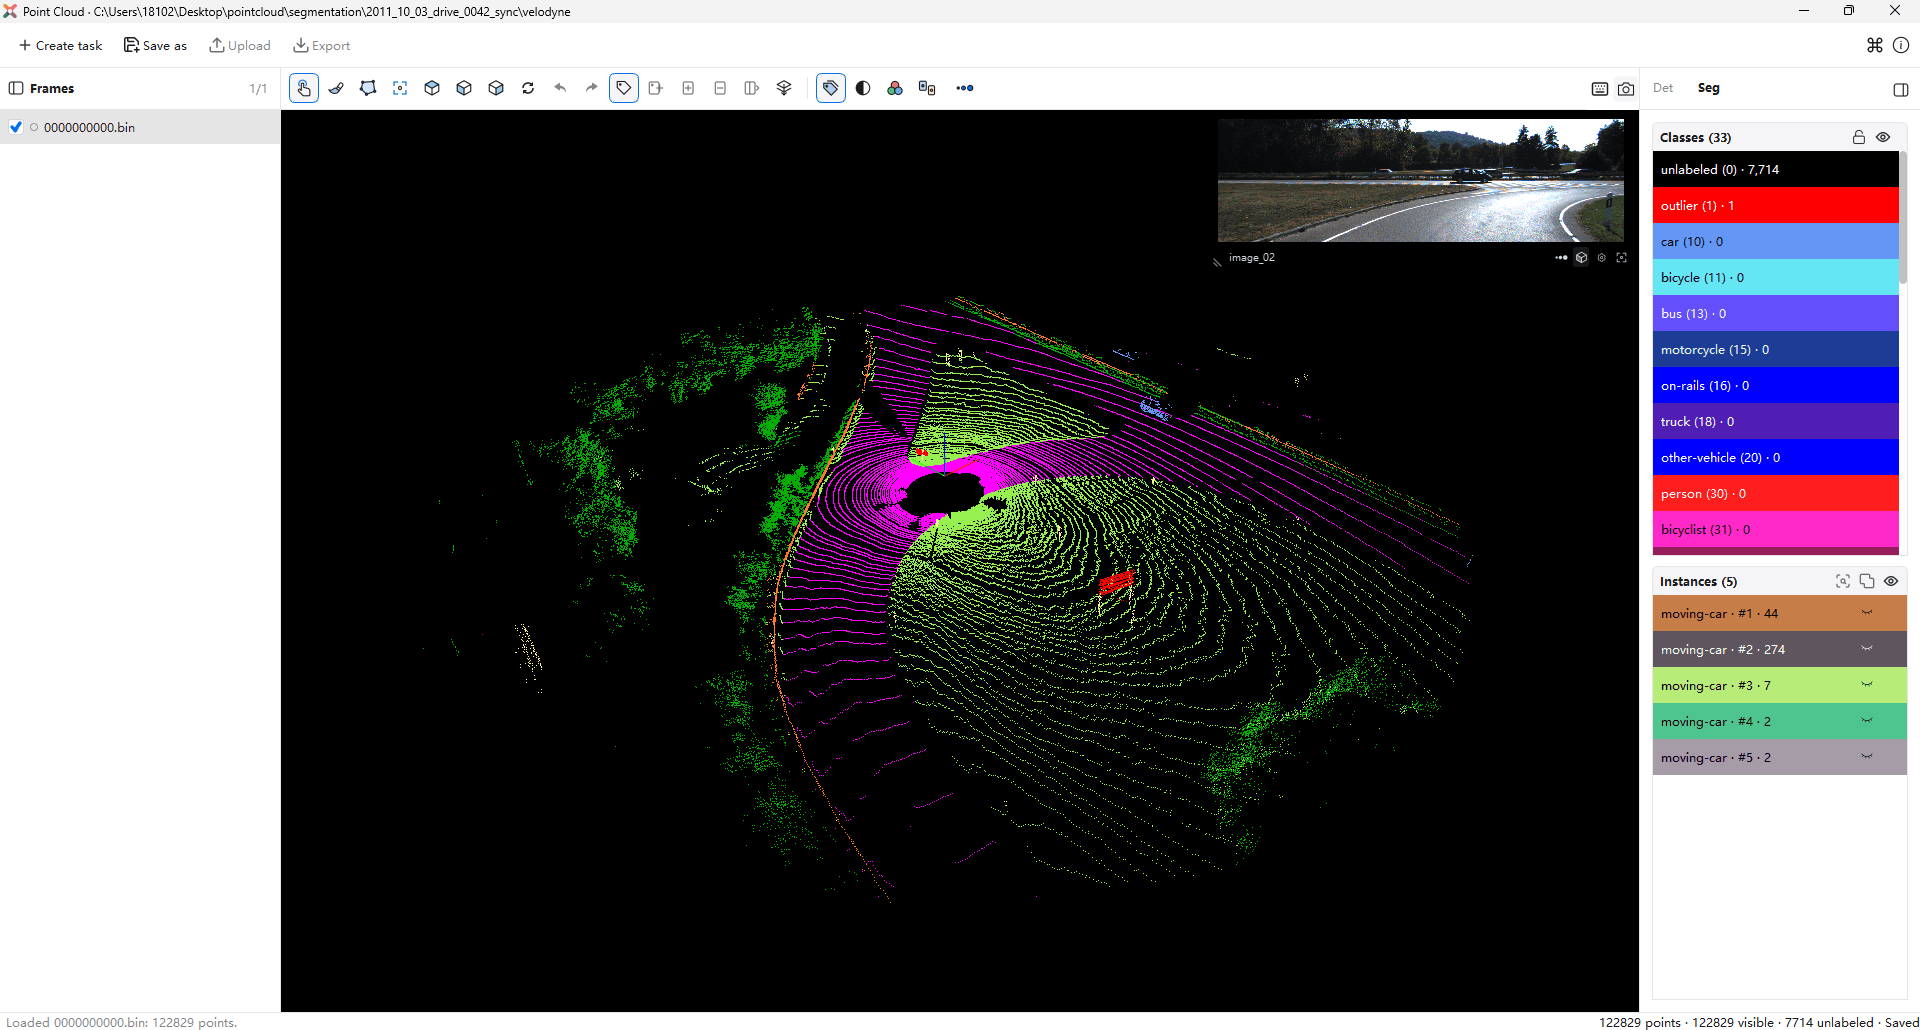
2026-11-03: Add an adjustable image grid with optional cell labels for inspecting annotations.2026-11-01: Add support for the RelateAnything object relation prediction model.2026-10-31: Add object-level multi-task attribute annotation with AI-assisted labeling and concurrent inference.2026-10-30: Add support for the Unlimited-OCR-2 model with image and PDF document parsing with multi-page context.2026-10-28: Add support for the WeVisOne-VL model with detection, referring localization, pointing, counting, OCR, text grounding, segmentation, text and box matting, visual prompting, and freeform instructions.2026-10-28: Add support for the Xiaomi-Lens-0 model with referring comprehension and segmentation, multi-instance grounding, reasoning segmentation, embodied referring, and fine-grained perception.2026-10-27: Add annotation display modes: color by label, instance, or group, and a binary mask view with white foreground on a black background.2026-10-27: Add square annotation support.2026-10-24: Add support for smooth zoom, free panning, and boundary clipping on the canvas.2026-10-18: Add support for GroundingPI, GroundAnything, and GroundAnything-VLM with detection, grounding, referring and category-based pointing, OCR, document layout, GUI grounding, and visual prompting.2026-10-01: Add 3D point cloud annotation, supporting 3D point cloud detection and segmentation.2026-08-19: Add support for image tagging, with tag creation, editing, reordering, and batch deletion.2026-08-12: Add support for D-FINE-seg instance segmentation models.2026-08-08: Add support for the RT-DETRv2-OBB rotated object detection model.2026-08-08: Add the Magic Wand tool for quickly creating polygons from contiguous color regions.2026-08-05: Release X-AnyLabeling v4.0.0.- For more details, please refer to the CHANGELOG
Introduction
X-AnyLabeling is a lightweight, efficient, and unified cross-platform desktop application for AI-assisted annotation of text, image, video, point cloud, and multimodal data. It combines versatile built-in tools, automated labeling workflows, state-of-the-art deep learning models, and flexible multi-format import and export. For remote inference, X-AnyLabeling-Server provides a lightweight, extensible backend for connecting custom models and compute resources.
Key Features
- Unified support for annotating and processing text, image, video, point cloud, and multimodal data.
- Covers tasks such as 2D image classification, object detection, instance segmentation, pose estimation, oriented object detection, multi-object tracking, optical character recognition, lane annotation, image captioning, visual question answering, document parsing, and 3D point clouds.
- Provides polygons, rectangles, cuboids, rotated boxes, quadrilaterals, circles, lines, polylines, points, masks, and task-specific tools for text detection, text recognition, relation recognition, and KIE.
- Integrates a wide range of state-of-the-art deep learning models for AI-assisted annotation, automated labeling, and batch dataset prediction.
- Supports both local and remote inference through engines and serving frameworks such as
ONNX Runtime,TensorRT,OpenCV DNN,vLLM, andSGLang. - Supports importing and exporting formats such as
COCO,VOC,YOLO,DOTA,MOT,MASK,PPOCR,MMGD,VLM-R1, andShareGPT. - Runs on Windows, Linux, and macOS, with interfaces available in English, Simplified Chinese, Japanese, and Korean.
- Supports custom model integration, flexible extension, and secondary development.
Model library
| Task Category | Supported Models |
|---|---|
| 🖼️ Image Classification | YOLOv5-Cls, YOLOv8-Cls, YOLO11-Cls, InternImage, PULC |
| 🎯 Object Detection | YOLOv5/6/7/8/9/10, YOLO11/12/26, YOLOX, YOLO-NAS, D-FINE, DAMO-YOLO, Gold_YOLO, RT-DETR, RF-DETR, DEIMv2 |
| 🖌️ Instance Segmentation | YOLOv5-Seg, YOLOv8-Seg, YOLO11-Seg, YOLO26-Seg, Hyper-YOLO-Seg, RF-DETR-Seg, D-FINE-seg |
| 🎨 Semantic Segmentation | U-Net |
| 🏃 Pose Estimation | YOLOv8-Pose, YOLO11-Pose, YOLO26-Pose, DWPose, RTMO |
| 😀 Face Estimation | SCRFD, YOLOv6Lite-Face |
| 👣 Tracking | TrackTrack, Bot-SORT, ByteTrack, SAM2/3-Video |
| 🔄 Rotated Object Detection | YOLOv5-Obb, YOLOv8-Obb, YOLO11-Obb, YOLO26-Obb, RT-DETRv2-OBB |
| 📏 Depth Estimation | DepthAnything 1/2 |
| 🔗 Relation Recognition | RelateAnything |
| 🧩 Segment Anything | SAM 1/2/3, SAM-HQ, SAM-Med2D, EdgeSAM, EfficientViT-SAM, MobileSAM |
| ✂️ Image Matting | RMBG 1.4/2.0 |
| 💡 Proposal | UPN |
| 🏷️ Tagging | RAM, RAM++ |
| 📄 OCR | PP-OCRv4, PP-OCRv5, PP-OCRv6 |
| 🧾 Layout Analysis | PP-DocLayoutV3 |
| 📑 Document Parsing | PaddleOCR-VL, PaddleOCR-VL-1.6, Unlimited-OCR-2 |
| 🗣️ Vision Foundation Models | Rex-Omni, Florence2, LocateAnything, GroundingPI, GroundAnything, GroundAnything-VLM, Xiaomi-Lens-0, WeVisOne-VL |
| 👁️ Vision Language Models | Qwen3-VL, Gemini, ChatGPT, GLM |
| 🛣️ Lane Detection | CLRNet |
| 🔢 Object Counting | CountGD, GeCO, GeCo2 |
| 📍 Grounding | Grounding DINO, YOLO-World, YOLOE, SAM 3 |
| 📚 Other | 👉 model_zoo 👈 |
Docs
- Remote Inference Service
- Installation & Quickstart
- Usage
- Command Line Interface
- Customize a model
- Chatbot
- VQA
- Image Classifier
- Video Classifier
- Document Parser
- 3D Point Cloud Annotation
Examples
- Classification
- Detection
- Segmentation
- Description
- Estimation
- OCR
- Document Parsing
- MOT
- iVOS
- Matting
- Relation
- VFM
- Counting
- Grounding
- Training
Contribute
We believe in open collaboration! X‑AnyLabeling continues to grow with the support of the community. Whether you're fixing bugs, improving documentation, or adding new features, your contributions make a real impact.
To get started, please read our Contributing Guide and make sure to agree to the Contributor License Agreement (CLA) before submitting a pull request.
If you find this project helpful, please consider giving it a ⭐️ star! Have questions or suggestions? Open an issue or email us at [email protected].
A huge thank you 🙏 to everyone helping to make X‑AnyLabeling better.
License
This project is licensed under the GNU General Public License v3.0. You may use, modify, and redistribute the software, including for commercial purposes, provided that you comply with the terms of the license.
Sponsor
Your sponsorship supports X-AnyLabeling's feature development, model integration, documentation, and community maintenance.
Acknowledgement
I extend my heartfelt thanks to the developers and contributors of AnyLabeling, LabelMe, LabelImg, roLabelImg, PPOCRLabel and CVAT, whose work has been crucial to the success of this project.
Citing
If you use this software in your research, please cite it as below:
@misc{X-AnyLabeling,
  year = {2023},
  author = {Wei Wang},
  publisher = {Github},
  organization = {CVHub},
  journal = {Github repository},
  title = {X-AnyLabeling: A Unified Desktop Platform for AI-Assisted Data Annotation},
  howpublished = {\url{https://github.com/CVHub520/X-AnyLabeling}}
}
관련 프로젝트 살펴보기
tensorflow/tensorflow
모두를 위한 오픈소스 머신러닝 프레임워크
201,311 스타huggingface/transformers
🤗 Transformers: 텍스트, 비전, 오디오, 멀티모달 분야의 최첨단 머신러닝 모델을 위한 모델 정의 프레임워크로, 추론과 학습을 모두 지원합니다.
168,576 스타AUTOMATIC1111/stable-diffusion-webui
Stable Diffusion 웹 UI
165,264 스타Comfy-Org/ComfyUI
그래프와 노드로 구성된 인터페이스를 갖춘, 가장 강력하고 모듈성이 뛰어난 확산 모델 GUI, API, 백엔드입니다. 세계에서 가장 빠른 로컬 추론 엔진입니다.
145,310 스타