
rmst/ddpg
rmst/ddpg has 216 GitHub stars and 64 forks. GitHot measured 0 stars in 24 hours. Last checked 2026-11-19 15:22 UTC. Last push 2018-02-16.
实测星标增长
- 24小时
- 0
- 7天
- 正在收集历史
- 15天
- 正在收集历史
- 1个月
- 正在收集历史
各周期内的星标净变化,周期相互重叠,并非每日新增。缺失的测量保持空白。星标代表关注度,不代表软件质量。
关于
TensorFlow implementation of the DDPG algorithm from the paper Continuous Control with Deep Reinforcement Learning (ICLR 2016)
机器学习README.md
原文Deep Deterministic Policy Gradient
Warning: This repo is no longer maintained. For a more recent (and improved) implementation of DDPG see https://github.com/openai/baselines/tree/master/baselines/ddpg .
Paper: "Continuous control with deep reinforcement learning" - TP Lillicrap, JJ Hunt et al., 2015
 |
 |
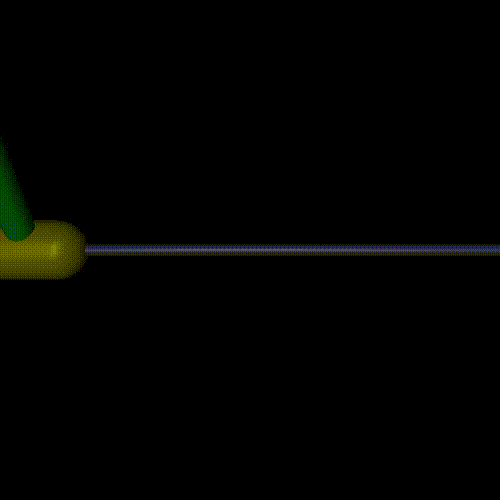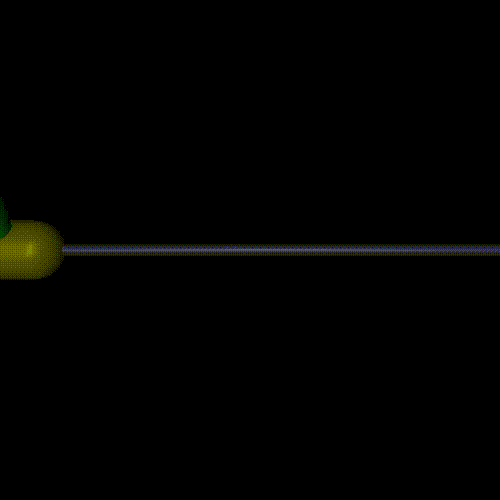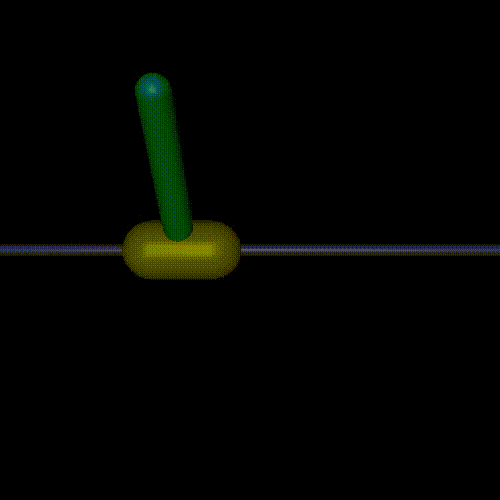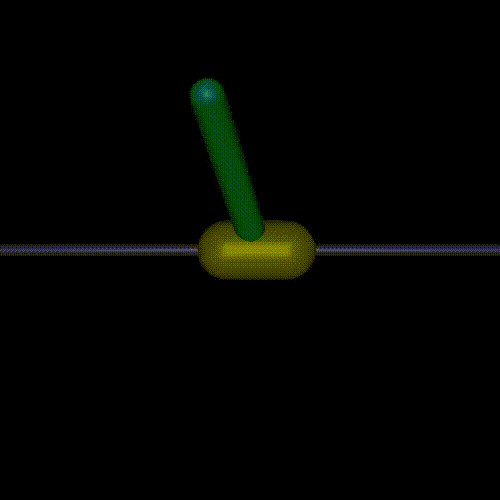 |
Installation
Install Gym and TensorFlow. Then:
pip install pyglet # required for gym rendering
pip install jupyter # required only for visualization (see below)

git clone https://github.com/SimonRamstedt/ddpg.git # get ddpg
Usage
Example:
python run.py --outdir ../ddpg-results/experiment1 --env InvertedDoublePendulum-v1
Enter python run.py -h to get a complete overview.
If you want to run in the cloud or a university cluster this might contain additional information.
Visualization
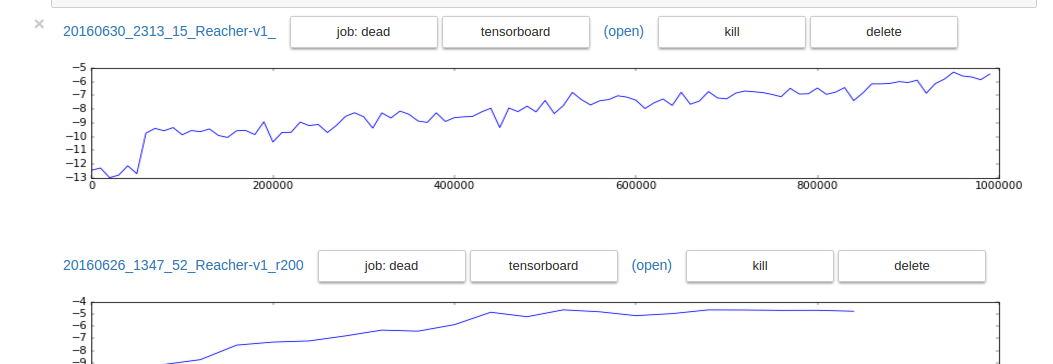
Example:
python dashboard.py --exdir ../ddpg-results/+
Enter python dashboard.py -h to get a complete overview.
Known issues
- No batch normalization yet
- No conv nets yet (i.e. only learning from low dimensional states)
- No proper seeding for reproducibilty
Please write me or open a github issue if you encounter problems! Contributions are welcome!
Improvements beyond the original paper
- Output normalization – the main reason for divergence are variations in return scales. Output normalization would probably solve this.
- Prioritized experience replay – faster learning, better performance especially with sparse rewards – Please write if you have/know of an implementation!
Advaned Usage
Remote execution:
python run.py --outdir [email protected]:/some/remote/directory/+ --env InvertedDoublePendulum-v1