
pathwaycom/arc-task-gen
pathwaycom/arc-task-gen has 10,883 GitHub stars and 76 forks. GitHot measured -4 stars in 24 hours and -19 in 7 days. Last checked 2026-11-14 00:28 UTC. Last push 2026-08-11.
实测星标增长
- 24小时
- -4
- 7天
- -19
- 15天
- 正在收集历史
- 1个月
- 正在收集历史
各周期内的星标净变化,周期相互重叠,并非每日新增。缺失的测量保持空白。星标代表关注度,不代表软件质量。
关于
Generates original ARC-AGI-1-style tasks distribution-matched to the public eval set.
开发工具README.md
原文ARC-AGI-1 Task Generator
Distribution-Matched Tasks for Model Evaluation
This repository generates fresh ARC-AGI-1-style tasks that resemble the public dataset. These tasks can be used to evaluate frontier models such as BDH-CQ on problems they are unlikely to have encountered before.
Overview
BDH-CQ is a reasoning model that combines in-context learning through evolving recurrent memory with iterative reasoning in a structured, continuous latent space.
It builds on Dragon Hatchling (BDH), a post-Transformer recurrent architecture in which neuron-like units communicate through low-rank interactions and maintain context in an evolving associative state. BDH-CQ extends this architecture: at inference time, its recurrent memory is continuously updated, and queries are solved through iterative computation in latent space rather than by generating an intermediate, text-based chain of thought.
We evaluate BDH-CQ on the public ARC-AGI-1 evaluation set and use controlled ARC-like interventions to study what the model learns from demonstrations.
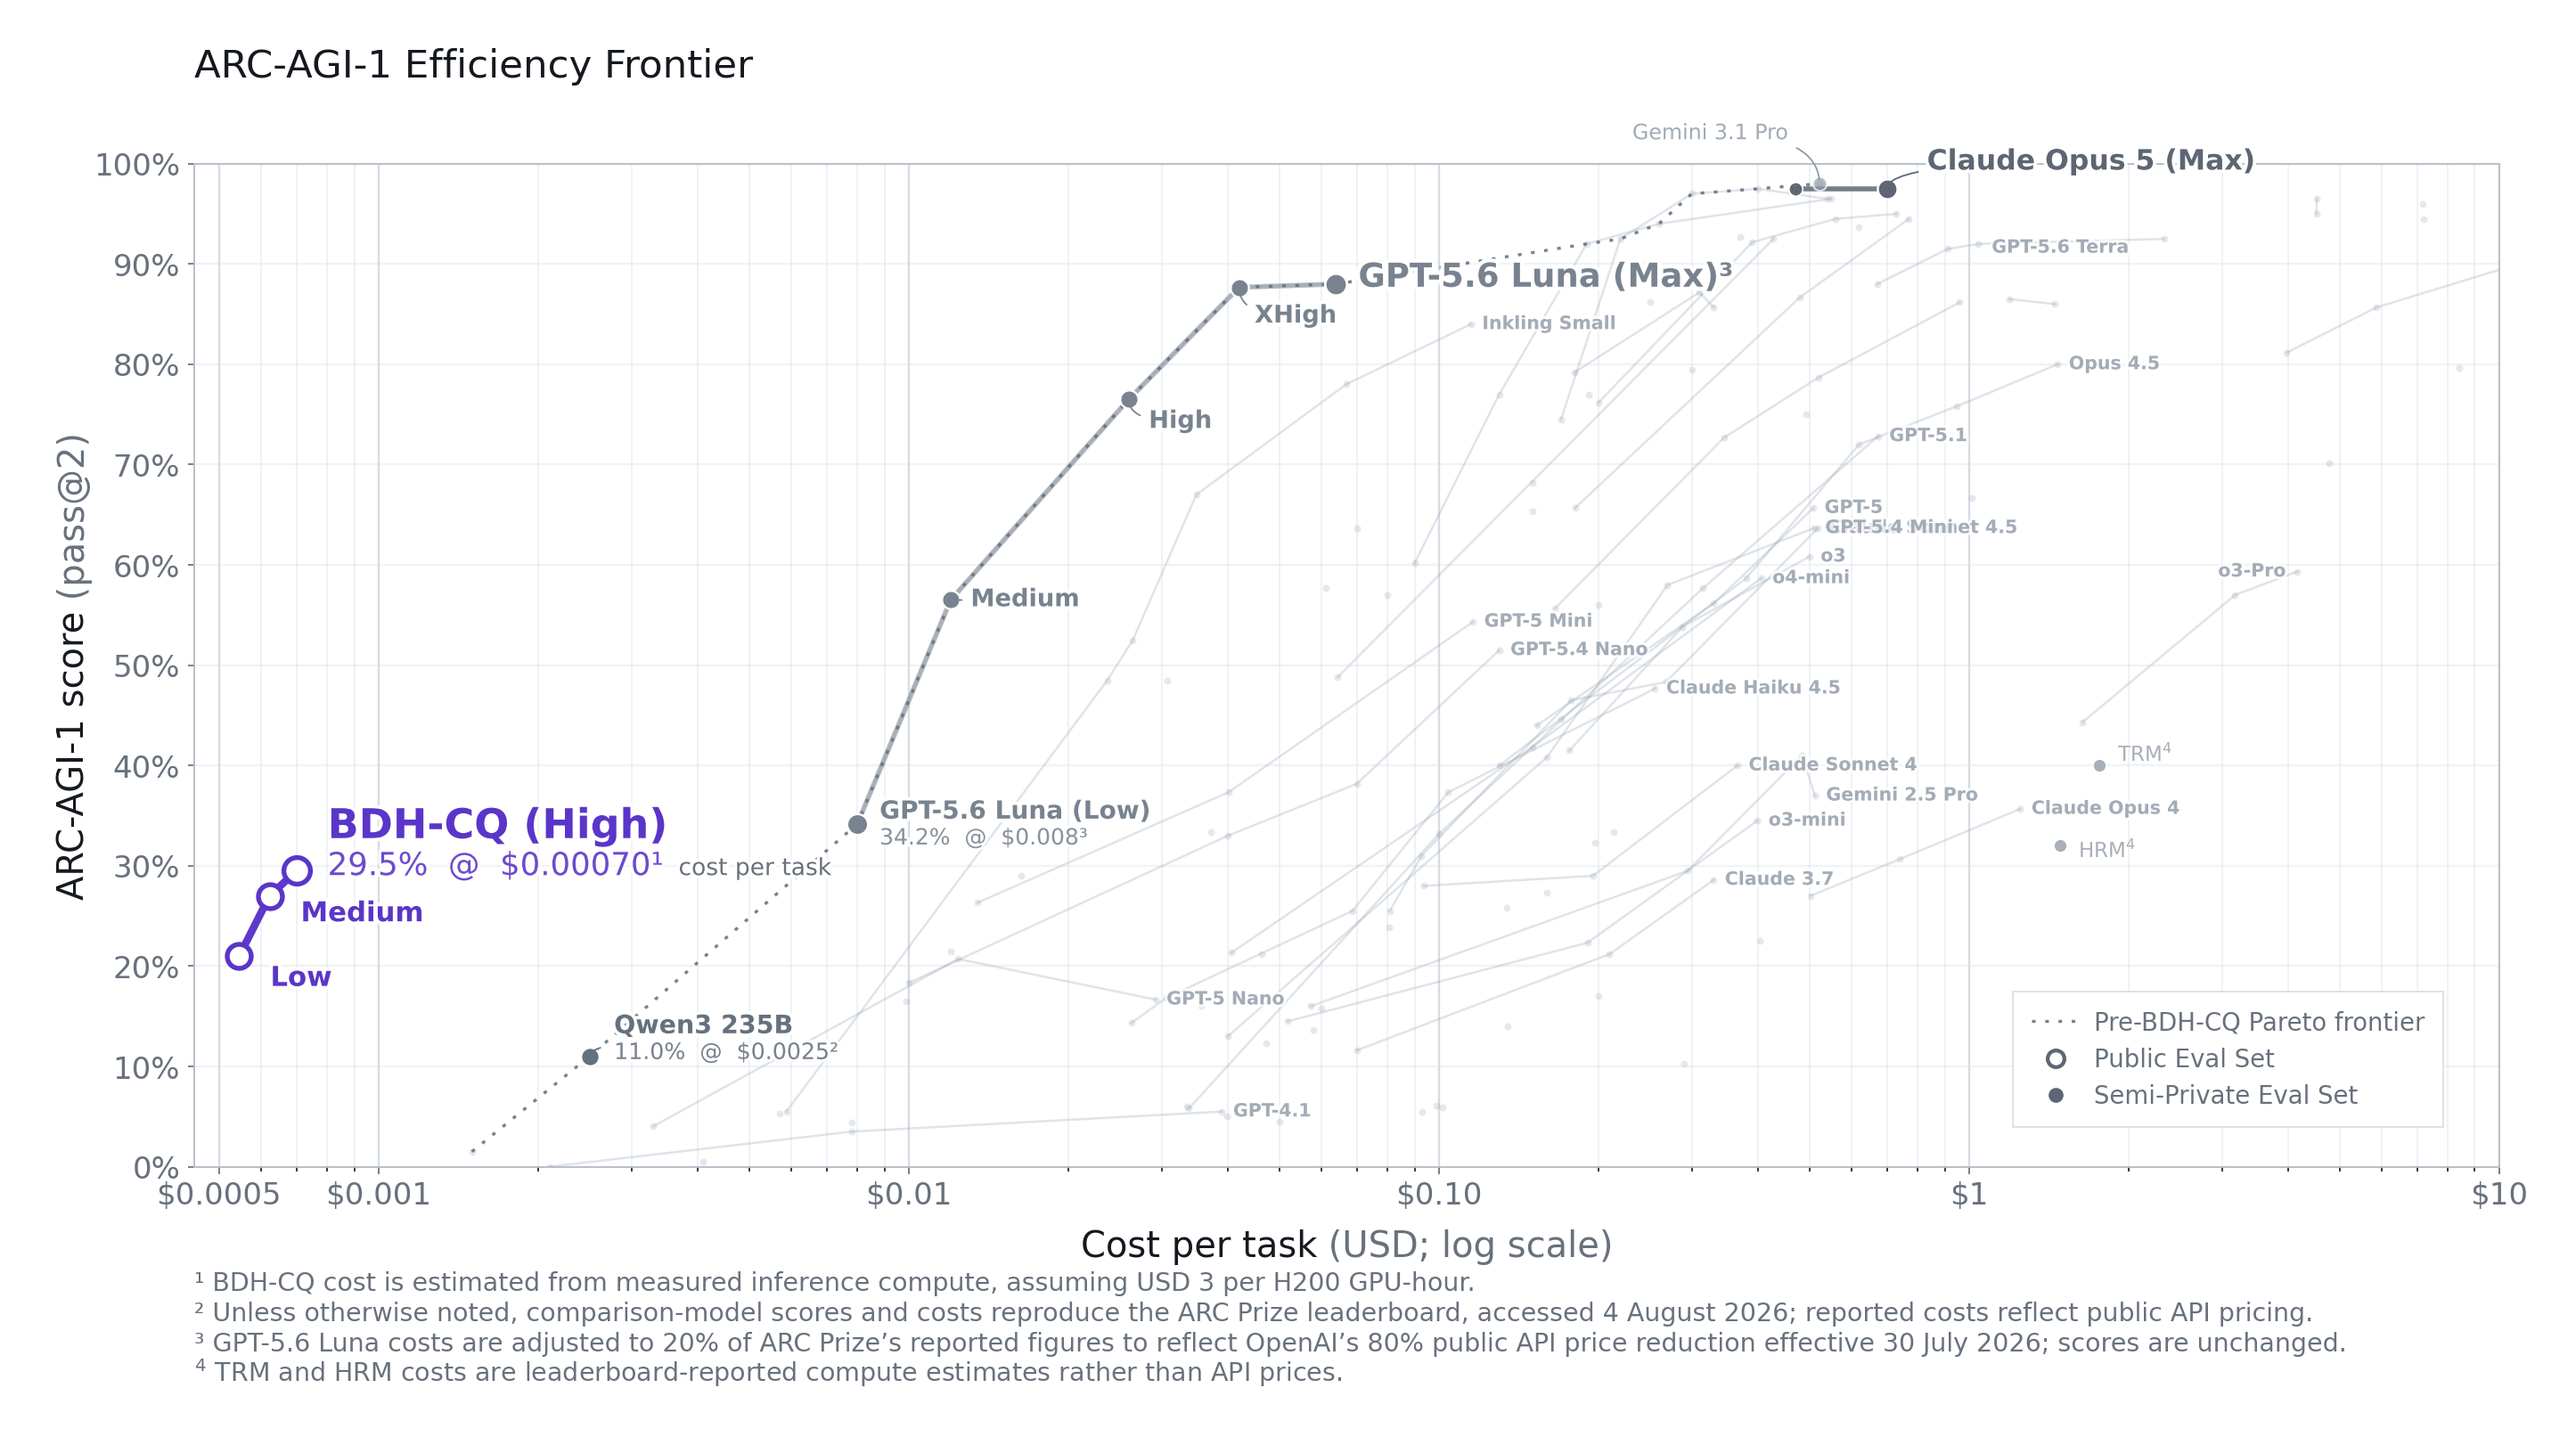
A 150M-parameter configuration achieves 29.5% pass@2 on the public ARC-AGI-1 evaluation set at a computed inference cost of $0.0007 per task. This is 11× cheaper per task than GPT-5.6 Luna (Low), following an 80% price reduction on July 30.
The architecture has also been tested in pretraining experiments ranging from 1B to 600B parameters, demonstrating Transformer-like scaling while retaining BDH-CQ's recurrent latent-reasoning capabilities.
Paper and Blog Post
This repository accompanies the following paper:
B. Engdahl, A. Kosowski, J. Chorowski, Z. Stamirowska, P. Uznański, J. Jiang, R. Phadke, R. Kinas, and R. Zhong. BDH-CQ: Introducing In-Context Learning with Recurrent Latent Reasoning.
For a broader introduction and discussion, read the accompanying blog post.
ARC-AGI-1 Efficiency Frontier
What You'll Find in This Repository
As a public benchmark, ARC-AGI-1 cannot fully isolate few-shot rule induction from potential prior familiarity with its tasks.
To provide a complementary measure, arc-task-gen creates a private evaluation set with similar properties, enabling meaningful comparisons between public-benchmark performance and performance on newly generated tasks.
The generated tasks.json file follows the standard ARC format:
{
  "train": [],
  "test": []
}
It is compatible with existing ARC evaluation harnesses.
Follow the instructions in instructions.md to start generating tasks.
Independent Reproduction
BDH-CQ's ARC-AGI-1 results were evaluated and reproduced by Łukasz Kaiser, a co-author of the Transformer architecture and TensorFlow.
The results were also independently reproduced by Remigiusz Kinas, a contributor to Bielik, and Richard Zhong, an NYU researcher. Their work focused on model evaluation and benchmark robustness.