
noahshinn/reflexion
noahshinn/reflexion has 3,414 GitHub stars and 337 forks. GitHot measured +2 stars in 24 hours and +30 in 7 days. Last checked 2026-11-08 17:38 UTC. Last push 2025-01-14.
[NeurIPS 2023] Reflexion:采用语言反馈强化学习的语言智能体
实测星标增长
- 24小时
- +2
- 7天
- +30
- 15天
- 正在收集历史
- 1个月
- 正在收集历史
各周期内的星标净变化,周期相互重叠,并非每日新增。缺失的测量保持空白。星标代表关注度,不代表软件质量。
README.md
原文[NeurIPS 2023] Reflexion: Language Agents with Verbal Reinforcement Learning
This repo holds the code, demos, and log files for Reflexion: Language Agents with Verbal Reinforcement Learning by Noah Shinn, Federico Cassano, Edward Berman, Ashwin Gopinath, Karthik Narasimhan, Shunyu Yao.
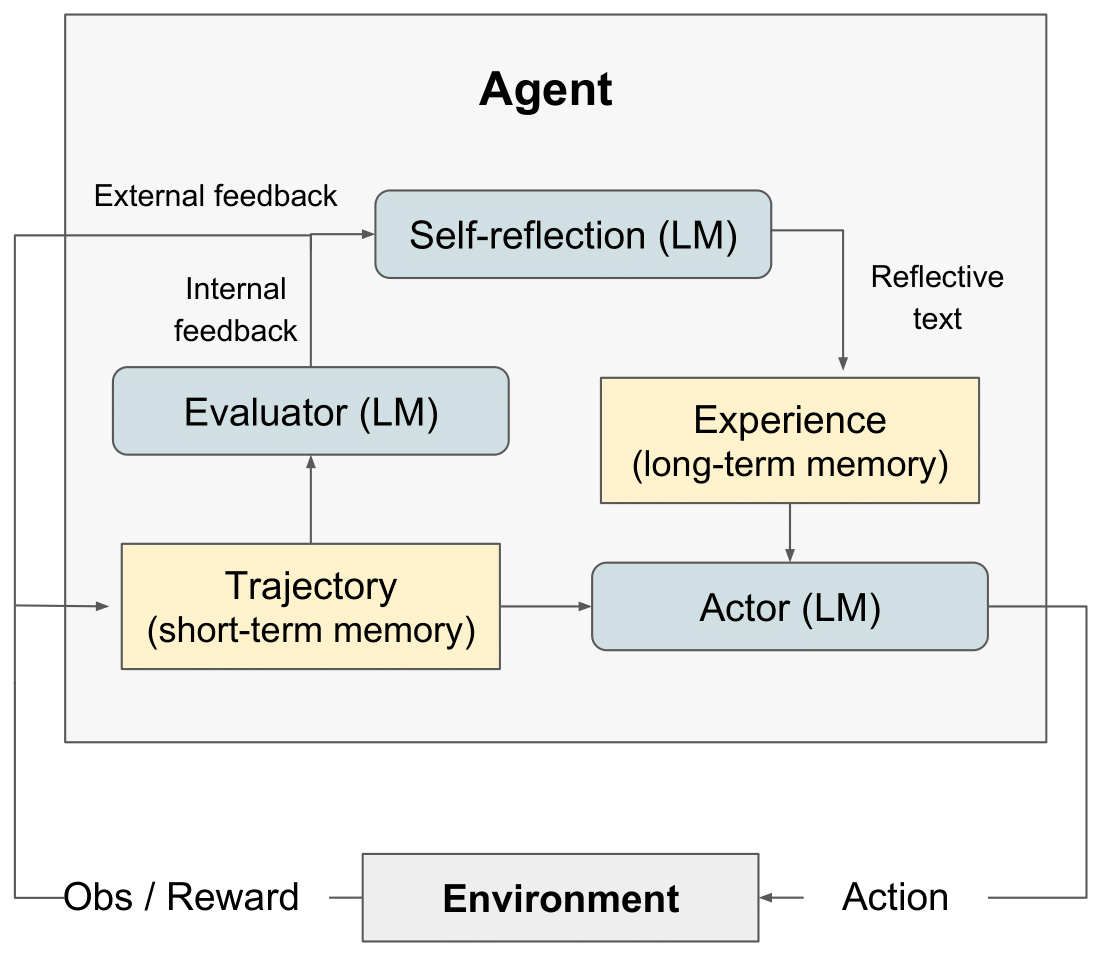
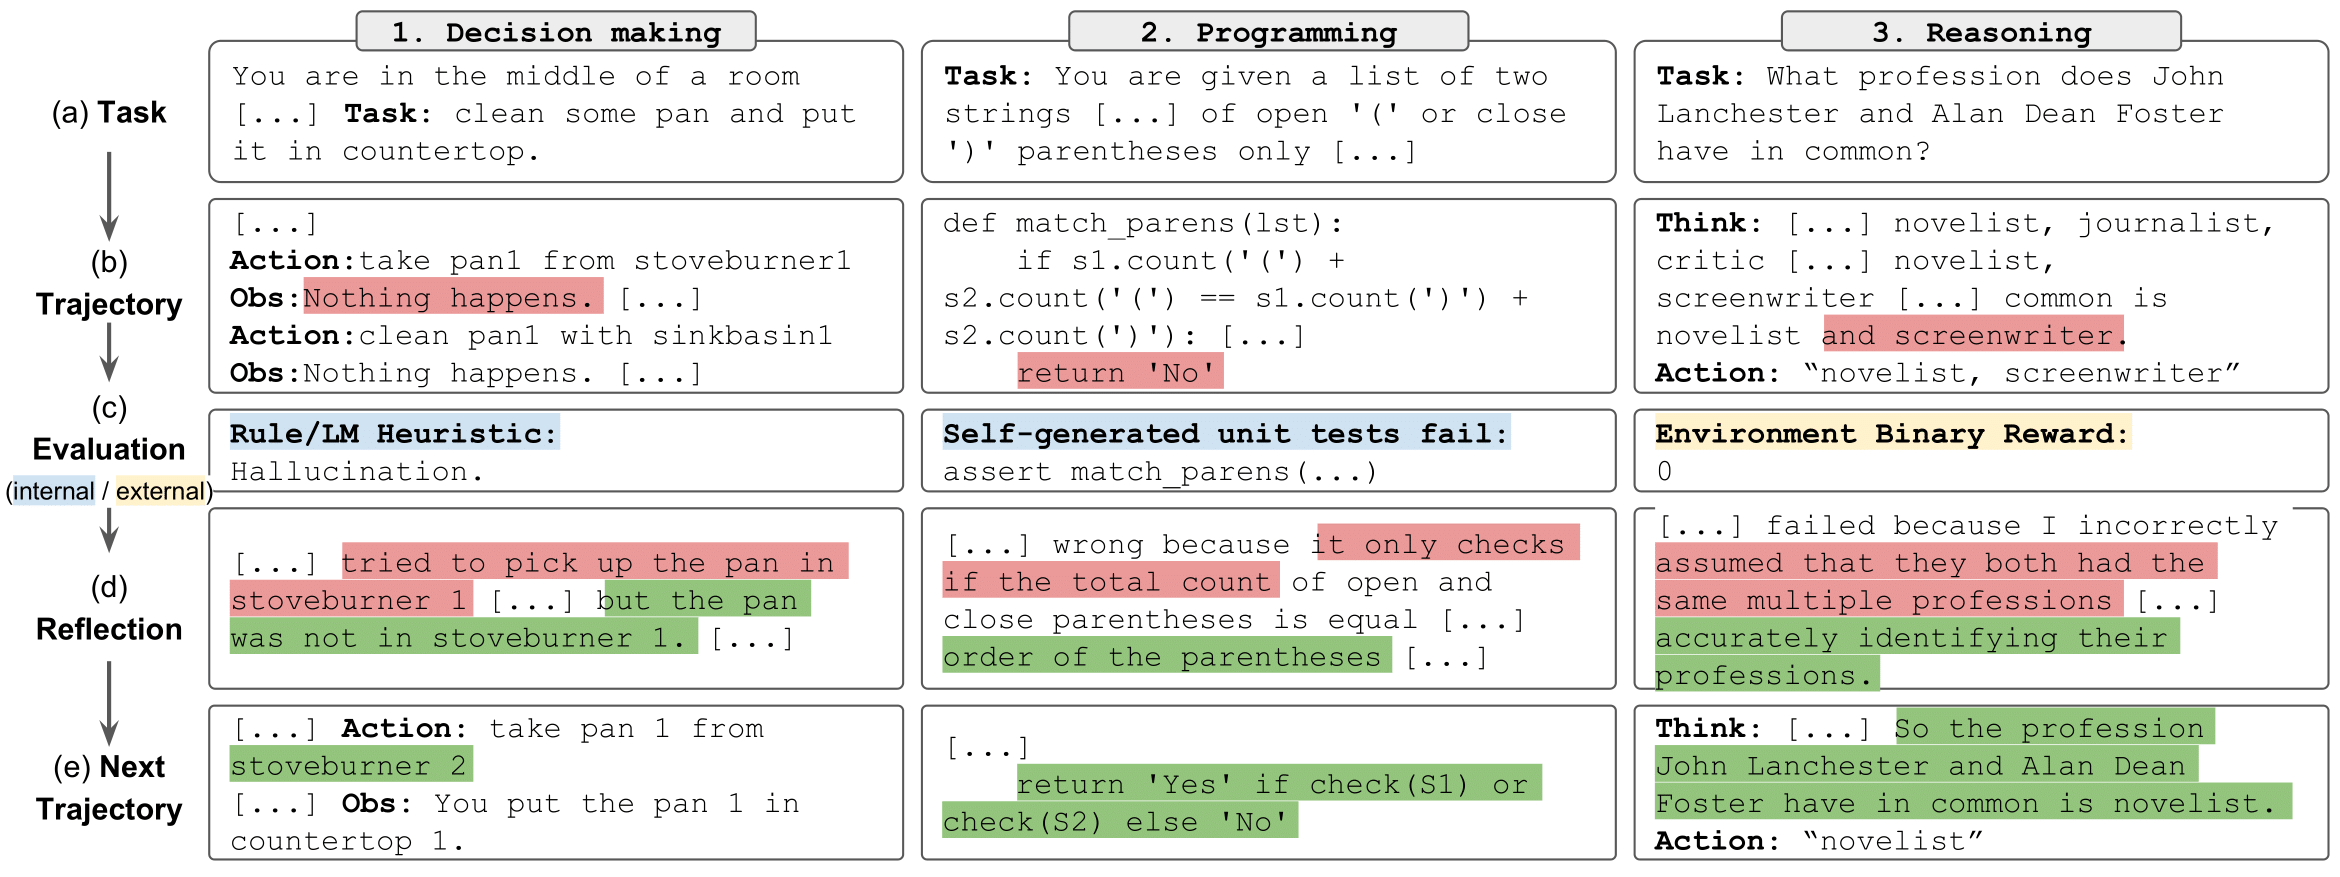
We have released the LeetcodeHardGym here
To Run: reasoning (HotPotQA)
We have provided a set of notebooks to easily run, explore, and interact with the results of the reasoning experiments. Each experiment consists of a random sample of 100 questions from the HotPotQA distractor dataset. Each question in the sample is attempted by an agent with a specific type and reflexion strategy.
Setup
To get started:
- Clone this repo and move to the HotPotQA directory:
git clone https://github.com/noahshinn/reflexion && cd ./hotpotqa_runs
- Install the module dependencies into your environment:
pip install -r requirements.txt
- Set
OPENAI_API_KEYenvironment variable to your OpenAI API key:
export OPENAI_API_KEY=<your key>
Agent Types
Agent type is determined by the notebook you choose to run. The available agent types include:
ReAct- ReAct AgentCoT_context- CoT Agent given supporting context about the questionCoT_no_context- CoT Agent given no supporting context about the question
The notebook for each agent type is located in the ./hotpot_runs/notebooks directory.
Reflexion Strategies
Each notebook allows you to specify the reflexion strategy to be used by the agents. The available reflexion strategies, which are defined in an Enum, include:
ReflexionStrategy.NONE- The agent is not given any information about its last attempt.ReflexionStrategy.LAST_ATTEMPT- The agent is given its reasoning trace from its last attempt on the question as context.ReflexionStrategy.REFLEXION- The agent is given its self-reflection on the last attempt as context.ReflexionStrategy.LAST_ATTEMPT_AND_REFLEXION- The agent is given both its reasoning trace and self-reflection on the last attempt as context.
To Run: decision-making (AlfWorld)
Clone this repo and move to the AlfWorld directory
git clone https://github.com/noahshinn/reflexion && cd ./alfworld_runs
Specify the run parameters in ./run_reflexion.sh.
num_trials: number of iterative learning steps
num_envs: number of task-environment pairs per trial
run_name: the name for this run
use_memory: use persisting memory to store self-reflections (turn off to run a baseline run)
is_resume: use logging directory to resume a previous run
resume_dir: the logging directory from which to resume the previous run
start_trial_num: if resume run, then the trial number of which to start
Run the trial
./run_reflexion.sh
The logs will be sent to ./root/<run_name>.
Another Note
Due to the nature of these experiments, it may not be feasible for individual developers to rerun the results as GPT-4 has limited access and significant API charges. All runs from the paper and additional results are logged in ./alfworld_runs/root for decision-making, ./hotpotqa_runs/root for reasoning, and ./programming_runs/root for programming
Other Notes
Check out the original implementation here
Read one of the original blog posts here
Check out an Appl implementation here.
Check out an interesting type-prediction implementation here: OpenTau
For all questions, contact [email protected]
Cite
@misc{shinn2023reflexion,
      title={Reflexion: Language Agents with Verbal Reinforcement Learning},
      author={Noah Shinn and Federico Cassano and Edward Berman and Ashwin Gopinath and Karthik Narasimhan and Shunyu Yao},
      year={2023},
      eprint={2303.11366},
      archivePrefix={arXiv},
      primaryClass={cs.AI}
}
探索相关项目
affaan-m/ECC
智能体执行与控制框架的性能优化系统。面向 Claude Code、Codex、Opencode、Cursor 等,涵盖技能、本能、记忆、安全与研究优先的开发。
299,558 星标NousResearch/hermes-agent
与你一同成长的智能体
261,686 星标multica-ai/andrej-karpathy-skills
一个用于改进 Claude Code 行为的 CLAUDE.md 文件,源自 Andrej Karpathy 对 LLM 编程陷阱的观察。
230,859 星标firecrawl/firecrawl
借助来自网络及其他来源的数据,强化你的 AI 智能体。正在构建面向超级智能的资料库。🔥
199,551 星标