
kan-bayashi/PytorchWaveNetVocoder
kan-bayashi/PytorchWaveNetVocoder has 301 GitHub stars and 58 forks. GitHot measured 0 stars in 24 hours and 0 in 7 days. Last checked 2026-11-22 00:46 UTC. Last push 2020-06-08.
可以做什么
- Support kaldi-like recipe, easy to reproduce the results
- Support multi-gpu training / decoding
- Support world features / mel-spectrogram as auxiliary features
- CMU Arctic database: egs/arctic
实测星标增长
- 24小时
- 0
- 7天
- 0
- 15天
- 正在收集历史
- 1个月
- 正在收集历史
各周期内的星标净变化,周期相互重叠,并非每日新增。缺失的测量保持空白。星标代表关注度,不代表软件质量。
关于
WaveNet-Vocoder implementation with pytorch.
机器学习README.md
原文I released new implementation kan-bayashi/ParallelWaveGAN. Please enjoy your hacking!
PYTORCH-WAVENET-VOCODER

This repository is the wavenet-vocoder implementation with pytorch.
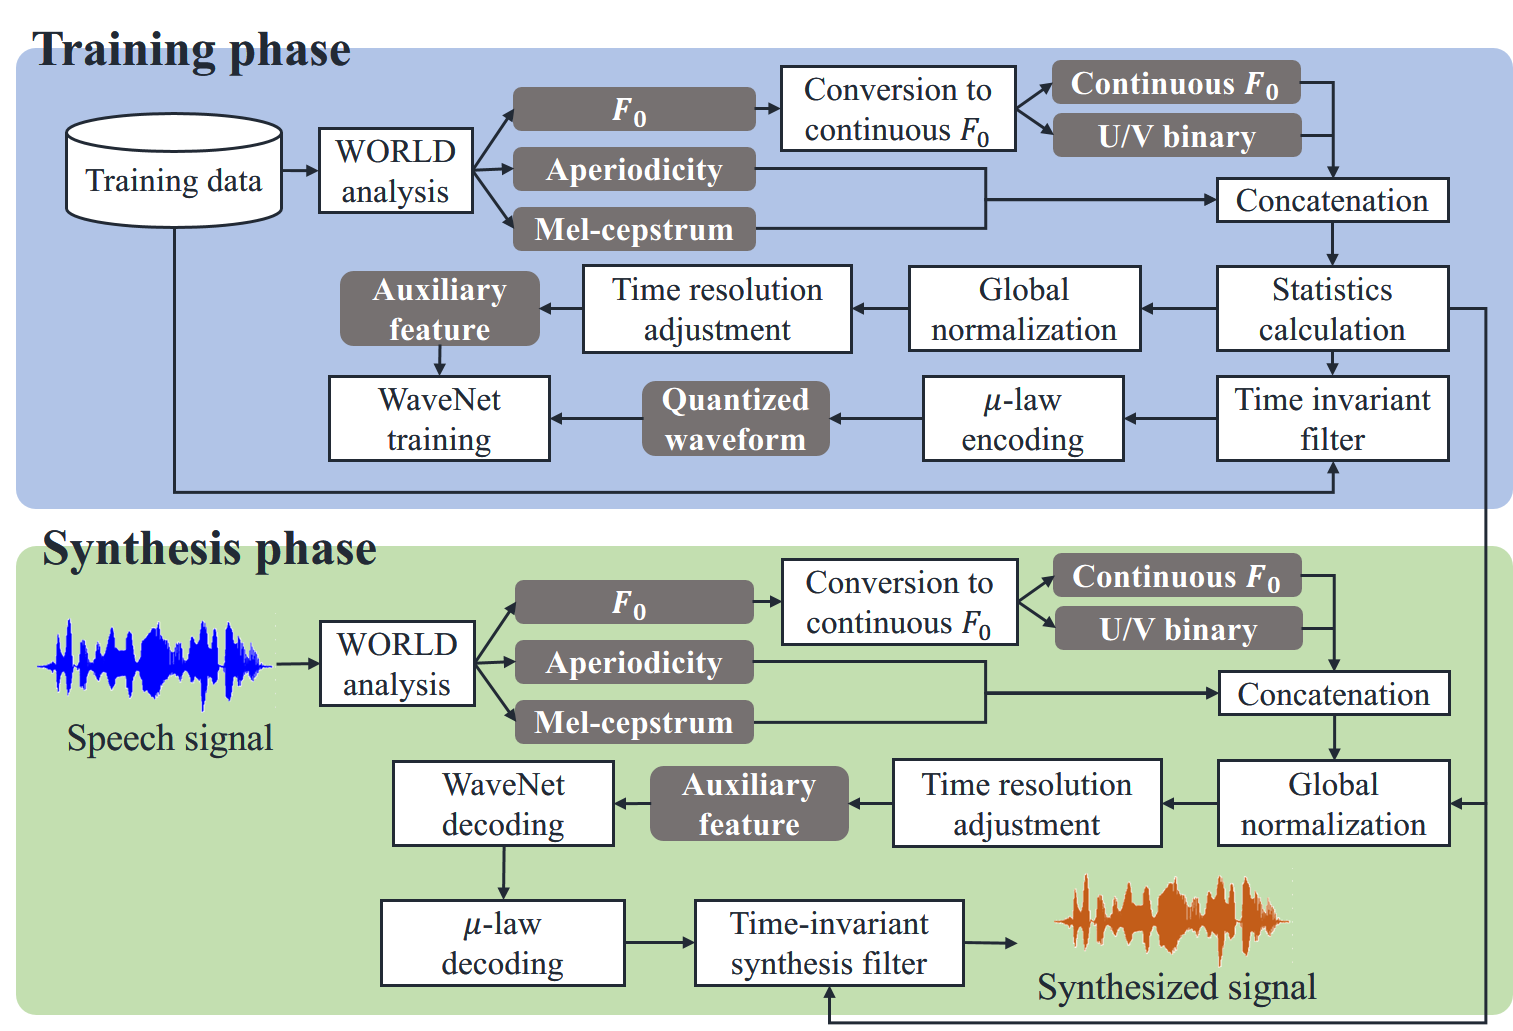
You can try the demo recipe in Google colab from now!

Key features
Support kaldi-like recipe, easy to reproduce the results
Support multi-gpu training / decoding
Support world features / mel-spectrogram as auxiliary features
Support recipes of three public databases
- CMU Arctic database:
egs/arctic - LJ Speech database:
egs/ljspeech - M-AILABS speech database:
egs/m-ailabs-speech
- CMU Arctic database:
Requirements
- python 3.6+
- virtualenv
- cuda 9.0+
- cndnn 7.1+
- nccl 2.0+ (for the use of multi-gpus)
Recommend to use the GPU with 10GB> memory.
Setup
A. Make virtualenv
$ git clone https://github.com/kan-bayashi/PytorchWaveNetVocoder.git
$ cd PytorchWaveNetVocoder/tools
$ make
B. Install with pip
$ git clone https://github.com/kan-bayashi/PytorchWaveNetVocoder.git
$ cd PytorchWaveNetVocoder

# recommend to use with pytorch 1.0.1 because only tested on 1.0.1
$ pip install torch==1.0.1 torchvision==0.2.2
$ pip install -e .

# please make dummy activate file to suppress warning in the recipe
$ mkdir -p tools/venv/bin && touch tools/venv/bin/activate
How-to-run
$ cd egs/arctic/sd
$ ./run.sh
See more detail of the recipes in egs/README.md.
Results
You can listen to samples from kan-bayashi/WaveNetVocoderSamples.
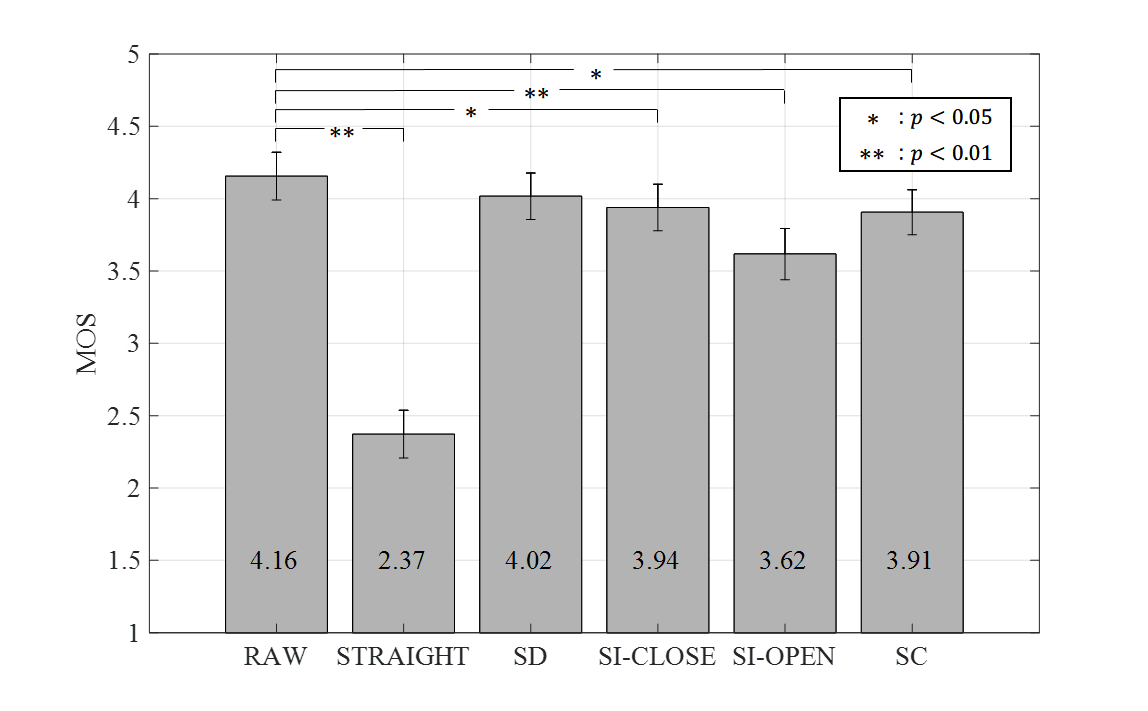
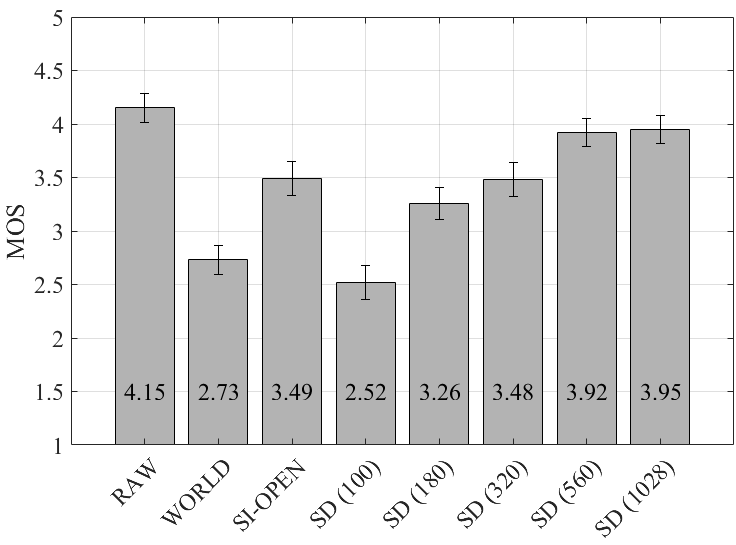
This is the subjective evaluation results using arctic recipe.
Comparison between model type
Effect of the amount of training data
If you want to listen more samples, please access our google drive from here.
Here is the list of samples:
arctic_raw_16k: original in arctic databasearctic_sd_16k_world: sd model with world aux feats + noise shaping with world mceparctic_si-open_16k_world: si-open model with world aux feats + noise shaping with world mceparctic_si-close_16k_world: si-close model with world aux feats + noise shaping with world mceparctic_si-close_16k_melspc: si-close model with mel-spectrogram aux featsarctic_si-close_16k_melspc_ns: si-close model with mel-spectrogram aux feats + noise shaping with stft mcepljspeech_raw_22.05k: original in ljspeech databaseljspeech_sd_22.05k_world: sd model with world aux feats + noise shaping with world mcepljspeech_sd_22.05k_melspc: sd model with mel-spectrogram aux featsljspeech_sd_22.05k_melspc_ns: sd model with mel-spectrogram aux feats + noise shaping with stft mcepm-ailabs_raw_16k: original in m-ailabs speech databasem-ailabs_sd_16k_melspc: sd model with mel-spectrogram aux feats
References
Please cite the following articles.
@inproceedings{tamamori2017speaker,
  title={Speaker-dependent WaveNet vocoder},
  author={Tamamori, Akira and Hayashi, Tomoki and Kobayashi, Kazuhiro and Takeda, Kazuya and Toda, Tomoki},
  booktitle={Proceedings of Interspeech},
  pages={1118--1122},
  year={2017}
}
@inproceedings{hayashi2017multi,
  title={An Investigation of Multi-Speaker Training for WaveNet Vocoder},
  author={Hayashi, Tomoki and Tamamori, Akira and Kobayashi, Kazuhiro and Takeda, Kazuya and Toda, Tomoki},
  booktitle={Proc. ASRU 2017},
  year={2017}
}
@article{hayashi2018sp,
  title={複数話者WaveNetボコーダに関する調査}.
  author={林知樹 and 小林和弘 and 玉森聡 and 武田一哉 and 戸田智基},
  journal={電子情報通信学会技術研究報告},
  year={2018}
}
Author
Tomoki Hayashi @ Nagoya University
e-mail:[email protected]
探索相关项目
加载中…