
fundamentalvision/BEVFormer
fundamentalvision/BEVFormer has 4,644 GitHub stars and 755 forks. GitHot measured 0 stars in 24 hours and +5 in 7 days. Last checked 2026-11-08 00:09 UTC. Last push 2024-08-15.
[ECCV 2022] 这是 BEVFormer 的官方实现。BEVFormer 是一个仅基于摄像头的自动驾驶感知框架,支持 3D 目标检测和语义地图分割等任务。
实测星标增长
- 24小时
- 0
- 7天
- +5
- 15天
- 更新延迟
- 1个月
- 更新延迟
各周期内的星标净变化,周期相互重叠,并非每日新增。缺失的测量保持空白。星标代表关注度,不代表软件质量。
README.md
原文BEVFormer: a Cutting-edge Baseline for Camera-based Detection
BEVFormer: Learning Bird's-Eye-View Representation from Multi-Camera Images via Spatiotemporal Transformers, ECCV 2022
- Paper in arXiv | Paper in Chinese | OpenDriveLab
- Slides in English | Occupancy and BEV Perception Talk Slides
- Blog in Chinese | Video Talk and Slides (in Chinese)
- BEV Perception Survey (Accepted by PAMI) | Github repo
News
- [2022/6/16]: We added two BEVformer configurations, which require less GPU memory than the base version. Please pull this repo to obtain the latest codes.
- [2022/6/13]: We release an initial version of BEVFormer. It achieves a baseline result of 51.7% NDS on nuScenes.
- [2022/5/23]: 🚀🚀Built on top of BEVFormer, BEVFormer++, gathering up all best practices in recent SOTAs and our unique modification, ranks 1st on Waymo Open Datast 3D Camera-Only Detection Challenge. We will present BEVFormer++ on CVPR 2022 Autonomous Driving Workshop.
- [2022/3/10]: 🚀BEVFormer achieve the SOTA on nuScenes Detection Task with 56.9% NDS (camera-only)!
Abstract
In this work, the authors present a new framework termed BEVFormer, which learns unified BEV representations with spatiotemporal transformers to support multiple autonomous driving perception tasks. In a nutshell, BEVFormer exploits both spatial and temporal information by interacting with spatial and temporal space through predefined grid-shaped BEV queries. To aggregate spatial information, the authors design a spatial cross-attention that each BEV query extracts the spatial features from the regions of interest across camera views. For temporal information, the authors propose a temporal self-attention to recurrently fuse the history BEV information. The proposed approach achieves the new state-of-the-art 56.9% in terms of NDS metric on the nuScenes test set, which is 9.0 points higher than previous best arts and on par with the performance of LiDAR-based baselines.
Methods
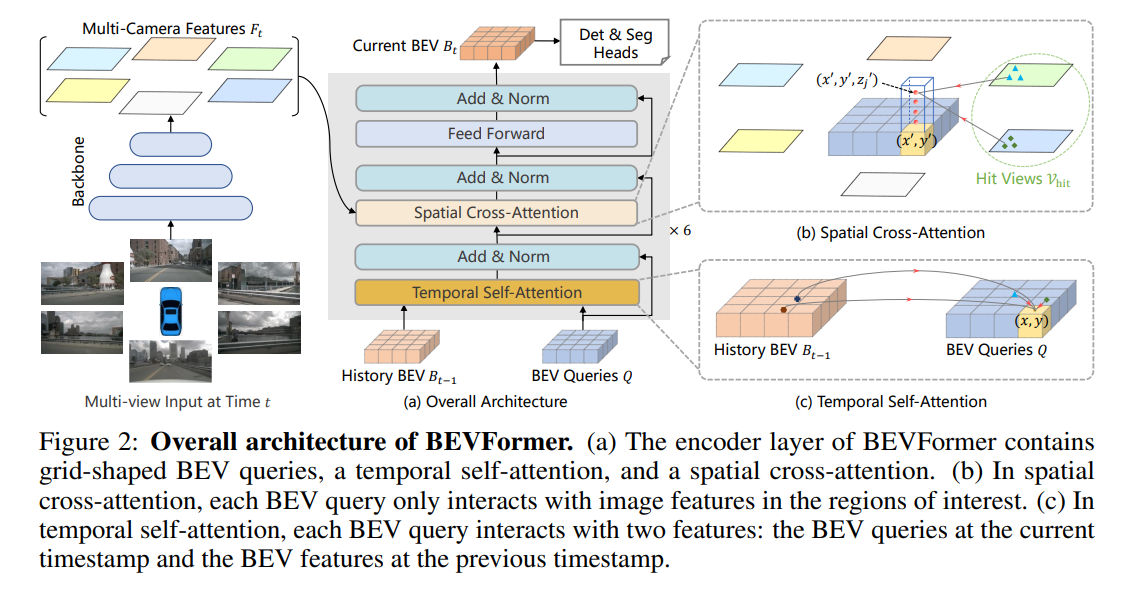
Getting Started
Model Zoo
| Backbone | Method | Lr Schd | NDS | mAP | memroy | Config | Download |
|---|---|---|---|---|---|---|---|
| R50 | BEVFormer-tiny_fp16 | 24ep | 35.9 | 25.7 | - | config | model/log |
| R50 | BEVFormer-tiny | 24ep | 35.4 | 25.2 | 6500M | config | model/log |
| R101-DCN | BEVFormer-small | 24ep | 47.9 | 37.0 | 10500M | config | model/log |
| R101-DCN | BEVFormer-base | 24ep | 51.7 | 41.6 | 28500M | config | model/log |
| R50 | BEVformerV2-t1-base | 24ep | 42.6 | 35.1 | 23952M | config | model/log |
| R50 | BEVformerV2-t1-base | 48ep | 43.9 | 35.9 | 23952M | config | model/log |
| R50 | BEVformerV2-t1 | 24ep | 45.3 | 38.1 | 37579M | config | model/log |
| R50 | BEVformerV2-t1 | 48ep | 46.5 | 39.5 | 37579M | config | model/log |
| R50 | BEVformerV2-t2 | 24ep | 51.8 | 42.0 | 38954M | config | model/log |
| R50 | BEVformerV2-t2 | 48ep | 52.6 | 43.1 | 38954M | config | model/log |
| R50 | BEVformerV2-t8 | 24ep | 55.3 | 46.0 | 40392M | config | model/log |
The Baidu Driver Link for (BEVFormerV2 model and log)[https://pan.baidu.com/s/1ynzlAt1DQbH8NkqmisatTw?pwd=fdcv] is here.
Catalog
- BEVFormerV2 HyperQuery
- BEVFormerV2 Optimization, including memory, speed, inference.
- BEVFormerV2 Release
- BEV Segmentation checkpoints
- BEV Segmentation code
- 3D Detection checkpoints
- 3D Detection code
- Initialization
Bibtex
If this work is helpful for your research, please consider citing the following BibTeX entry.
@article{li2022bevformer,
  title={BEVFormer: Learning Bird’s-Eye-View Representation from Multi-Camera Images via Spatiotemporal Transformers},
  author={Li, Zhiqi and Wang, Wenhai and Li, Hongyang and Xie, Enze and Sima, Chonghao and Lu, Tong and Qiao, Yu and Dai, Jifeng}
  journal={arXiv preprint arXiv:2203.17270},
  year={2022}
}
@article{Yang2022BEVFormerVA,
  title={BEVFormer v2: Adapting Modern Image Backbones to Bird's-Eye-View Recognition via Perspective Supervision},
  author={Chenyu Yang and Yuntao Chen and Haofei Tian and Chenxin Tao and Xizhou Zhu and Zhaoxiang Zhang and Gao Huang and Hongyang Li and Y. Qiao and Lewei Lu and Jie Zhou and Jifeng Dai},
  journal={ArXiv},
  year={2022},
}
Acknowledgement
Many thanks to these excellent open source projects: