
acolyte
cchantep
65stars
:tiger: Mockup/testing JDBC & MongoDB driver (or Chmeee's son on the Ringworld).
Store, explore, and understand your data.
cchantep
:tiger: Mockup/testing JDBC & MongoDB driver (or Chmeee's son on the Ringworld).

Cedar-Cat-Studios
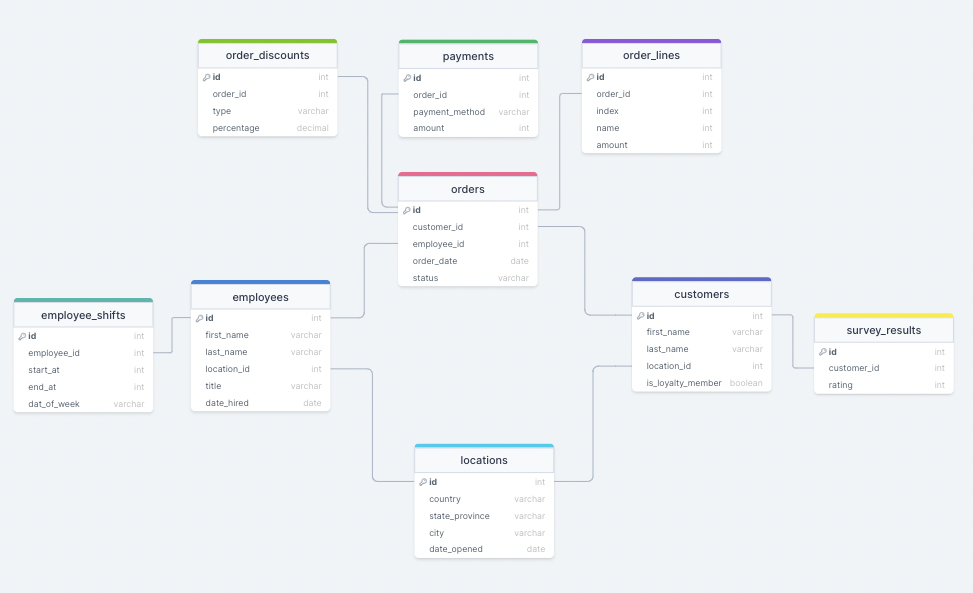
QUERY; The daily SQL video game. This repo acts as the open source project for developer and community contributions

center-for-threat-informed-defense
Cloud Analytics helps defenders detect attacks to their cloud infrastructure by developing behavioral analytics for cloud platforms as well as a blueprint for how others can create and use cloud analytics effectively.

centreon
Centreon is a network, system and application monitoring tool. Centreon is the only AIOps Platform Providing Holistic Visibility to Complex IT Workflows from Cloud to Edge.

cggh
Eyes on your (genomic) data

cgnl
Run Plex Media Server with PostgreSQL instead of SQLite

chaconnewu

Free resources for learning data science

change-metrics
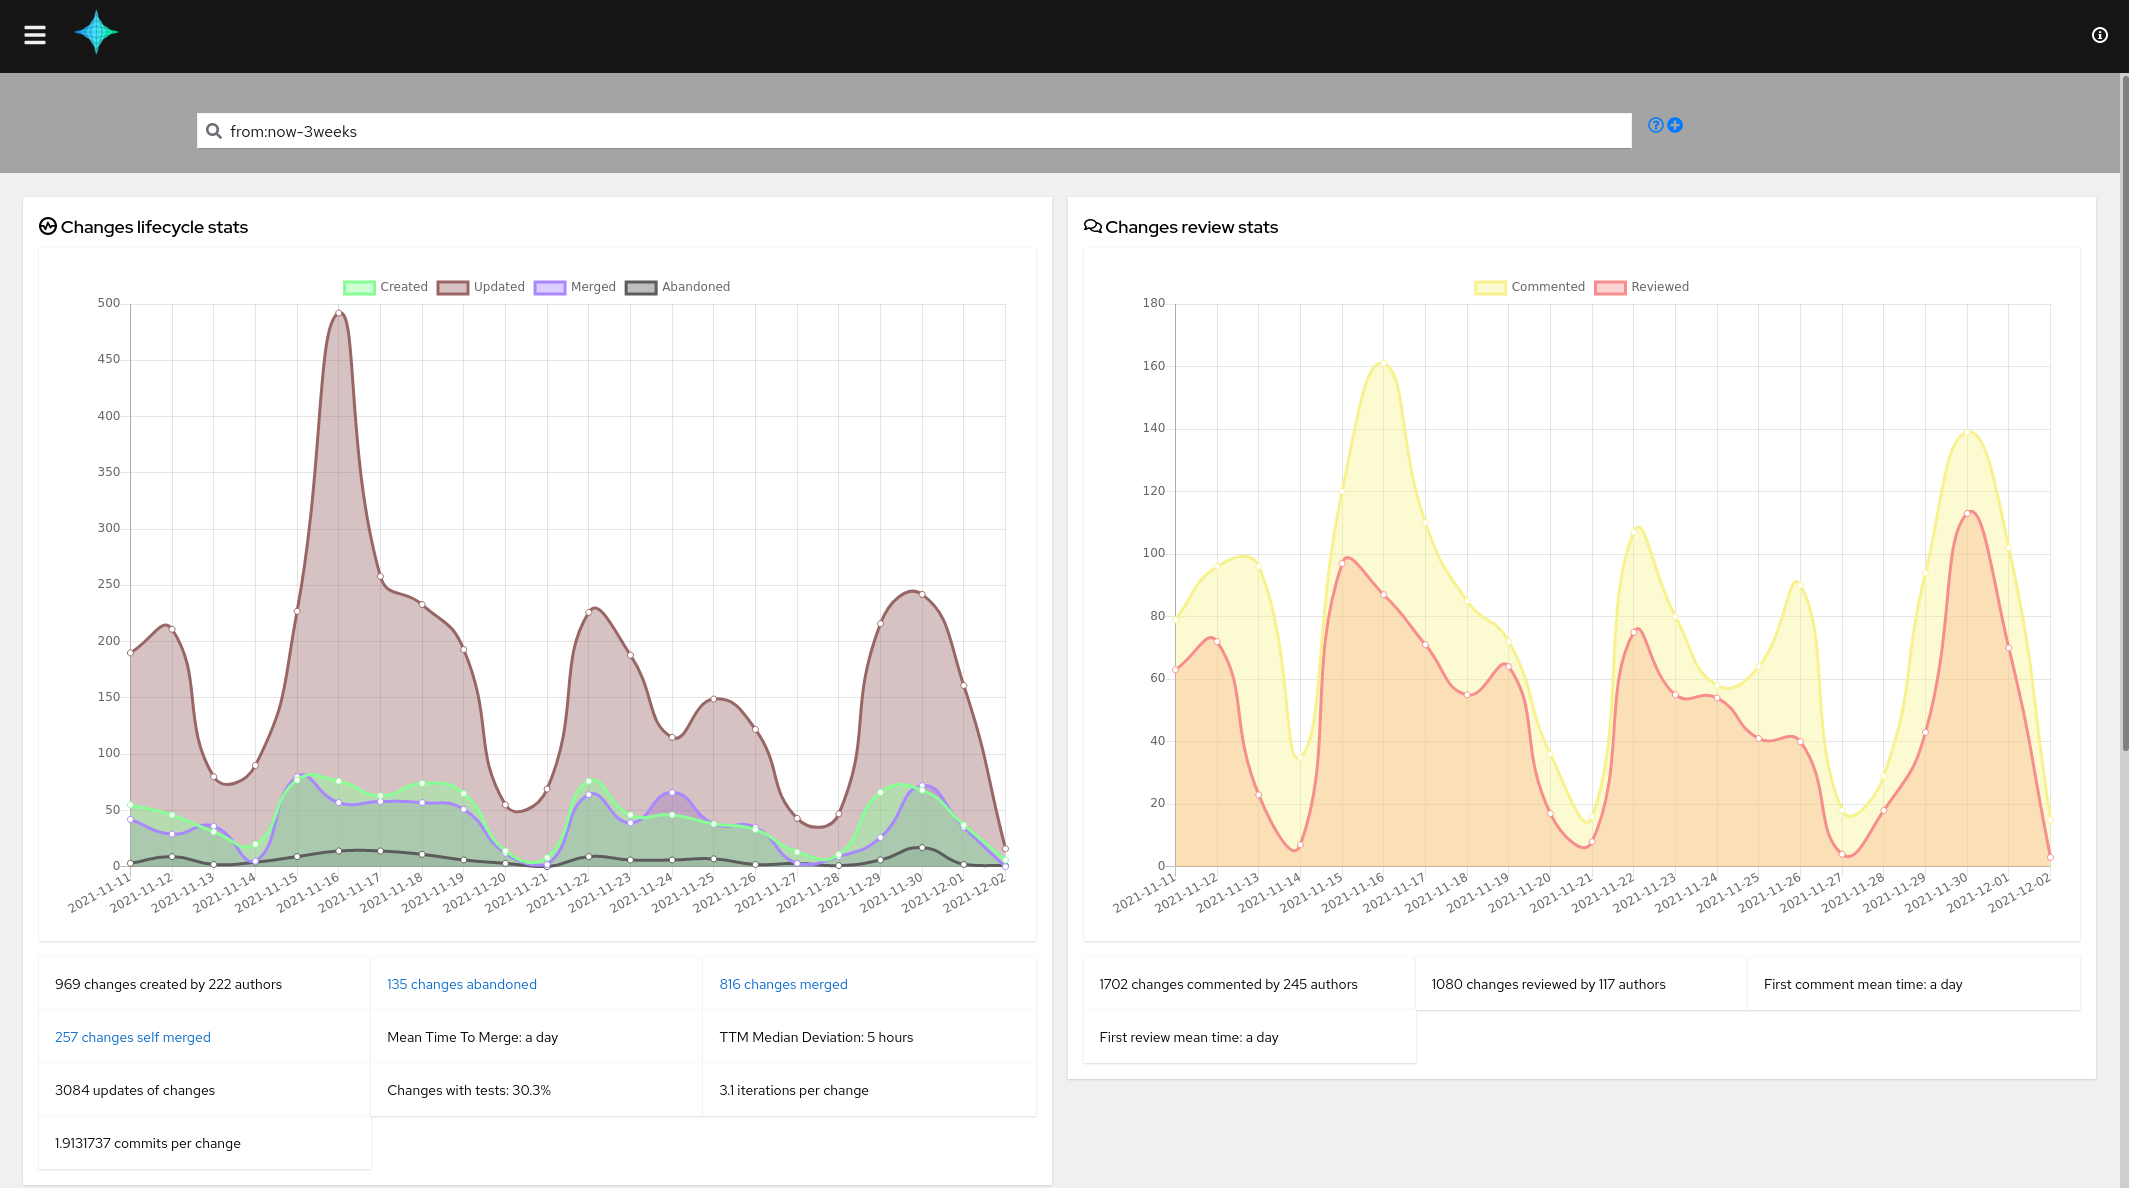
Monocle helps teams and individual to better organize daily duties and to detect anomalies in the way changes are produced and reviewed.

charles-001

Your single pane of glass for real-time analytics into MySQL/MariaDB & ProxySQL

chartbrew
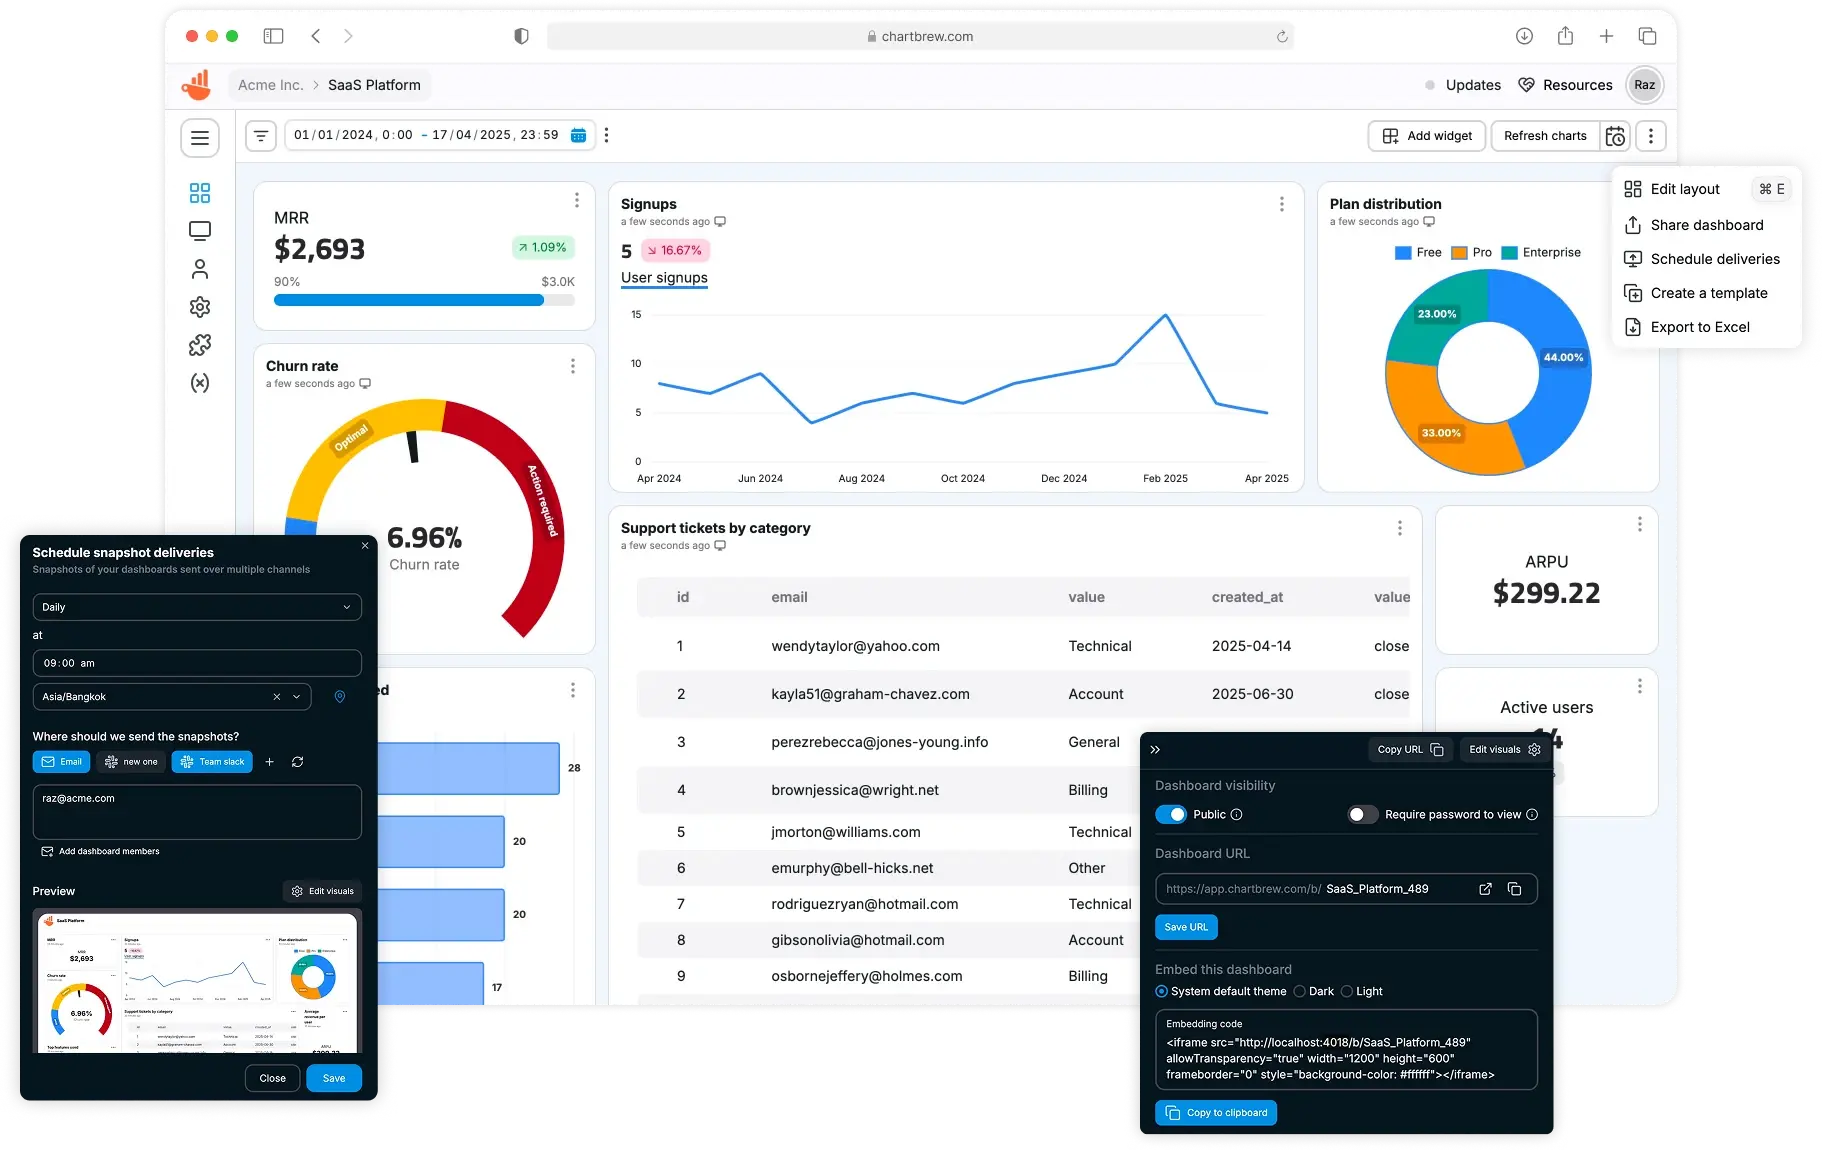
Open-source reporting platform to build and share live dashboards from APIs, SQL and NoSQL databases, with powerful AI assistant, scheduling, and embeddable charts 📈📊

ChawlaAvi
A collection of code snippets from the publication Daily Dose of Data Science on Substack: http://www.dailydoseofds.com/
This project demonstrates how to build and automate an ETL pipeline using DAGs in Airflow and load the transformed data to Bigquery. There are different tools that have been used in this project such as Astro, DBT, GCP, Airflow, Metabase.

chdb-io

chDB is an in-process OLAP SQL Engine 🚀 powered by ClickHouse

chennaione
Insanely easy way to work with Android Database.

chinnonsantos
SQL de todos os Países e Nações (c/ Código do Portal do Comércio Exterior ou BACEN) + Estados e Federações Brasileiras (c/ DDD e Código do IBGE) + Cidades e Municípios Brasileiros (c/ Código do IBGE), incluindo as 31 regiões administrativas do DF, Ilhas e Áreas Remotas do Mundo.

chiphuyen

Claude Code dashboard with usage stats, error analysis, and sharable feature

ChristianTremblay
Pyhaystack is a module that allow python programs to connect to a haystack server project-haystack.org. Connection can be established with Niagara Platform running the nhaystack, Skyspark and Widesky. For this to work with Anaconda IPython Notebook in Windows, be sure to use "python setup.py install" using the Anaconda Command Prompt in Windows. If not, module will be installed for System path python but won't work in the environment of Anaconda IPython Notebook. You will need hszinc 1.3+ for this to work.

CHYbeta
Code-Audit-Challenges

ciaren-labs
Open-source, local-first visual ETL and data pipeline builder. Drag-and-drop data prep and ML workflows, preview every step, schedule runs, and export clean pandas or Polars Python code. Self-hosted, no lock-in.

circuithub

Hey! Hey! Can u rel8?

citusdata
PostgreSQL extension adding HyperLogLog data structures as a native data type

Marketplace of Kubernetes applications available for quick and easy installation in to Civo Kubernetes clusters

clappr
A clappr plugin to report playback statuses (timers: session, buffering, watch and counters: play, pause, error, fps)

clarilayer
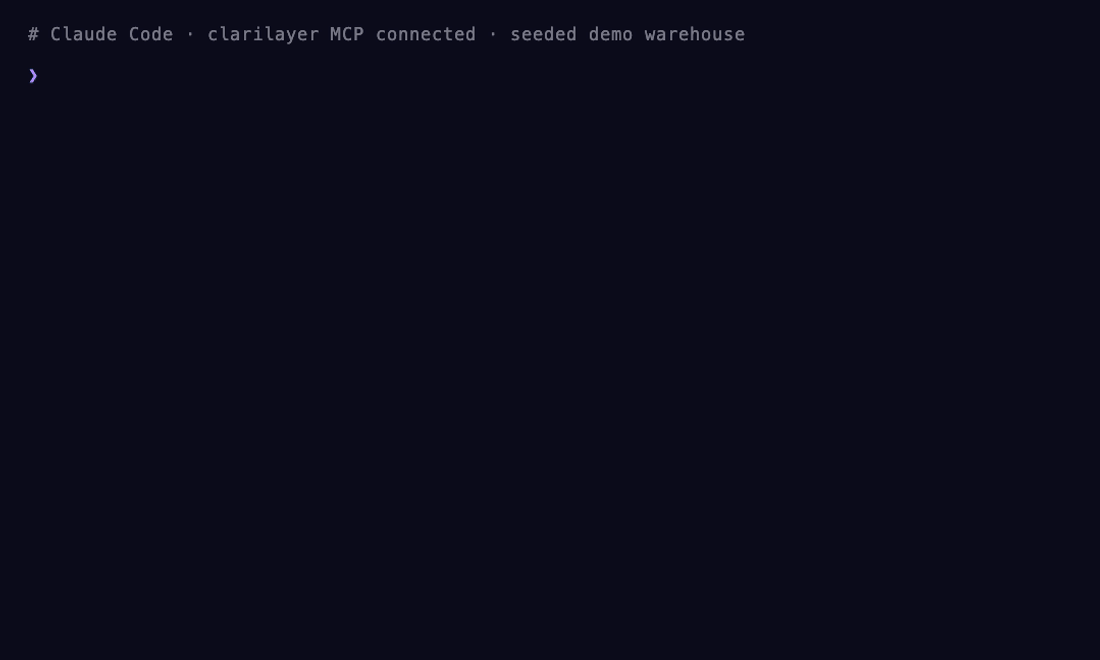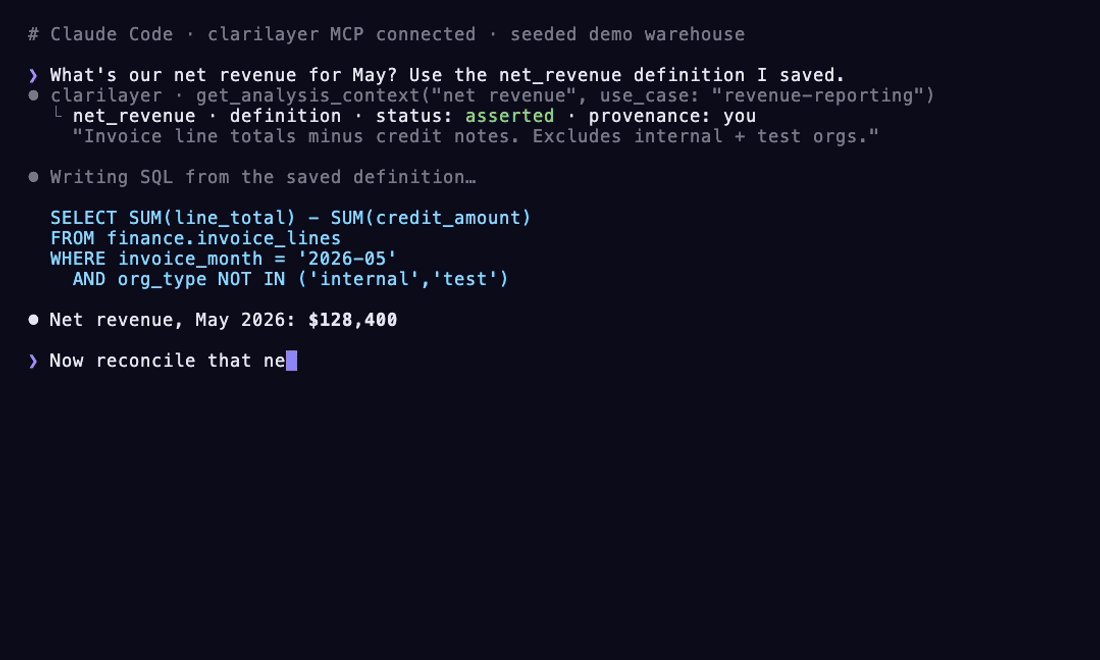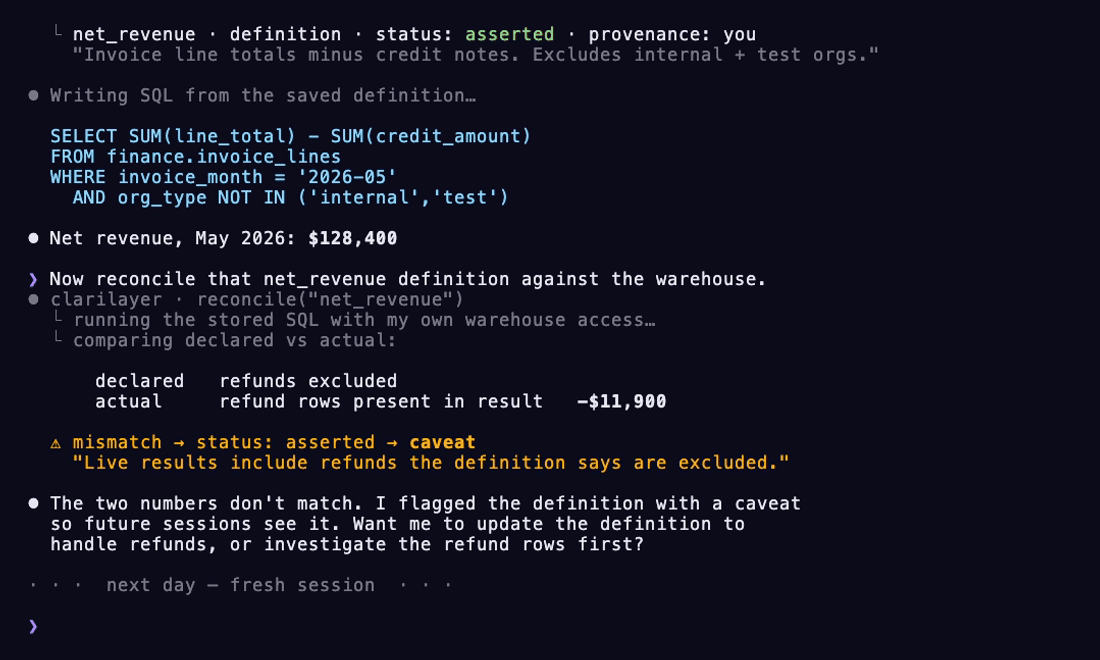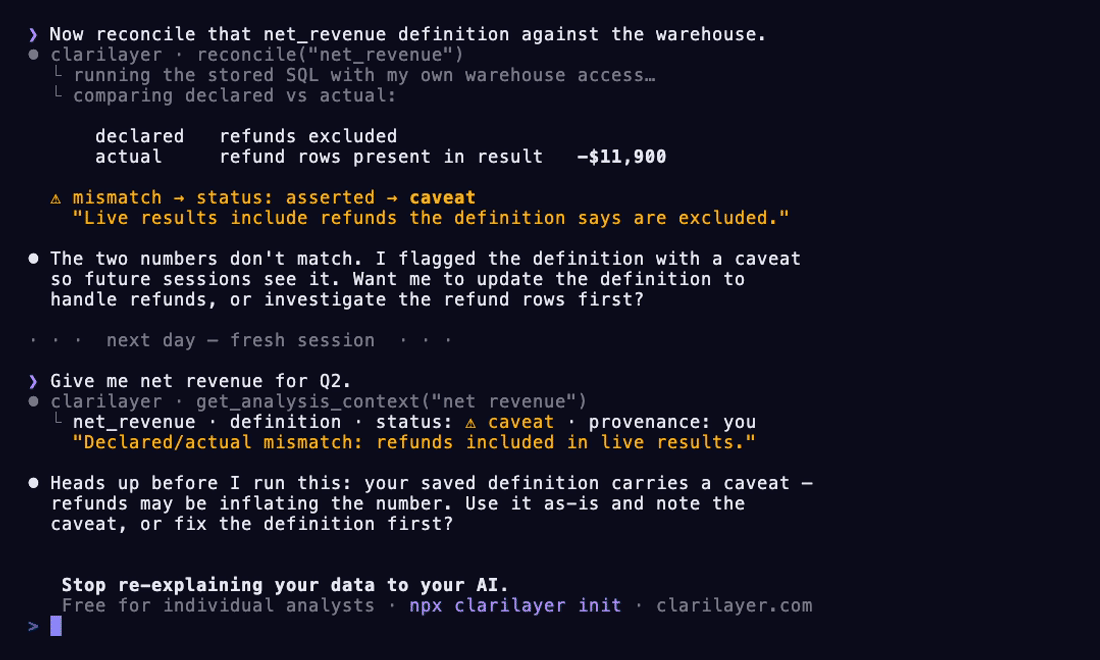
Memory for your AI work across projects and sessions. Save decisions, rules and lessons with source and applicability. Connect over MCP.

