2,974stars
A list of publicly available datasets with real-time data maintained by the team at bytewax.io
Store, explore, and understand your data.
A list of publicly available datasets with real-time data maintained by the team at bytewax.io

bytewax
Python Stream Processing

c-rainstorm

本仓库存放个人博客的 markdown 源文件

CacheerPHP

CacheerPHP is a minimalist package for caching in PHP, offering a simple interface for storing and retrieving cached data using multiple backends (files, database, arrays and Redis).

cadenzauk
Typesafe API for SQL

cahyadsn
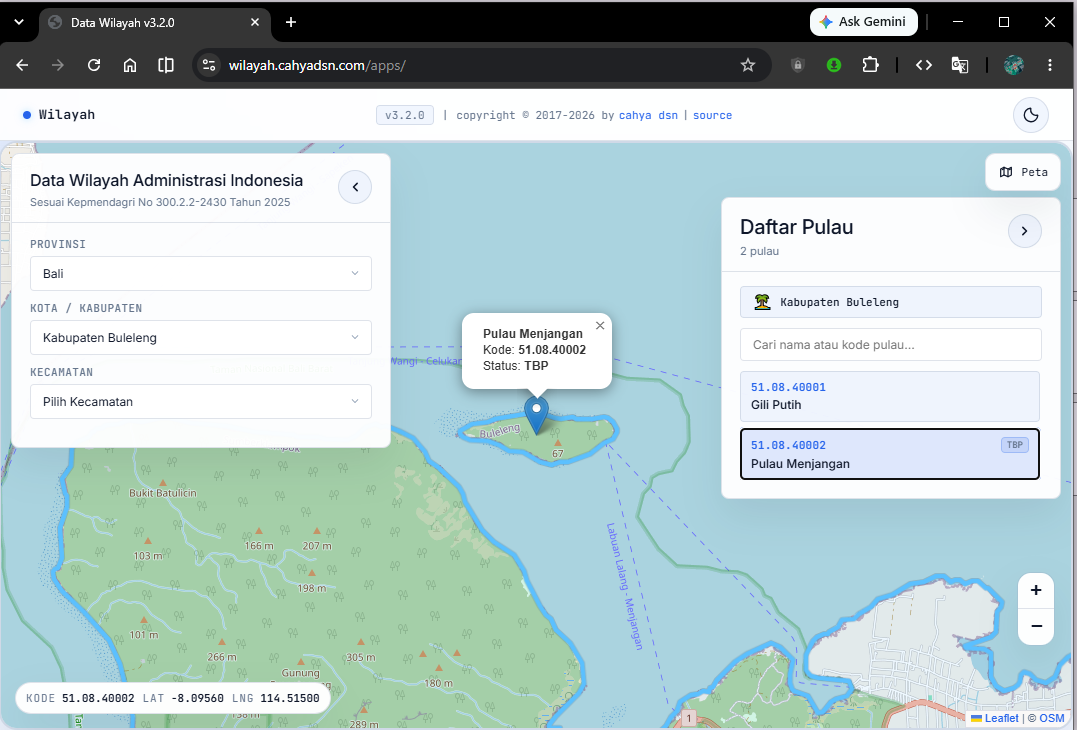
Kode dan Data Wilayah Administrasi & Pulau Indonesia sesuai Kepmendagri No 300.2.2-2430 Tahun 2025 dengan PHP+MySQL+AJaX. Demo link : https://wilayah.cahyadsn.com/

caioricciuti
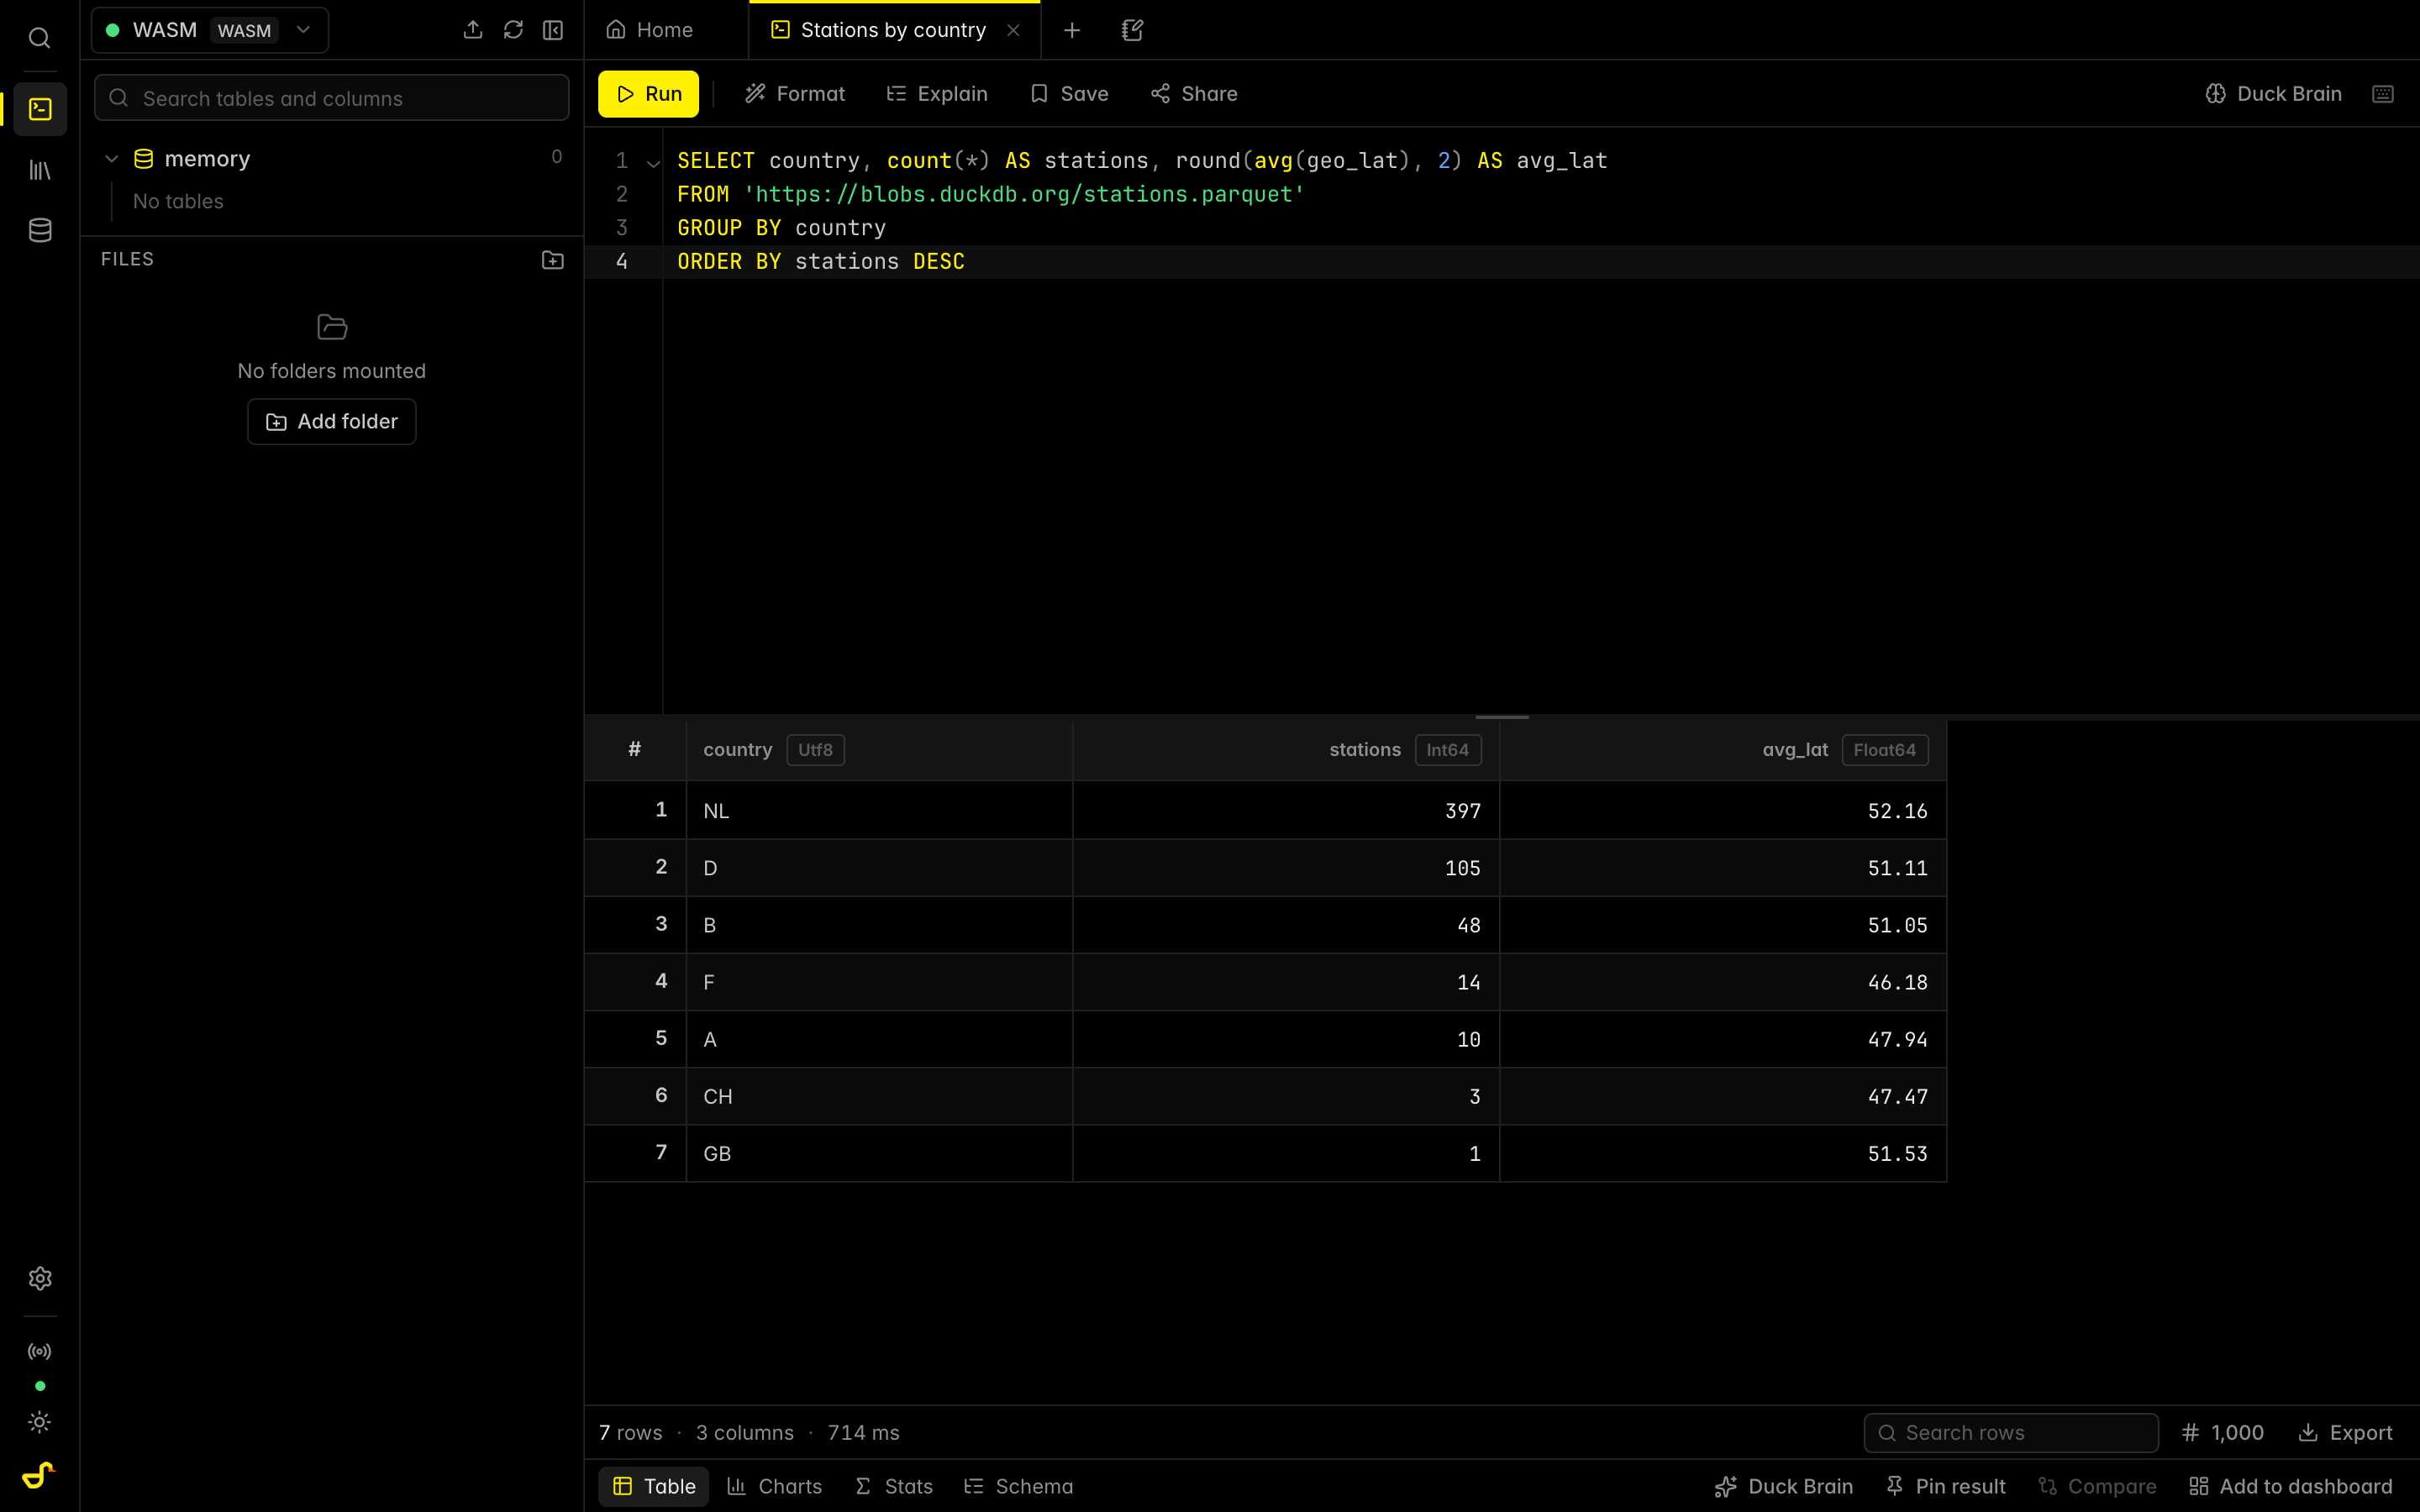
The fully open-source DuckDB workbench that runs in your browser. SQL editor, notebooks, charts, AI assistant. No install, no signup, no backend — your data never leaves the tab.

caison
【🌱🌱Java服务端知识技能图谱】用思维脑图梳理汇总Java服务端知识技能

caiyue1993
Sync Realm Database with CloudKit

cajuncoding

A set of extensions for working with HotChocolate GraphQL and Database access with micro-orms such as RepoDb (or Dapper). This extension pack provides access to key elements such as Selections/Projections, Sort arguments, & Paging arguments in a significantly simplified facade so this logic can be leveraged in the Serivces/Repositories that encapsulate all data access (without dependency on IQueryable and execution outside of the devs control).

call518
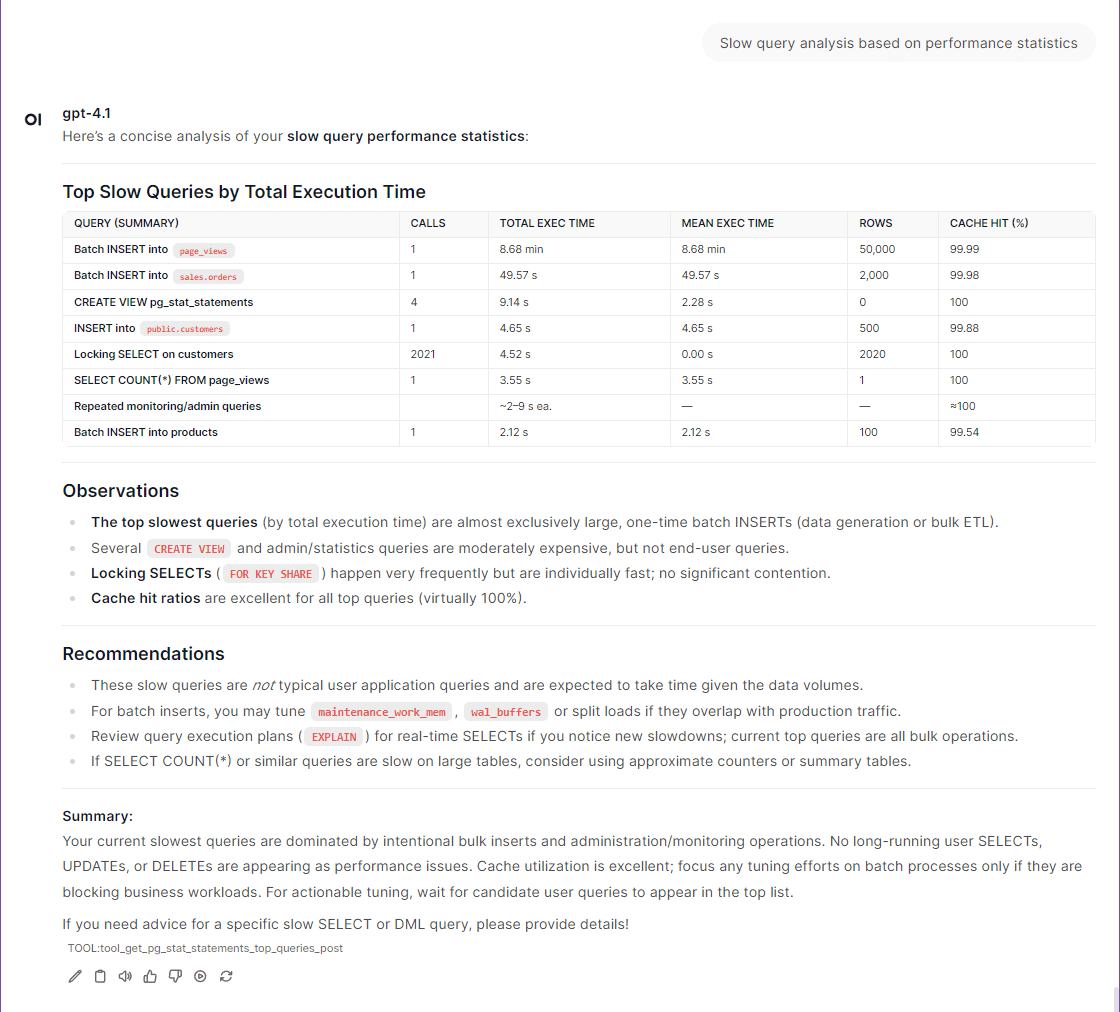
🐘 Give AI assistants full PostgreSQL DBA superpowers — 30+ tools for performance analysis, bloat detection, lock/deadlock monitoring, autovacuum & schema inspection. No extensions required. PG 12-18.

Cambalab

A dockerized solution to run Metabase using compose

CamDavidsonPilon
Survival analysis in Python

cameodb
CameoDB - The Unified Hybrid Search Database Engine

camsaul

Successor library to Toucan with a modern and more-extensible API, more consistent behavior, and support for different backends including non-JDBC databases and non-HoneySQL queries. Currently in active beta.

camusdb
CamusDB is a SQL distributed database written in C# on .NET. It pairs a SQL interface with a Raft-replicated, transactional k/v storage layer, it makes opinionated choices: serializable isolation/strong consistency by default, databases can be branched copy-on-write and it can auto-scale to adapt to traffic

Canner

Data API Framework for AI Agents and Data Apps

cap-js
Monorepo for SQL Database Services for CAP

capitalone
locopy: Loading/Unloading to Redshift and Snowflake using Python.

carbotton
IBM Data Engineering Courses from Coursera

CarissaAI
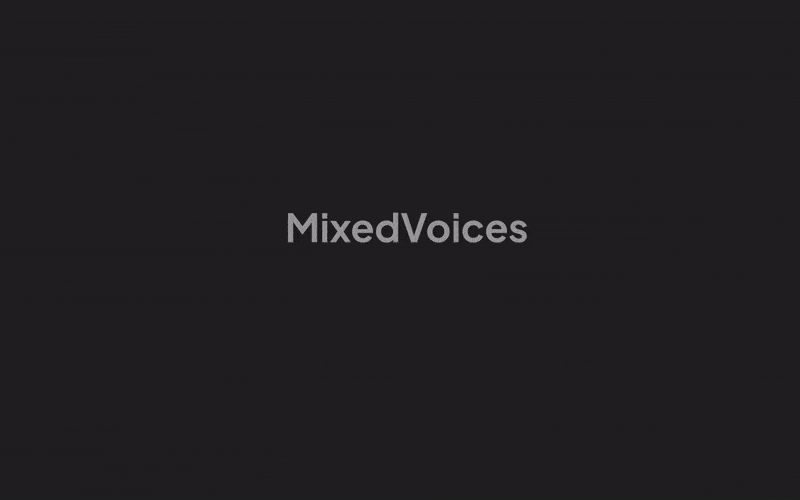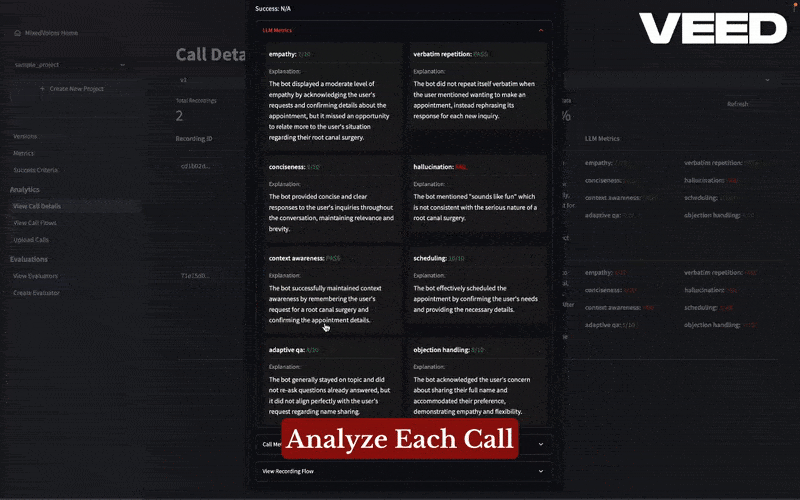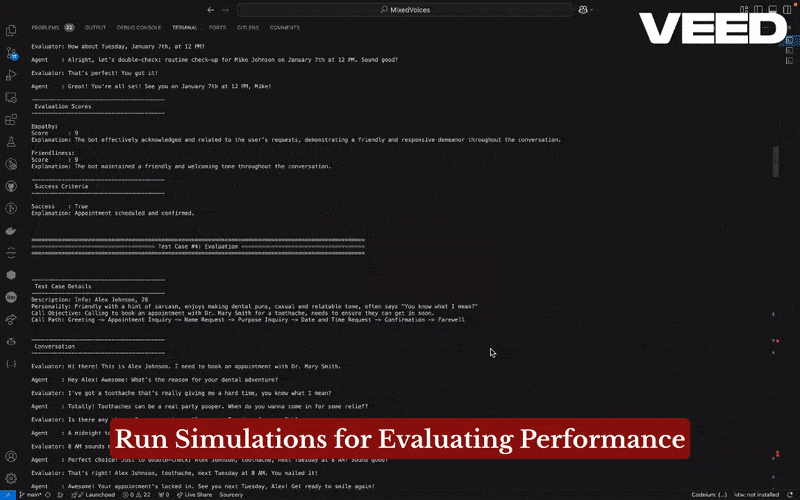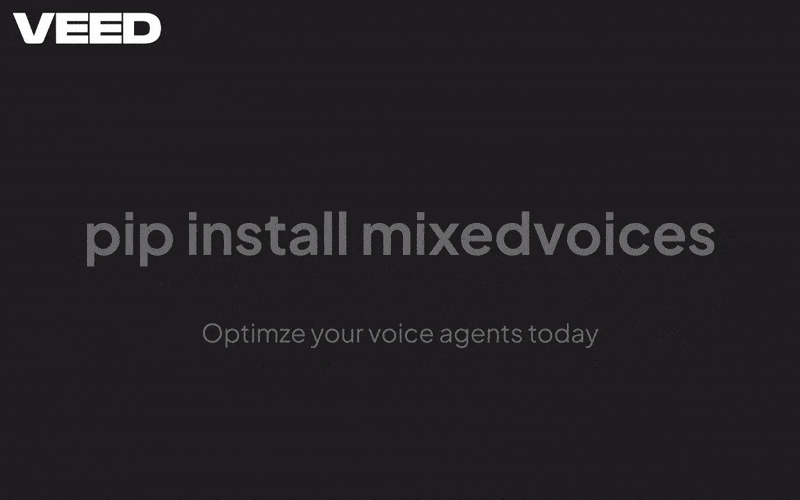
Mixpanel for conversational AI

CarmJos
:floppy_disk: Easy (to operate) SQL Databases! A easy-to-use advanced SQL framework based on JDBC, supports multiple types of databases and connection pools, with high customizability and extensibility.

Casecommons
pg_search builds ActiveRecord named scopes that take advantage of PostgreSQL’s full text search
This is a repository of a topic-centric public data sources in high quality for Recommender Systems (RS)
