
bsed
andrewbihl
414stars
Simple SQL-like syntax on top of Perl text processing.
Store, explore, and understand your data.
andrewbihl
Simple SQL-like syntax on top of Perl text processing.

andyforever
A GUI Desktop App for export sequelize models from database automatically.

angulartics
Vendor-agnostic analytics for Angular2 applications.

ankane
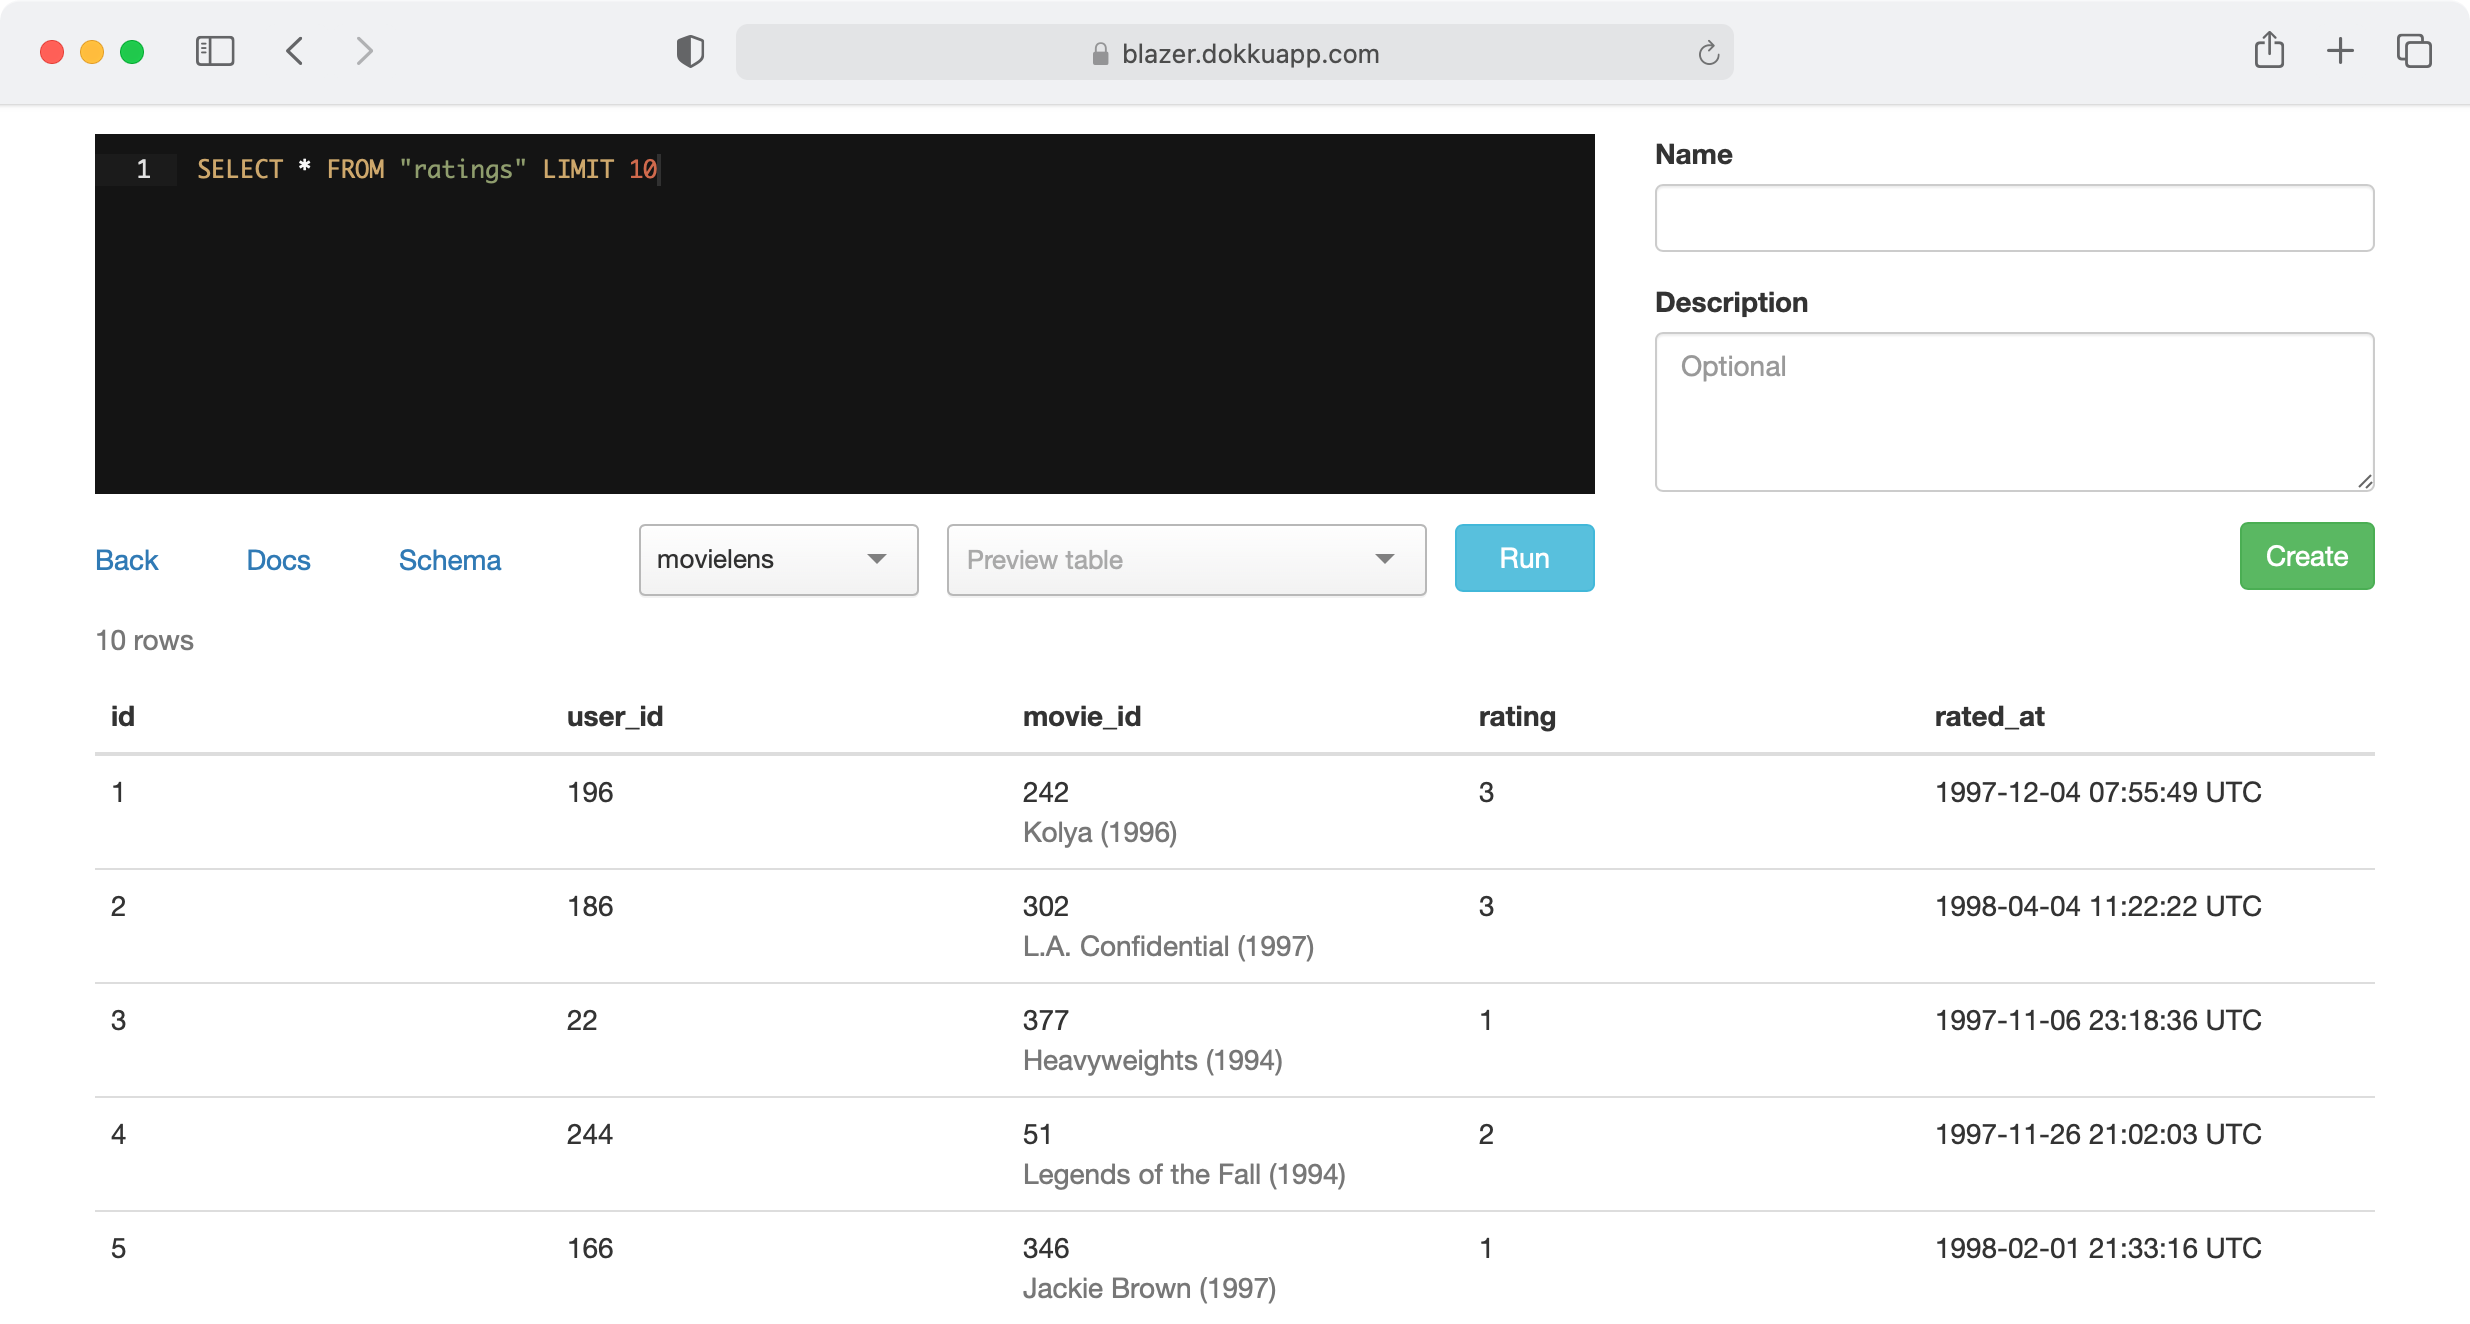
Business intelligence made simple
ankane
Sync data from one Postgres database to another

ankurchavda

A data engineering project with Kafka, Spark Streaming, dbt, Docker, Airflow, Terraform, GCP and much more!

anlek
Mongify allows you to map your data from a sql database and into a mongodb document database.

AnonCatalyst
Coeus 🌐 is an OSINT ToolBox empowering users with tools for effective intelligence gathering from open sources. From social media monitoring 📱 to data analysis 📊, it offers a centralized platform for seamless OSINT investigations.

antares-sql
A modern, fast and productivity driven SQL client with a focus in UX

antoniosarosi
Toy Database

antonkomarev

It counts how many times your GitHub profile has been viewed. Free cloud micro-service.

antonmks
GPU database engine

apache
Apache Beam is a unified programming model for Batch and Streaming data processing.
apache
Apache Calcite
apache
Node.js Driver for Apache Cassandra
apache
Seamless multi-primary syncing database with an intuitive HTTP/JSON API, designed for reliability
apache
Fauxton is the new Web UI for CouchDB
apache
Extensible SQL Lexer and Parser for Rust
apache
Apache Drill is a distributed MPP query layer for self describing data
apache

Gluten is a middle layer responsible for offloading JVM-based SQL engines' execution to native engines.
apache
Apache Hamilton helps data scientists and engineers define testable, modular, self-documenting dataflows, that encode lineage/tracing and metadata. Runs and scales everywhere python does.
apache
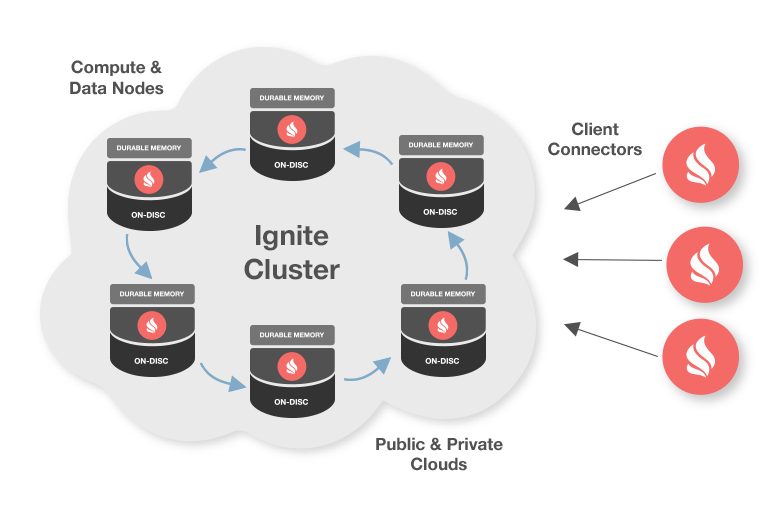
Apache Ignite
apache
Apache Ignite 3
apache
Apache Jackrabbit Oak