zhmiao/OpenLongTailRecognition-OLTR
zhmiao/OpenLongTailRecognition-OLTR has 873 GitHub stars and 130 forks. GitHot measured 0 stars in 24 hours, 0 in 7 days, and 0 in 15 days. Last checked 2026-11-10 00:28 UTC. Last push 2022-07-16.
Pytorch implementation for "Large-Scale Long-Tailed Recognition in an Open World" (CVPR 2019 ORAL)
Measured star growth
- in 24h
- 0
- in 7 days
- 0
- in 15 days
- 0
- in 1 month
- Update delayed
Net star changes over overlapping periods, not daily totals. Missing measurements are left blank. Stars measure attention, not software quality.
README.md
OriginalLarge-Scale Long-Tailed Recognition in an Open World
Overview
Open Long-Tailed Recognition (OLTR) is the author's re-implementation of the long-tail recognizer described in:
"Large-Scale Long-Tailed Recognition in an Open World"
Ziwei Liu*, Zhongqi Miao*, Xiaohang Zhan, Jiayun Wang, Boqing Gong, Stella X. Yu (CUHK & UC Berkeley / ICSI)
in IEEE Conference on Computer Vision and Pattern Recognition (CVPR) 2019, Oral Presentation

Further information please contact Zhongqi Miao and Ziwei Liu.
Update notifications
- 03/04/2020: We changed all valirables named
selfatttomodulatedattso that the attention module can be properly trained in the second stage for Places-LT. ImageNet-LT does not have this problem since the weights are not freezed. We have updated new results using fixed code, which is still better than reported. The weights are also updated. Thanks! - 02/11/2020: We updated configuration files for
Places_LTdataset. The current results are a little bit higher than reported, even with updated F-measure calculation. One important thing to be considered is that we have unfrozon the model weights for the first stage training ofPlaces-LT, which means it is not suitable for single-GPU training in most cases (we used 4 1080ti in our implementation). However, for the second stage, since the memory and center loss do not support multi-GPUs currently, please switch back to single-GPU training. Thank you very much! - 01/29/2020: We updated the
False Positivecalculation inutil.pyso that the numbers are normal again. The reported F-measure numbers in the paper might be a little bit higher than actual numbers for all baselines. We will update it as soon as possible. We have updated the new F-measure number in the following table. Thanks. - 12/19/2019: Updated modules with 'clone()' methods and set
use_fcin ImageNet-LT stage-1 config toFalse. Currently, the results for ImageNet-LT is comparable to reported numbers in the paper (a little bit better), and the reproduced results are updated below. We also found the bug in Places-LT. We will update the code and reproduced results as soon as possible. - 08/05/2019: Fixed a bug in
utils.py. Update re-implemented ImageNet-LT weights at the end of this page. - 05/02/2019: Fixed a bug in
run_network.pyso the models train properly. Update configuration file for Imagenet-LT stage 1 training so that the results from the paper can be reproduced.
Requirements
- PyTorch (version >= 0.4.1)
- scikit-learn
Data Preparation
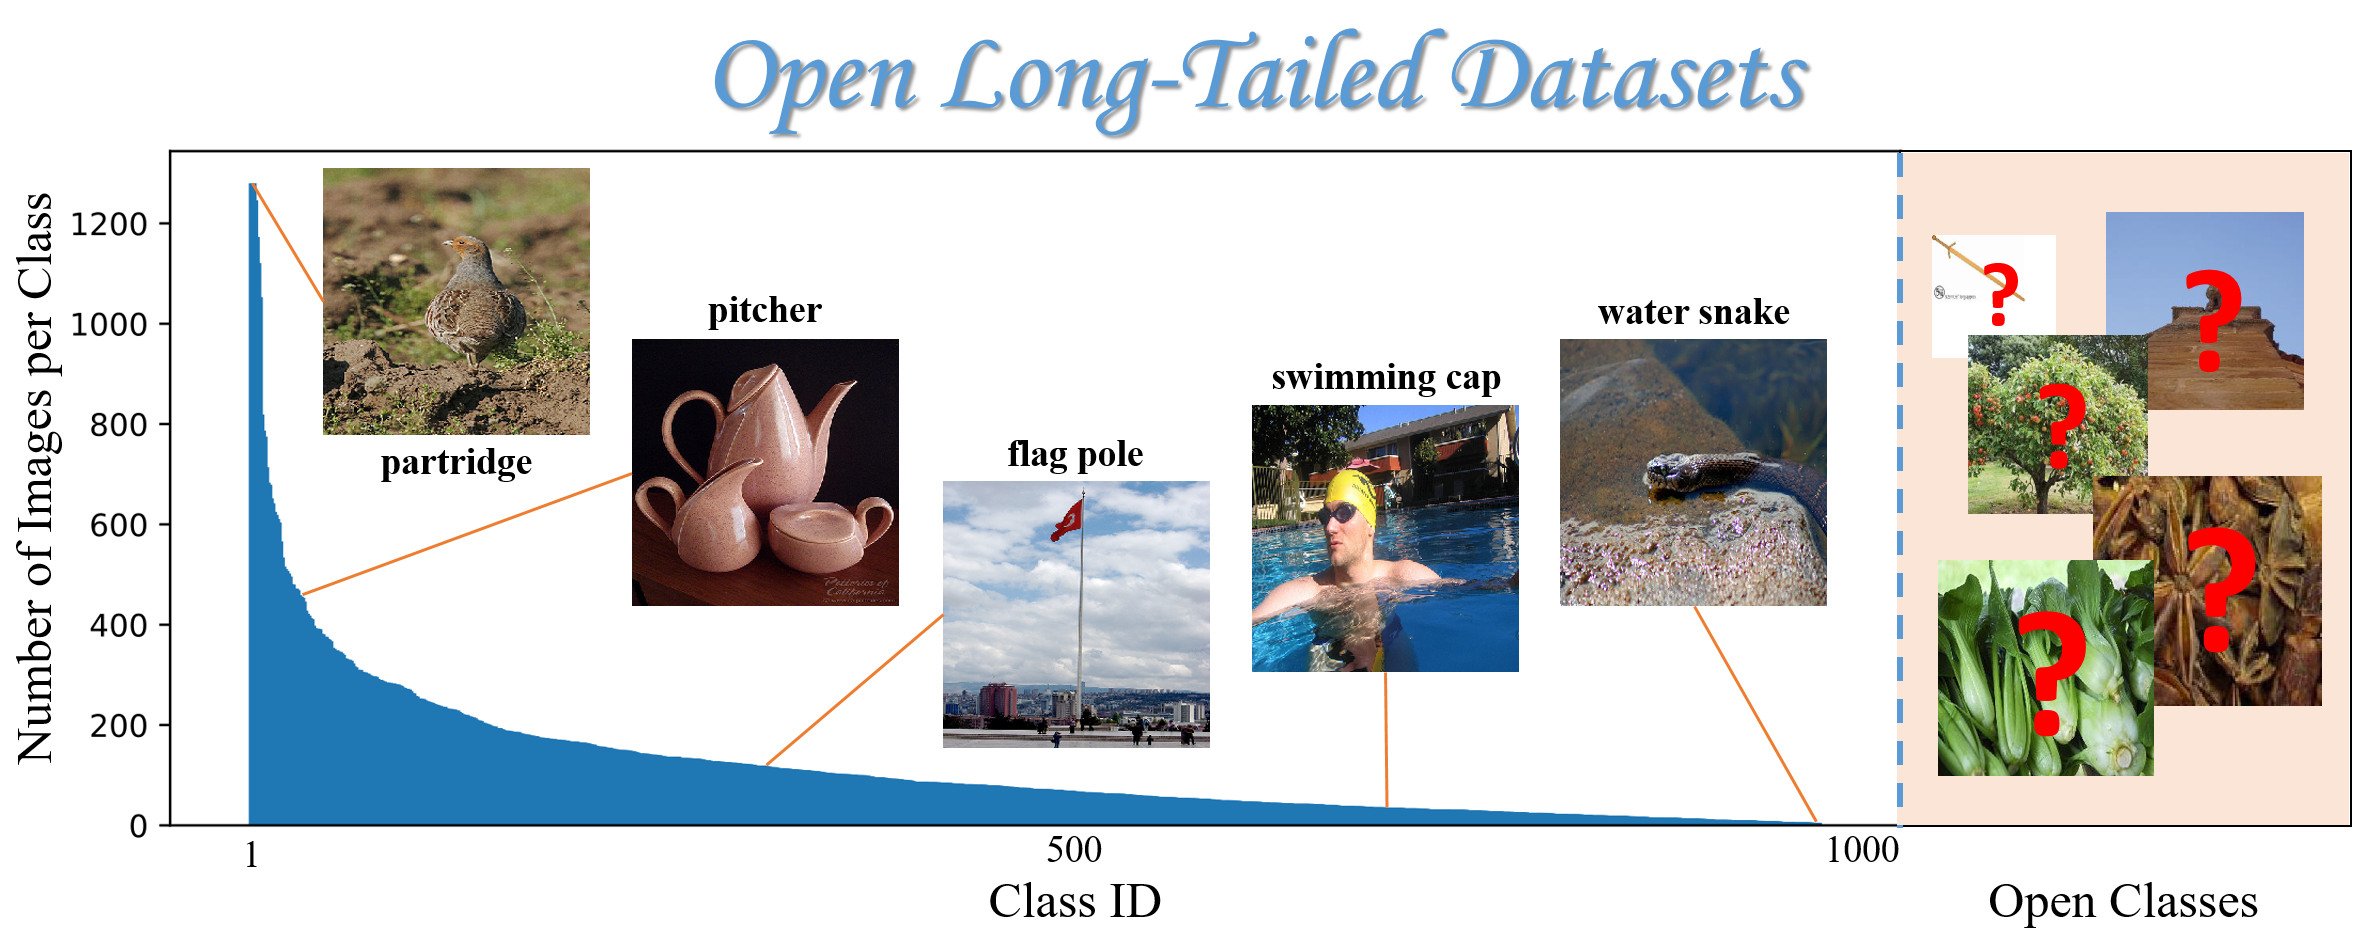
NOTE: Places-LT dataset have been updated since the first version. Please download again if you have the first version.
First, please download the ImageNet_2014 and Places_365 (256x256 version). Please also change the
data_rootinmain.pyaccordingly.Next, please download ImageNet-LT and Places-LT from here. Please put the downloaded files into the
datadirectory like this:
data
  |--ImageNet_LT
    |--ImageNet_LT_open
    |--ImageNet_LT_train.txt
    |--ImageNet_LT_test.txt
    |--ImageNet_LT_val.txt
    |--ImageNet_LT_open.txt
  |--Places_LT
    |--Places_LT_open
    |--Places_LT_train.txt
    |--Places_LT_test.txt
    |--Places_LT_val.txt
    |--Places_LT_open.txt
Download Caffe Pre-trained Models for Places_LT Stage_1 Training
- Caffe pretrained ResNet152 weights can be downloaded from here, and save the file to
./logs/caffe_resnet152.pth
Getting Started (Training & Testing)
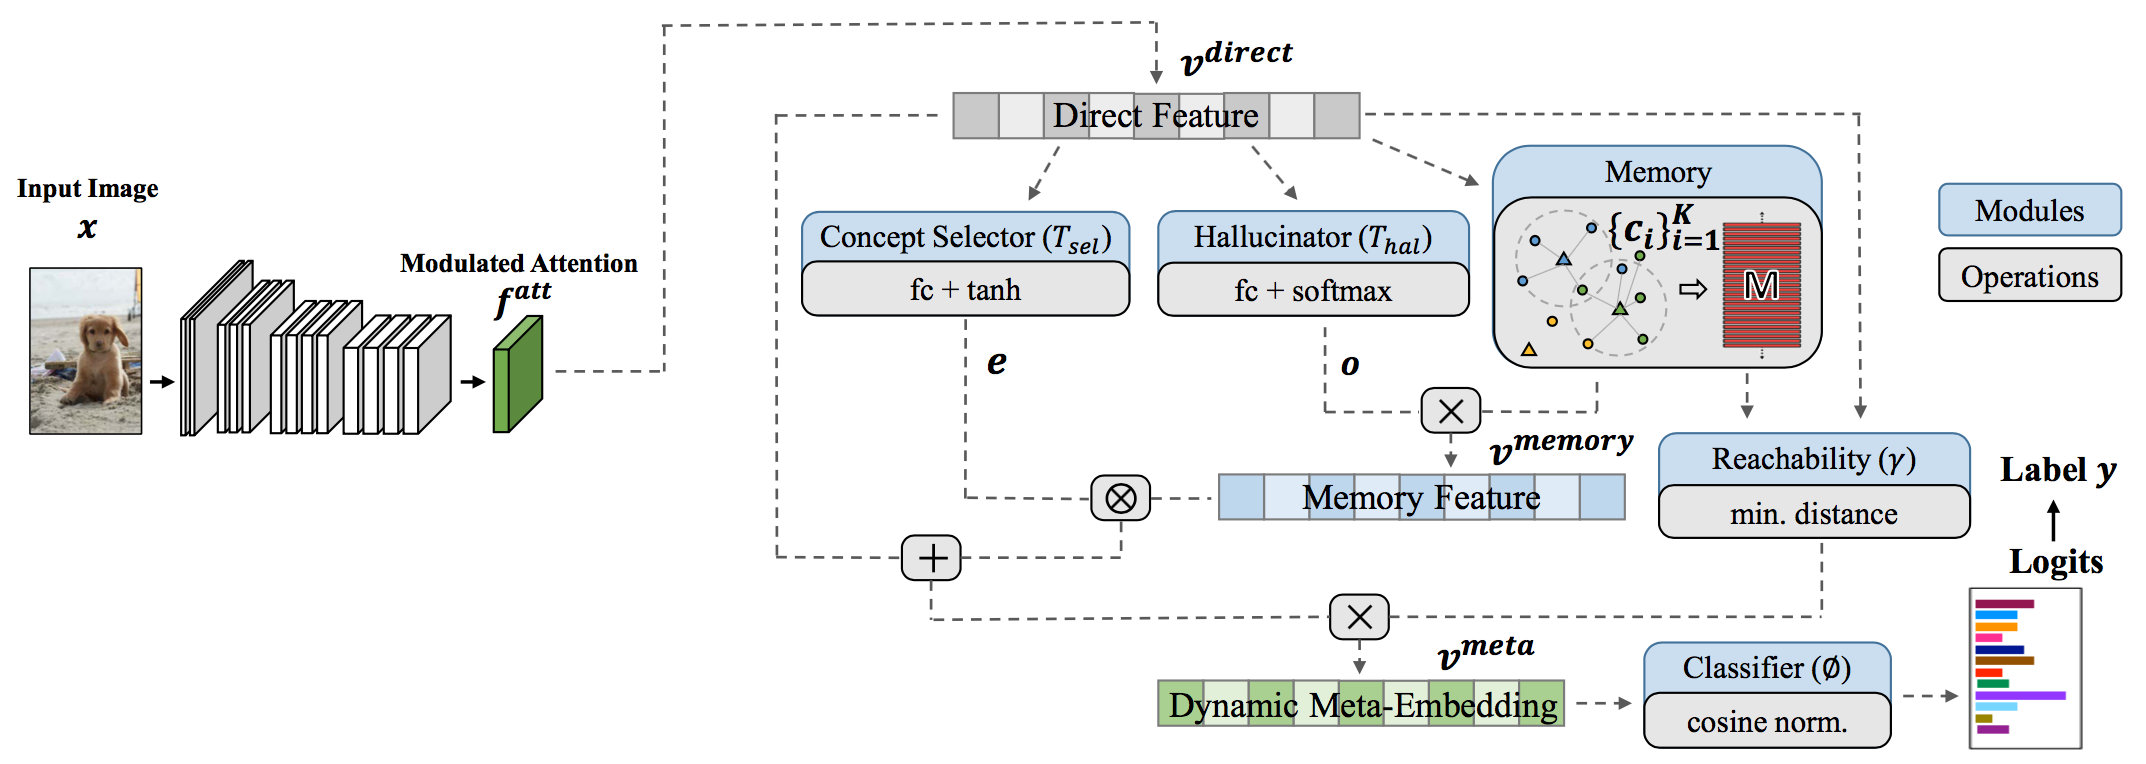
ImageNet-LT
- Stage 1 training:
python main.py --config ./config/ImageNet_LT/stage_1.py
- Stage 2 training:
python main.py --config ./config/ImageNet_LT/stage_2_meta_embedding.py
- Close-set testing:
python main.py --config ./config/ImageNet_LT/stage_2_meta_embedding.py --test
- Open-set testing (thresholding)
python main.py --config ./config/ImageNet_LT/stage_2_meta_embedding.py --test_open
- Test on stage 1 model
python main.py --config ./config/ImageNet_LT/stage_1.py --test
Places-LT
- Stage 1 training (At this stage, multi-GPU might be necessary since we are finetuning a ResNet-152.):
python main.py --config ./config/Places_LT/stage_1.py
- Stage 2 training (At this stage, only single-GPU is supported, please switch back to single-GPU training.):
python main.py --config ./config/Places_LT/stage_2_meta_embedding.py
- Close-set testing:
python main.py --config ./config/Places_LT/stage_2_meta_embedding.py --test
- Open-set testing (thresholding)
python main.py --config ./config/Places_LT/stage_2_meta_embedding.py --test_open
Reproduced Benchmarks and Model Zoo (Updated on 03/05/2020)
ImageNet-LT Open-Set Setting
| Backbone | Many-Shot | Medium-Shot | Few-Shot | F-Measure | Download |
|---|---|---|---|---|---|
| ResNet-10 | 44.2 | 35.2 | 17.5 | 44.6 | model |
Places-LT Open-Set Setting
| Backbone | Many-Shot | Medium-Shot | Few-Shot | F-Measure | Download |
|---|---|---|---|---|---|
| ResNet-152 | 43.7 | 40.2 | 28.0 | 50.0 | model |
CAUTION
The current code was prepared using single GPU. The use of multi-GPU can cause problems except for the first stage of Places-LT.
License and Citation
The use of this software is released under BSD-3.
@inproceedings{openlongtailrecognition,
  title={Large-Scale Long-Tailed Recognition in an Open World},
  author={Liu, Ziwei and Miao, Zhongqi and Zhan, Xiaohang and Wang, Jiayun and Gong, Boqing and Yu, Stella X.},
  booktitle={IEEE Conference on Computer Vision and Pattern Recognition (CVPR)},
  year={2019}
}
Explore related projects
tensorflow/tensorflow
An Open Source Machine Learning Framework for Everyone
201,427 starshuggingface/transformers
🤗 Transformers: the model-definition framework for state-of-the-art machine learning models in text, vision, audio, and multimodal models, for both inference and training.
168,711 starsAUTOMATIC1111/stable-diffusion-webui
Stable Diffusion web UI
165,274 starsComfy-Org/ComfyUI
The most powerful and modular diffusion model GUI, api and backend with a graph/nodes interface. The fastest local inference engine in the world.
146,024 stars