
zh-plus/video-to-pose3D
zh-plus/video-to-pose3D has 669 GitHub stars and 128 forks. GitHot measured 0 stars in 24 hours. Last checked 2026-11-15 22:32 UTC. Last push 2023-06-07.
Measured star growth
- in 24h
- 0
- in 7 days
- Update delayed
- in 15 days
- Update delayed
- in 1 month
- Update delayed
Net star changes over overlapping periods, not daily totals. Missing measurements are left blank. Stars measure attention, not software quality.
About
Convert video to 3D pose in one-key.
Creative & MediaREADME.md
OriginalVideo to Pose3D
Predict 3d human pose from video
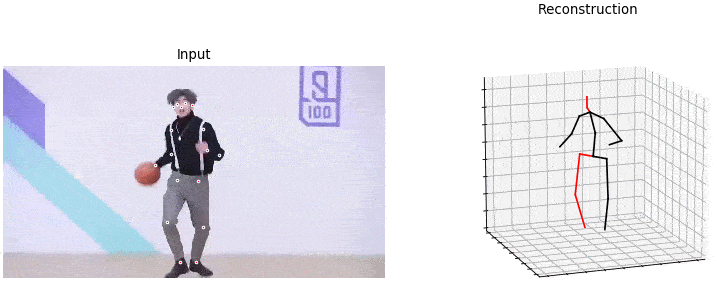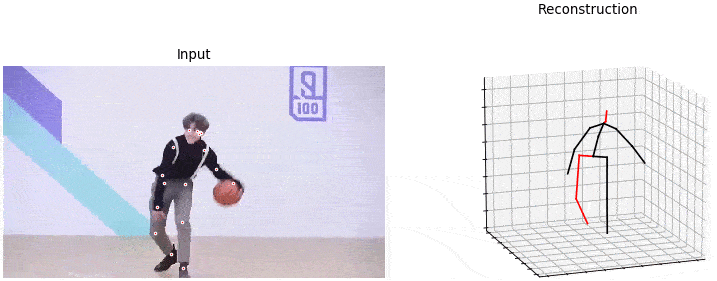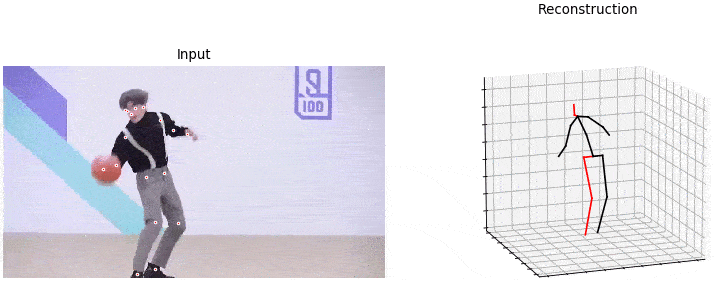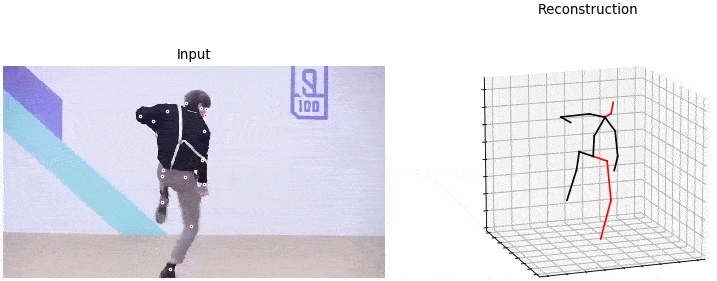
Prerequisite
- Environment
- Linux system
- Python > 3.6 distribution
- Dependencies
- Packages
- Pytorch > 1.0.0
- torchsample
- ffmpeg
- tqdm
- pillow
- scipy
- pandas
- h5py
- visdom
- nibabel
- opencv-python (install with pip)
- matplotlib
- 2D Joint detectors
- Alphapose (Recommended)
- Download duc_se.pth from (Google Drive | Baidu pan),
place to
./joints_detectors/Alphapose/models/sppe - Download yolov3-spp.weights from (Google Drive | Baidu pan),
place to
./joints_detectors/Alphapose/models/yolo
- Download duc_se.pth from (Google Drive | Baidu pan),
place to
- HR-Net (Bad 3d joints performance in my testing environment)
- Download pose_hrnet* from Google Drive | Baidu pan),
place to
./joints_detectors/hrnet/models/pytorch/pose_coco/ - Download yolov3.weights from here,
place to
./joints_detectors/hrnet/lib/detector/yolo
- Download pose_hrnet* from Google Drive | Baidu pan),
place to
- OpenPose (Not tested, PR to README.md is highly appreciated )
- Mediapipe
- Install mediapipe from pypi:
pip install mediapipe
- Install mediapipe from pypi:
- Alphapose (Recommended)
- 3D Joint detectors
- Download pretrained_h36m_detectron_coco.bin from here,
place it into
./checkpointfolder
- Download pretrained_h36m_detectron_coco.bin from here,
place it into
- 2D Pose trackers (Optional)
- PoseFlow (Recommended) No extra dependences
- LightTrack (Bad 2d tracking performance in my testing environment)
- See original README, and perform same get started step on
./pose_trackers/lighttrack
- See original README, and perform same get started step on
- Packages
Usage
- place your video into
./outputsfolder. (I've prepared a test video).
Single person video
- change the
video_pathin the./videopose.py - Run it! You will find the rendered output video in the
./outputsfolder.
Multiple person video (Not implemented yet)
For developing, check
./videopose_multi_personvideo = 'kobe.mp4' handle_video(f'outputs/{video}') # Run AlphaPose, save the result into ./outputs/alpha_pose_kobe track(video) # Taking the result from above as the input of PoseTrack, output poseflow-results.json # into the same directory of above. # The visualization result is save in ./outputs/alpha_pose_kobe/poseflow-vis # TODO: Need more action: # 1. "Improve the accuracy of tracking algorithm" or "Doing specific post processing # after getting the track result". # 2. Choosing person(remove the other 2d points for each frame)
Tips
- The PyCharm is recommended since it is the IDE I'm using during development.
- If you're using PyCharm, mark
./joints_detectors/Alphapose,./joints_detectors/hrnetand./pose_trackersas source root. - If your're trying to run in command line, add these paths mentioned above to the sys.path at the head of
./videopose.py
Advanced
As this script is based on the VedioPose3D provided by Facebook, and automated in the following way:
args = parse_args()

args.detector_2d = 'alpha_pose'
dir_name = os.path.dirname(video_path)
basename = os.path.basename(video_path)
video_name = basename[:basename.rfind('.')]
args.viz_video = video_path
args.viz_output = f'{dir_name}/{args.detector_2d}_{video_name}.gif'

args.evaluate = 'pretrained_h36m_detectron_coco.bin'

with Timer(video_path):
    main(args)
The meaning of arguments can be found here, you can customize it conveniently by changing the args in ./videopose.py.
Acknowledgement
The 2D pose to 3D pose and visualization part is from VideoPose3D.
Some of the "In the wild" script is adapted from the other fork.
The project structure and ./videopose.py running script is adapted from this repo
Coming soon
The other feature will be added to improve accuracy in the future:
- Human completeness check.
- Object Tracking to the first complete human covering largest area.
- Change 2D pose estimation method such as AlphaPose.
- Test HR-Net as 2d joints detector.
- Test LightTrack as pose tracker.
- Multi-person video(complex) support.
- Data augmentation to solve "high-speed with low-rate" problem: SLOW-MO.
Citation
@misc{videotopose2021,
  author = {Zheng, Hao},
  title = {video-to-pose3D},
  year = {2021},
  publisher = {GitHub},
  journal = {GitHub repository},
  howpublished = {\url{https://github.com/zh-plus/video-to-pose3D}},
}