
xid32/SoundMind
xid32/SoundMind has 1,116 GitHub stars and 131 forks. GitHot measured 0 stars in 24 hours. Last checked 2026-11-09 09:38 UTC. Last push 2025-11-26.
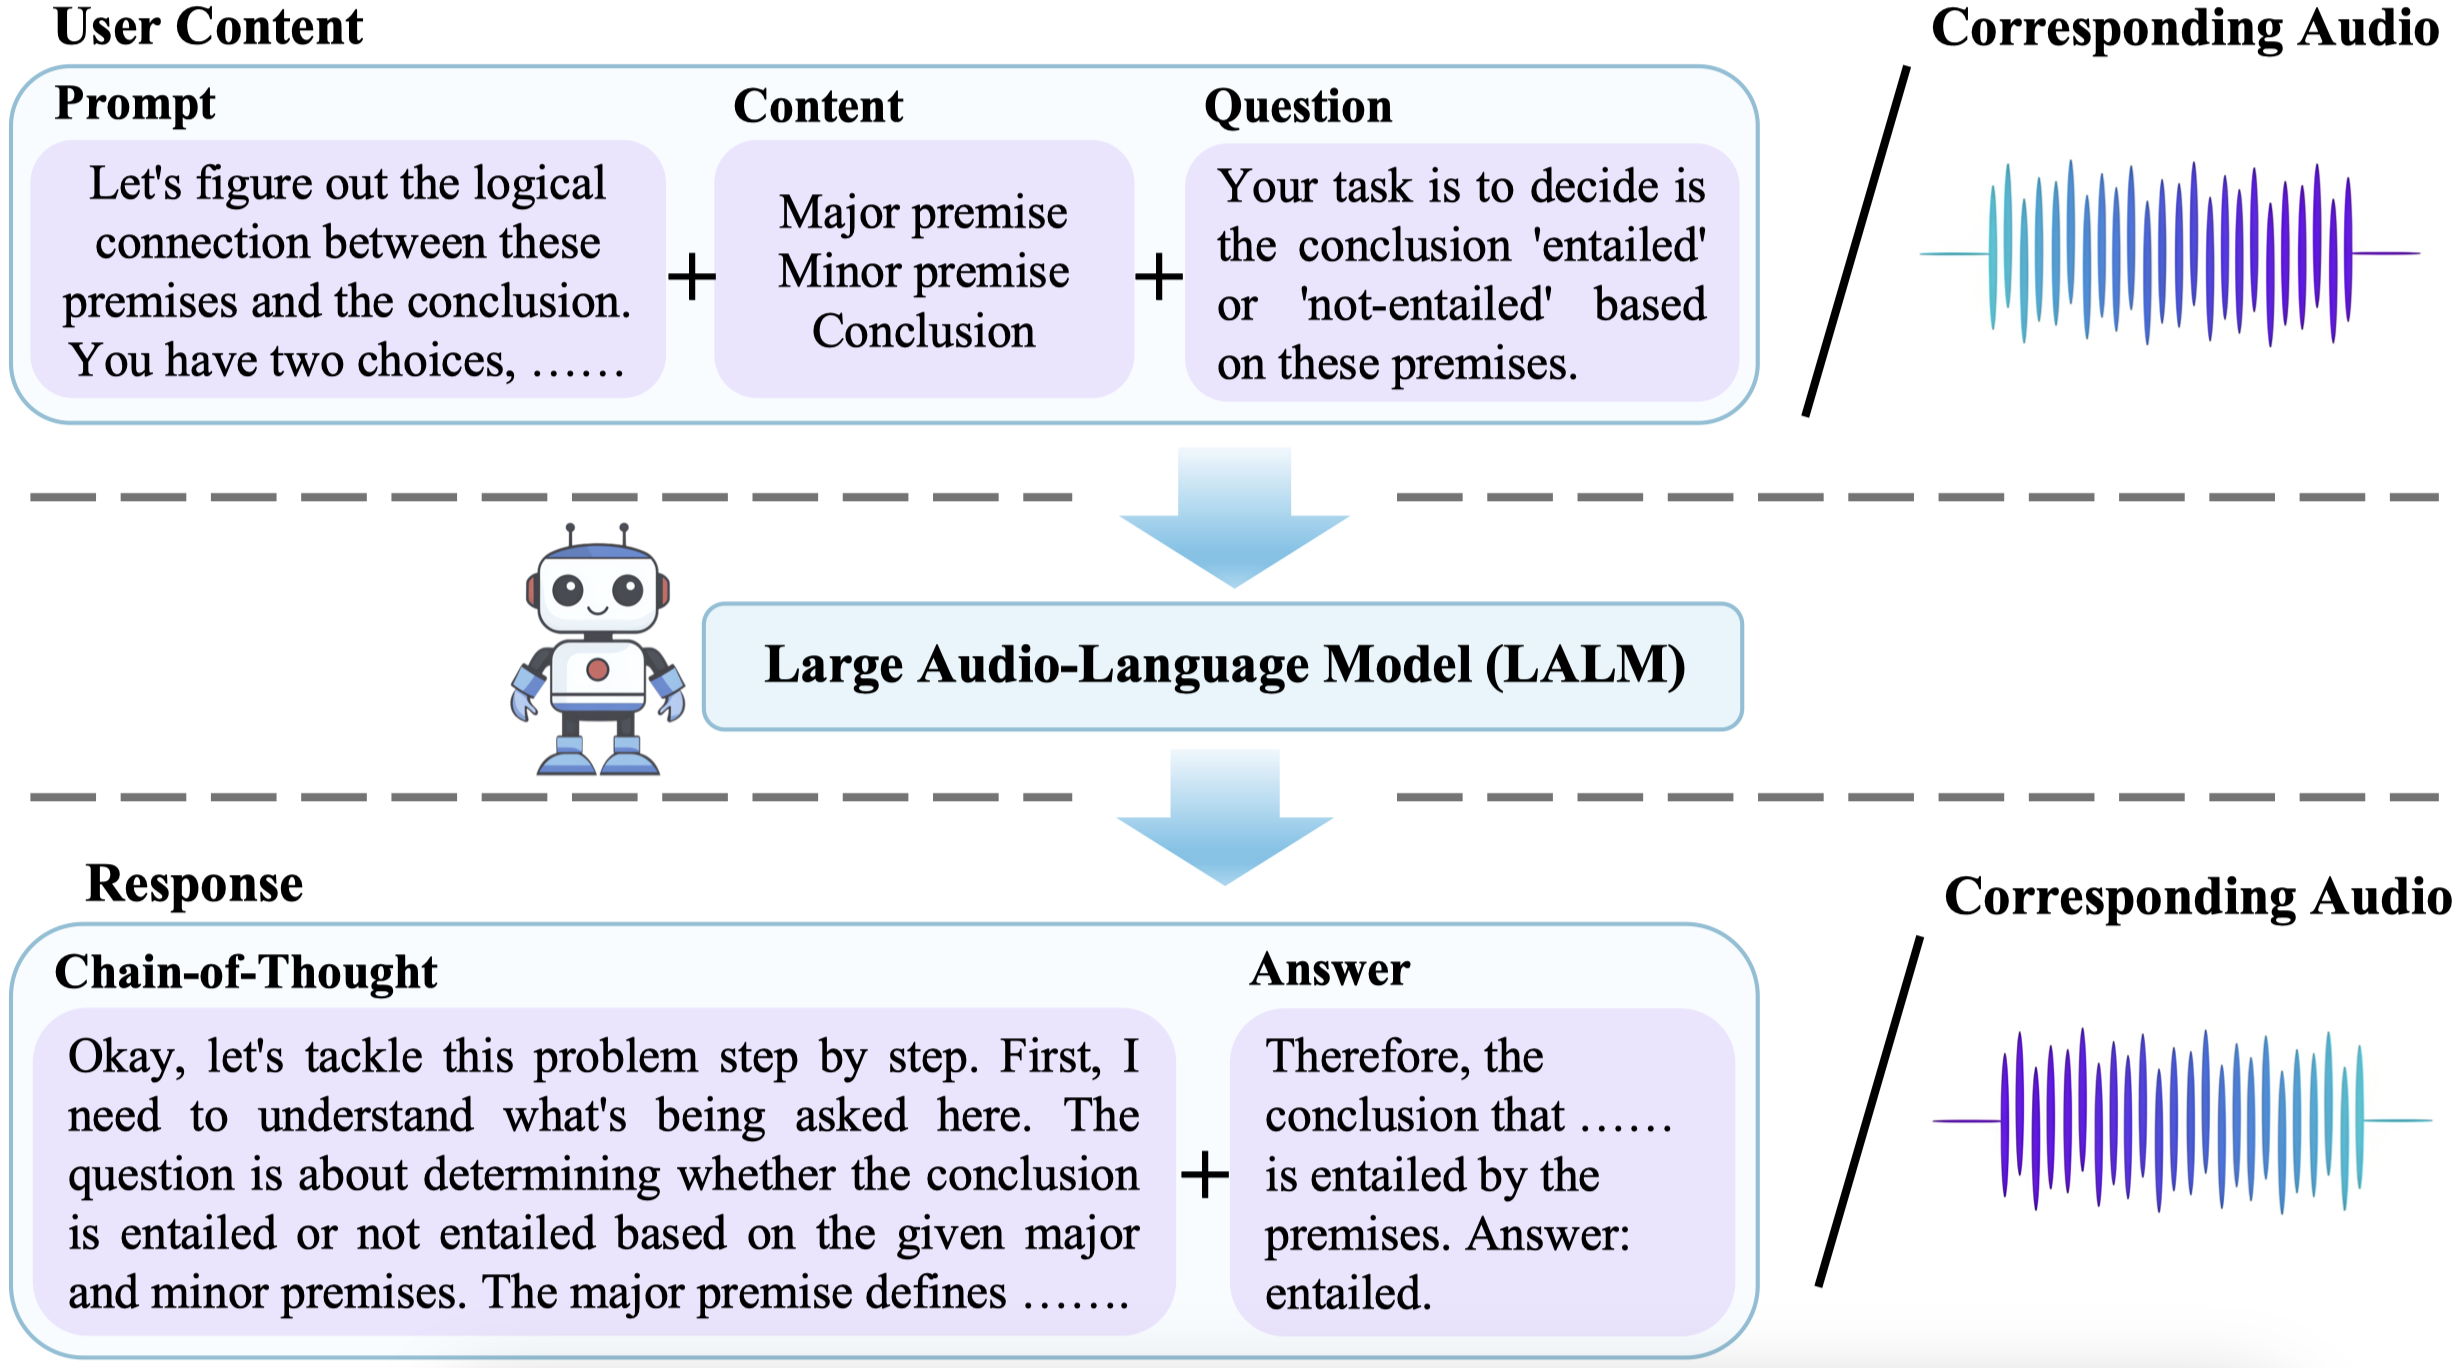
We introduce the Audio Logical Reasoning (ALR) dataset, consisting of 6,446 text-audio annotated samples specifically designed for complex reasoning tasks. Building on this resource, we propose SoundMind, a rule-based reinforcement learning (RL) algorithm tailored to endow audio language models (ALMs) with deep bimodal reasoning abilities.
Measured star growth
- in 24h
- 0
- in 7 days
- Update delayed
- in 15 days
- Update delayed
- in 1 month
- Update delayed
Net star changes over overlapping periods, not daily totals. Missing measurements are left blank. Stars measure attention, not software quality.
README.md
OriginalSoundMind: RL-Incentivized Logic Reasoning for Audio-Language Models [EMNLP 2025 Main Conference (Oral)]



This repository is the official implementation of SoundMind: RL-Incentivized Logic Reasoning for Audio-Language Models (EMNLP 2025). We introduce SoundMind-RL, a novel rule-based reinforcement learning framework that empowers large-scale audio-language models with advanced logical reasoning capabilities across both audio and textual modalities. To enable such training, we build the SoundMind dataset, an Audio Logical Reasoning (ALR) benchmark comprising 6,446 high-quality samples annotated with chain-of-thought reasoning in both audio and text forms.
Dataset Download
To download our dataset, please visit this link: Hugging Face.
Alternatively, you can also download it from Dropbox.
Run the following command:
wget -c "https://www.dropbox.com/scl/fi/irtbrnmk5e0ecvv8fyrum/audio_dataset.zip?rlkey=p1ebkt9h1bkyjsq3fo2bp667v&st=gxr542e2&dl=1" -O audio_dataset.zip
The dataset contains train, test, and validation splits with corresponding text descriptions and metadata stored as JSON files. All annotation files are located in the dataset-annotation-json folder in this GitHub.
Requirements
Recommended Hardware
8× NVIDIA H800 80GB or 8× NVIDIA H100 80GB GPUs.
Codebase and Compatibility
Our codebase is based on verl. If you are already familiar with verl, you should be able to quickly get started with this repository.
Environment Setup (Recommended: Anaconda)
- Python: Version >= 3.9
- CUDA: Version >= 12.1
For training and inference engines to utilize better and faster hardware support, CUDA/cuDNN and other dependencies are required, and some of the dependencies are easy to be overridden when installing other packages.
We need to install the following prerequisites:
- CUDA: Version >= 12.4
- cuDNN: Version >= 9.8.0
# change directory to anywhere you like, in verl source code directory is not recommended
wget https://developer.download.nvidia.com/compute/cudnn/9.8.0/local_installers/cudnn-local-repo-ubuntu2204-9.8.0_1.0-1_amd64.deb
dpkg -i cudnn-local-repo-ubuntu2204-9.8.0_1.0-1_amd64.deb
cp /var/cudnn-local-repo-ubuntu2204-9.8.0/cudnn-*-keyring.gpg /usr/share/keyrings/
apt-get update
apt-get -y install cudnn-cuda-12
Create and activate a new conda environment:
conda create -n alr python==3.10
conda activate alr
Install verl:
bash scripts/install_vllm_sglang_mcore.sh
pip install --no-deps -e .
Please make sure that the installed packages are not overridden during the installation of other packages.
The packages worth checking are:
- torch and torch series
- vLLM
- SGLang
- pyarrow
- tensordict
For Qwen2.5-Omni, we need to update some additional library versions.
pip install transformers==4.52.3
pip install accelerate
pip install qwen-omni-utils[decord] -U
Preprocessing Data
Our project and code rely on Audio Logical Reasoning (ALR) dataset.
Generate Parquet Format Dataset
- Option 1: Two modal inputs are used
cd ./examples/data_preprocess
python alr.py
- Option 2: Only texts are used
cd ./examples/data_preprocess
python alr_text.py
- Option 3: Only audio is used
cd ./examples/data_preprocess
python alr_audio.py
Checkpoint Download
To download our model checkpoint, please visit this link: Checkpoint Link
Run the following command:
wget -c "https://www.dropbox.com/scl/fi/f24wyecnycfu6g6ip10ac/qwen2_5_omni_logic.zip?rlkey=xlixctyr8cbfpv85arhka0b8c&st=wd5rlh9b&dl=1" -O qwen2_5_omni_logic.zip
RL-Training & Evaluation
If you don't want to use the pre-trained model we provided, you can use the official version. You can change the model path implementation in download_qwen25omni.py and main_grpo.sh.
Run the following command:
python download_qwen25omni.py
bash main_grpo.sh
✏️ Citation
If you think this project is helpful, please feel free to leave a star⭐️ and cite our paper:
@article{diao2025soundmind,
  title={SoundMind: RL-Incentivized Logic Reasoning for Audio-Language Models},
  author={Diao, Xingjian and Zhang, Chunhui and Kong, Keyi and Wu, Weiyi and Ma, Chiyu and Ouyang, Zhongyu and Qing, Peijun and Vosoughi, Soroush and Gui, Jiang},
  journal={arXiv preprint arXiv:2506.12935},
  year={2025}
}
Explore related projects
ytdl-org/youtube-dl
Command-line program to download videos from YouTube.com and other video sites
141,500 starsexcalidraw/excalidraw
Virtual whiteboard for sketching hand-drawn like diagrams
135,396 starsgodotengine/godot
Godot Engine – Multi-platform 2D and 3D game engine
119,840 starsmrdoob/three.js
JavaScript 3D Library.
117,905 stars