
xLLM-AI/xllm has 1,618 GitHub stars and 330 forks. GitHot measured 0 stars in 24 hours. Last checked 2026-11-08 03:28 UTC. Last push 2026-11-02.
A high-performance inference engine for LLM, VLM, DiT and REC models, optimized for diverse AI accelerators. It is hosted in OpenAtom Foundation.
What you can do
- Top-tier Performance: Delivers high-throughput, low-latency inference through many advanced features.
- Mainstream Hardware Support: Purpose-built and deeply optimized for Chinese AI accelerators.
- Service-Engine Decoupled Architecture: Service layer handles scheduling and availability; engine layer handles computation.
- Enterprise-grade Deployment: Battle-tested at scale across JD.com's core retail business.
Measured star growth
- in 24h
- 0
- in 7 days
- Collecting history
- in 15 days
- Collecting history
- in 1 month
- Collecting history
Net star changes over overlapping periods, not daily totals. Missing measurements are left blank. Stars measure attention, not software quality.
README.md
Original


News
- 2026-08-27: 🎉 We day-0 support the GLM-5.3-Flash model, please refer to the Deployment Document for deployment.
- 2026-07-06: 🎉 xLLM is officially donated to the OpenAtom Foundation!
- 2026-06-13: 🎉 We day-0 support the MiniMax-M3 model, please refer to the Deployment Document for deployment.
More News
- 2026-04-24: 🎉 We day-0 support the DeepSeek-V4 model, please refer to the Deployment Document for deployment.
- 2026-02-12: 🎉 We day-0 support high-performance inference for the GLM-5 model, please refer to the Deployment Document for deployment.
- 2025-12-21: 🎉 We day-0 support high-performance inference for the GLM-4.7 model.
- 2025-12-08: 🎉 We day-0 support high-performance inference for the GLM-4.6V model.
- 2025-12-05: 🎉 We now support high-performance inference for the GLM-4.5/GLM-4.6 series models.
- 2025-12-05: 🎉 We now support high-performance inference for the VLM-R1 model.
- 2025-12-05: 🎉 We build hybrid KV cache management based on Mooncake, supporting global KV cache management with intelligent offloading and prefetching.
- 2025-10-16: 🎉 We recently have released our xLLM Technical Report on arXiv, providing comprehensive technical blueprints and implementation insights.
Overview
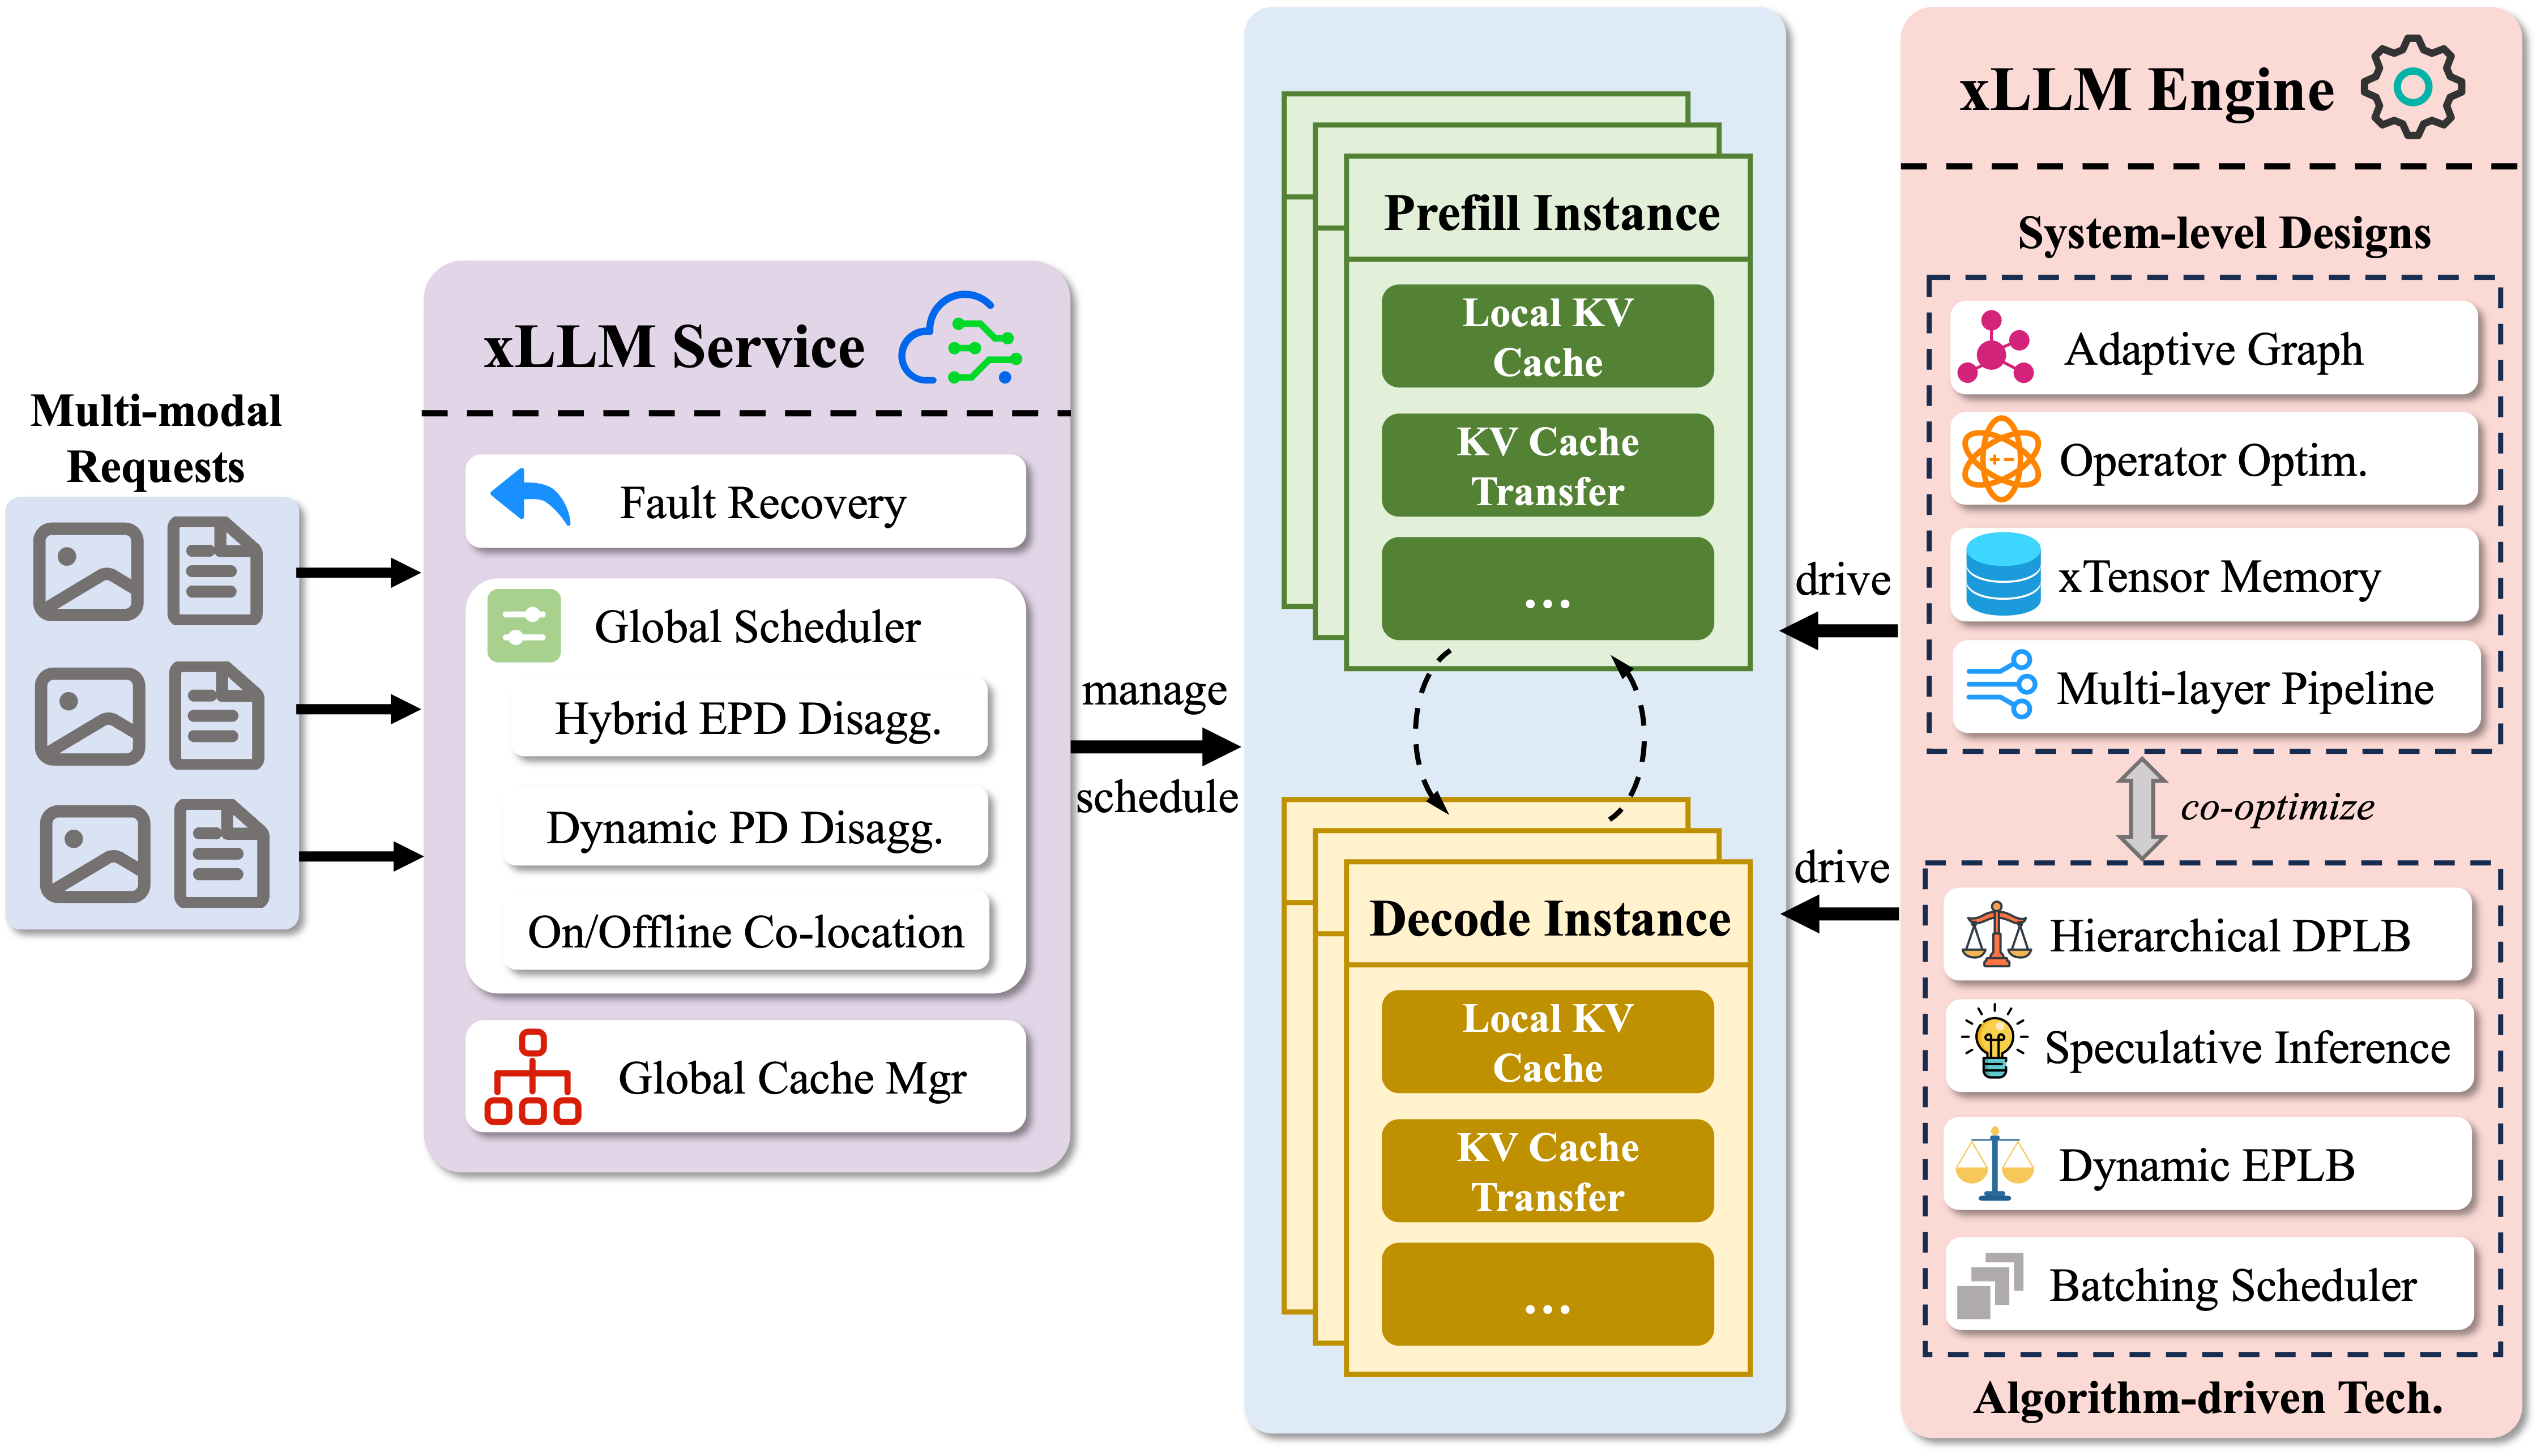
xLLM is an efficient LLM inference framework, specifically optimized for Chinese AI accelerators, enabling enterprise-grade deployment with enhanced efficiency and reduced cost.
Highlights
- Top-tier Performance: Delivers high-throughput, low-latency inference through many advanced features.
- Mainstream Hardware Support: Purpose-built and deeply optimized for Chinese AI accelerators.
- Service-Engine Decoupled Architecture: Service layer handles scheduling and availability; engine layer handles computation.
- Enterprise-grade Deployment: Battle-tested at scale across JD.com's core retail business.
Hardware Support
| Hardware | Abbreviation | Example | Remark |
|---|---|---|---|
| Ascend NPU | NPU | A2, A3 | HDK Driver 25.2.0 + |
| Cambricon MLU | MLU | MLU | |
| Moore Threads GPU | MUSA | S5000 | |
| Hygon DCU | DCU | BW1000 | |
| MetaX MACA | MACA | MXC500 | |
| Iluvatar CoreX GPU | ILU | BI150 |
Getting Started
Community & Support
Acknowledgment
This project was made possible thanks to the following open-source projects:
- ScaleLLM - xLLM draws inspiration from ScaleLLM's graph construction method and references its runtime execution.
- Mooncake - Build xLLM hybrid KV cache management based on Mooncake.
- brpc - Build high-performance http service based on brpc.
- tokenizers-cpp - Build C++ tokenizer based on tokenizers-cpp.
- safetensors - xLLM relies on the C binding safetensors capability.
- Partial JSON Parser - Implement xLLM's C++ JSON parser with insights from Python and Go implementations.
- concurrentqueue - A fast multi-producer, multi-consumer lock-free concurrent queue for C++11.
Thanks to the following collaborating university laboratories:
- THU-MIG (School of Software, BNRist, Tsinghua University)
- USTC-Cloudlab (Cloud Computing Lab, University of Science and Technology of China)
- Beihang-HiPO (Beihang HiPO research group)
- PKU-DS-LAB (Data Structure Laboratory, Peking University)
- PKU-NetSys-LAB (NetSys Lab, Peking University)
- TJU-TANKLab (TANK Lab, Tianjin University)
Thanks to all the following developers who have contributed to xLLM.
Citation
If you think this repository is helpful to you, welcome to cite us:
@article{liu2025xllm,
  title={xLLM Technical Report},
  author={xLLM team},
  journal={arXiv preprint arXiv:2510.14686},
  year={2025}
}
Explore related projects
affaan-m/ECC
The agent harness performance optimization system. Skills, instincts, memory, security, and research-first development for Claude Code, Codex, Opencode, Cursor and beyond.
299,268 starsNousResearch/hermes-agent
The agent that grows with you
261,556 starsmultica-ai/andrej-karpathy-skills
A single CLAUDE.md file to improve Claude Code behavior, derived from Andrej Karpathy's observations on LLM coding pitfalls.
230,666 starsfirecrawl/firecrawl
Supercharge your AI agents with data from the web and beyond. Building the library for superintelligence. 🔥
199,551 stars