
workofart/ml-by-hand
workofart/ml-by-hand has 110 GitHub stars and 16 forks. GitHot measured 0 stars in 24 hours, 0 in 7 days, and -1 in 15 days. Last checked 2026-11-15 16:00 UTC. Last push 2026-06-17.
Measured star growth
- in 24h
- 0
- in 7 days
- 0
- in 15 days
- -1
- in 1 month
- Collecting history
Net star changes over overlapping periods, not daily totals. Missing measurements are left blank. Stars measure attention, not software quality.
About
A deep learning library built from scratch with complex neural networks examples built on top for learning purposes.
Machine LearningREADME.md
OriginalML By Hand
 |
📝 Blog Post 1 |
📝 Blog Post 2 |
📊 GPT-2 Model Card
We are creating a deep learning library from scratch (that evolved from a simple autograd engine). It is designed to demystify the inner workings of building deep learning models by exposing every mathematical detail and stripping down the abstractions shiny ML libraries (e.g. PyTorch/TensorFlow) have. This project tries to provide an opportunity to learn deep learning from first-principles. And use the hand-built library to create and train state-of-art models (such as GPT-2 (Model Card)).
“What I cannot create, I do not understand.” — Richard Feynman
Key Principles
- Learn By Doing: All formulas and calculations are derived in code, so you see exactly how gradients (or derivatives) are computed—no hidden black boxes!
- Learning Over Optimization: Focus on understanding the underlying mathematics and algorithms, rather than optimizing for speed or memory usage (though we can still train GPT models on a single CPU)
- PyTorch-Like API: API interface closely mirrors PyTorch for low adoption overhead
- Minimal Dependencies: User code and examples should go through
autograd.backend.xp; that alias binds tonumpyby default,mlxon macOS when available, orcupyon CUDA Linux hosts.pytorchis used for gradient correctness checks in unit tests.
Why build a deep learning library from scratch?
This project initially took inspiration from Micrograd, which was trying to build an Autograd (Wikipedia) engine from scratch for educational purposes. An autograd engine computes exact derivatives by tracking computations and applying the chain rule systematically. It enables neural networks to learn from errors and adjust parameters automatically. That's the core of deep learning. Then I started to add more features since everything seemed very straightforward after I had the initial building blocks (i.e. Tensor-level operations) implemented.
The primary motivation is to learn about neural networks from scratch and from first principles. There are many good ML libraries out there (e.g. Tensorflow, PyTorch, Scikit-learn, etc.) that are well-optimized and have a lot of features. But they often introduce lots of abstractions, which hide the underlying concepts and make it difficult to understand how they work. I believe, to better utilize those abstractions/libraries, we must first understand how everything works from the ground up. This is the guiding principle for this project. All mathematical and calculus operations are explicitly derived in the code without abstraction. Also, debugging a neural network, especially the backward() implementations of various functions (e.g. loss, and activation), offers a rewarding learning experience.
The goal is to keep the API interface as close as possible to PyTorch to reduce extra onboarding overhead and utilize it to validate correctness.
Demo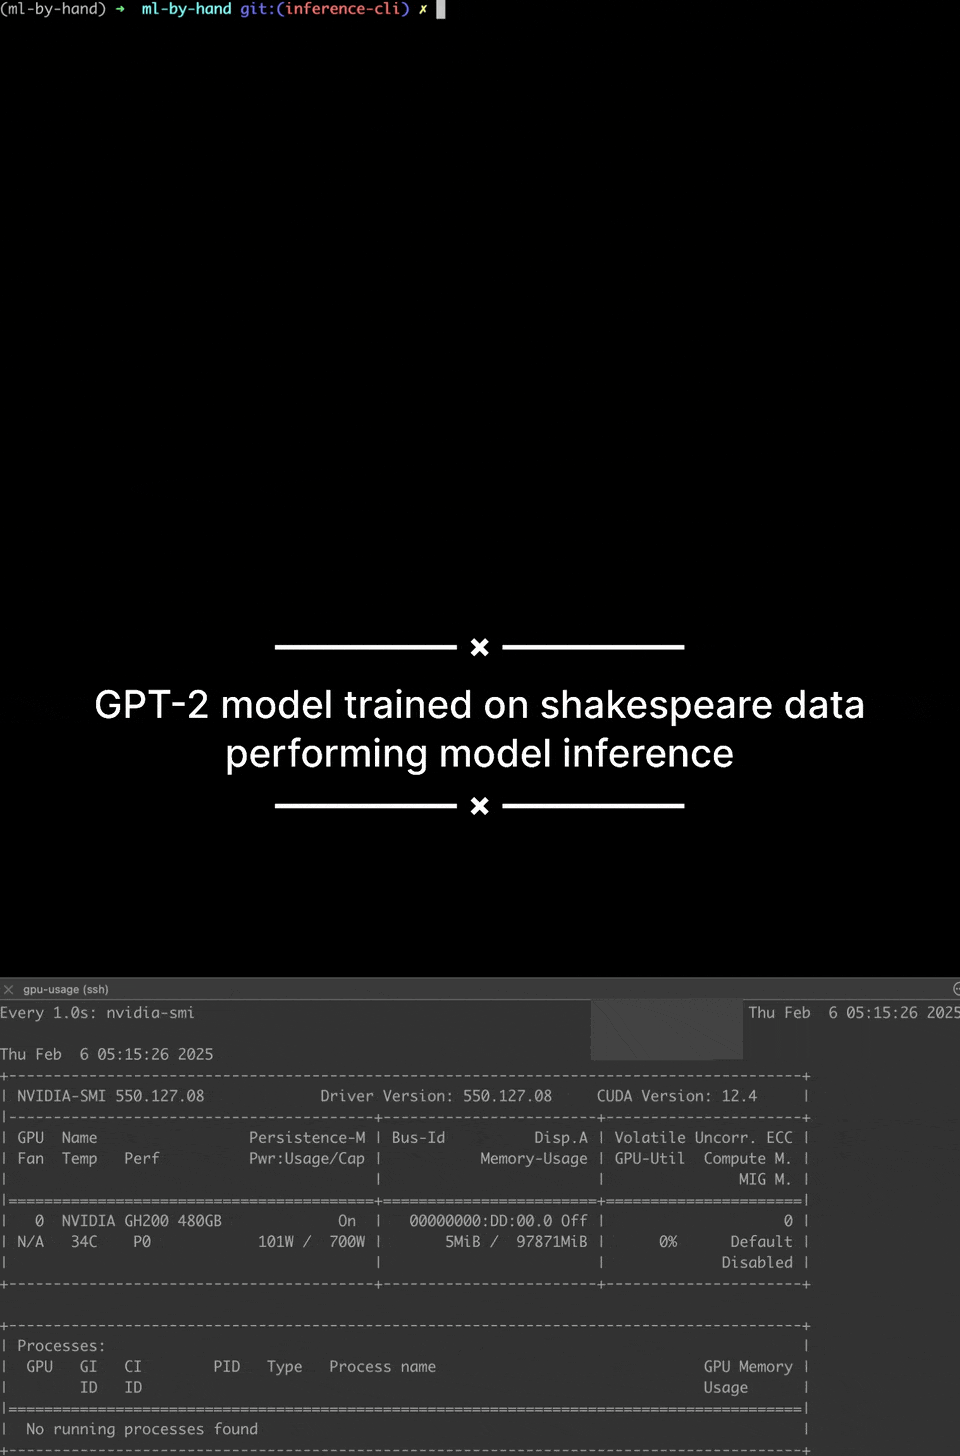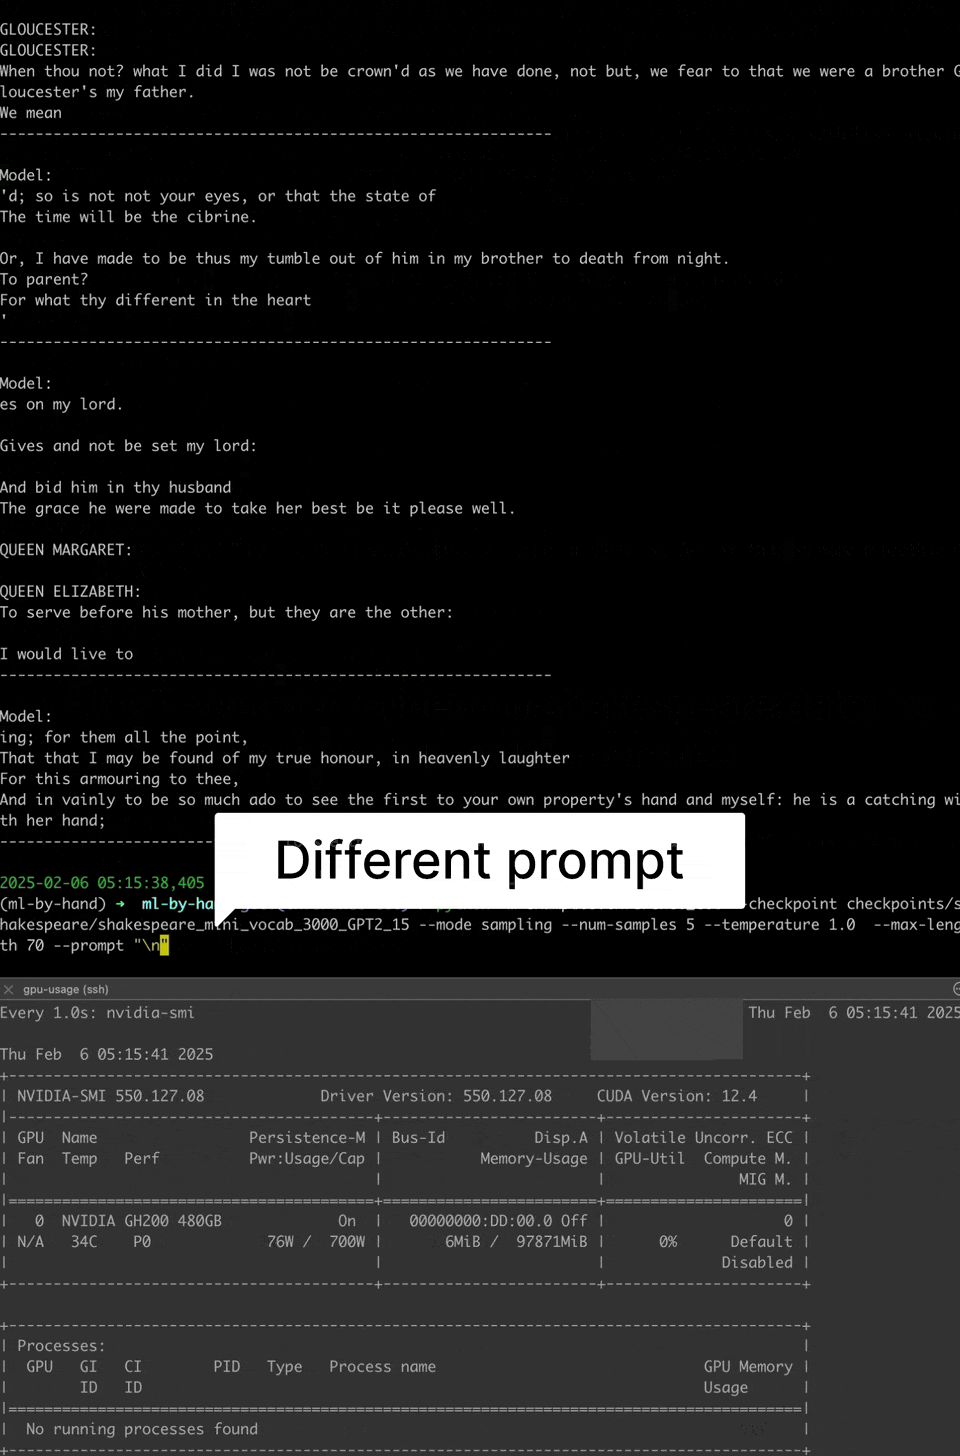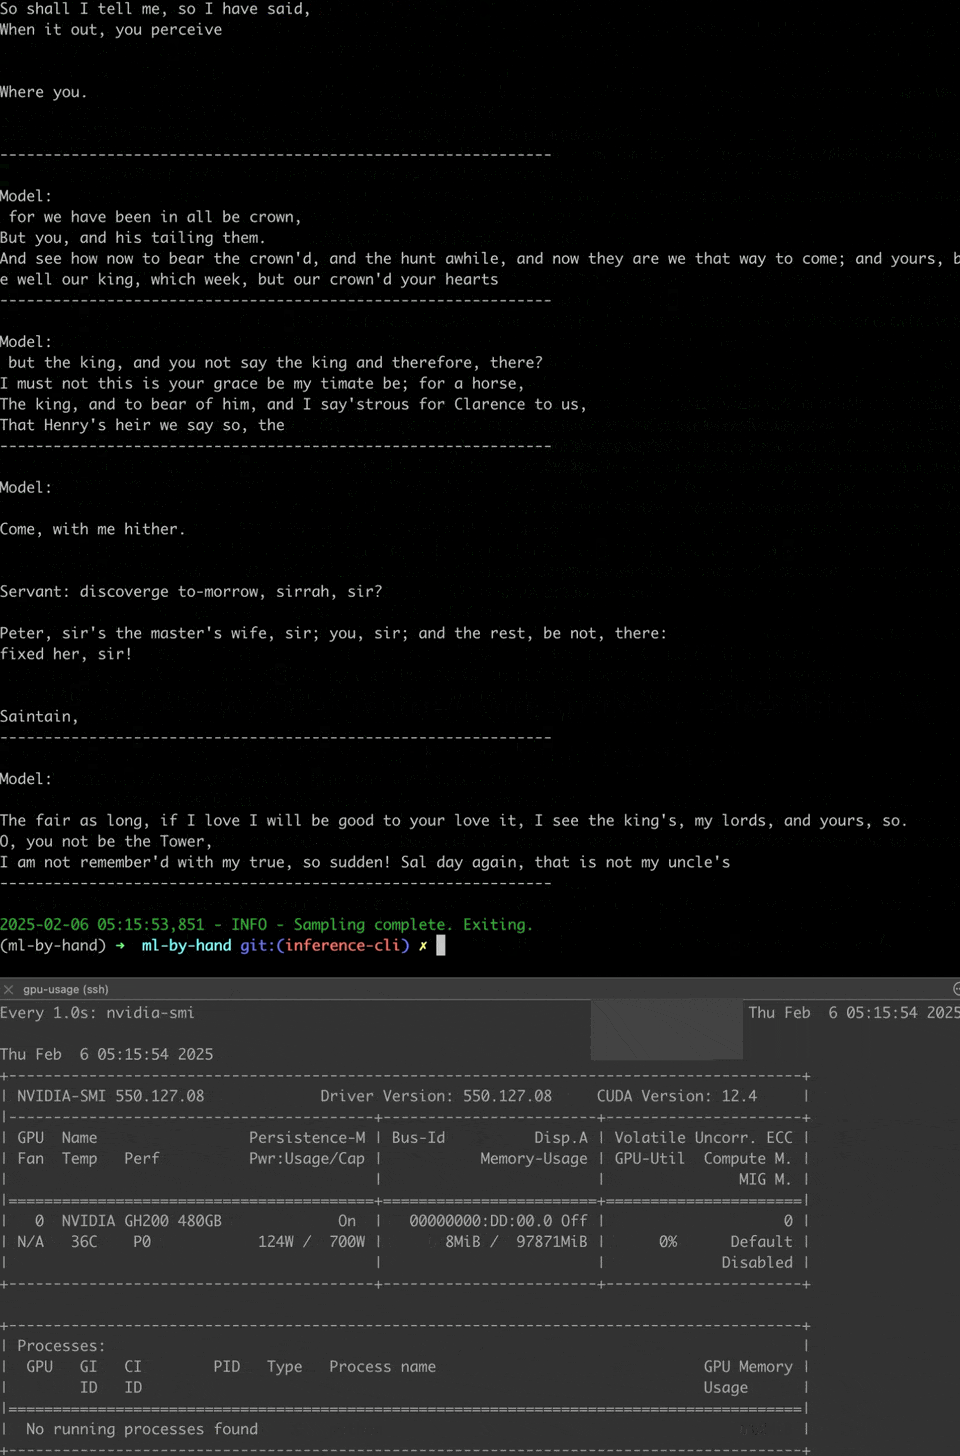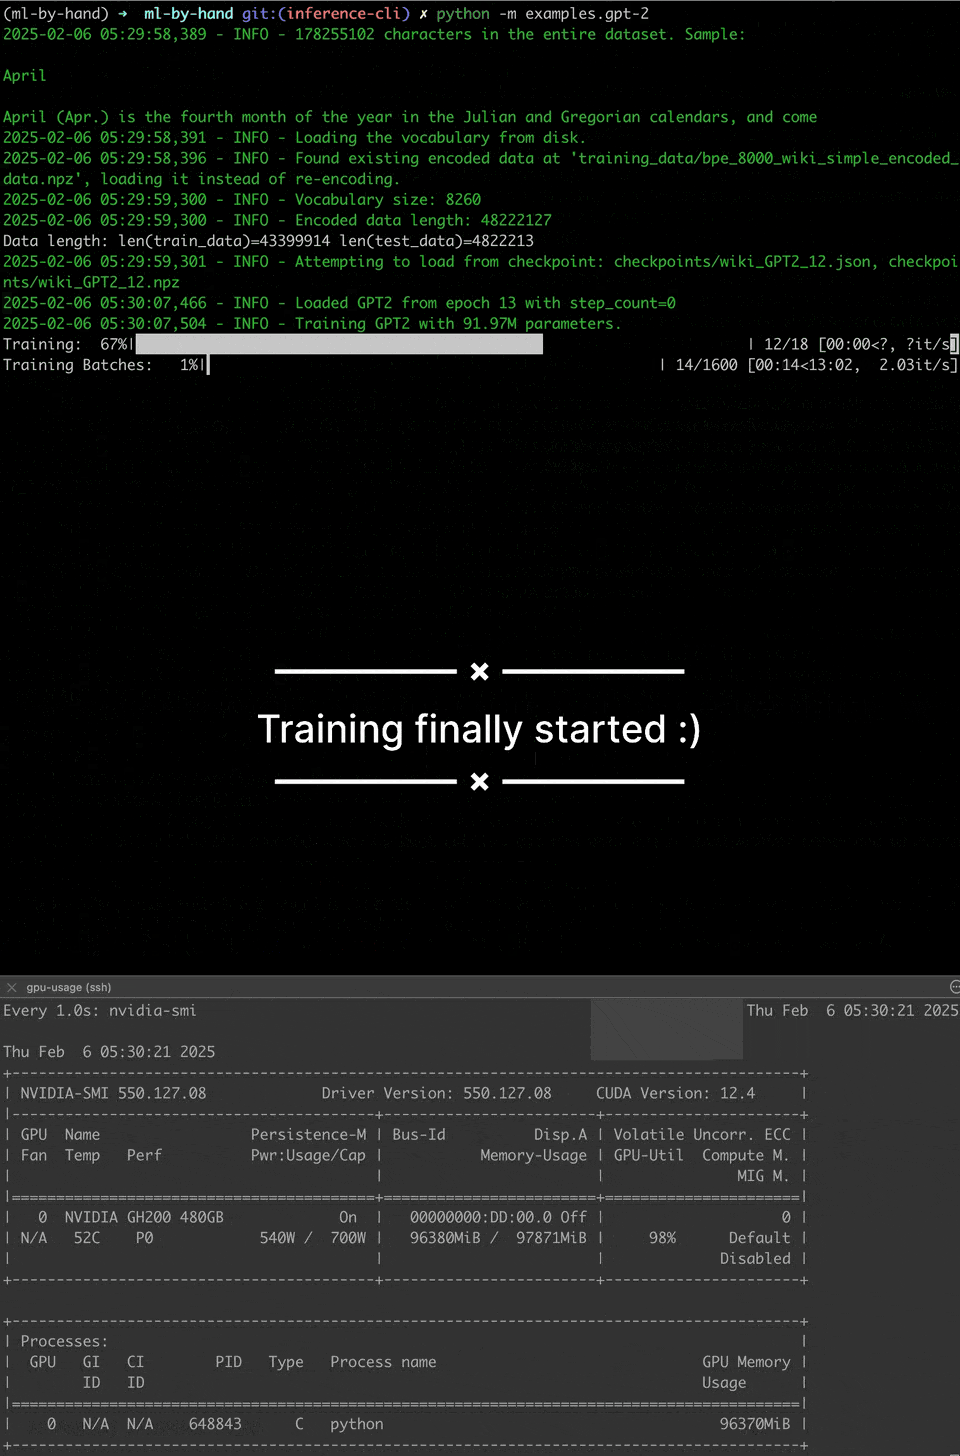 |
Try inference with the pre-trained checkpointUsing the library, we're able to pre-train GPT-2 124M model from scratch on OpenWebText (56k steps * 1024 context length * 480 global batch size = 27 billion tokens, bfloat16) at GitHub release, including its BPE tokenizer vocabulary. Download the weights (~240 MB) and run inference locally: Click to expandThen, from the repo root (after the Environment Setup below): |
ExamplesExplore the 📌 LLMs:
|
Toy Example of Using the LibraryClick to expand |
Environment Setup
This repo uses uv.lock as the source of truth for dependency installation:
./bootstrap.sh
source .venv/bin/activate
Documentation
Check out the modules in this project in the docs website built from the docs/ directory.
Hardware Backends
There are couple of hardware backends that are supported for acceleration, thanks to CuPy and MLX for the seemless NumPy-like primitive API.
Backend selection happens automatically. In user code, import and use autograd.backend.xp; the alias is then bound to one of these backends:
mlxis preferred when available on macOScupyis preferred on Linux when a CUDA device is detectedbootstrap.shauto-detects CUDA on Linux and syncs one of the pinned extras:cuda11,cuda12, orcuda13.- Manual installs are also available through
pyproject.tomlextras:
uv sync --extra dev --extra cuda12- Pick exactly one CUDA extra that matches your installed CUDA major version.
numpyis the fallback, which doesn't have any hardware acceleration
You can also force a backend explicitly:
AUTOGRAD_BACKEND=numpy uv run pytest
AUTOGRAD_BACKEND=mlx uv run pytest
AUTOGRAD_BACKEND=cupy uv run pytest
Tests
Comprehensive unit tests and integration tests available in test/autograd
uv run pytest
CI exercises both backend paths:
- MLX on
macos-latest - NumPy on
ubuntu-latest - CuPy auto-detection is available on CUDA Linux hosts, but is not covered by the current GitHub Actions matrix.
Future Work
- Expanding the autograd engine to power cutting-edge neural architectures
- Further performance tuning while maintaining clarity and educational value
- Interactive tutorials for newcomers to ML and advanced topics alike
Contributing
Contributions are welcome! If you find bugs, want to request features, or add examples, feel free to open an issue or submit a pull request.
License
MIT