
wookay/Octo.jl
wookay/Octo.jl has 170 GitHub stars and 8 forks. GitHot measured 0 stars in 24 hours and 0 in 7 days. Last checked 2026-11-09 22:18 UTC. Last push 2026-09-20.
Octo.jl 🐙 is an SQL Query DSL in Julia
Measured star growth
- in 24h
- 0
- in 7 days
- 0
- in 15 days
- Collecting history
- in 1 month
- Collecting history
Net star changes over overlapping periods, not daily totals. Missing measurements are left blank. Stars measure attention, not software quality.
README.md
OriginalOcto.jl
| Documentation | Build Status |
|---|---|
 |
  |
Octo.jl is an SQL Query DSL in Julia.
It also comes with a very useful tool called Repo.
You could Repo.get, Repo.insert! Repo.update! Repo.delete! for many database drivers without hand-written SQL.
It's influenced by Ecto.
- ☕️ You can make a donation to support this project.
SQL Query DSL
julia> using Octo.Adapters.SQL

julia> struct User
       end

julia> Schema.model(User, table_name="users")
| primary_key   | table_name   |
| ------------- | ------------ |
| id            | users        |

julia> u = from(User)
FromItem users

julia> [SELECT * FROM u]
SELECT * FROM users

julia> [SELECT (u.name, u.salary) FROM u]
SELECT name, salary FROM users

julia> [SELECT * FROM u WHERE u.id == 2]
SELECT * FROM users WHERE id = 2

julia> to_sql([SELECT * FROM u WHERE u.id == 2])
"SELECT * FROM users WHERE id = 2"

Repo
Current supported database drivers:
- PostgreSQL (via Postgres.jl)
- SQLite (via SQLite.jl)
- MySQL (via MySQL.jl)
- DuckDB (via duckdb/tools/juliapkg)
julia> using Octo.Adapters.PostgreSQL

julia> Repo.debug_sql()
LogLevelDebugSQL::RepoLogLevel = -1

julia> Repo.connect(
           adapter = Octo.Adapters.PostgreSQL,
           dbname = "postgresqltest",
           user = "postgres",
       )
Octo.Repo.Connection(false, "postgresqltest", Main.PostgreSQLLoader, Octo.Adapters.PostgreSQL, Postgres.Connection:
  host =
  user = postgres
  dbname = postgresqltest
  port = 5432
  status = open
  in_transaction = false
  statement_cache_size = 0/100
)

julia> struct Employee
       end

julia> Schema.model(Employee, table_name="Employee", primary_key="ID")
| primary_key   | table_name   |
| ------------- | ------------ |
| ID            | Employee     |

julia> Repo.execute([DROP TABLE IF EXISTS Employee])
[ Info: DROP TABLE IF EXISTS Employee

julia> Repo.execute(Raw("""
           CREATE TABLE Employee (
               ID SERIAL,
               Name VARCHAR(255),
               Salary FLOAT(8),
               PRIMARY KEY (ID)
           )"""))
┌ Info: CREATE TABLE Employee (
│     ID SERIAL,
│     Name VARCHAR(255),
│     Salary FLOAT(8),
│     PRIMARY KEY (ID)
└ )

julia> Repo.insert!(Employee, [
           (Name="Jeremy",  Salary=10000.50),
           (Name="Cloris",  Salary=20000.50),
           (Name="John",    Salary=30000.50),
           (Name="Hyunden", Salary=40000.50),
           (Name="Justin",  Salary=50000.50),
           (Name="Tom",     Salary=60000.50),
       ])
[ Info: INSERT INTO Employee (Name, Salary) VALUES ($1, $2) RETURNING ID    (Name = "Jeremy", Salary = 10000.5), (Name = "Cloris", Salary = 20000.5), (Name = "John", Salary = 30000.5), (Name = "Hyunden", Salary = 40000.5), (Name = "Justin", Salary = 50000.5), (Name = "Tom", Salary = 60000.5)
|   id |   num_affected_rows |
| ---- | ------------------- |
|    6 |                   6 |

julia> Repo.get(Employee, 2)
[ Info: SELECT * FROM Employee WHERE ID = 2
|   id | name     |    salary |
| ---- | -------- | --------- |
|    2 | Cloris   |   20000.5 |
1 row.

julia> Repo.get(Employee, 2:5)
[ Info: SELECT * FROM Employee WHERE ID BETWEEN 2 AND 5
|   id | name      |    salary |
| ---- | --------- | --------- |
|    2 | Cloris    |   20000.5 |
|    3 | John      |   30000.5 |
|    4 | Hyunden   |   40000.5 |
|    5 | Justin    |   50000.5 |
4 rows.

julia> Repo.get(Employee, (Name="Jeremy",))
[ Info: SELECT * FROM Employee WHERE Name = 'Jeremy'
|   id | name     |    salary |
| ---- | -------- | --------- |
|    1 | Jeremy   |   10000.5 |
1 row.

julia> Repo.query(Employee)
[ Info: SELECT * FROM Employee
|   id | name      |    salary |
| ---- | --------- | --------- |
|    1 | Jeremy    |   10000.5 |
|    2 | Cloris    |   20000.5 |
|    3 | John      |   30000.5 |
|    4 | Hyunden   |   40000.5 |
|    5 | Justin    |   50000.5 |
|    6 | Tom       |   60000.5 |
6 rows.

julia> Repo.insert!(Employee, (Name="Jessica", Salary=70000.50))
[ Info: INSERT INTO Employee (Name, Salary) VALUES ($1, $2) RETURNING ID    (Name = "Jessica", Salary = 70000.5)
|   id |   num_affected_rows |
| ---- | ------------------- |
|    7 |                   1 |

julia> Repo.update!(Employee, (ID=2, Salary=85000))
[ Info: UPDATE Employee SET Salary = $1 WHERE ID = 2    85000
|   num_affected_rows |
| ------------------- |
|                   1 |

julia> Repo.delete!(Employee, (ID=3,))
[ Info: DELETE FROM Employee WHERE ID = 3
|   num_affected_rows |
| ------------------- |
|                   1 |

julia> Repo.delete!(Employee, 3:5)
[ Info: DELETE FROM Employee WHERE ID BETWEEN 3 AND 5
|   num_affected_rows |
| ------------------- |
|                   2 |

julia> em = from(Employee)
FromItem Employee

julia> Repo.query(em)
[ Info: SELECT * FROM Employee
|   id | name      |    salary |
| ---- | --------- | --------- |
|    1 | Jeremy    |   10000.5 |
|    6 | Tom       |   60000.5 |
|    7 | Jessica   |   70000.5 |
|    2 | Cloris    |   85000.0 |
4 rows.

julia> Repo.query([SELECT * FROM em WHERE em.Name == "Cloris"])
[ Info: SELECT * FROM Employee WHERE Name = 'Cloris'
|   id | name     |    salary |
| ---- | -------- | --------- |
|    2 | Cloris   |   85000.0 |
1 row.

julia> Repo.query(em, (Name="Cloris",))
[ Info: SELECT * FROM Employee WHERE Name = 'Cloris'
|   id | name     |    salary |
| ---- | -------- | --------- |
|    2 | Cloris   |   85000.0 |
1 row.

julia> ❓ = Octo.PlaceHolder
PlaceHolder

julia> Repo.query([SELECT * FROM em WHERE em.Name == ❓], ["Cloris"])
[ Info: SELECT * FROM Employee WHERE Name = $1    "Cloris"
|   id | name     |    salary |
| ---- | -------- | --------- |
|    2 | Cloris   |   85000.0 |
1 row.
Subqueries
julia> sub = from([SELECT * FROM em WHERE em.Salary > 30000], :sub)
SubQuery (SELECT * FROM Employee WHERE Salary > 30000) AS sub

julia> Repo.query(sub)
[ Info: SELECT * FROM Employee WHERE Salary > 30000
|   id | name      |    salary |
| ---- | --------- | --------- |
|    6 | Tom       |   60000.5 |
|    7 | Jessica   |   70000.5 |
|    2 | Cloris    |   85000.0 |
3 rows.

julia> Repo.query([SELECT sub.Name FROM sub])
[ Info: SELECT sub.Name FROM (SELECT * FROM Employee WHERE Salary > 30000) AS sub
| name      |
| --------- |
| Tom       |
| Jessica   |
| Cloris    |
3 rows.
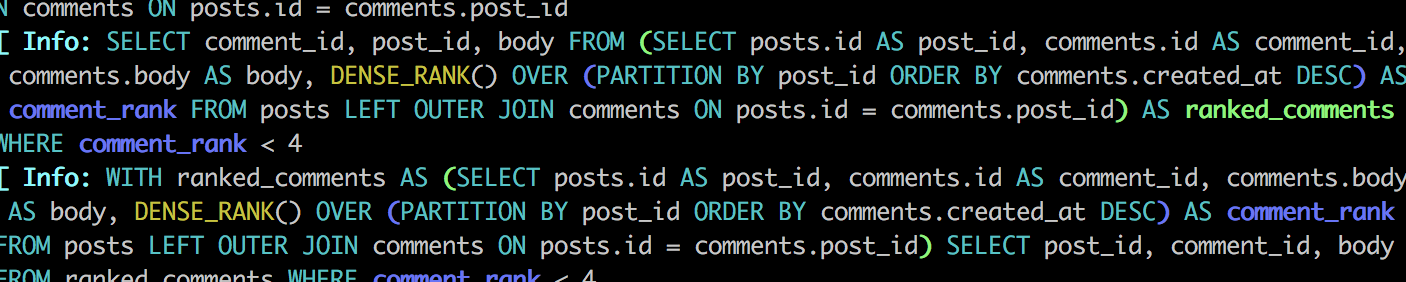
Colored SQL statements
Requirements
You need Julia.
julia> type ] key
(v1.11) pkg> add Octo
(v1.11) pkg> add Postgres # for PostgreSQL (depends on Postgres.jl 2.1)
(v1.11) pkg> add SQLite   # for SQLite     (depends on SQLite.jl 1.8)
(v1.11) pkg> add MySQL    # for MySQL      (depends on MySQL.jl 1.6)
(v1.11) pkg> add DuckDB   # for DuckDB     (depends on DuckDB.jl 1.5)
See also DBInterface.jl.
Explore related projects
Asabeneh/30-Days-Of-Python
The 30 Days of Python programming challenge is a step-by-step guide to learn the Python programming language in 30 days. This challenge may take more than 100 days. Follow your own pace. These videos may help too: https://www.youtube.com/channel/UC7PNRuno1rzYPb1xLa4yktw
78,423 starsgrafana/grafana
The open and composable observability and data visualization platform. Visualize metrics, logs, and traces from multiple sources like Prometheus, Loki, Elasticsearch, InfluxDB, Postgres and many more.
77,790 starsredis/redis
For developers, who are building real-time data-driven applications, Redis is the preferred, fastest, and most feature-rich cache, data structure server, and document and vector query engine.
77,309 starsapache/superset
Apache Superset is a Data Visualization and Data Exploration Platform
75,455 stars