
wkentaro/sam3-onnx
wkentaro/sam3-onnx has 126 GitHub stars and 23 forks. GitHot measured +1 stars in 24 hours. Last checked 2026-11-16 19:12 UTC. Last push 2026-11-13.
Measured star growth
- in 24h
- +1
- in 7 days
- Update delayed
- in 15 days
- Update delayed
- in 1 month
- Update delayed
Net star changes over overlapping periods, not daily totals. Missing measurements are left blank. Stars measure attention, not software quality.
About
ONNX export and inference for SAM3.
Developer ToolsREADME.md
Originalsam3-onnx
ONNX export and inference for SAM3, on the CPU, CUDA, CoreML, and WebGPU.
Quick start
git clone https://github.com/wkentaro/sam3-onnx.git --recursive && cd sam3-onnx

uvx hf download wkentaro/sam3-onnx-models-v0.7.0 --local-dir models  # download pre-exported models

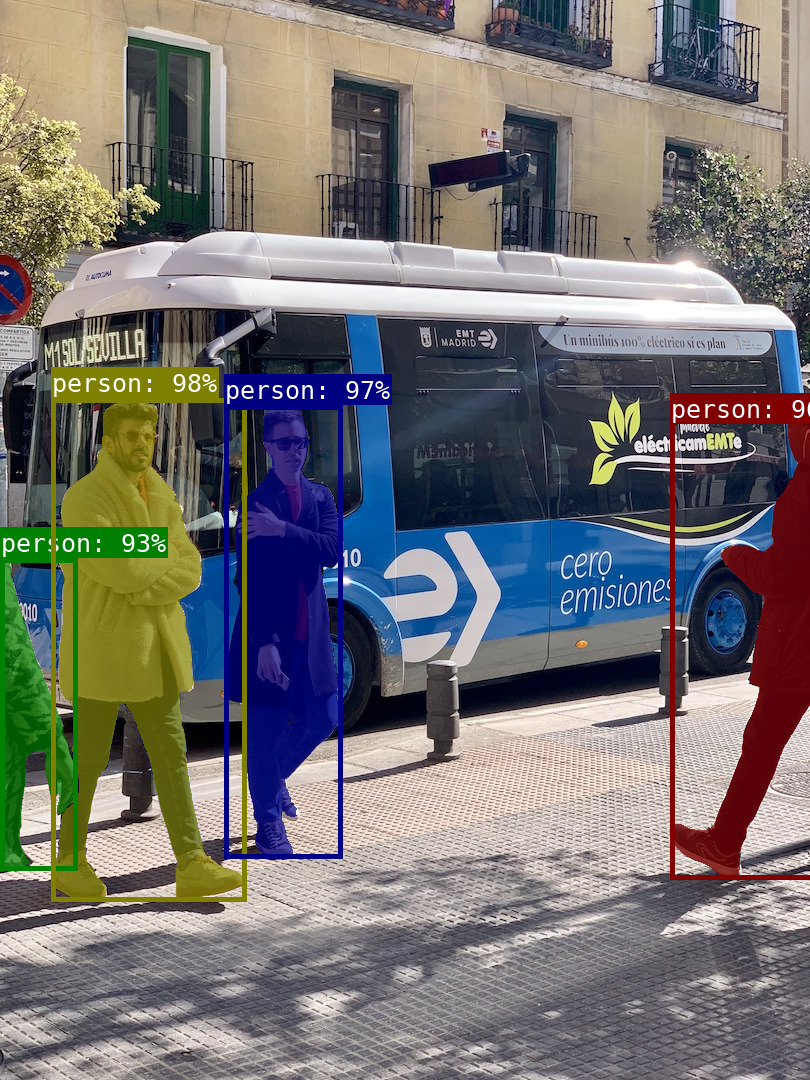
uv run --no-dev infer_onnx.py --image images/bus.jpg --text-prompt person
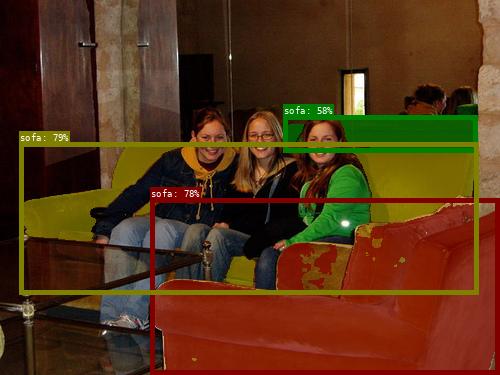
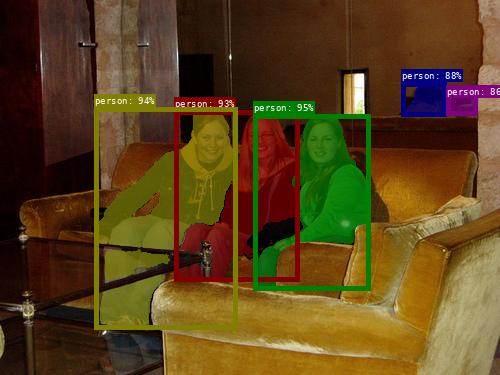
uv run --no-dev infer_onnx.py --image images/sofa.jpg --text-prompt sofa
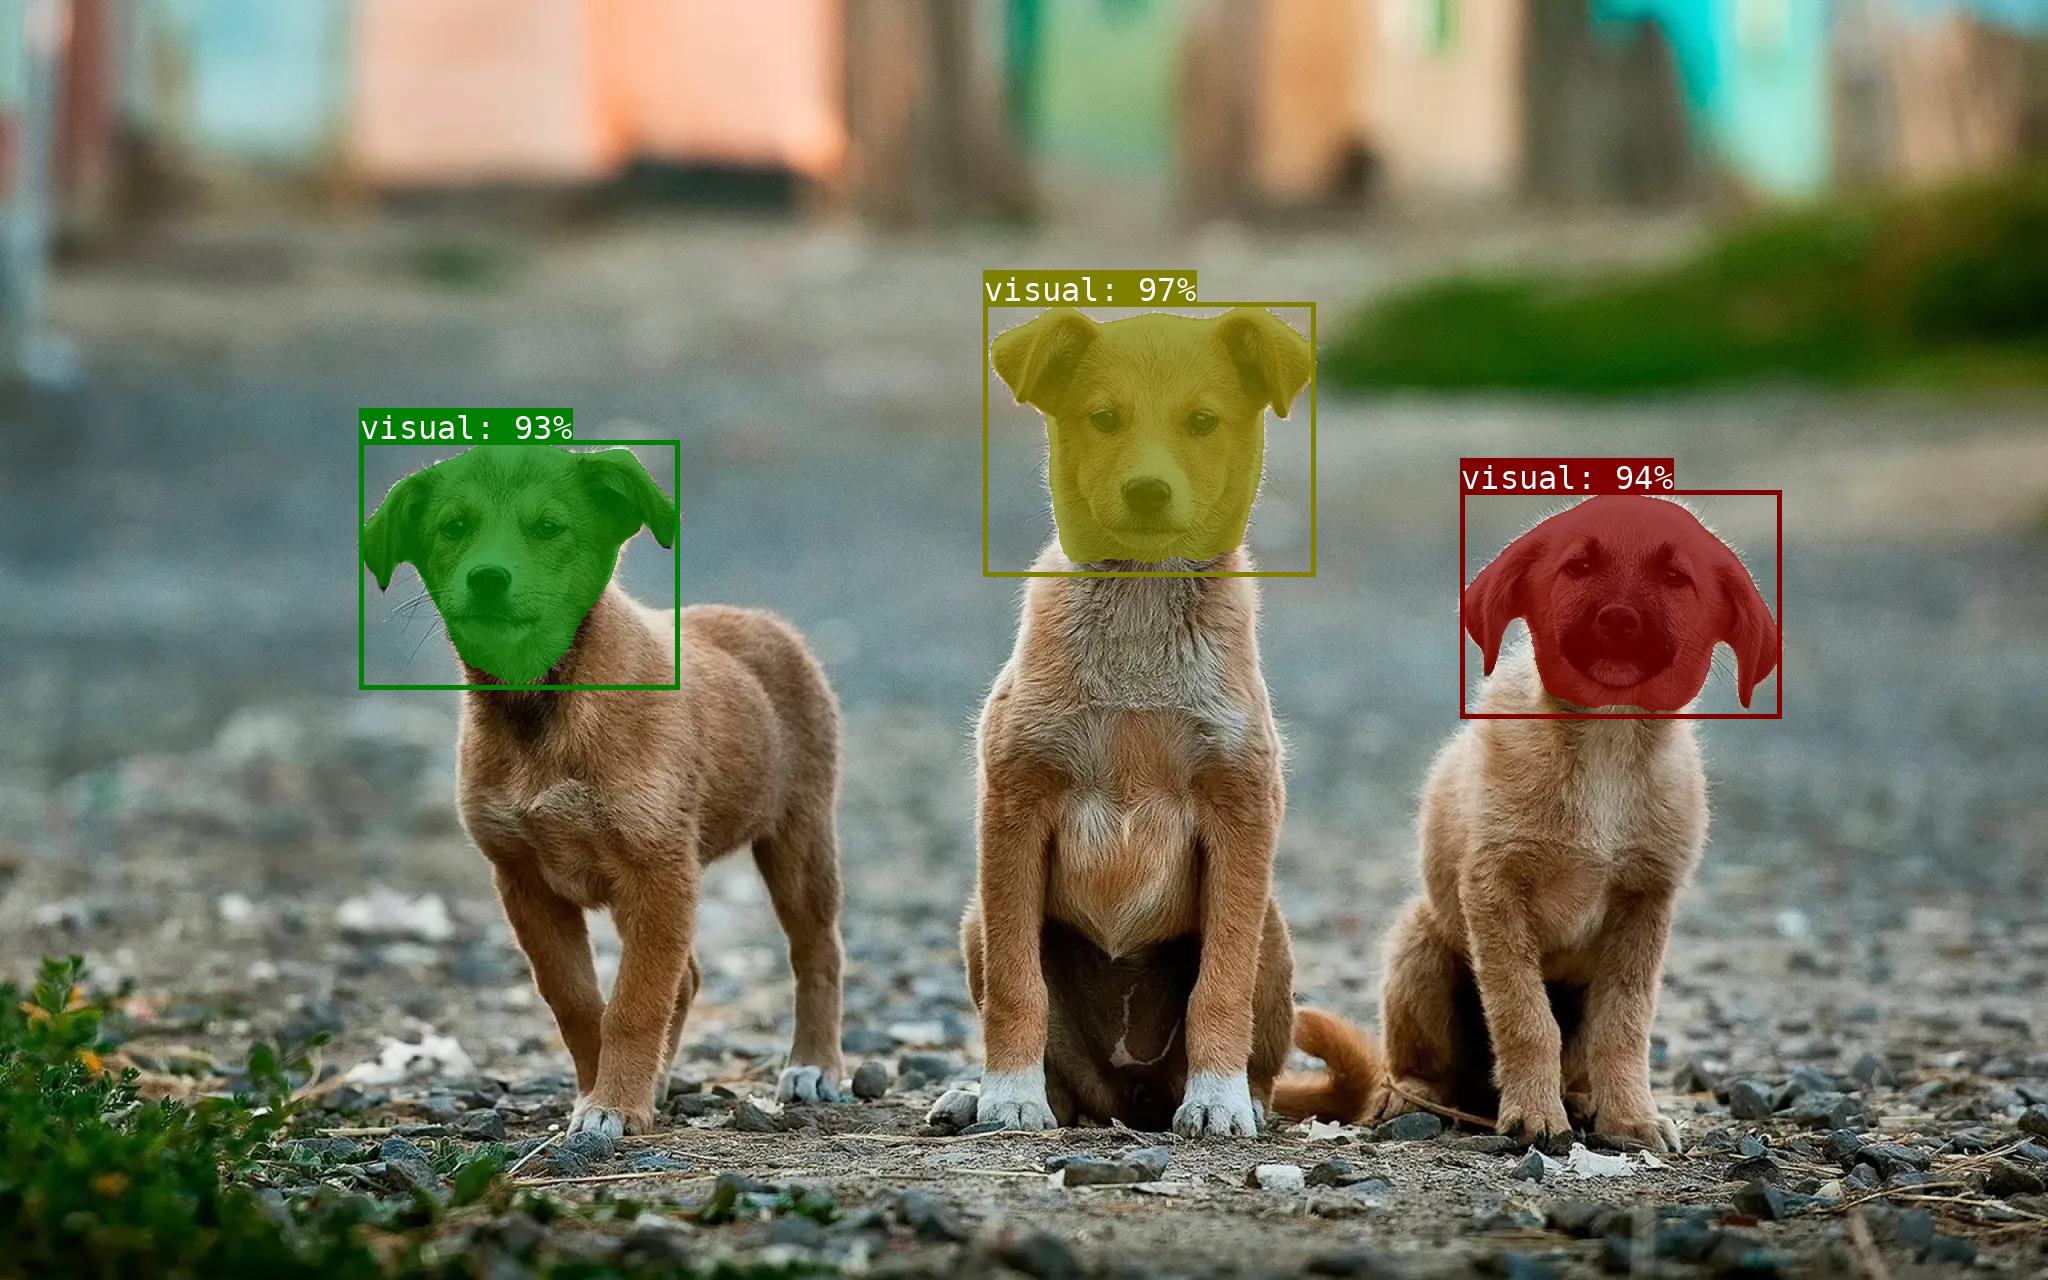
uv run --no-dev infer_onnx.py --image images/dog.jpg --box-prompt  # opens a gui to select box
Examples
uv run --no-dev infer_onnx.py --image images/bus.jpg --text-prompt person
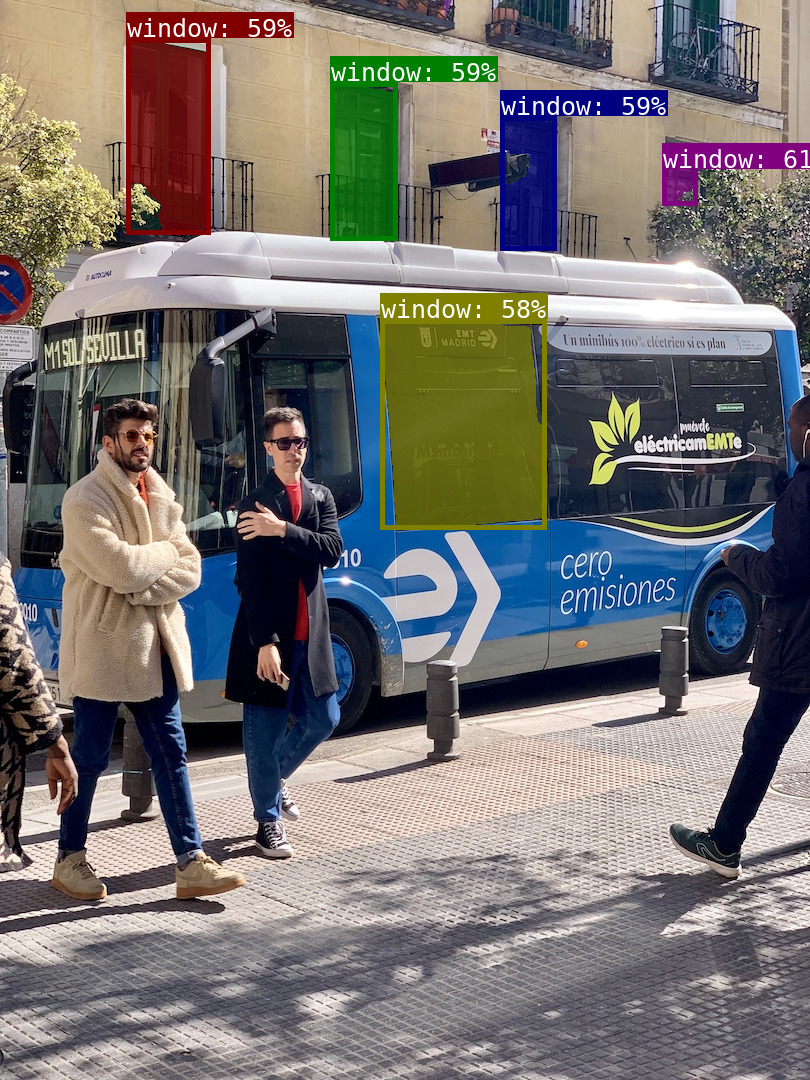
uv run --no-dev infer_onnx.py --image images/bus.jpg --text-prompt window
uv run --no-dev infer_onnx.py --image images/bus.jpg --box-prompt 0.547,0.656,0.042,0.091  # select a block
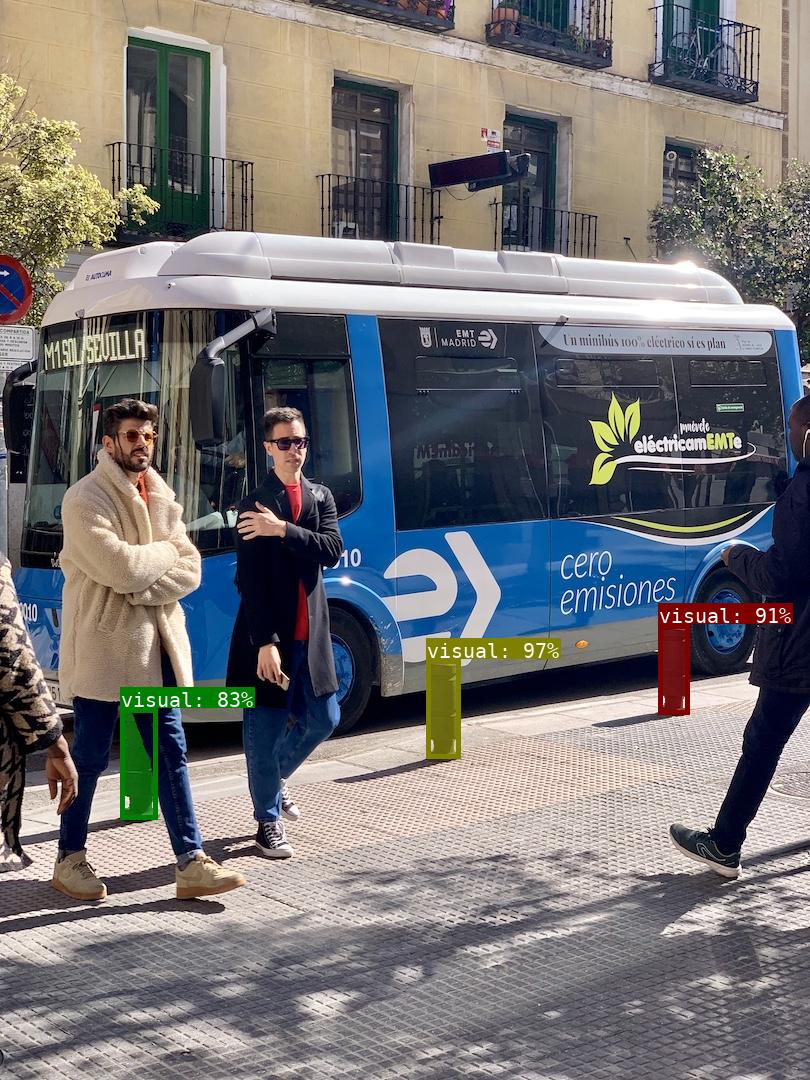
uv run --no-dev infer_onnx.py --image images/sofa.jpg --text-prompt person
uv run --no-dev infer_onnx.py --image images/sofa.jpg --text-prompt sofa
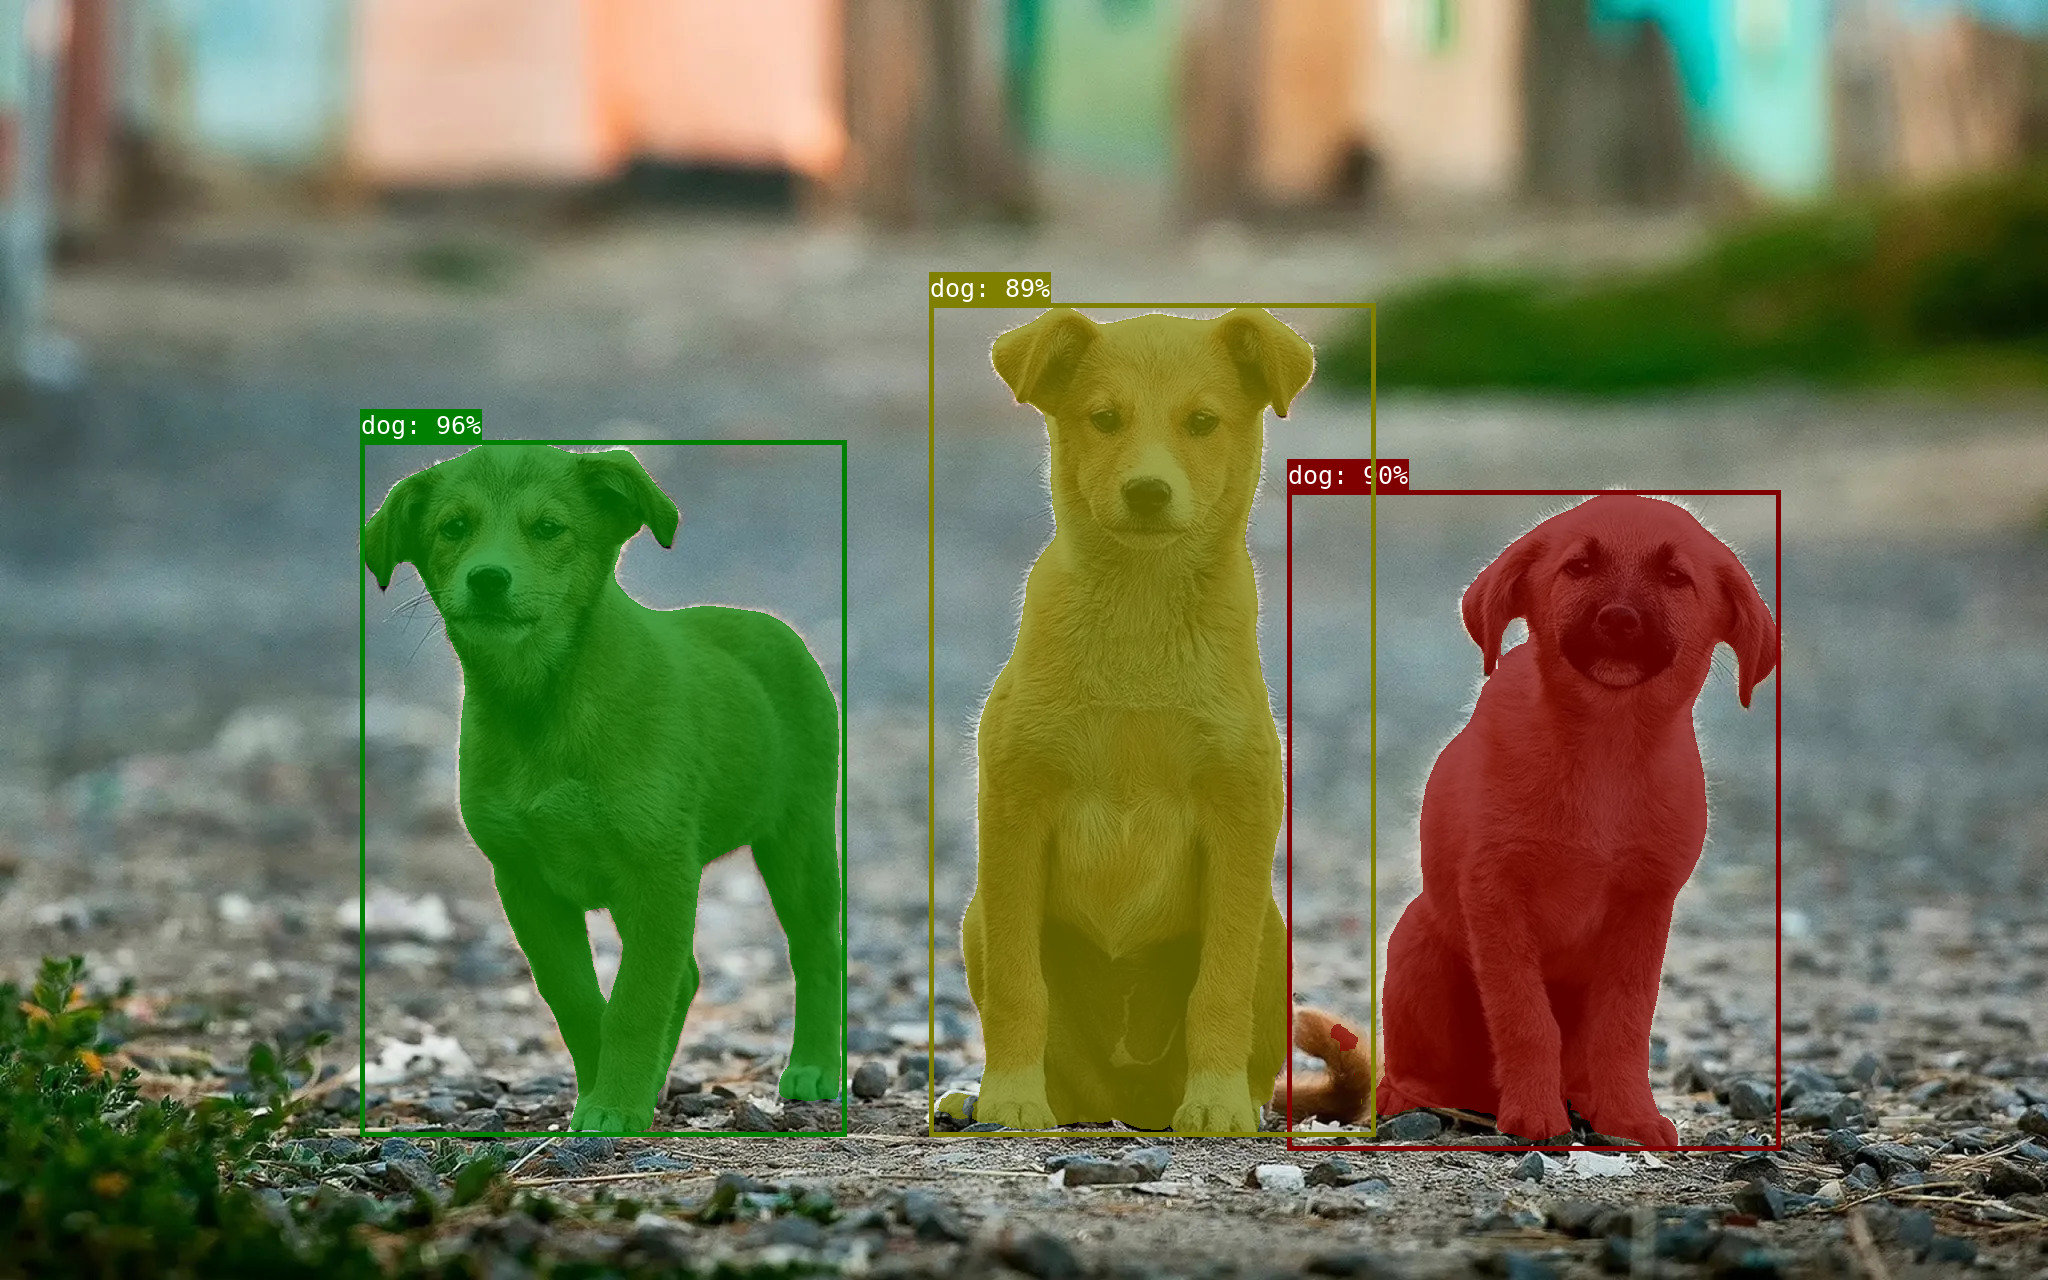
uv run --no-dev infer_onnx.py --image images/dog.jpg --text-prompt dog
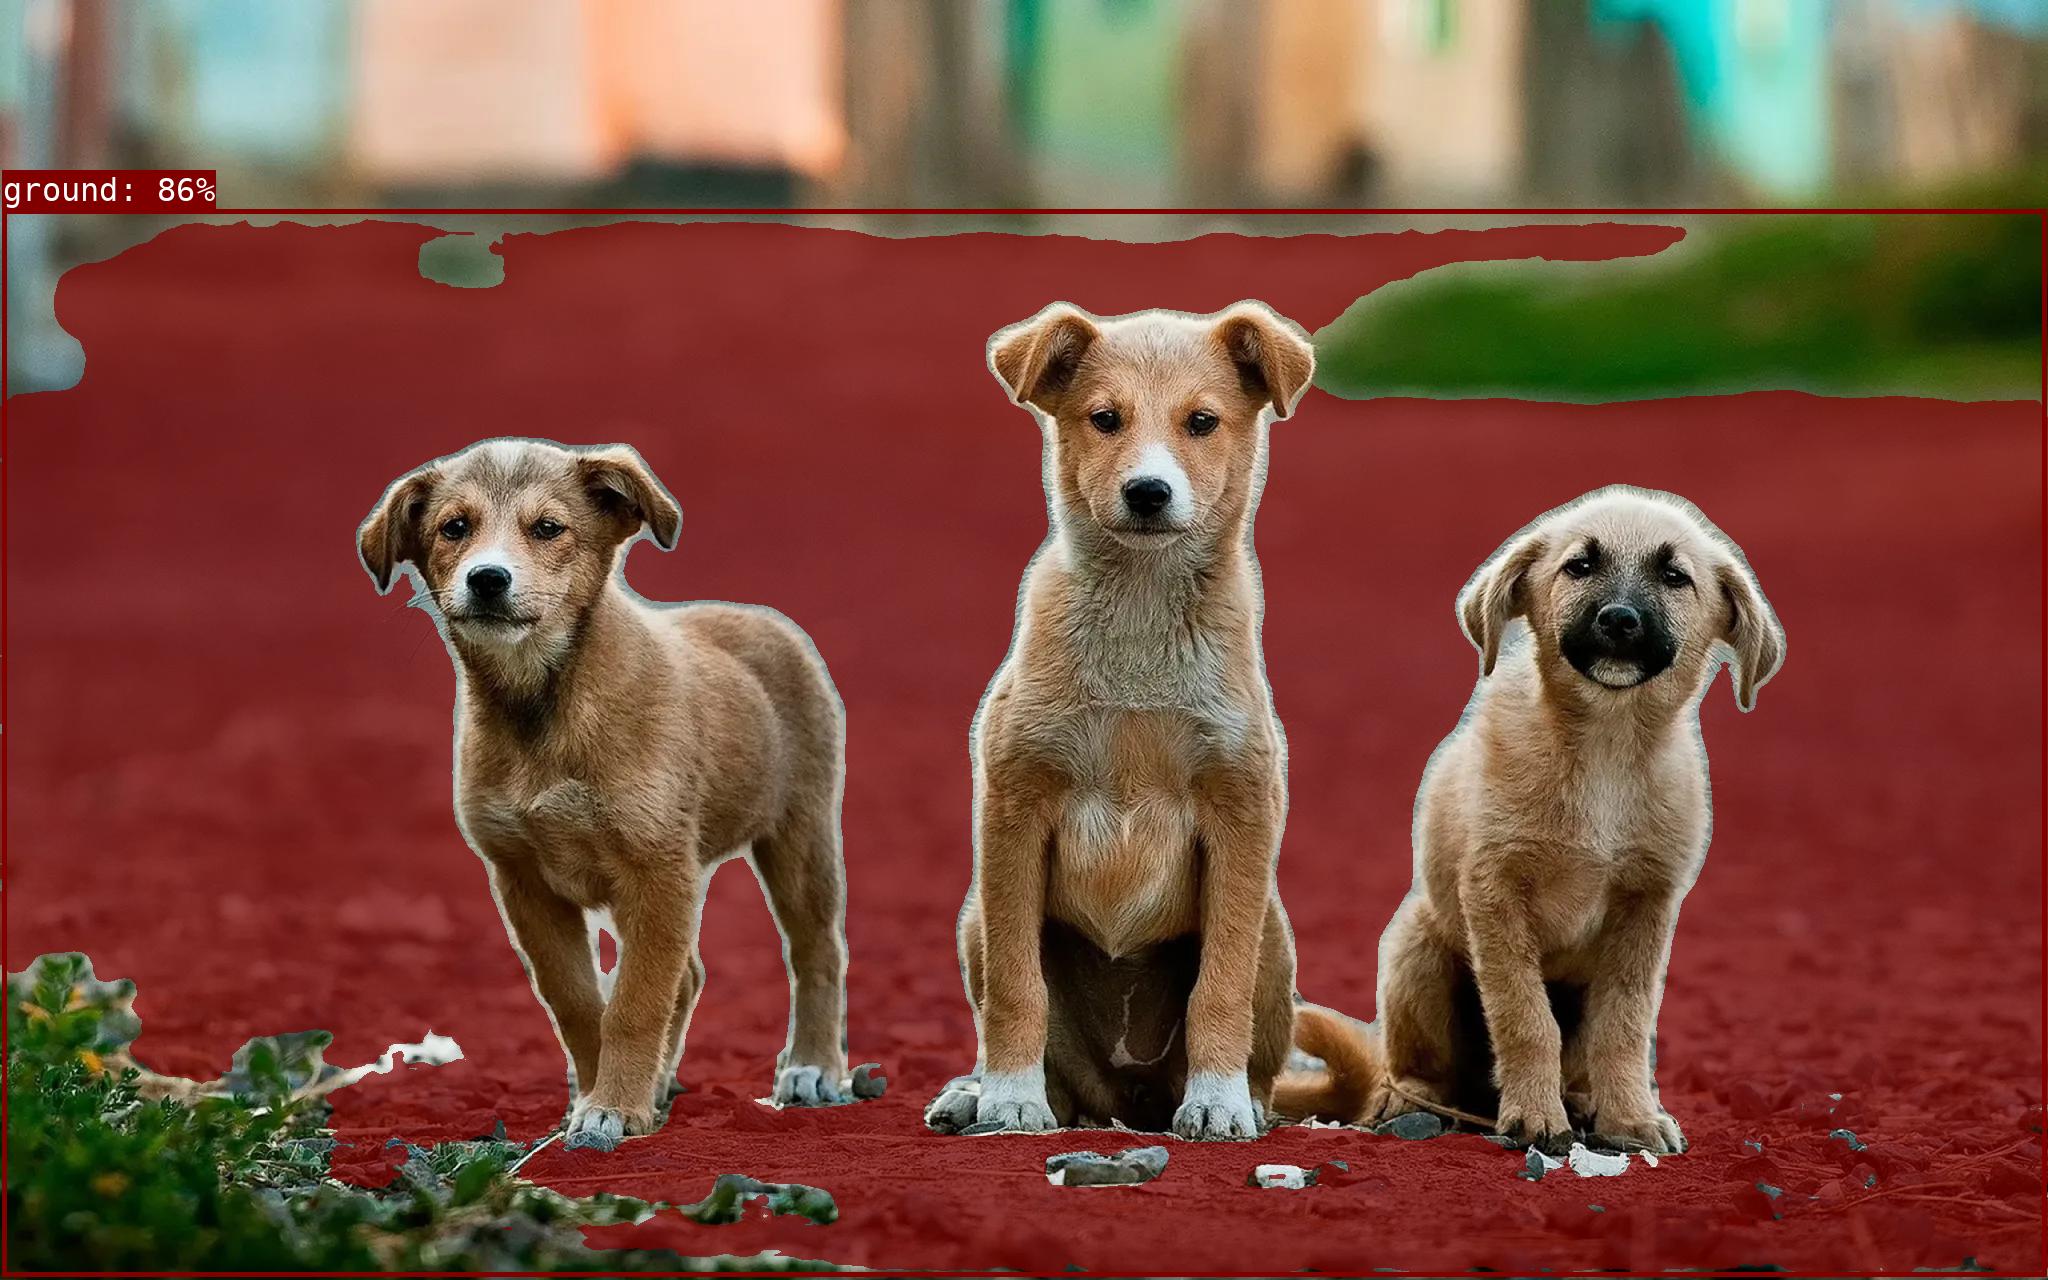
uv run --no-dev infer_onnx.py --image images/dog.jpg --text-prompt ground
uv run --no-dev infer_onnx.py --image images/dog.jpg --box-prompt 0.561,0.342,0.167,0.217
Usage
Image
uv run --no-dev infer_onnx.py --image images/bus.jpg --text-prompt person
uv run --no-dev infer_onnx.py --image images/bus.jpg --box-prompt  # opens a gui to select box
uv run --no-dev infer_onnx.py --image images/bus.jpg --point-prompt 0.18,0.55
A box is cx,cy,w,h[,label] and a point is x,y[,label], normalized, with label 0 for a negative example or the background. Both repeat, and a box combines with --text-prompt. Add --single-mask for one mask from several points.
Video
# find and track every person through the video
uv run --no-dev infer_video_onnx.py --video sam3/assets/videos/bedroom.mp4 --text-prompt person --output /tmp/bedroom.mp4
# track the object at a point or box
uv run --no-dev infer_video_onnx.py --video sam3/assets/videos/bedroom.mp4 --point-prompt 0.22,0.65 --output /tmp/bedroom.mp4
uv run --no-dev infer_video_onnx.py --video sam3/assets/videos/bedroom.mp4 --box-prompt 0.417,0.37,0.208,0.741 --output /tmp/bedroom.mp4
Devices
--device |
Runs on | Add |
|---|---|---|
cpu (default) |
the CPU | --int8 for an int8 image encoder, which takes 40% less time on an x86 CPU |
cuda |
an NVIDIA GPU | --fp16 |
coreml |
an Apple GPU, the fastest on a Mac after about 6 s of startup | --fp16 |
webgpu |
any GPU through Vulkan, Direct3D 12, or Metal, starting in about 1 s | --fp16 |
# cuda: the gpu group, in its own environment
UV_PROJECT_ENVIRONMENT=.venv-gpu uv run --no-dev --no-group cpu --group gpu infer_onnx.py --image images/bus.jpg --text-prompt person --device cuda --fp16

# coreml and webgpu: the webgpu group
uv run --no-dev --group webgpu infer_onnx.py --image images/bus.jpg --text-prompt person --device coreml --fp16
uv run --no-dev --group webgpu infer_onnx.py --image images/bus.jpg --text-prompt person --device webgpu --fp16
The gpu group installs onnxruntime-gpu with its CUDA and cuDNN libraries, so no system CUDA install is needed. Keep it in its own environment without the dev group: onnxruntime and onnxruntime-gpu overwrite each other's files, and so do the cuDNN libraries of torch and onnxruntime-gpu.
Speed
Milliseconds per image or tracked frame on an RTX 3080 Ti, with --fp16 against upstream PyTorch in bfloat16:
| Prompt | ONNX | PyTorch |
|---|---|---|
| Image, text | 172 | 176 |
| Image, point | 153 | 150 |
| Video, text | 254 | 258 |
| Video, 1 point | 180 | 187 |
| Video, 3 points | 242 | 234 |
On an M5 with --fp16, an image takes 1.2 s on CoreML and 2.4 s on WebGPU. See docs/performance.md for how each device runs the models, and how to run benchmark.py.
Export
uv sync  # the dev group, with PyTorch for the export

# models/*.onnx, on a CUDA GPU
uv run export_onnx.py

# float16 copies for --fp16
uv run postprocess_onnx.py --fp16 models/*.onnx

# an int8 image encoder for --int8
uv run postprocess_onnx.py --int8 models/sam3_image_encoder.onnx
More
- docs/performance.md: how each device runs the models, with the measurements
- docs/video-api.md: the Python API of video tracking
- docs/litetext.md: SAM3-LiteText, a distilled MobileCLIP language encoder whose license may limit it to non-commercial research
- docs/development.md: PyTorch inference, parity checks against PyTorch, and uploading models