
wilpel/caveman-compression
wilpel/caveman-compression has 1,115 GitHub stars and 68 forks. GitHot measured 0 stars in 24 hours. Last checked 2026-11-09 09:42 UTC. Last push 2025-12-03.
Caveman Compression is a semantic compression method for LLM contexts. It removes predictable grammar while preserving the unpredictable, factual content that defines meaning.
Measured star growth
- in 24h
- 0
- in 7 days
- Update delayed
- in 15 days
- Update delayed
- in 1 month
- Update delayed
Net star changes over overlapping periods, not daily totals. Missing measurements are left blank. Stars measure attention, not software quality.
README.md
Original


What is this?
Strip grammar. Keep facts. Save tokens.
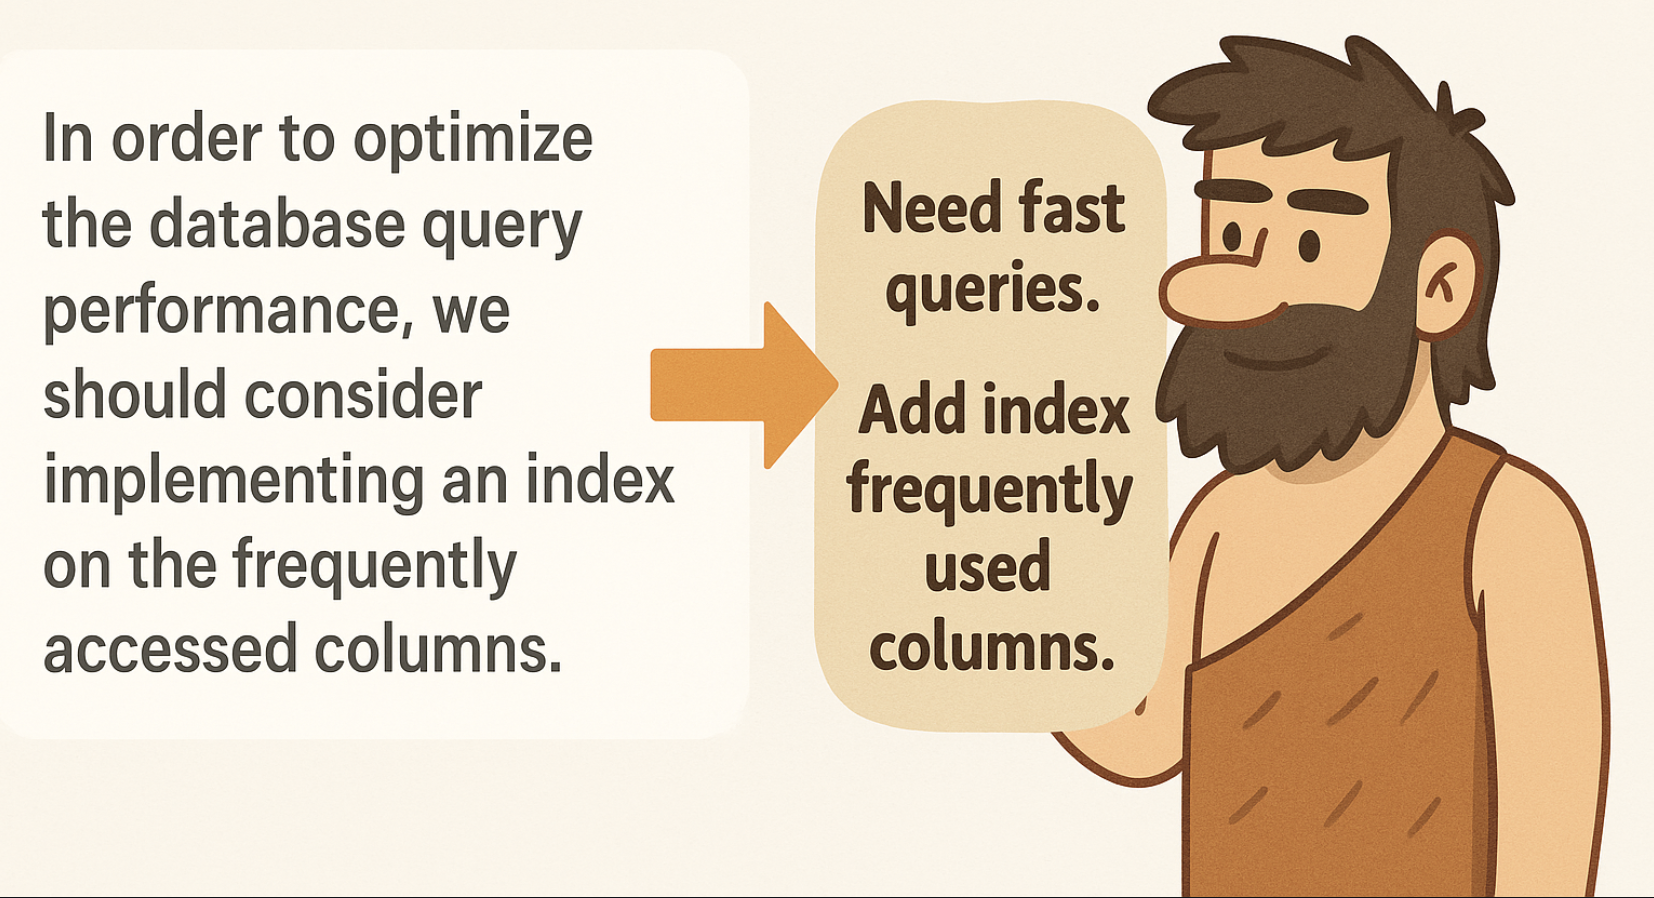
- "In order to optimize the database query performance, we should consider implementing an index on the frequently accessed columns..." (70 tokens)
+ "Need fast queries. Check which columns used most. Add index to those columns..." (50 tokens)

= 29% reduction
How It Works
LLMs excel at filling linguistic gaps. They predict missing grammar, connectives, and structure.
Key insight: We remove only what LLMs can reliably reconstruct.
What we remove (predictable):
- Grammar: "a", "the", "is", "are"
- Connectives: "therefore", "however", "because"
- Passive constructions: "is calculated by"
- Filler words: "very", "quite", "essentially"
What we keep (unpredictable):
- Facts: numbers, names, dates
- Technical terms: "O(log n)", "binary search"
- Constraints: "medium-large", "frequently accessed"
- Specifics: "Stockholm", "99.9% uptime"
Compressed: "Company medium-large. Location Stockholm."
Decompressed: "at a medium-large company based in Stockholm"
           ↑ grammar added, facts unchanged ↑
Quick Start
Installation
LLM-based (best compression, requires OpenAI API):
python3 -m venv venv
source venv/bin/activate
pip install -r requirements.txt

# Set up API key
cp .env.example .env
# Edit .env and add your OpenAI API key
NLP-based (free, offline, multilingual):
python3 -m venv venv
source venv/bin/activate
pip install -r requirements-nlp.txt
python -m spacy download en_core_web_sm  # or other language models
MLM-based (free, offline, predictability-aware):
python3 -m venv venv
source venv/bin/activate
pip install -r requirements-mlm.txt
python -m spacy download en_core_web_sm
Usage
NLP-based compression (most stable, 15-30% reduction, free, offline):
python caveman_compress_nlp.py compress "Your verbose text here"
python caveman_compress_nlp.py compress -f input.txt -o output.txt
python caveman_compress_nlp.py compress -f input.txt -l es  # specify language
MLM-based compression (20-30% reduction, free, offline, predictability-aware):
python caveman_compress_mlm.py compress "Your verbose text here"
python caveman_compress_mlm.py compress -f input.txt -o output.txt
python caveman_compress_mlm.py compress -f input.txt -k 30  # adjust compression level
LLM-based compression (40-58% reduction, requires API key):
python caveman_compress.py compress "Your verbose text here"
python caveman_compress.py compress -f input.txt -o output.txt
Decompress:
python caveman_compress.py decompress "Caveman text here"
Examples
Resume
| Normal (201 tokens) | Caveman (156 tokens) |
I am John Smith, a 32-year-old Senior Software Engineer at a large enterprise software company based in San Francisco, California. I have over 8 years of experience in backend development, distributed systems, and database optimization. Throughout my career, I have successfully designed and implemented scalable microservices... |
John Smith. 32 years old. Senior Software Engineer. Large enterprise software company. San Francisco, California. 8 years experience. Backend development, distributed systems, database optimization. Designed scalable microservices. 50 million requests daily... |
| 22% reduction |
System Prompt
| Normal (171 tokens) | Caveman (72 tokens) |
You are a helpful AI assistant designed to provide accurate and concise responses to user queries. When answering questions, you should always prioritize clarity and correctness over speed. If you are uncertain about any information, you must explicitly state your uncertainty... |
Helpful AI assistant. Provide accurate, concise responses. Prioritize clarity, correctness. If uncertain, state uncertainty. Break complex problems into smaller steps. Explain reasoning clearly... |
| 58% reduction |
API Documentation
| Normal (137 tokens) | Caveman (79 tokens) |
To authenticate with our API, you need to include your API key in the Authorization header of every request. The API key should be prefixed with the word "Bearer" followed by a space. If authentication fails, the server will return a 401 Unauthorized status code... |
Authenticate API. Include API key in Authorization header every request. Prefix API key with "Bearer" space. Authentication fail, server return 401 Unauthorized status code, error message explain fail... |
| 42% reduction |
Benchmarks
Factual Preservation
Automated benchmark verifying that specific facts are preserved and retrievable after compression:
# LLM-based compression
python benchmark/factual_preservation/run_factual_benchmark.py

# NLP-based compression
python benchmark/factual_preservation/run_factual_benchmark_nlp.py
Results: 13/13 facts preserved (100%) with 12-25% compression ratio.
See benchmark/factual_preservation/ for details.
Example Reductions
| Test Case | Original | Compressed | Reduction |
|---|---|---|---|
| System prompt | 171 tokens | 72 tokens | 58% |
| API documentation | 137 tokens | 79 tokens | 42% |
| Resume | 201 tokens | 156 tokens | 22% |
| Average | 170 | 102 | 40% |
All examples validated with GPT-4o. See examples/ for full text.
Core Principles
- Strip connectives - Remove: therefore, however, because, in order to
- 2-5 words per sentence - One atomic thought per sentence
- Action verbs - Prefer: do, make, fix, check vs facilitate, optimize
- Be concrete - "test five, test six" not "test values 5-6"
- Active voice - "calculate value" not "value is calculated"
- Keep meaningful info - Numbers, sizes, names, constraints stay
See SPEC.md for full rules.
Use Cases
RAG Knowledge Base (199→118 tokens, 41%)
Original:
A network router is a device that forwards data packets between computer networks. Routers perform the traffic directing functions on the Internet. When a data packet arrives at a router, the router examines the destination IP address...
Compressed:
Network router forwards data packets. Routers direct Internet traffic. Packet arrives router. Router examines destination IP address. Router determines best path. Router uses routing table...
Why it works: Store compressed docs in vector DB. Agent receives compressed RAG results directly. No decompression needed—agent understands caveman format. Fits 2-3x more context.
Agent Internal Reasoning (196→102 tokens, 48%)
Original:
First, I need to understand what the user is asking for. They want to calculate the optimal route between two cities considering both distance and traffic conditions. Let me break this down into steps. Step one: I should identify the starting city...
Compressed:
Need understand user request. User wants optimal route between cities. Consider distance, traffic. Step one: Identify starting city, destination city. Step two: Retrieve current traffic data for routes...
Why it works: Agent thinks in caveman format during problem-solving. Chain-of-thought uses 50% fewer tokens. More reasoning steps fit in context window.
Compression Methods
LLM-based (caveman_compress.py)
- Reduction: 40-58%
- Cost: Requires OpenAI API key
- Quality: Best compression, context-aware
- Speed: ~2s per request
- Use when: Maximum token savings needed
MLM-based (caveman_compress_mlm.py)
- Reduction: 20-30%
- Cost: Free
- Quality: Excellent compression, predictability-aware using RoBERTa
- Speed: ~1-5s per document (local model)
- Method: Removes top-k most predictable tokens based on masked language model probabilities
- Use when: Need better compression than NLP without API costs, can tolerate model download (~500MB) and initial loading time
NLP-based (caveman_compress_nlp.py)
- Reduction: 15-30%
- Cost: Free
- Quality: Good compression, rule-based
- Speed: <100ms
- Languages: 15+ supported (en, es, de, fr, it, pt, nl, el, nb, lt, ja, zh, pl, ro, ru, and more)
- Use when: Working offline, processing large volumes, no API budget, or need multilingual support
When to Use
✅ Good for:
- LLM reasoning/thinking blocks
- Token-constrained contexts
- Internal documentation
- Step-by-step instructions
❌ Avoid for:
- User-facing content
- Marketing copy
- Legal documents
- Emotional communication
Documentation
- SPEC.md - Full specification and rules
- examples/ - Before/after samples
- benchmark/ - Semantic losslessness tests
- prompts/compression.txt - System prompt for compression
- prompts/decompression.txt - System prompt for decompression
Contributing
Contributions welcome. Submit issues or PRs.
License
MIT
Author
William Peltomäki
Inspired by TOON and the token-optimization movement.
Explore related projects
affaan-m/ECC
The agent harness performance optimization system. Skills, instincts, memory, security, and research-first development for Claude Code, Codex, Opencode, Cursor and beyond.
300,295 starsNousResearch/hermes-agent
The agent that grows with you
262,115 starsmultica-ai/andrej-karpathy-skills
A single CLAUDE.md file to improve Claude Code behavior, derived from Andrej Karpathy's observations on LLM coding pitfalls.
231,433 starsfirecrawl/firecrawl
Supercharge your AI agents with data from the web and beyond. Building the library for superintelligence. 🔥
200,178 stars