
voice-cloning-app/Voice-Cloning-App
voice-cloning-app/Voice-Cloning-App has 1,438 GitHub stars and 237 forks. GitHot measured 0 stars in 24 hours and +1 in 7 days. Last checked 2026-11-12 06:20 UTC. Last push 2024-12-02.
A Python/Pytorch app for easily synthesising human voices
What you can do
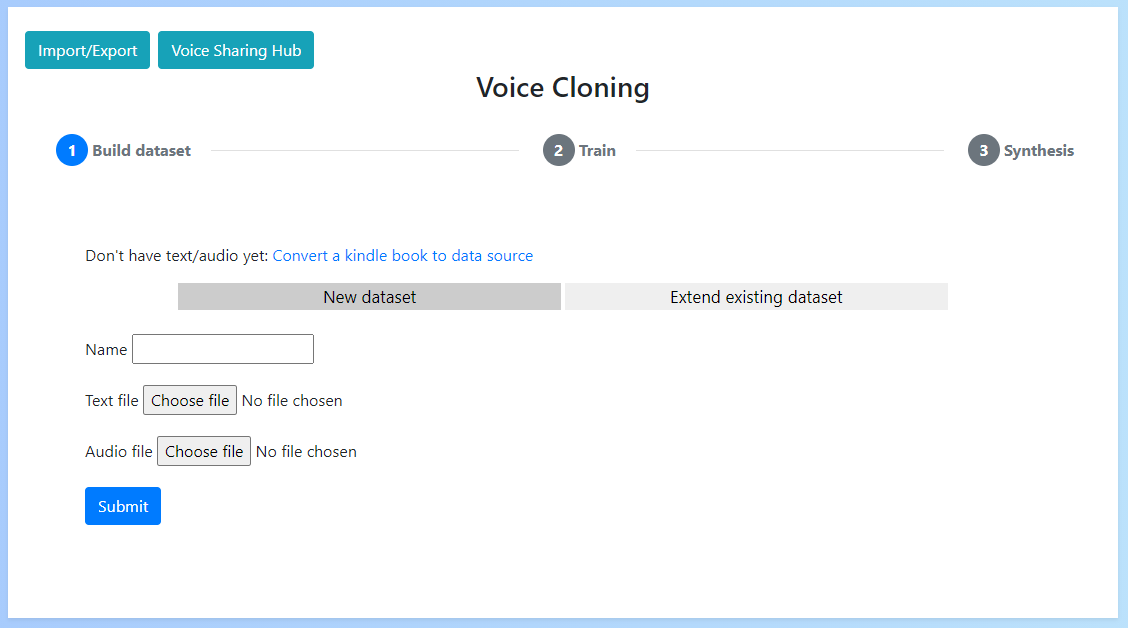
- Automatic dataset generation (with support for subtitles and audiobooks)
- Additional language support
- Local & remote training
- Easy train start/stop
Measured star growth
- in 24h
- 0
- in 7 days
- +1
- in 15 days
- Collecting history
- in 1 month
- Collecting history
Net star changes over overlapping periods, not daily totals. Missing measurements are left blank. Stars measure attention, not software quality.
README.md
OriginalVoice Cloning App


A Python/Pytorch app for easily synthesising human voices
Documentation
Discord Server
Video guide
Voice Sharing Hub
FAQ's
System Requirements
- Windows 10 or Ubuntu 20.04+ operating system
- 5GB+ Disk space
- NVIDIA GPU with at least 4GB of memory & driver version 456.38+ (optional)
Key features
- Automatic dataset generation (with support for subtitles and audiobooks)
- Additional language support
- Local & remote training
- Easy train start/stop
- Data importing/exporting
- Multi GPU support
Manual Guides
Future Improvements
- Add support for Talknet
- Add GTA alignment for Hifi-gan
- Improved batch size estimation
- AMD GPU support
Other resources
- Remote training notebook
- Try out existing voices at uberduck.ai and Vocodes
- Youtube data fetching (created by Diskr33t#5880)
- Synthesize in Colab (created by mega b#6696)
- Generate youtube transcription (created by mega b#6696)
- Wit.ai transcription
Acknowledgements
This project uses a reworked version of Tacotron2. All rights for belong to NVIDIA and follow the requirements of their BSD-3 licence.
Additionally, the project uses DSAlign, Silero, DeepSpeech & hifi-gan.
Thank you to Dr. John Bustard at Queen's University Belfast for his support throughout the project.
Supported by uberduck.ai, reach out to them for live model hosting.
Also a big thanks to the members of the VocalSynthesis subreddit for their feedback.
Finally thank you to everyone raising issues and contributing to the project.
Explore related projects
tensorflow/tensorflow
An Open Source Machine Learning Framework for Everyone
201,505 starshuggingface/transformers
🤗 Transformers: the model-definition framework for state-of-the-art machine learning models in text, vision, audio, and multimodal models, for both inference and training.
168,815 starsAUTOMATIC1111/stable-diffusion-webui
Stable Diffusion web UI
165,300 starsComfy-Org/ComfyUI
The most powerful and modular diffusion model GUI, api and backend with a graph/nodes interface. The fastest local inference engine in the world.
146,472 stars