
vid-gen/awesome-video-world-model
vid-gen/awesome-video-world-model has 37 GitHub stars and 1 forks. GitHot measured 0 stars in 24 hours, +1 in 7 days, and +5 in 15 days. Last checked 2026-11-12 09:19 UTC. Last push 2026-10-25.
A paper list of awesome video world model
Measured star growth
- in 24h
- 0
- in 7 days
- +1
- in 15 days
- +5
- in 1 month
- Collecting history
Net star changes over overlapping periods, not daily totals. Missing measurements are left blank. Stars measure attention, not software quality.
README.md
OriginalReading, Writing, Sharing, and Interacting
with the World through Video
A Survey Toward Unified Video World Models

Shengqiong Wu1,* · Meng Luo2,* · Bobo Li2 · Ziwei Liu3
Shuicheng Yan2 · Ming-Hsuan Yang4 · Philip Torr1 · Hao Fei1,†
1 University of Oxford · 2 National University of Singapore
3 Nanyang Technological University · 4 University of California, Merced
* Equal contribution · † Project lead & correspondence
Awesome Video World Models
Literature on video comprehension, generation, unified video models, and video world models.
Contents
Browse the literature · The survey at a glance · Research timeline · World-model taxonomy · BibTeX · Contributing
Browse the literature


The survey at a glance
An observed video is a partial, lossy, temporally ordered trace of a latent temporal world. A model maintains its own represented state, which can be incomplete or wrong. The four operations describe different ways of connecting these objects; one system can perform several operations.
| Operation | Core question | The survey covers |
|---|---|---|
 Reading · video comprehension |
What world properties can be inferred from the trace? | Tasks and benchmarks; representation learning; Video-LLMs; video agents; applications |
 Writing · video generation |
What trace follows from a partial world specification? | Tasks and conditions; latent representations; generative models; control; applications |
 Sharing · unified video models |
How can comprehension and generation support one another? | Unified architectures; learning paradigms; editing and reasoning; cross-direction evaluation |
 Interacting · video world models |
How does state evolve under actions and new observations? | Architectures and training; control and memory; responsiveness and grounding; applications and evaluation |
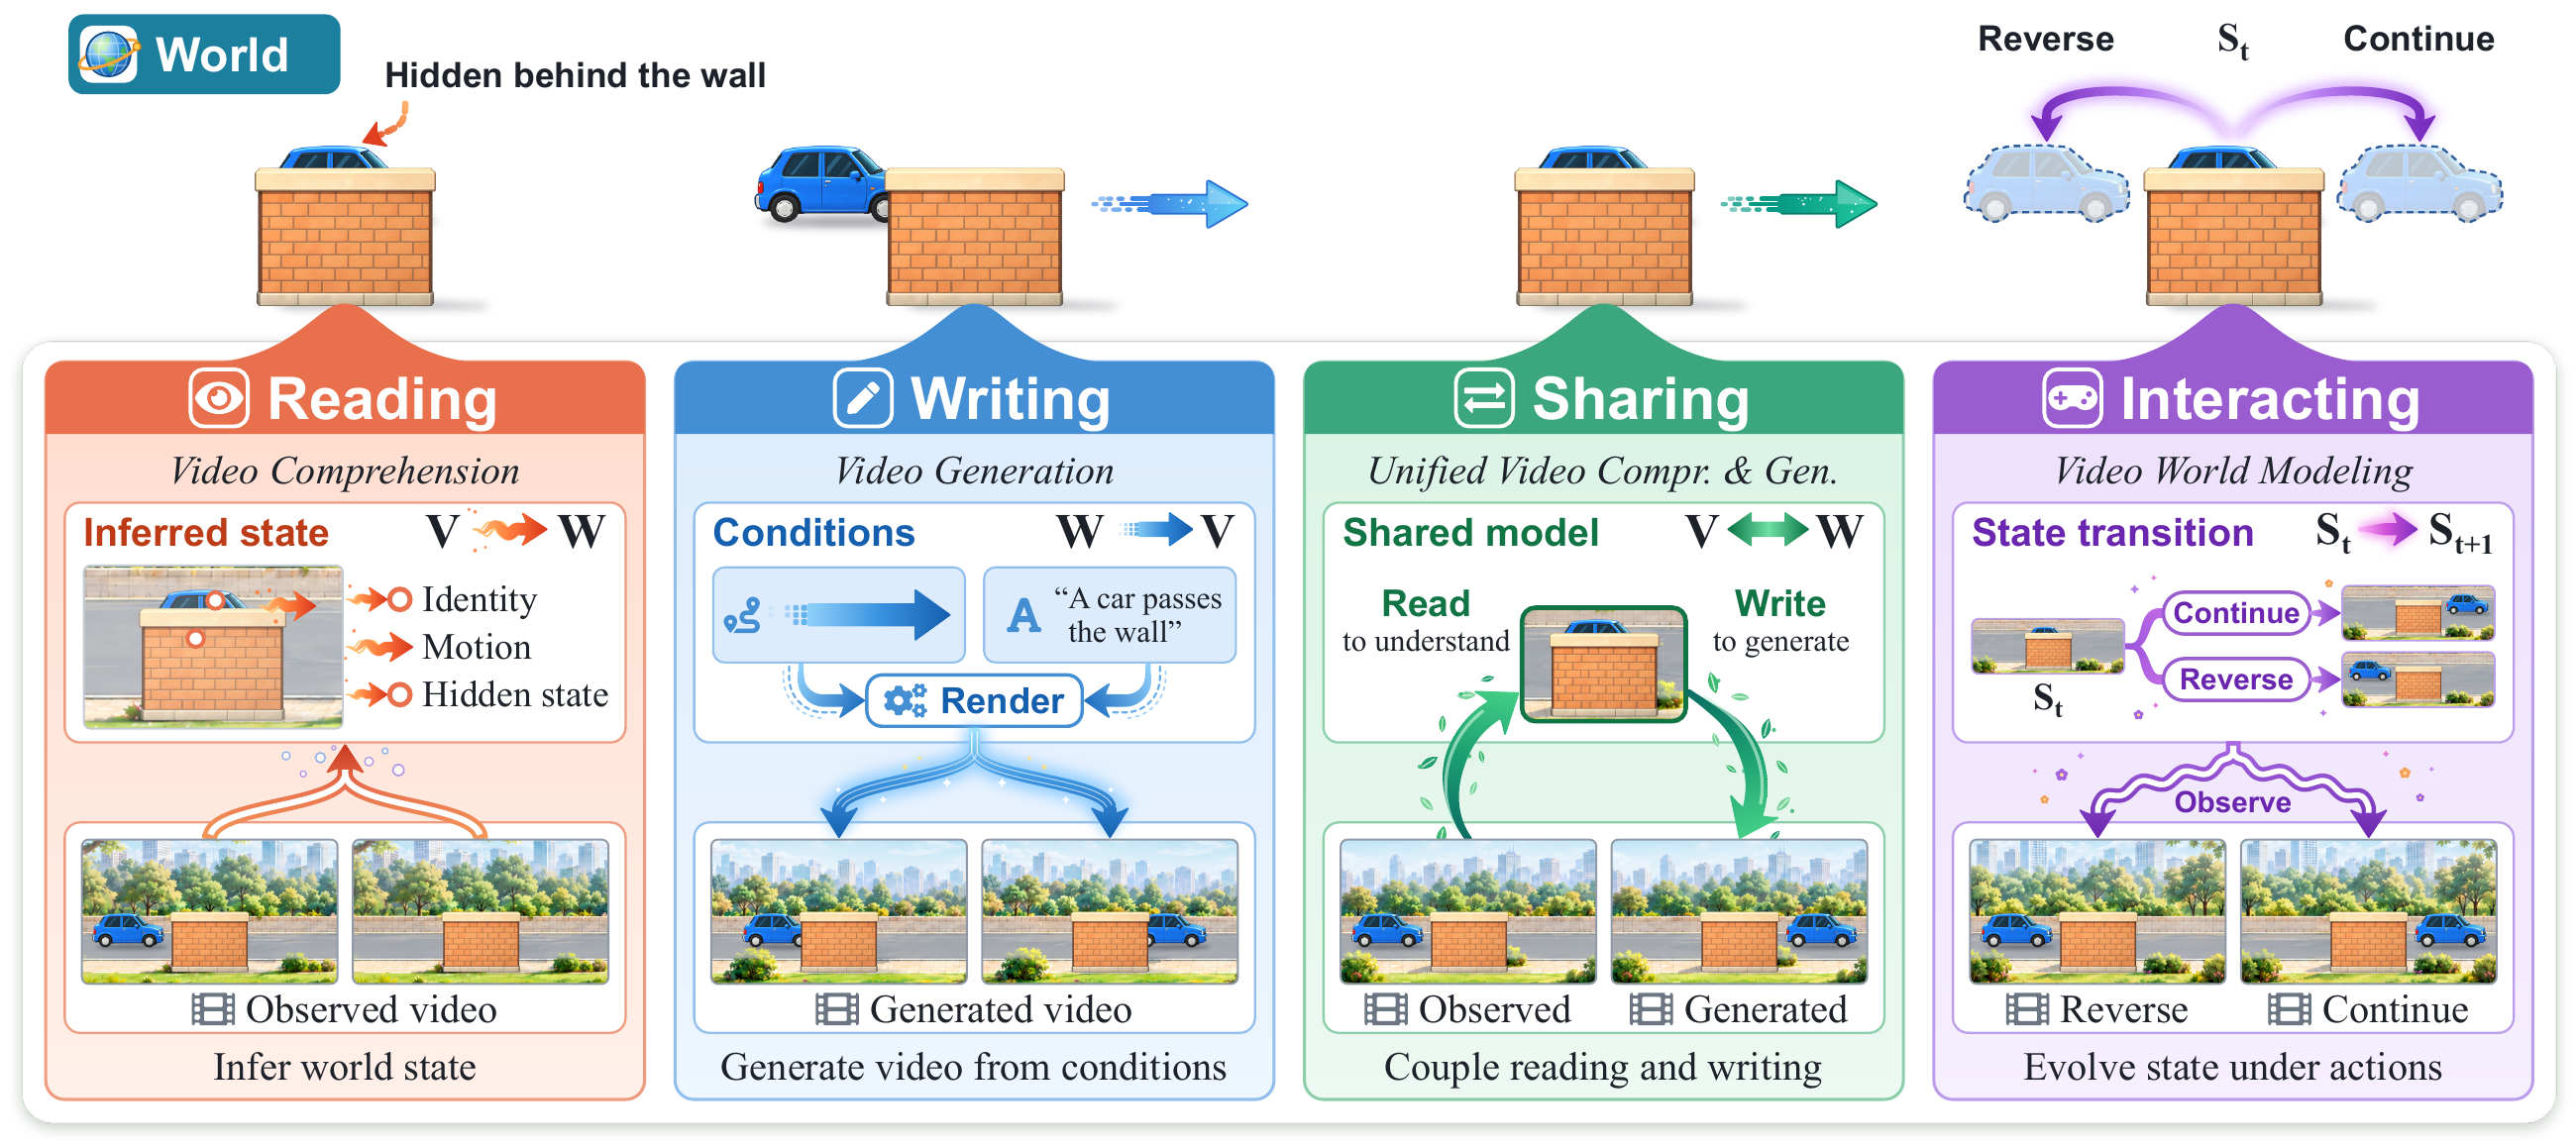
Temporal coherence and world consistency are different. Smooth neighboring frames do not establish persistent identity, layout, physics, or causal responses. A hard cut can break visual smoothness while preserving the world. Neither property implies the other.
Research timeline

World-model taxonomy
The survey crosses prediction space with transition interface. The same model can occupy different cells depending on how it is trained and used.
| Prediction space | Passive: no action input | Action-conditioned: fixed controls | Interactive: new controls after feedback |
|---|---|---|---|
| Observation space — frames, video tokens, or video-decoding latents | Forecast video from observed history | Predict controlled video from a supplied action sequence | Advance a visual world after each new control |
| Latent state — video-derived features without required rendering | Predict target features from context | Roll out candidate feature trajectories | Plan, act, observe, and replan |
Predicting generative latents that are decoded into video still counts as observation-space prediction. “Interactive” describes the control interface, not the attention pattern.
Literature
Full citations are available in BibTeX.
Reading the World
Video comprehension, representation learning, Video-LLMs, long-video reasoning, streaming perception, and video agents.
Years: 2026 · 2025 · 2024 · 2023 · 2022 · 2021 · 2019 · 2017.
2026
CVPR 2026A Multi-Agent Perception-Action Alliance for Efficient Long Video Reasoning. [paper] [code]arXiv 2026Accuracy and Cost Claims Do Not Survive Re-Execution in Agentic VideoQA. [paper]arXiv 2026APT: Atomic Physical Transitions for Causal Video-Language Understanding. [paper] [project]arXiv 2026Audio-Visual Intelligence in Large Foundation Models. [paper] [project]arXiv 2026CASE: Cost-Aware Stopping for Efficient Long-Video Agents. [paper]arXiv 2026Efficient Universal Perception Encoder. [paper] [code]TPAMI 2026Ego-R1: Agentic Chain-of-Tool-Thought for Ultra-Long Egocentric Video Reasoning. [paper] [project]arXiv 2026EgoTools: Towards Tool-Centric Reasoning in Real-World Egocentric Videos. [paper] [code] [project]CVPR 2026EVA: Efficient Reinforcement Learning for End-to-End Video Agent. [paper] [code] [project]ICLR 2026FrameThinker: Learning to Think with Long Videos via Multi-Turn Frame Spotlighting. [paper] [code]ACL 2026From Verbatim to Gist: Distilling Pyramidal Multimodal Memory via Semantic Information Bottleneck for Long-Horizon Video Agents. [paper] [code]Findings of ACL 2026GRPO-CARE: Consistency-Aware Reinforcement Learning for Multimodal Reasoning. [paper] [code]CVPR 2026InternVideo-Next: Towards World-Understanding Video Models. [paper] [code]arXiv 2026InternVideo3: Agentify Foundation Models with Multimodal Contextual Reasoning. [paper] [code]arXiv 2026LLaVA-OneVision-2: Towards Next-Generation Perceptual Intelligence. [paper] [code] [project]ACL 2026LongVideoAgent: Multi-Agent Reasoning with Long Videos. [paper] [code] [project]CVPR 2026LongVT: Incentivizing ”Thinking with Long Videos” via Native Tool Calling. [paper] [code] [project]arXiv 2026OneStreamer: Unifying Perception, Memory, and Proactive Response in Streaming Video Interaction. [paper] [project]CVPR 2026OneThinker: All-in-One Reasoning Model for Image and Video. [paper] [code]CVPR 2026SAGE: Training Smart Any-Horizon Agents for Long Video Reasoning with Reinforcement Learning. [paper] [code] [project]ICASSP 2026SceneRAG: Scene-Level Retrieval-Augmented Generation for Video Understanding. [paper]CVPR Findings 2026SCP: Spatial Causal Prediction in Video. [paper] [project]ICLR 2026Seeing, Listening, Remembering, and Reasoning: A Multimodal Agent with Long-Term Memory. [paper] [code] [project]CVPR 2026Streaming Video Instruction Tuning. [paper] [code] [project]ICLR 2026StreamingVLM: Real-Time Understanding for Infinite Video Streams. [paper] [code]CVPR 2026Think, Then Verify: A Hypothesis-Verification Multi-Agent Framework for Long Video Understanding. [paper] [code] [project]ICLR 2026Unveiling the Cognitive Compass: Theory-of-Mind-Guided Multimodal Emotion Reasoning. [paper]ECCV 2026V-JEPA 2.1: Unlocking Dense Features in Video Self-Supervised Learning. [paper] [code]ECCV 2026Video Generation Models Are General-Purpose Vision Learners. [paper] [code] [project]CVPR Findings 2026Video Reasoning Without Training. [paper] [project]ECCV 2026Video-Holmes: Can MLLM Think Like Holmes for Complex Video Reasoning?. [paper] [code] [project]AAAI 2026VideoChat-A1: Thinking with Long Videos by Chain-of-Shot Reasoning. [paper] [code]ICLR 2026VideoChat-Flash: Hierarchical Compression for Long-Context Video Modeling. [paper] [code] [project]arXiv 2026VideoChat3: Fully Open Video MLLM for Efficient and Generalist Video Understanding. [paper] [code]ICLR 2026VideoMind: A Chain-of-LoRA Agent for Temporal-Grounded Video Reasoning. [paper] [code] [project]CVPR Findings 2026VideoP2R: Video Understanding from Perception to Reasoning. [paper] [project]KDD 2026VideoRAG: Retrieval-Augmented Generation with Extreme Long-Context Videos. [paper] [code]CVPR Findings 2026VideoThinker: Building Agentic VideoLLMs with LLM-Guided Tool Reasoning. [paper]arXiv 2026VisPhyWorld: Probing Physical Reasoning via Code-Driven Video Reconstruction. [paper] [code] [project]CVPR 2026WorldMM: Dynamic Multimodal Memory Agent for Long Video Reasoning. [paper] [code] [project]
2025
CVPR 2025Apollo: An Exploration of Video Understanding in Large Multimodal Models. [paper] [project]arXiv 2025AViLA: Asynchronous Vision-Language Agent for Streaming Multimodal Data Interaction. [paper] [project]NeurIPS 2025Deep Video Discovery: Agentic Search with Tool Use for Long-Form Video Understanding. [paper] [code]Nature 2025DeepSeek-R1 Incentivizes Reasoning in LLMs Through Reinforcement Learning. [paper] [code] [project]NeurIPS 2025DeepVideo-R1: Video Reinforcement Fine-Tuning via Difficulty-Aware Regressive GRPO. [paper] [code]NeurIPS 2025Eagle 2.5: Boosting Long-Context Post-Training for Frontier Vision-Language Models. [paper] [code] [project]IJCV 2025Ego-Exo4D: Understanding Skilled Human Activity from First- and Third-Person Perspectives. [paper] [project]CVPR 2025EgoLife: Towards Egocentric Life Assistant. [paper] [code] [project]CVPR 2025Enhancing Video-LLM Reasoning via Agent-of-Thoughts Distillation. [paper] [code] [project]arXiv 2025FineVision: Open Data Is All You Need. [paper]arXiv 2025InternVL3.5: Advancing Open-Source Multimodal Models in Versatility, Reasoning, and Efficiency. [paper] [code] [project]arXiv 2025Kwai Keye-VL 1.5 Technical Report. [paper] [code]Transactions on Machine Learning Research 2025LLaVA-OneVision: Easy Visual Task Transfer. [paper] [code] [project]Transactions on Machine Learning Research 2025LLaVA-Video: Video Instruction Tuning with Synthetic Data. [paper] [code] [project]Transactions on Machine Learning Research 2025Long Context Transfer from Language to Vision. [paper] [code]ICLR 2025LongVILA: Scaling Long-Context Visual Language Models for Long Videos. [paper] [code]CVPR 2025MMVU: Measuring Expert-Level Multi-Discipline Video Understanding. [paper] [code] [project]NeurIPS 2025Perception Encoder: The Best Visual Embeddings Are Not at the Output of the Network. [paper] [code] [project]ICCV 2025Principles of Visual Tokens for Efficient Video Understanding. [paper]arXiv 2025Qwen2.5-Omni Technical Report. [paper] [code]arXiv 2025Qwen2.5-VL Technical Report. [paper] [code]arXiv 2025Qwen3-Omni Technical Report. [paper] [code]arXiv 2025Qwen3-VL Technical Report. [paper] [code]ICLR 2025SAM 2: Segment Anything in Images and Videos. [paper] [code] [project]NeurIPS 2025Scaling RL to Long Videos. [paper] [code]arXiv 2025SigLIP 2: Multilingual Vision-Language Encoders with Improved Semantic Understanding, Localization, and Dense Features. [paper] [code]arXiv 2025SurgVLM: A Large Vision-Language Model and Systematic Evaluation Benchmark for Surgical Intelligence. [paper] [code] [project]CVPR 2025Thinking in Space: How Multimodal Large Language Models See, Remember, and Recall Spaces. [paper] [code] [project]NeurIPS 2025Time-R1: Post-Training Large Vision Language Model for Temporal Video Grounding. [paper] [code] [project]arXiv 2025Towards Anticipatory Agents for Streaming Video Understanding. [paper]arXiv 2025TRAVL: A Recipe for Making Video-Language Models Better Judges of Physics Implausibility. [paper] [project]NeurIPS 2025Two Causally Related Needles in a Video Haystack. [paper] [code] [project]NeurIPS 2025Unleashing Hour-Scale Video Training for Long Video-Language Understanding. [paper] [code] [project]ICCV 2025VCA: Video Curious Agent for Long Video Understanding. [paper]NeurIPS 2025Video-R1: Reinforcing Video Reasoning in MLLMs. [paper] [code]CVPR 2025Video-XL: Extra-Long Vision Language Model for Hour-Scale Video Understanding. [paper] [code]arXiv 2025VideoAgent2: Enhancing the LLM-Based Agent System for Long-Form Video Understanding by Uncertainty-Aware CoT. [paper]arXiv 2025VideoChat-R1: Enhancing Spatio-Temporal Perception via Reinforcement Fine-Tuning. [paper] [code]Science China Information Sciences 2025VideoChat: Chat-Centric Video Understanding. [paper] [code]arXiv 2025VideoExplorer: Think with Videos for Agentic Long-Video Understanding. [paper] [code]arXiv 2025VideoLLaMA 3: Frontier Multimodal Foundation Models for Image and Video Understanding. [paper] [code]NeurIPS 2025VideoLucy: Deep Memory Backtracking for Long Video Understanding. [paper] [code] [project]arXiv 2025VideoMultiAgents: A Multi-Agent Framework for Video Question Answering. [paper] [code]Findings of ACL 2025VideoRAG: Retrieval-Augmented Generation Over Video Corpus. [paper] [code]CVPR 2025VideoTree: Adaptive Tree-Based Video Representation for LLM Reasoning on Long Videos. [paper] [code] [project]ICML 2025VistaDPO: Video Hierarchical Spatial-Temporal Direct Preference Optimization for Large Video Models. [paper] [code]
2024
CVPR 2024Chat-UniVi: Unified Visual Representation Empowers Large Language Models with Image and Video Understanding. [paper] [code]ECCV 2024DriveLM: Driving with Graph Visual Question Answering. [paper] [code] [project]TPAMI 2024Enhancing Video-Language Representations with Structural Spatio-Temporal Alignment. [paper]arXiv 2024Gemini 1.5: Unlocking Multimodal Understanding Across Millions of Tokens of Context. [paper]CVPR 2024Honeybee: Locality-Enhanced Projector for Multimodal LLM. [paper] [code]NeurIPS 2024HourVideo: 1-Hour Video-Language Understanding. [paper] [code] [project]ECCV 2024InternVideo2: Scaling Foundation Models for Multimodal Video Understanding. [paper] [code]ECCV 2024LLaMA-VID: An Image Is Worth 2 Tokens in Large Language Models. [paper] [code] [project]CVPR 2024MA-LMM: Memory-Augmented Large Multimodal Model for Long-Term Video Understanding. [paper] [code] [project]COLM 2024Mamba: Linear-Time Sequence Modeling with Selective State Spaces. [paper] [code]arXiv 2024MiniCPM-V: A GPT-4V Level MLLM on Your Phone. [paper] [code]ICML 2024Momentor: Advancing Video Large Language Model with Fine-Grained Temporal Reasoning. [paper] [code]CVPR 2024MovieChat: From Dense Token to Sparse Memory for Long Video Understanding. [paper] [code]Transactions on Machine Learning Research 2024Revisiting Feature Prediction for Learning Visual Representations from Video. [paper] [code] [project]CVPR 2024TimeChat: A Time-Sensitive Multimodal Large Language Model for Long Video Understanding. [paper] [code]ACL 2024Video-ChatGPT: Towards Detailed Video Understanding via Large Vision and Language Models. [paper] [code]EMNLP 2024Video-LLaVA: Learning United Visual Representation by Alignment Before Projection. [paper] [code]ICML 2024Video-of-Thought: Step-by-Step Video Reasoning from Perception to Cognition. [paper] [code] [project]ECCV 2024VideoAgent: A Memory-Augmented Multimodal Agent for Video Understanding. [paper] [code] [project]ECCV 2024VideoAgent: Long-Form Video Understanding with Large Language Model As Agent. [paper] [code]arXiv 2024VideoLLaMA 2: Advancing Spatial-Temporal Modeling and Audio Understanding in Video-LLMs. [paper] [code]CVPR 2024VideoLLM-Online: Online Video Large Language Model for Streaming Video. [paper] [code] [project]ICML 2024VideoPrism: A Foundational Visual Encoder for Video Understanding. [paper] [code] [project]
2023
ICML 2023BLIP-2: Bootstrapping Language-Image Pre-Training with Frozen Image Encoders and Large Language Models. [paper] [code]NeurIPS 2023Self-Chained Image-Language Model for Video Localization and Question Answering. [paper] [code]ICCV 2023Sigmoid Loss for Language Image Pre-Training. [paper] [code]ICCV 2023Tracking Anything with Decoupled Video Segmentation. [paper] [code] [project]ICCV 2023Unmasked Teacher: Towards Training-Efficient Video Foundation Models. [paper] [code]CVPR 2023Vid2Seq: Large-Scale Pretraining of a Visual Language Model for Dense Video Captioning. [paper] [project]EMNLP 2023Video-LLaMA: An Instruction-Tuned Audio-Visual Language Model for Video Understanding. [paper] [code] [project]CVPR 2023VideoMAE V2: Scaling Video Masked Autoencoders with Dual Masking. [paper] [code]ICCV 2023ViperGPT: Visual Inference via Python Execution for Reasoning. [paper] [code] [project]NeurIPS 2023Visual Instruction Tuning. [paper] [code] [project]CVPR 2023Visual Programming: Compositional Visual Reasoning Without Training. [paper] [code] [project]
2022
CVPR 2022Advancing High-Resolution Video-Language Representation with Large-Scale Video Transcriptions. [paper] [code]Neurocomputing 2022CLIP4Clip: An Empirical Study of CLIP for End to End Video CLIP Retrieval and Captioning. [paper] [code]NeurIPS 2022Flamingo: A Visual Language Model for Few-Shot Learning. [paper]Transactions on Machine Learning Research 2022GIT: A Generative Image-to-Text Transformer for Vision and Language. [paper] [code]arXiv 2022InternVideo: General Video Foundation Models via Generative and Discriminative Learning. [paper] [code]CVPR 2022Language As Queries for Referring Video Object Segmentation. [paper] [code]CVPR 2022Masked Feature Prediction for Self-Supervised Visual Pre-Training. [paper]Medical Image Analysis 2022Rendezvous: Attention Mechanisms for the Recognition of Surgical Action Triplets in Endoscopic Videos. [paper] [code]NeurIPS 2022Training Language Models to Follow Instructions with Human Feedback. [paper]CVPR 2022Video Swin Transformer. [paper] [code]arXiv 2022VideoCoCa: Video-Text Modeling with Zero-Shot Transfer from Contrastive Captioners. [paper]NeurIPS 2022VideoMAE: Masked Autoencoders Are Data-Efficient Learners for Self-Supervised Video Pre-Training. [paper] [code]ACM MM 2022X-CLIP: End-to-End Multi-Grained Contrastive Learning for Video-Text Retrieval. [paper] [code] [project]ECCV 2022XMem: Long-Term Video Object Segmentation with an Atkinson-Shiffrin Memory Model. [paper] [code] [project]
2021
CVPR 2021A Large-Scale Study on Unsupervised Spatiotemporal Representation Learning. [paper] [code]ICLR 2021An Image Is Worth 16x16 Words: Transformers for Image Recognition at Scale. [paper] [code]NeurIPS 2021Associating Objects with Transformers for Video Object Segmentation. [paper] [project]ICCV 2021Frozen in Time: A Joint Video and Image Encoder for End-to-End Retrieval. [paper] [code] [project]ICML 2021Is Space-Time Attention All You Need for Video Understanding?. [paper] [code]ICML 2021Learning Transferable Visual Models from Natural Language Supervision. [paper] [code]NeurIPS 2021MERLOT: Multimodal Neural Script Knowledge Models. [paper] [code] [project]CVPR 2021Spatiotemporal Contrastive Video Representation Learning. [paper] [code]EMNLP 2021VideoCLIP: Contrastive Pre-Training for Zero-Shot Video-Text Understanding. [paper] [code]ICCV 2021ViViT: A Video Vision Transformer. [paper] [code]
2019
CVPR 2019Cross-Task Weakly Supervised Learning from Instructional Videos. [paper] [code]ICCV 2019SlowFast Networks for Video Recognition. [paper] [code]ICCV 2019VideoBERT: A Joint Model for Video and Language Representation Learning. [paper]
2017
ICCV 2017Dense-Captioning Events in Videos. [paper] [code] [project]IEEE Transactions on Medical Imaging 2017EndoNet: A Deep Architecture for Recognition Tasks on Laparoscopic Videos. [paper]ICCV 2017Localizing Moments in Video with Natural Language. [paper] [code]CVPR 2017Quo Vadis, Action Recognition? A New Model and the Kinetics Dataset. [paper]ICCV 2017TALL: Temporal Activity Localization via Language Query. [paper]
Writing the World
Video generation and editing, latent representations, diffusion, flow and autoregressive models, control strategies, and audio-video synthesis.
Years: 2026 · 2025 · 2024 · 2023 · 2022 · 2021 · 2020 · 2018 · 2017 · 2016.
2026
ICLR 2026Controllable First-Frame-Guided Video Editing via Mask-Aware LoRA Fine-Tuning. [paper] [code] [project]arXiv 2026DiVid: Diagnosing Dimension-Specific Diversity Collapse in Video Generation Models. [paper]CVPR 2026EVATok: Adaptive Length Video Tokenization for Efficient Visual Autoregressive Generation. [paper] [code] [project]AAAI 2026HiTVideo: Hierarchical Tokenizers for Enhancing Text-to-Video Generation with Autoregressive Large Language Models. [paper] [project]ICLR 2026JavisDiT++: Unified Modeling and Optimization for Joint Audio-Video Generation. [paper] [code] [project]ICLR 2026JavisDiT: Joint Audio-Video Diffusion Transformer with Hierarchical Spatio-Temporal Prior Synchronization. [paper] [code] [project]arXiv 2026LongTake: Learning to Sustain Dynamics in Long-Horizon Video Generation. [paper] [project]arXiv 2026LTX-2: Efficient Joint Audio-Visual Foundation Model. [paper] [code]ICLR 2026Lumos-1: On Autoregressive Video Generation with Discrete Diffusion from a Unified Model Perspective. [paper] [code]ECCV 2026OneVAE: Joint Discrete and Continuous Optimization Helps Discrete Video VAE Train Better. [paper] [code]ECCV 2026PhysRAG: Enhancing Physics-Awareness in Video Generation via Retrieval-Augmented Generation. [paper] [code]arXiv 2026S2PD: Serial-to-Parallel Diffusion for Physically and Logically Consistent Video Generation. [paper] [code] [project]arXiv 2026SANA-Video 2.0: Hybrid Linear Attention with Attention Residuals for Efficient Video Generation. [paper] [code] [project]arXiv 2026Seedance 2.0: Advancing Video Generation for World Complexity. [paper]CVPR 2026STARFlow-V: End-to-End Video Generative Modeling with Autoregressive Normalizing Flows. [paper] [code] [project]CVPR 2026TV2TV: A Unified Framework for Interleaved Language and Video Generation. [paper]ICLR 2026Unified In-Context Video Editing. [paper] [project]arXiv 2026V-RAE: Rethinking Video Latent Spaces for Generation. [paper] [code] [project]CVPR Findings 2026Video2LoRA: Unified Semantic-Controlled Video Generation via Per-Reference-Video LoRA. [paper] [code]ICML 2026VideoFlexTok: Flexible-Length Coarse-to-Fine Video Tokenization. [paper] [code] [project]ICML 2026World-R1: Reinforcing 3D Constraints for Text-to-Video Generation. [paper] [code] [project]
2025
arXiv 2025Any2Caption:Interpreting Any Condition to Caption for Controllable Video Generation. [paper] [project]arXiv 2025Automated Movie Generation via Multi-Agent CoT Planning. [paper] [code] [project]ICLR 2025Autoregressive Video Generation Without Vector Quantization. [paper] [code] [project]ICLR 2025CameraCtrl: Enabling Camera Control for Video Diffusion Models. [paper] [code] [project]ICLR 2025CogVideoX: Text-to-Video Diffusion Models with an Expert Transformer. [paper] [code] [project]CoRL 2025Dreamitate: Real-World Visuomotor Policy Learning via Video Generation. [paper] [code] [project]arXiv 2025Exploring MLLM-Diffusion Information Transfer with MetaCanvas. [paper] [project]ICCV 2025FullDiT: Video Generative Foundation Models with Multimodal Control via Full Attention. [paper] [project]CVPR 2025Goku: Flow Based Video Generative Foundation Models. [paper] [code] [project]arXiv 2025HunyuanVideo 1.5 Technical Report. [paper] [code]CVPR 2025Identity-Preserving Text-to-Video Generation by Frequency Decomposition. [paper] [code] [project]ICLR 2025Image and Video Tokenization with Binary Spherical Quantization. [paper] [code]NeurIPS 2025Improving Video Generation with Human Feedback. [paper] [code] [project]NeurIPS 2025InfinityStar: Unified Spacetime AutoRegressive Modeling for Visual Generation. [paper] [code]arXiv 2025MAGI-1: Autoregressive Video Generation at Scale. [paper] [code]CVPR 2025One-Minute Video Generation with Test-Time Training. [paper] [project]arXiv 2025Ovi: Twin Backbone Cross-Modal Fusion for Audio-Video Generation. [paper] [code] [project]ICLR 2025Pyramidal Flow Matching for Efficient Video Generative Modeling. [paper] [code] [project]arXiv 2025Seedance 1.0: Exploring the Boundaries of Video Generation Models. [paper] [project]Report 2025Sora 2 Is Here. [paper]arXiv 2025Step-Video-T2V Technical Report: The Practice, Challenges, and Future of Video Foundation Model. [paper] [code]CVPR 2025StreamingT2V: Consistent, Dynamic, and Extendable Long Video Generation from Text. [paper] [code]ICCV 2025VACE: All-in-One Video Creation and Editing. [paper] [code] [project]Technical report 2025Veo: a text-to-video generation system. [paper]NeurIPS 2025VideoMAR: Autoregressive Video Generation with Continuous Tokens. [paper] [project]ICCV 2025VLIPP: Towards Physically Plausible Video Generation with Vision and Language Informed Physical Prior. [paper] [code] [project]CVPR 2025VLOGGER: Multimodal Diffusion for Embodied Avatar Synthesis. [paper] [project]NeurIPS 2025Wan-Move: Motion-Controllable Video Generation via Latent Trajectory Guidance. [paper] [code] [project]arXiv 2025Wan: Open and Advanced Large-Scale Video Generative Models. [paper] [code]
2024
SIGGRAPH Asia 2024Anim-Director: A Large Multimodal Model Powered Agent for Controllable Animation Video Generation. [paper] [code]CVPR 2024Animate Anyone: Consistent and Controllable Image-to-Video Synthesis for Character Animation. [paper] [project]ICLR 2024AnimateDiff: Animate Your Personalized Text-to-Image Diffusion Models Without Specific Tuning. [paper] [code]NeurIPS 2024Autoregressive Image Generation Without Vector Quantization. [paper] [code]NeurIPS 2024CV-VAE: A Compatible Video VAE for Latent Generative Video Models. [paper] [code] [project]arXiv 2024DiCoDe: Diffusion-Compressed Deep Tokens for Autoregressive Video Generation with Language Models. [paper] [code] [project]ECCV 2024DriveDreamer: Towards Real-World-Driven World Models for Autonomous Driving. [paper] [code] [project]CVPR 2024Dysen-VDM: Empowering Dynamics-Aware Text-to-Video Diffusion with LLMs. [paper] [code] [project]ECCV 2024EMO: Emote Portrait Alive – Generating Expressive Portrait Videos with Audio2Video Diffusion Model Under Weak Conditions. [paper] [project]ICLR 2024Finite Scalar Quantization: VQ-VAE Made Simple. [paper] [code]NeurIPS 2024FreeLong: Training-Free Long Video Generation with SpectralBlend Temporal Attention. [paper] [code] [project]arXiv 2024Hallo: Hierarchical Audio-Driven Visual Synthesis for Portrait Image Animation. [paper] [code]arXiv 2024HunyuanVideo: A Systematic Framework for Large Video Generative Models. [paper] [code]Project 2024Kling AI. [paper]ICLR 2024Language Model Beats Diffusion – Tokenizer Is Key to Visual Generation. [paper]ICLR 2024Learning to Act from Actionless Videos Through Dense Correspondences. [paper] [code] [project]arXiv 2024LiFT: Leveraging Human Feedback for Text-to-Video Model Alignment. [paper] [code] [project]ICLR 2024LLM-Grounded Video Diffusion Models. [paper] [code] [project]arXiv 2024Loong: Generating Minute-Level Long Videos with Autoregressive Language Models. [paper] [project]arXiv 2024LTX-Video: Realtime Video Latent Diffusion. [paper] [code]SIGGRAPH Asia 2024Lumiere: A Space-Time Diffusion Model for Video Generation. [paper]CVPR 2024MagicAnimate: Temporally Consistent Human Image Animation Using Diffusion Model. [paper] [code] [project]ICLR 2024MagicDrive: Street View Generation with Diverse 3D Geometry Control. [paper] [code] [project]Report 2024Mochi 1. [paper] [code]arXiv 2024Mora: Enabling Generalist Video Generation via a Multi-Agent Framework. [paper] [code] [project]SIGGRAPH 2024MotionCtrl: A Unified and Flexible Motion Controller for Video Generation. [paper] [code] [project]arXiv 2024Movie Gen: A Cast of Media Foundation Models. [paper] [project]arXiv 2024MuseTalk: Real-Time High-Fidelity Video Dubbing via Spatio-Temporal Sampling. [paper] [code]arXiv 2024Open-Sora: Democratizing Efficient Video Production for All. [paper] [code]CVPR 2024Panacea: Panoramic and Controllable Video Generation for Autonomous Driving. [paper] [code] [project]ICML 2024Scaling Rectified Flow Transformers for High-Resolution Image Synthesis. [paper]ICLR 2024SEINE: Short-to-Long Video Diffusion Model for Generative Transition and Prediction. [paper] [code] [project]AAAI 2024T2I-Adapter: Learning Adapters to Dig Out More Controllable Ability for Text-to-Image Diffusion Models. [paper] [code]ICLR 2024TokenFlow: Consistent Diffusion Features for Consistent Video Editing. [paper] [code] [project]ICLR 2024Universal Guidance for Diffusion Models. [paper] [code]Report 2024Video Generation Models As World Simulators. [paper]CVPR 2024Video-P2P: Video Editing with Cross-Attention Control. [paper] [code] [project]CVPR 2024VideoCrafter2: Overcoming Data Limitations for High-Quality Video Diffusion Models. [paper]COLM 2024VideoDirectorGPT: Consistent Multi-Scene Video Generation via LLM-Guided Planning. [paper] [project]ICML 2024VideoPoet: A Large Language Model for Zero-Shot Video Generation. [paper] [project]
2023
ICCV 2023Adding Conditional Control to Text-to-Image Diffusion Models. [paper] [code]CVPR 2023Align Your Latents: High-Resolution Video Synthesis with Latent Diffusion Models. [paper] [project]ICLR 2023An Image Is Worth One Word: Personalizing Text-to-Image Generation Using Textual Inversion. [paper] [code] [project]ICLR 2023CogVideo: Large-Scale Pretraining for Text-to-Video Generation via Transformers. [paper] [code]NeurIPS 2023Diffusion Self-Guidance for Controllable Image Generation. [paper] [project]arXiv 2023DragNUWA: Fine-Grained Control in Video Generation by Integrating Text, Image, and Trajectory. [paper] [project]CVPR 2023DreamBooth: Fine Tuning Text-to-Image Diffusion Models for Subject-Driven Generation. [paper] [project]ICCV 2023FateZero: Fusing Attentions for Zero-Shot Text-Based Video Editing. [paper] [code] [project]ICLR 2023Flow Matching for Generative Modeling. [paper] [code]ICCV 2023FreeDoM: Training-Free Energy-Guided Conditional Diffusion Model. [paper] [code]NeurIPS 2023Learning Universal Policies via Text-Guided Video Generation. [paper]ICLR 2023Make-A-Video: Text-to-Video Generation Without Text-Video Data. [paper] [project]ACL 2023NUWA-XL: Diffusion Over Diffusion for eXtremely Long Video Generation. [paper]ICLR 2023Phenaki: Variable Length Video Generation from Open Domain Textual Descriptions. [paper] [project]ICLR 2023Prompt-to-Prompt Image Editing with Cross-Attention Control. [paper] [code] [project]CVPR 2023SadTalker: Learning Realistic 3D Motion Coefficients for Stylized Audio-Driven Single Image Talking Face Animation. [paper] [code] [project]ICCV 2023Scalable Diffusion Models with Transformers. [paper] [code] [project]arXiv 2023Stable Video Diffusion: Scaling Latent Video Diffusion Models to Large Datasets. [paper] [code]ICCV 2023Tune-A-Video: One-Shot Tuning of Image Diffusion Models for Text-to-Video Generation. [paper] [code] [project]NeurIPS 2023VideoComposer: Compositional Video Synthesis with Motion Controllability. [paper] [code] [project]arXiv 2023VideoControlNet: A Motion-Guided Video-to-Video Translation Framework by Using Diffusion Model with ControlNet. [paper] [project]
2022
CVPR 2022Autoregressive Image Generation Using Residual Quantization. [paper] [code]arXiv 2022Classifier-Free Diffusion Guidance. [paper]CVPR 2022High-Resolution Image Synthesis with Latent Diffusion Models. [paper] [code]arXiv 2022Imagen Video: High Definition Video Generation with Diffusion Models. [paper] [project]ICLR 2022LoRA: Low-Rank Adaptation of Large Language Models. [paper] [code]ICLR 2022SDEdit: Guided Image Synthesis and Editing with Stochastic Differential Equations. [paper] [code] [project]NeurIPS 2022Video Diffusion Models. [paper] [project]
2021
ICLR 2021Denoising Diffusion Implicit Models. [paper] [code]CVPR 2021Taming Transformers for High-Resolution Image Synthesis. [paper] [code] [project]arXiv 2021VideoGPT: Video Generation Using VQ-VAE and Transformers. [paper] [code] [project]
2020
ACM MM 2020A Lip Sync Expert Is All You Need for Speech to Lip Generation in the Wild. [paper] [code] [project]NeurIPS 2020Denoising Diffusion Probabilistic Models. [paper] [code] [project]
2018
ACM Transactions on Graphics 2018Stereo Magnification: Learning View Synthesis Using Multiplane Images. [paper] [code] [project]arXiv 2018Stochastic Adversarial Video Prediction. [paper] [code] [project]
2017
NeurIPS 2017GANs Trained by a Two Time-Scale Update Rule Converge to a Local Nash Equilibrium. [paper] [code]NeurIPS 2017Neural Discrete Representation Learning. [paper] [project]
2016
Sharing the World
Unified understanding and generation through shared tokens, continuous representations, modular interfaces, joint learning, and generative reasoning.
Years: 2026 · 2025 · 2024 · 2023 · 2020.
2026
CVPR 2026AToken: A Unified Tokenizer for Vision. [paper] [code]ICML 2026Beyond Language Modeling: An Exploration of Multimodal Pretraining. [paper] [project]arXiv 2026Bridging Video Understanding and Generation in a Unified Framework. [paper]arXiv 2026Cosmos 3: Omnimodal World Models for Physical AI. [paper] [code] [project]arXiv 2026CounterVid: Counterfactual Video Generation for Mitigating Action and Temporal Hallucinations in Video-Language Models. [paper] [code] [project]arXiv 2026CyCLeGen: Cycle-Consistent Layout Prediction and Image Generation in Vision Foundation Models. [paper]arXiv 2026EWAM: Emergent Depth-Wise Specialization in a Unified Embodied Model – From Semantic Understanding Through Visual Foresight to Action. [paper] [code] [project]arXiv 2026Gen4U: Unifying Video Generation and Understanding via Diffusion. [paper]arXiv 2026HYDRA-X: Native Unified Multimodal Models with Holistic Visual Tokenizers. [paper]arXiv 2026Lance: Unified Multimodal Modeling by Multi-Task Synergy. [paper] [code] [project]ECCV 2026Lumos-Nexus: Efficient Frequency Bridging with Homogeneous Latent Space for Video Unified Models. [paper] [code] [project]arXiv 2026Mamoda2.5: Enhancing Unified Multimodal Model with DiT-MoE. [paper] [code] [project]arXiv 2026MoRoute: Dynamic Routing for In-Context Multimodal Video Generation. [paper] [project]ICLR 2026NExT-OMNI: Towards Any-to-Any Omnimodal Foundation Models with Discrete Flow Matching. [paper]arXiv 2026Omni-Video 2: Scaling MLLM-Conditioned Diffusion for Unified Video Generation and Editing. [paper] [code] [project]arXiv 2026OmniWeaving: Towards Unified Video Generation with Free-Form Composition and Reasoning. [paper] [code] [project]arXiv 2026OpenCoF: Learning to Reason Through Video Generation. [paper] [code] [project]arXiv 2026PixelUMM: Encoder-Free Unified Image and Video Understanding and Generation. [paper] [code] [project]arXiv 2026ProAR: Learning Prospective Reasoning with Autoregressive Video Models. [paper] [code] [project]arXiv 2026Pseudo-Unification: Entropy Probing Reveals Divergent Information Patterns in Unified Multimodal Models. [paper]CVPR 2026PyraTok: Language-Aligned Pyramidal Tokenizer for Video Understanding and Generation. [paper] [code] [project]ICLR 2026Reconstruction Alignment Improves Unified Multimodal Models. [paper] [code] [project]CVPR 2026Thinking with Video: Video Generation As a Promising Multimodal Reasoning Paradigm. [paper] [code]CVPR 2026TUNA: Taming Unified Visual Representations for Native Unified Multimodal Models. [paper] [project]arXiv 2026Uni-ViGU: Towards Unified Video Generation and Understanding via a Diffusion-Based Video Generator. [paper] [code] [project]ACL 2026UniCorn: Towards Self-Improving Unified Multimodal Models Through Self-Generated Supervision. [paper] [code] [project]CVPR 2026UnityVideo: Unified Multi-Modal Multi-Task Learning for Enhancing World-Aware Video Generation. [paper] [code] [project]ICLR 2026UniVideo: Unified Understanding, Generation, and Editing for Videos. [paper] [code] [project]arXiv 2026UniWAM: Unified World-Action Model. [paper] [code] [project]arXiv 2026VideoAgent: All-in-One Framework for Video Understanding and Editing. [paper] [code]CVPR 2026VISTA: A Test-Time Self-Improving Video Generation Agent. [paper] [project]
2025
CVPR 2025Divot: Diffusion Powers Video Tokenizer for Comprehension and Generation. [paper] [code]arXiv 2025Does Understanding Inform Generation in Unified Multimodal Models? From Analysis to Path Forward. [paper] [code]arXiv 2025Emerging Properties in Unified Multimodal Pretraining. [paper] [code] [project]arXiv 2025Emu3.5: Native Multimodal Models Are World Learners. [paper] [code]arXiv 2025HaploOmni: Unified Single Transformer for Multimodal Video Understanding and Generation. [paper] [code]CVPR 2025Janus: Decoupling Visual Encoding for Unified Multimodal Understanding and Generation. [paper] [code]NeurIPS 2025JavisGPT: A Unified Multi-Modal LLM for Sounding-Video Comprehension and Generation. [paper] [code] [project]arXiv 2025Omni-Video: Democratizing Unified Video Understanding and Generation. [paper] [code] [project]NeurIPS 2025Show-o2: Improved Native Unified Multimodal Models. [paper] [code]ICLR 2025Show-o: One Single Transformer to Unify Multimodal Understanding and Generation. [paper] [code]arXiv 2025Towards Reason-Informed Video Editing in Unified Models with Self-Reflective Learning. [paper]arXiv 2025Transfer Between Modalities with MetaQueries. [paper] [code] [project]ICLR 2025Transfusion: Predict the Next Token and Diffuse Images with One Multi-Modal Model. [paper]arXiv 2025Unified Reward Model for Multimodal Understanding and Generation. [paper] [code] [project]arXiv 2025UniUGP: Unifying Understanding, Generation, and Planing for End-to-End Autonomous Driving. [paper] [project]arXiv 2025UniVA: Universal Video Agent Towards Open-Source Next-Generation Video Generalist. [paper] [project]arXiv 2025UniVid: The Open-Source Unified Video Model. [paper] [code] [project]ICLR 2025VILA-U: A Unified Foundation Model Integrating Visual Understanding and Generation. [paper] [code] [project]
2024
arXiv 2024Chameleon: Mixed-Modal Early-Fusion Foundation Models. [paper] [code]ICLR 2024DreamLLM: Synergistic Multimodal Comprehension and Creation. [paper] [code] [project]arXiv 2024Emu3: Next-Token Prediction Is All You Need. [paper] [code] [project]CVPR 2024Generative Multimodal Models Are In-Context Learners. [paper] [code] [project]ACM MM 2024GPT4Video: A Unified Multimodal Large Language Model for Instruction-Followed Understanding and Safety-Aware Generation. [paper]ICLR 2024Making LLaMA SEE and Draw with SEED Tokenizer. [paper] [code] [project]ICML 2024NExT-GPT: Any-to-Any Multimodal LLM. [paper] [code] [project]ICML 2024Video-LaVIT: Unified Video-Language Pre-Training with Decoupled Visual-Motional Tokenization. [paper] [code] [project]arXiv 2024VideoAgent: Self-Improving Video Generation. [paper] [code] [project]
2023
2020
arXiv 2020UniVL: A Unified Video and Language Pre-Training Model for Multimodal Understanding and Generation. [paper] [code]
Interacting with the World
Video world models, action-conditioned prediction, interactive simulation, persistent memory, physical grounding, planning, robotics, and driving.
Years: 2027 · 2026 · 2025 · 2024 · 2023 · 2018.
2027
ICPR 2027DrivingWorld: Constructing World Model for Autonomous Driving via Video GPT. [paper] [code]
2026
arXiv 2026Action Forcing: Training World Models on Unsupervised Video by Recovering Underlying Egomotion Bases. [paper]arXiv 2026Addressable Memory for Video World Models. [paper] [project]arXiv 2026Aero-World: Action-Conditioned Aerial Video Generation from Inertial Controls. [paper]ECCV 2026AnchorWeave: World-Consistent Video Generation with Retrieved Local Spatial Memories. [paper] [code] [project]arXiv 2026BiWM: Advancing Open-Source Interactive Video World Models with Bidirectional Autoregression. [paper] [code]arXiv 2026Causal Forcing++: Scalable Few-Step Autoregressive Diffusion Distillation for Real-Time Interactive Video Generation. [paper] [code]ICML 2026Causal Forcing: Autoregressive Diffusion Distillation Done Right for High-Quality Real-Time Interactive Video Generation. [paper] [code] [project]ICML 2026Causal-JEPA: Learning World Models Through Object-Level Latent Masking. [paper] [code] [project]ICLR 2026Ctrl-World: A Controllable Generative World Model for Robot Manipulation. [paper] [code] [project]arXiv 2026Delta Forcing: Trust Region Steering for Interactive Autoregressive Video Generation. [paper]ICML 2026DreamDojo: A Generalist Robot World Model from Large-Scale Human Videos. [paper] [code] [project]arXiv 2026EA-WM: Event-Aware Generative World Model with Structured Kinematic-to-Visual Action Fields. [paper] [code]arXiv 2026Echo-Infinity: Learning Evolving Memory for Real-Time Infinite Video Generation. [paper] [code] [project]arXiv 2026FLEX-WAM: Flexible Block-Causal World-Action Models for Long-Horizon Imagination and Planning. [paper]arXiv 2026GE-Sim 2.0: A Roadmap Towards Comprehensive Closed-Loop Video World Simulators for Robotic Manipulation. [paper] [code] [project]arXiv 2026Geometry-Aware Implicit Memory for Video World Models. [paper] [code] [project]arXiv 2026GigaWorld-1: A Roadmap to Build World Models for Robot Policy Evaluation. [paper] [project]arXiv 2026H-JEPA: End-to-End Learning of Hierarchical World Models for Visual Planning. [paper] [code] [project]arXiv 2026Honeycomb: Constant-Size Scene Memory Representation for Video World Models. [paper] [code] [project]ICLR 2026Horizon Imagination: Efficient On-Policy Rollout in Diffusion World Models. [paper] [code]arXiv 2026Keepsake: Selective Spatial Memory for Long-Horizon Video Generation. [paper]arXiv 2026LaWAM: Latent World Action Models for Efficient Dynamics-Aware Robot Policies. [paper] [code] [project]arXiv 2026LeWorldModel: Stable End-to-End Joint-Embedding Predictive Architecture from Pixels. [paper] [code] [project]ICML 2026Light Forcing: Accelerating Autoregressive Video Diffusion via Sparse Attention. [paper] [code]ICML 2026LIVE: Long-Horizon Interactive Video World Modeling. [paper] [code] [project]arXiv 2026LiveWorld: Simulating Out-of-Sight Dynamics in Generative Video World Models. [paper] [code] [project]arXiv 2026Matrix-Game 3.5: Enhancing Real-Time Streaming Interactive World Models with Patch Memory. [paper] [code] [project]arXiv 2026minWM: A Full-Stack Open-Source Framework for Real-Time Interactive Video World Models. [paper] [code]arXiv 2026MultiWorld: Scalable Multi-Agent Multi-View Video World Models. [paper] [code] [project]arXiv 2026Next Forcing: Causal World Modeling with Multi-Chunk Prediction. [paper] [code] [project]arXiv 2026NVIDIA OmniDreams: Real-Time Generative World Model for Closed-Loop Autonomous Vehicle Simulation. [paper] [code] [project]arXiv 2026One-Forcing: Towards Stable One-Step Autoregressive Video Generation. [paper] [code] [project]arXiv 2026OneWorld: Learning Consistent Physics Across Actions in World Models. [paper]CVPR 2026PHANTOM: Physics-Infused Video Generation via Joint Modeling of Visual and Latent Physical Dynamics. [paper] [project]ECCV 2026PhyGDPO: Physics-Aware Groupwise Direct Preference Optimization for Physically Consistent Text-to-Video Generation. [paper] [code] [project]3DV 2026PhysMotion: Physics-Grounded Dynamics from a Single Image. [paper] [project]ICLR 2026Rolling Forcing: Autoregressive Long Video Diffusion in Real Time. [paper] [code] [project]arXiv 2026Solaris: Building a Multiplayer Video World Model in Minecraft. [paper] [project]arXiv 2026SolarWM: Open Data and Scalable Training for Long-Horizon Video World Models. [paper] [code] [project]arXiv 2026Spatial Memory Intelligence: Endowing World Models with Understanding-Driven Long-Term Memory. [paper] [project]arXiv 2026Training Object Permanence in World Models. [paper] [project]ICLR 2026Vid2World: Crafting Video Diffusion Models to Interactive World Models. [paper] [code] [project]arXiv 2026Video = World + Event Stream. [paper] [project]arXiv 2026Vidu S1: A Real-Time Interactive Video Generation Model. [paper]arXiv 2026Vidu S2: Real-Time Interactive, Editable, and Spatial Video Generation. [paper] [project]arXiv 2026Waypoint-1.5: A Real-Time Video World Model for Consumer Hardware. [paper] [code] [project]ICLR 2026World-in-World: World Models in a Closed-Loop World. [paper] [code] [project]arXiv 2026World-Language-Action Model for Unified World Modeling, Language Reasoning, and Action Synthesis. [paper] [code]arXiv 2026World-VLA-Loop: Closed-Loop Learning of Video World Model and VLA Policy. [paper] [code] [project]ICML 2026WorldCache: Accelerating World Models for Free via Heterogeneous Token Caching. [paper] [code]arXiv 2026WorldDirector: Building Controllable World Simulators with Persistent Dynamic Memory. [paper] [code] [project]arXiv 2026X-World: Controllable Ego-Centric Multi-Camera World Models for Scalable End-to-End Driving. [paper] [project]CVPR 2026Yume1.5: A Text-Controlled Interactive World Generation Model. [paper] [code] [project]
2025
ICML 2025AdaWorld: Learning Adaptable World Models with Latent Actions. [paper] [code] [project]NeurIPS 2025Autoregressive Adversarial Post-Training for Real-Time Interactive Video Generation. [paper] [project]SIGGRAPH Asia 2025Context As Memory: Scene-Consistent Interactive Long Video Generation with Memory Retrieval. [paper] [project]arXiv 2025Cosmos World Foundation Model Platform for Physical AI. [paper] [code] [project]arXiv 2025Cosmos-Drive-Dreams: Scalable Synthetic Driving Data Generation with World Foundation Models. [paper] [code] [project]ICML 2025Diffusion Adversarial Post-Training for One-Step Video Generation. [paper]ICLR 2025Diffusion Models Are Real-Time Game Engines. [paper] [project]ICML 2025DINO-WM: World Models on Pre-Trained Visual Features Enable Zero-Shot Planning. [paper] [code] [project]CoRL 2025DreamGen: Unlocking Generalization in Robot Learning Through Video World Models. [paper] [code] [project]ICLR 2025FasterCache: Training-Free Video Diffusion Model Acceleration with High Quality. [paper] [code]NeurIPS 2025Frame Context Packing and Drift Prevention in Next-Frame-Prediction Video Diffusion Models. [paper] [code] [project]CVPR 2025From Slow Bidirectional to Fast Autoregressive Video Diffusion Models. [paper] [code] [project]arXiv 2025GAIA-2: A Controllable Multi-View Generative World Model for Autonomous Driving. [paper] [project]Report 2025GAIA-3: Scaling World Models to Power Safety and Evaluation. [paper]ICCV 2025GameFactory: Creating New Games with Generative Interactive Videos. [paper] [code] [project] [data]Report 2025Genie 3: A New Frontier for World Models. [paper]arXiv 2025GigaWorld-0: World Models As Data Engine to Empower Embodied AI. [paper] [code] [project]arXiv 2025Hunyuan-GameCraft: High-Dynamic Interactive Game Video Generation with Hybrid History Condition. [paper] [code] [project]ICCV 2025IRASim: A Fine-Grained World Model for Robot Manipulation. [paper] [project]CoRL 2025LaDi-WM: A Latent Diffusion-Based World Model for Predictive Manipulation. [paper] [code] [project]ICML 2025Latent Action Learning Requires Supervision in the Presence of Distractors. [paper] [code] [project]ICLR 2025Latent Action Pretraining from Videos. [paper] [code] [project]ICCV 2025Long-Context State-Space Video World Models. [paper] [project]Nature 2025Mastering Diverse Control Tasks Through World Models. [paper] [code] [project]arXiv 2025Matrix-Game 2.0: An Open-Source Real-Time and Streaming Interactive World Model. [paper] [code] [project]arXiv 2025Matrix-Game: Interactive World Foundation Model. [paper] [code] [project]ICCV 2025Moto: Latent Motion Token As the Bridging Language for Learning Robot Manipulation from Videos. [paper] [code] [project]arXiv 2025MoWM: Mixture-of-World-Models for Embodied Planning via Latent-to-Pixel Feature Modulation. [paper]CVPR 2025Navigation World Models. [paper]NeurIPS 2025PhysCtrl: Generative Physics for Controllable and Physics-Grounded Video Generation. [paper] [code] [project]CVPR 2025PhysGen3D: Crafting a Miniature Interactive World from a Single Image. [paper] [project]arXiv 2025RELIC: Interactive Video World Model with Long-Horizon Memory. [paper] [project]NeurIPS 2025RoboScape: Physics-Informed Embodied World Model. [paper]NeurIPS 2025Self Forcing: Bridging the Train-Test Gap in Autoregressive Video Diffusion. [paper] [code] [project]CVPR 2025Timestep Embedding Tells: It's Time to Cache for Video Diffusion Model. [paper] [code] [project]arXiv 2025Training Agents Inside of Scalable World Models. [paper] [project]arXiv 2025TurboDiffusion: Accelerating Video Diffusion Models by 100-200 Times. [paper] [code]arXiv 2025V-JEPA 2: Self-Supervised Video Models Enable Understanding, Prediction and Planning. [paper] [code]ICML 2025Video Prediction Policy: A Generalist Robot Policy with Predictive Visual Representations. [paper] [code] [project]NeurIPS 2025Video World Models with Long-Term Spatial Memory. [paper] [code] [project]NeurIPS 2025VideoREPA: Learning Physics for Video Generation Through Relational Alignment with Foundation Models. [paper] [code] [project]ICCV 2025VMem: Consistent Interactive Video Scene Generation with Surfel-Indexed View Memory. [paper] [code] [project]arXiv 2025World Models That Know When They Don't Know – Controllable Video Generation with Calibrated Uncertainty. [paper] [code]NeurIPS 2025WorldMem: Long-Term Consistent World Simulation with Memory. [paper] [code] [project]NeurIPS 2025WorldWeaver: Generating Long-Horizon Video Worlds via Rich Perception. [paper] [project]
2024
NeurIPS 2024Diffusion for World Modeling: Visual Details Matter in Atari. [paper] [code] [project]NeurIPS 2024Diffusion Forcing: Next-Token Prediction Meets Full-Sequence Diffusion. [paper] [code] [project]arXiv 2024EVA: An Embodied World Model for Future Video Anticipation. [paper]Report 2024Genie 2: A Large-Scale Foundation World Model. [paper]ICML 2024Genie: Generative Interactive Environments. [paper]arXiv 2024IGOR: Image-GOal Representations Are the Atomic Control Units for Foundation Models in Embodied AI. [paper] [project]NeurIPS 2024iVideoGPT: Interactive VideoGPTs Are Scalable World Models. [paper] [code] [project]ICLR 2024Learning Interactive Real-World Simulators. [paper] [project]ICLR 2024Learning to Act Without Actions. [paper] [code]Project 2024Oasis: A Universe in a Transformer. [paper] [code] [project]arXiv 2024Owl-1: Omni World Model for Consistent Long Video Generation. [paper]arXiv 2024Pandora: Towards General World Model with Natural Language Actions and Video States. [paper] [code] [project]ECCV 2024PhysGen: Rigid-Body Physics-Grounded Image-to-Video Generation. [paper] [code] [project]ICML 2024RoboDreamer: Learning Compositional World Models for Robot Imagination. [paper] [code] [project]ICLR 2024Unleashing Large-Scale Video Generative Pre-Training for Visual Robot Manipulation. [paper] [code] [project]NeurIPS 2024Vista: A Generalizable Driving World Model with High Fidelity and Versatile Controllability. [paper] [code] [project]
2023
arXiv 2023GAIA-1: A Generative World Model for Autonomous Driving. [paper] [project]ICML 2023Temporally Consistent Transformers for Video Generation. [paper]
2018
NeurIPS 2018Recurrent World Models Facilitate Policy Evolution. [paper] [project]ICLR 2018Stochastic Variational Video Prediction. [paper] [project]
Datasets, Benchmarks and Evaluation
Training data, understanding and generation benchmarks, evaluation of world properties, perceptual metrics, and decision-oriented protocols.
Years: 2026 · 2025 · 2024 · 2023 · 2022 · 2021 · 2020 · 2019 · 2018 · 2017 · 2016 · 2015 · 2012 · 2011 · 2004.
2026
ECCV 2026A Large-Scale Game Video Dataset with Action and State Annotations. [paper] [code] [project] [data]arXiv 2026Action100M: A Large-Scale Video Action Dataset. [paper] [code]arXiv 2026AgentVidBench: A Multi-Hop Video Question Answering Benchmark for Evaluating MLLM Agents. [paper] [code]arXiv 2026APM-Bench: Benchmarking Cross-Session Persistent Memory for Egocentric Streaming Video Assistants. [paper] [project]arXiv 2026ARC-Bench: Closed-Loop Replanning Masks Broken Action Ranking in Frozen JEPA World Models. [paper]ECCV 2026Benchmarking Scientific Understanding and Reasoning for Video Generation Using VideoScience-Bench. [paper] [code] [project]Transactions on Machine Learning Research 2026CaliBench: Are the Stochastic Dynamics of Video World Models Physically Calibrated?. [paper] [code]CVPR 2026CaST-Bench: Benchmarking Causal Chain-Grounded Spatio-Temporal Reasoning for Video Question Answering. [paper] [project]arXiv 2026CG-World: A Large-Scale World-State Dataset and Protocol for World Models. [paper]arXiv 2026CRONOS: Benchmarking Counterfactual Physical Consistency in Video Models. [paper] [code] [project]ECCV 2026Deform360: A Massive Multi-View Visuotactile Dataset for Deformable World Models. [paper] [project]arXiv 2026DMC-CF: Dynamic Multimodal CounterFactual QA Benchmark for Causal Reasoning. [paper]WACV 2026Do Generative Video Models Understand Physical Principles?. [paper] [code] [project]IJCV 2026Dr. V: A Hierarchical Perception-Temporal-Cognition Framework to Diagnose Video Hallucination by Fine-Grained Spatial-Temporal Grounding. [paper] [code]ICLR 2026DrivingGen: A Comprehensive Benchmark for Generative Video World Models in Autonomous Driving. [paper] [code] [project]ECCV 2026EgoPolice: A Benchmark for Egocentric Video Understanding in High-Stakes Police Body-Worn Camera Footage. [paper] [code]ECCV 2026Evaluating Reasoning Coherence in Video Generative Models with Text and Visual Hints. [paper] [code] [project]WACV 2026Evaluating Text-to-Image and Text-to-Video Synthesis with a Conditional Frechet Distance. [paper] [code]ECCV 2026From Evaluation to Enhancement: Benchmarking and Improving Think-with-Video Reasoning for Video Generative Models. [paper]arXiv 2026How Should World Models Be Evaluated for Embodied Decision-Making? A Decision-Making-Centric Position. [paper]arXiv 2026IPIBench: Evaluating Interactive Proactive Intelligence of MLLMs Under Continuous Streams. [paper] [code] [project]ICML 2026iWorld-Bench: A Benchmark for Interactive World Models with a Unified Action Generation Framework. [paper] [code] [project] [data]arXiv 2026Long Time No See: Benchmarking VLMs for Out-of-Sight Spatiotemporal Reasoning in Egocentric Videos. [paper] [code]arXiv 2026LongAV-Compass: Towards Unified Evaluation of Minute-Scale Audio-Visual Generation Across T2AV, I2AV, and V2AV. [paper] [code]arXiv 2026LongVidSearch: An Agentic Benchmark for Multi-Hop Evidence Retrieval Planning in Long Videos. [paper] [code]arXiv 2026MBench: A Comprehensive Benchmark on Memory Capability for Video World Models. [paper] [code] [project]ECCV 2026MemoBench: Benchmarking World Modeling in Dynamically Changing Environments. [paper] [code] [project]arXiv 2026MIND: Benchmarking Memory Consistency and Action Control in World Models. [paper] [code] [project]arXiv 2026MiraBench: Evaluating Action-Conditioned Reliability in Robotic World Models. [paper]ICLR 2026MME-Unify: A Comprehensive Benchmark for Unified Multimodal Understanding and Generation Models. [paper] [code] [project]Findings of ACL 2026MSVBench: Towards Human-Level Evaluation of Multi-Shot Video Generation. [paper]arXiv 2026MultiRef-Compass: Towards Comprehensive Evaluation of Multi-Reference-to-Audio-Video Generation. [paper]arXiv 2026MuSS: A Large-Scale Dataset and Cinematic Narrative Benchmark for Multi-Shot Subject-to-Video Generation. [paper] [code] [project]arXiv 2026OmniInteract: Benchmarking Real-World Streaming Interaction for Real-Time Omnimodal Assistants. [paper] [code]arXiv 2026OmniVBench: A Benchmark and Large-Scale Dataset for Omni Reference-to-Video Generation. [paper]ICLR 2026OmniVideoBench: Towards Audio-Visual Understanding Evaluation for Omni MLLMs. [paper] [code] [project]ICLR 2026OmniWorld: A Multi-Domain and Multi-Modal Dataset for 4D World Modeling. [paper] [code] [project]ECCV 2026OpenVE-3M: A Large-Scale High-Quality Dataset for Instruction-Guided Video Editing Supplementary Material. [paper] [code] [project]ECCV 2026Out of Sight, Out of Mind? Evaluating State Evolution in Video World Models. [paper] [project]arXiv 2026OVO-S-Bench: A Hierarchical Benchmark for Streaming Spatial Intelligence in Multimodal LLMs. [paper] [code] [project]CVPR 2026PAI-Bench: A Comprehensive Benchmark for Physical AI. [paper] [code]arXiv 2026PAWBench: How Far Are We from Probabilistically Aligned World Modeling?. [paper] [code] [project]ICLR 2026Phantom-Data: Towards a General Subject-Consistent Video Generation Dataset. [paper] [project]arXiv 2026PhyProbe: Rethinking Physical Consistency Evaluation in Generated Videos. [paper]arXiv 2026PhysEditWorld: A Large-Scale Dataset Toward Physics-Editable World Models. [paper] [code] [project]arXiv 2026PhysicsMind: Sim and Real Mechanics Benchmarking for Physical Reasoning and Prediction in Foundational VLMs and World Models. [paper] [code] [project]ICLR 2026PhyWorldBench: A Comprehensive Evaluation of Physical Realism in Text-to-Video Models. [paper] [code]CVPR 2026RealUnify: Do Unified Models Truly Benefit from Unification? A Comprehensive Benchmark. [paper] [code]arXiv 2026RoboWM-Bench: A Benchmark for Evaluating World Models in Robotic Manipulation. [paper] [code] [project]arXiv 2026stable-worldmodel: A Platform for Reproducible World Modeling Research and Evaluation. [paper] [code] [project]Findings of ACL 2026StreamingEval: A Unified Evaluation Framework Towards Realistic Streaming Video Understanding. [paper] [code]ECCV 2026SVCBench: A Streaming Video Counting Benchmark for Spatial-Temporal State Maintenance. [paper] [code] [project]ICML 2026T2AV-Compass: Towards Unified Evaluation for Text-to-Audio-Video Generation. [paper] [code] [project]arXiv 2026TimeBlind: A Spatio-Temporal Compositionality Benchmark for Video LLMs. [paper] [code] [project]arXiv 2026TorchUMM: A Unified Multimodal Model Codebase for Evaluation, Analysis, and Post-Training. [paper] [code]arXiv 2026TRACE: Temporal Audit and Condition-Aware Evaluation of Streaming Video Understanding. [paper] [code]ACL 2026Uni-MMMU: A Massive Multi-Discipline Multimodal Unified Benchmark. [paper] [code] [project]arXiv 2026UniG2U-Bench: Do Unified Models Advance Multimodal Understanding?. [paper] [project]CVPR 2026UniM: A Unified Any-to-Any Interleaved Multimodal Benchmark. [paper] [code] [project]arXiv 2026UniSAFE: A Comprehensive Benchmark for Safety Evaluation of Unified Multimodal Models. [paper] [code]CVPR 2026UniVBench: Towards Unified Evaluation for Video Foundation Models. [paper] [code]arXiv 2026V2V-Bench: A Comprehensive Benchmark for Video-to-Video Generation Evaluation. [paper]TPAMI 2026VBench++: Comprehensive and Versatile Benchmark Suite for Video Generative Models. [paper] [code] [project]arXiv 2026Video-Index: A Curated Meta-Benchmark for Video Understanding. [paper] [code] [project]arXiv 2026Video-MME-Logical: A Controlled Diagnostic Benchmark for Video Temporal-Logical Reasoning. [paper] [code] [project]arXiv 2026Video-MME-v2: Towards the Next Stage in Benchmarks for Comprehensive Video Understanding. [paper] [code] [project]ACL 2026Video-MMMU: Evaluating Knowledge Acquisition from Multidisciplinary Professional Videos. [paper] [code] [project]arXiv 2026VideoGAIA: A Benchmark for General AI Assistants on Agentic Video Understanding. [paper] [code]arXiv 2026VideoOdyssey: A Benchmark for Ultra-Long-Context and Omni-Modal Video Understanding. [paper] [code] [project]ICLR 2026VideoPhy-2: A Challenging Action-Centric Physical Commonsense Evaluation in Video Generation. [paper] [code] [project]Transactions on Machine Learning Research 2026VideoScore2: Think Before You Score in Generated Video Evaluation. [paper] [code] [project]arXiv 2026WBench: A Comprehensive Multi-Turn Benchmark for Interactive Video World Model Evaluation. [paper] [code] [project]arXiv 2026What Can Latent World Models Know? Physical Information in Multimodal Predictive Representations. [paper] [code] [project]Transactions on Machine Learning Research 2026What Drives Success in Physical Planning with Joint-Embedding Predictive World Models?. [paper] [code]arXiv 2026What-If World: A Causal Benchmark for General World Models in Embodied Scenarios. [paper]arXiv 2026World Embedding Benchmark. [paper] [code]AI Open 2026WorldArena: A Unified Benchmark for Evaluating Perception and Functional Utility of Embodied World Models. [paper] [code] [project]arXiv 2026WorldBench: Benchmarking Physical Understanding of World Models by Isolating Physics Concepts. [paper] [project]ICLR 2026WorldGym: World Model As an Environment for Policy Evaluation. [paper] [code] [project]CVPR 2026WorldLens: Full-Spectrum Evaluations of Driving World Models in Real World. [paper] [code] [project]arXiv 2026WorldMark: A Unified Benchmark Suite for Interactive Video World Models. [paper] [code] [project]arXiv 2026WorldOlympiad: Can Your World Model Survive a Triathlon?. [paper] [code] [project] [data]arXiv 2026WorldRoamBench: An Open-World Benchmark for Long-Horizon Stability of Interactive World Models. [paper] [project]
2025
Transactions on Machine Learning Research 2025A Shortcut-Aware Video-QA Benchmark for Physical Understanding via Minimal Video Pairs. [paper] [code]ICCV 2025ARGUS: Hallucination and Omission Evaluation in Video-LLMs. [paper] [project]ICLR 2025Beyond FVD: An Enhanced Metric for Evaluating Video Generation Distribution Quality. [paper] [code] [project]arXiv 2025CausalVQA: A Physically Grounded Causal Reasoning Benchmark for Video Models. [paper] [code] [project]arXiv 2025DSI-Bench: A Benchmark for Dynamic Spatial Intelligence. [paper] [code] [project]arXiv 2025EWMBench: Evaluating Scene, Motion, and Semantic Quality in Embodied World Models. [paper] [code]CVPR 2025HD-EPIC: A Highly-Detailed Egocentric Video Dataset. [paper] [project]arXiv 2025IntPhys 2: Benchmarking Intuitive Physics Understanding in Complex Synthetic Environments. [paper] [code]CVPR 2025Koala-36M: A Large-Scale Video Dataset Improving Consistency Between Fine-Grained Conditions and Video Content. [paper] [code] [project]ICCV 2025LVBench: An Extreme Long Video Understanding Benchmark. [paper] [code] [project]NeurIPS 2025MJ-Video: Benchmarking and Rewarding Video Generation with Fine-Grained Video Preference. [paper] [code] [project]CVPR 2025MLVU: Benchmarking Multi-Task Long Video Understanding. [paper] [code]arXiv 2025MMSI-Video-Bench: A Holistic Benchmark for Video-Based Spatial Intelligence. [paper] [code] [project]ICCV Workshops 2025NuScenes-SpatialQA: A Spatial Understanding and Reasoning Benchmark for Vision-Language Models in Autonomous Driving. [paper] [project]CVPR 2025OmniDrive: A Holistic Vision-Language Dataset for Autonomous Driving with Counterfactual Reasoning. [paper] [code]CVPR 2025OpenHumanVid: A Large-Scale High-Quality Dataset for Enhancing Human-Centric Video Generation. [paper]ICLR 2025OpenVid-1M: A Large-Scale High-Quality Dataset for Text-to-Video Generation. [paper] [code]CVPR 2025OVO-Bench: How Far Is Your Video-LLMs from Real-World Online Video Understanding?. [paper] [code]arXiv 2025PhyAVBench: A Challenging Audio Physics-Sensitivity Benchmark for Physically Grounded Text-to-Audio-Video Generation. [paper] [code]ICLR 2025PhysBench: Benchmarking and Enhancing Vision-Language Models for Physical World Understanding. [paper] [code] [project]ICCV 2025STI-Bench: Are MLLMs Ready for Precise Spatial-Temporal World Understanding?. [paper] [code] [project]ICLR 2025SVBench: A Benchmark with Temporal Multi-Turn Dialogues for Streaming Video Understanding. [paper] [code] [project]CVPR 2025T2V-CompBench: A Comprehensive Benchmark for Compositional Text-to-Video Generation. [paper] [code] [project]arXiv 2025TempCore: Are Video QA Benchmarks Temporally Grounded?. [paper]ICML 2025Towards World Simulator: Crafting Physical Commonsense-Based Benchmark for Video Generation. [paper] [code] [project]NeurIPS 2025UltraVideo: High-Quality UHD Video Dataset with Comprehensive Captions. [paper] [code] [project]arXiv 2025VBench-2.0: Advancing Video Generation Benchmark Suite for Intrinsic Faithfulness. [paper] [code] [project]CVPR 2025VEU-Bench: Towards Comprehensive Understanding of Video Editing. [paper] [project]CVPR 2025Video-MME: The First-Ever Comprehensive Evaluation Benchmark of Multi-Modal LLMs in Video Analysis. [paper] [project]ICLR 2025VideoPhy: Evaluating Physical Commonsense for Video Generation. [paper] [code]ICCV 2025VMBench: A Benchmark for Perception-Aligned Video Motion Generation. [paper] [code] [project]arXiv 2025WorldEval: World Model As Real-World Robot Policies Evaluator. [paper] [code] [project]NeurIPS 2025WorldModelBench: Judging Video Generation Models As World Models. [paper] [code] [project]arXiv 2025WorldPrediction: A Benchmark for High-Level World Modeling and Long-Horizon Procedural Planning. [paper] [code]ICCV 2025WorldScore: A Unified Evaluation Benchmark for World Generation. [paper] [code] [project]ICML 2025WorldSimBench: Towards Video Generation Models As World Simulators. [paper] [project]
2024
arXiv 2024ACT-Bench: Towards Action Controllable World Models for Autonomous Driving. [paper] [code] [project]NeurIPS 2024ChronoMagic-Bench: A Benchmark for Metamorphic Evaluation of Text-to-Time-Lapse Video Generation. [paper] [code] [project]CVPR 2024DL3DV-10K: A Large-Scale Scene Dataset for Deep Learning-Based 3D Vision. [paper] [code] [project]RSS 2024DROID: A Large-Scale In-the-Wild Robot Manipulation Dataset. [paper] [code] [project]CVPR 2024EvalCrafter: Benchmarking and Evaluating Large Video Generation Models. [paper] [code] [project]arXiv 2024EventHallusion: Diagnosing Event Hallucinations in Video LLMs. [paper] [code]arXiv 2024FrÉchet Video Motion Distance: A Metric for Evaluating Motion Consistency in Videos. [paper] [code]ICLR 2024InternVid: A Large-Scale Video-Text Dataset for Multimodal Understanding and Generation. [paper] [code]NeurIPS 2024LongVideoBench: A Benchmark for Long-Context Interleaved Video-Language Understanding. [paper] [code] [project]NeurIPS 2024MMBench-Video: A Long-Form Multi-Shot Benchmark for Holistic Video Understanding. [paper] [code] [project]CVPR 2024MVBench: A Comprehensive Multi-Modal Video Understanding Benchmark. [paper] [code]CVPR 2024On the Content Bias in Frechet Video Distance. [paper] [code] [project]ICRA 2024Open X-Embodiment: Robotic Learning Datasets and RT-X Models. [paper] [code] [project]CVPR 2024Panda-70M: Captioning 70M Videos with Multiple Cross-Modality Teachers. [paper] [code]ACM MM 2024PanoSent: A Panoptic Sextuple Extraction Benchmark for Multimodal Conversational Aspect-Based Sentiment Analysis. [paper]NeurIPS 2024ShareGPT4Video: Improving Video Understanding and Generation with Better Captions. [paper] [code] [project]ICLR 2024STREAM: Spatio-TempoRal Evaluation and Analysis Metric for Video Generative Models. [paper] [code]Findings of ACL 2024TempCompass: Do Video LLMs Really Understand Videos?. [paper] [code]arXiv 2024TemporalBench: Benchmarking Fine-Grained Temporal Understanding for Multimodal Video Models. [paper] [code] [project]CVPR 2024VBench: Comprehensive Benchmark Suite for Video Generative Models. [paper] [code] [project]arXiv 2024VideoHallucer: Evaluating Intrinsic and Extrinsic Hallucinations in Large Video-Language Models. [paper] [code] [project]EMNLP 2024VideoScore: Building Automatic Metrics to Simulate Fine-Grained Human Feedback for Video Generation. [paper] [code] [project]
2023
NeurIPS 2023EgoSchema: A Diagnostic Benchmark for Very Long-Form Video Language Understanding. [paper] [code] [project]ICLR 2023Evaluating Long-Term Memory in 3D Mazes. [paper] [code]NeurIPS 2023FETV: A Benchmark for Fine-Grained Evaluation of Open-Domain Text-to-Video Generation. [paper] [code]ICCV 2023MeViS: A Large-Scale Benchmark for Video Segmentation with Motion Expressions. [paper] [code] [project]
2022
CVPR 2022Ego4D: Around the World in 3,000 Hours of Egocentric Video. [paper] [code] [project]TPAMI 2022IntPhys 2019: A Benchmark for Visual Intuitive Physics Understanding. [paper] [code]IJCV 2022Rescaling Egocentric Vision: Collection, Pipeline and Challenges for EPIC-KITCHENS-100. [paper] [project]
2021
EMNLP 2021CLIPScore: A Reference-Free Evaluation Metric for Image Captioning. [paper] [code]NeurIPS 2021Detecting Moments and Highlights in Videos via Natural Language Queries. [paper] [code]CVPR 2021NExT-QA: Next Phase of Question-Answering to Explaining Temporal Actions. [paper] [code]NeurIPS 2021Physion: Evaluating Physical Prediction from Vision in Humans and Machines. [paper] [code] [project]CVPR Workshops 2021SoccerNet-v2: A Dataset and Benchmarks for Holistic Understanding of Broadcast Soccer Videos. [paper] [code]NeurIPS 2021STAR: A Benchmark for Situated Reasoning in Real-World Videos. [paper] [code] [project]
2020
CVPR 2020BDD100K: A Diverse Driving Dataset for Heterogeneous Multitask Learning. [paper] [code]ICLR 2020CLEVRER: Collision Events for Video Representation and Reasoning. [paper] [code] [project]CVPR 2020nuScenes: A Multimodal Dataset for Autonomous Driving. [paper] [code] [project]CVPR 2020Scalability in Perception for Autonomous Driving: Waymo Open Dataset. [paper] [code] [project]ECCV 2020URVOS: Unified Referring Video Object Segmentation Network with a Large-Scale Benchmark. [paper]ICASSP 2020VGGSound: A Large-Scale Audio-Visual Dataset. [paper] [code] [project]CVPR 2020Where Does It Exist: Spatio-Temporal Video Grounding for Multi-Form Sentences. [paper] [project]
2019
AAAI 2019ActivityNet-QA: A Dataset for Understanding Complex Web Videos via Question Answering. [paper] [code]CVPR 2019COIN: A Large-Scale Dataset for Comprehensive Instructional Video Analysis. [paper] [project]Interspeech 2019Fréchet Audio Distance: A Reference-Free Metric for Evaluating Music Enhancement Algorithms. [paper] [code]ICCV 2019HowTo100M: Learning a Text-Video Embedding by Watching Hundred Million Narrated Video Clips. [paper] [project]CVPR 2019LaSOT: A High-Quality Benchmark for Large-Scale Single Object Tracking. [paper] [code]ICCV 2019VaTeX: A Large-Scale, High-Quality Multilingual Dataset for Video-and-Language Research. [paper]
2018
ICML Workshop on Theoretical Foundations and Applications of Deep Generative Models 2018A Note on the Inception Score. [paper]ECCV 2018Audio-Visual Event Localization in Unconstrained Videos. [paper] [code]CVPR Workshops 2018SoccerNet: A Scalable Dataset for Action Spotting in Soccer Videos. [paper] [code] [project]CVPR 2018The Unreasonable Effectiveness of Deep Features As a Perceptual Metric. [paper] [code] [project]arXiv 2018Towards Accurate Generative Models of Video: A New Metric & Challenges. [paper] [project]AAAI 2018Towards Automatic Learning of Procedures from Web Instructional Videos. [paper] [code]EMNLP 2018TVQA: Localized, Compositional Video Question Answering. [paper] [code]arXiv 2018YouTube-VOS: A Large-Scale Video Object Segmentation Benchmark. [paper] [project]
2017
ICASSP 2017Audio Set: An Ontology and Human-Labeled Dataset for Audio Events. [paper] [project]CVPR 2017TGIF-QA: Toward Spatio-Temporal Reasoning in Visual Question Answering. [paper] [code]ICCV 2017The "Something Something" Video Database for Learning and Evaluating Visual Common Sense. [paper]arXiv 2017The 2017 DAVIS Challenge on Video Object Segmentation. [paper] [project]arXiv 2017The Kinetics Human Action Video Dataset. [paper]Computer Vision and Image Understanding 2017The THUMOS Challenge on Action Recognition for Videos “in the Wild”. [paper]
2016
arXiv 2016MOT16: A Benchmark for Multi-Object Tracking. [paper] [project]CVPR 2016MSR-VTT: A Large Video Description Dataset for Bridging Video and Language. [paper]
2015
CVPR 2015ActivityNet: A Large-Scale Video Benchmark for Human Activity Understanding. [paper] [code]
2012
arXiv 2012UCF101: A Dataset of 101 Human Actions Classes from Videos in the Wild. [paper]
2011
2004
IEEE Transactions on Image Processing 2004Image Quality Assessment: From Error Visibility to Structural Similarity. [paper] [code] [project]
Surveys and Foundations
Related surveys, conceptual foundations, and general modeling methods that support video and world-model research.
Years: 2026 · 2025 · 2024 · 2023 · 2022 · 2021 · 2020 · 2017 · 2015 · 2014 · 1982.
2026
arXiv 2026A Definition and Roadmap for World Models. [paper]arXiv 2026AI for Games in the Foundation Model Era. [paper] [project]arXiv 2026Towards Interactive Video World Modeling: Frontiers, Challenges, Benchmarks, and Future Trends. [paper] [project]ACM Computing Surveys 2026Understanding World or Predicting Future? A Comprehensive Survey of World Models. [paper] [project]IEEE Transactions on Circuits and Systems for Video Technology 2026Video Understanding with Large Language Models: A Survey. [paper] [project]
2025
arXiv 20253D and 4D World Modeling: A Survey. [paper] [project]ACM Computing Surveys 2025A Survey on Video Diffusion Models. [paper] [project]COLM 2025Tulu 3: Pushing Frontiers in Open Language Model Post-Training. [paper]arXiv 2025Unified Multimodal Understanding and Generation Models: Advances, Challenges, and Opportunities. [paper] [project]
2024
arXiv 2024A Survey on Long Video Generation: Challenges, Methods, and Prospects. [paper]National Science Review 2024A Survey on Multimodal Large Language Models. [paper] [project]arXiv 2024Is Sora a World Simulator? A Comprehensive Survey on General World Models and Beyond. [paper] [project]
2023
2022
Report 2022A Path Towards Autonomous Machine Intelligence. [paper]ICLR 2022Finetuned Language Models Are Zero-Shot Learners. [paper] [code]CVPR 2022Masked Autoencoders Are Scalable Vision Learners. [paper] [code]CVPR 2022MaskGIT: Masked Generative Image Transformer. [paper] [code] [project]
2021
2020
Communications of the ACM 2020Generative Adversarial Networks. [paper]
2017
2015
2014
ICLR 2014Auto-Encoding Variational Bayes. [paper]
1982
Book 1982Vision: A Computational Investigation into the Human Representation and Processing of Visual Information. [book]
BibTeX
Download references.bib for the listed papers. The website also supports single-reference copying and filtered BibTeX downloads. Public bibliographic metadata is available in JSON.
Contributing
Relevant papers, corrected metadata, and category suggestions are welcome. Read the contribution guide, suggest a paper, or open a focused pull request.
Acknowledgements
Thanks to the researchers and open-source communities whose work makes this survey and reference collection possible.
Explore related projects
ytdl-org/youtube-dl
Command-line program to download videos from YouTube.com and other video sites
141,539 starsexcalidraw/excalidraw
Virtual whiteboard for sketching hand-drawn like diagrams
135,559 starsgodotengine/godot
Godot Engine – Multi-platform 2D and 3D game engine
120,003 starsmrdoob/three.js
JavaScript 3D Library.
118,228 stars