
toon-format/toon has 25,605 GitHub stars and 1,123 forks. GitHot measured +3 stars in 24 hours. Last checked 2026-11-04 09:44 UTC. Last push 2026-11-01.
🎒 Token-Oriented Object Notation (TOON) – compact, human-readable serialization of JSON data for LLM prompts. TypeScript SDK, CLI, benchmarks.
What you can do
- 📊 Token-Efficient & Accurate: Matches JSON's retrieval accuracy with fewer tokens – see Benchmarks.
- 🔁 JSON Data Model: Encodes the same objects, arrays, and primitives as JSON with deterministic, lossless round-trips.
- 🛤️ LLM-Friendly Guardrails: [N] declares how many rows, {fields} how wide – so truncated or malformed output can't slip through.
- 📐 Minimal Syntax: Uses indentation instead of braces and minimizes quoting, giving YAML-like readability with CSV-style compactness.
Measured star growth
- in 24h
- +3
- in 7 days
- Collecting history
- in 15 days
- Collecting history
- in 1 month
- Collecting history
Net star changes over overlapping periods, not daily totals. Missing measurements are left blank. Stars measure attention, not software quality.
README.md
Original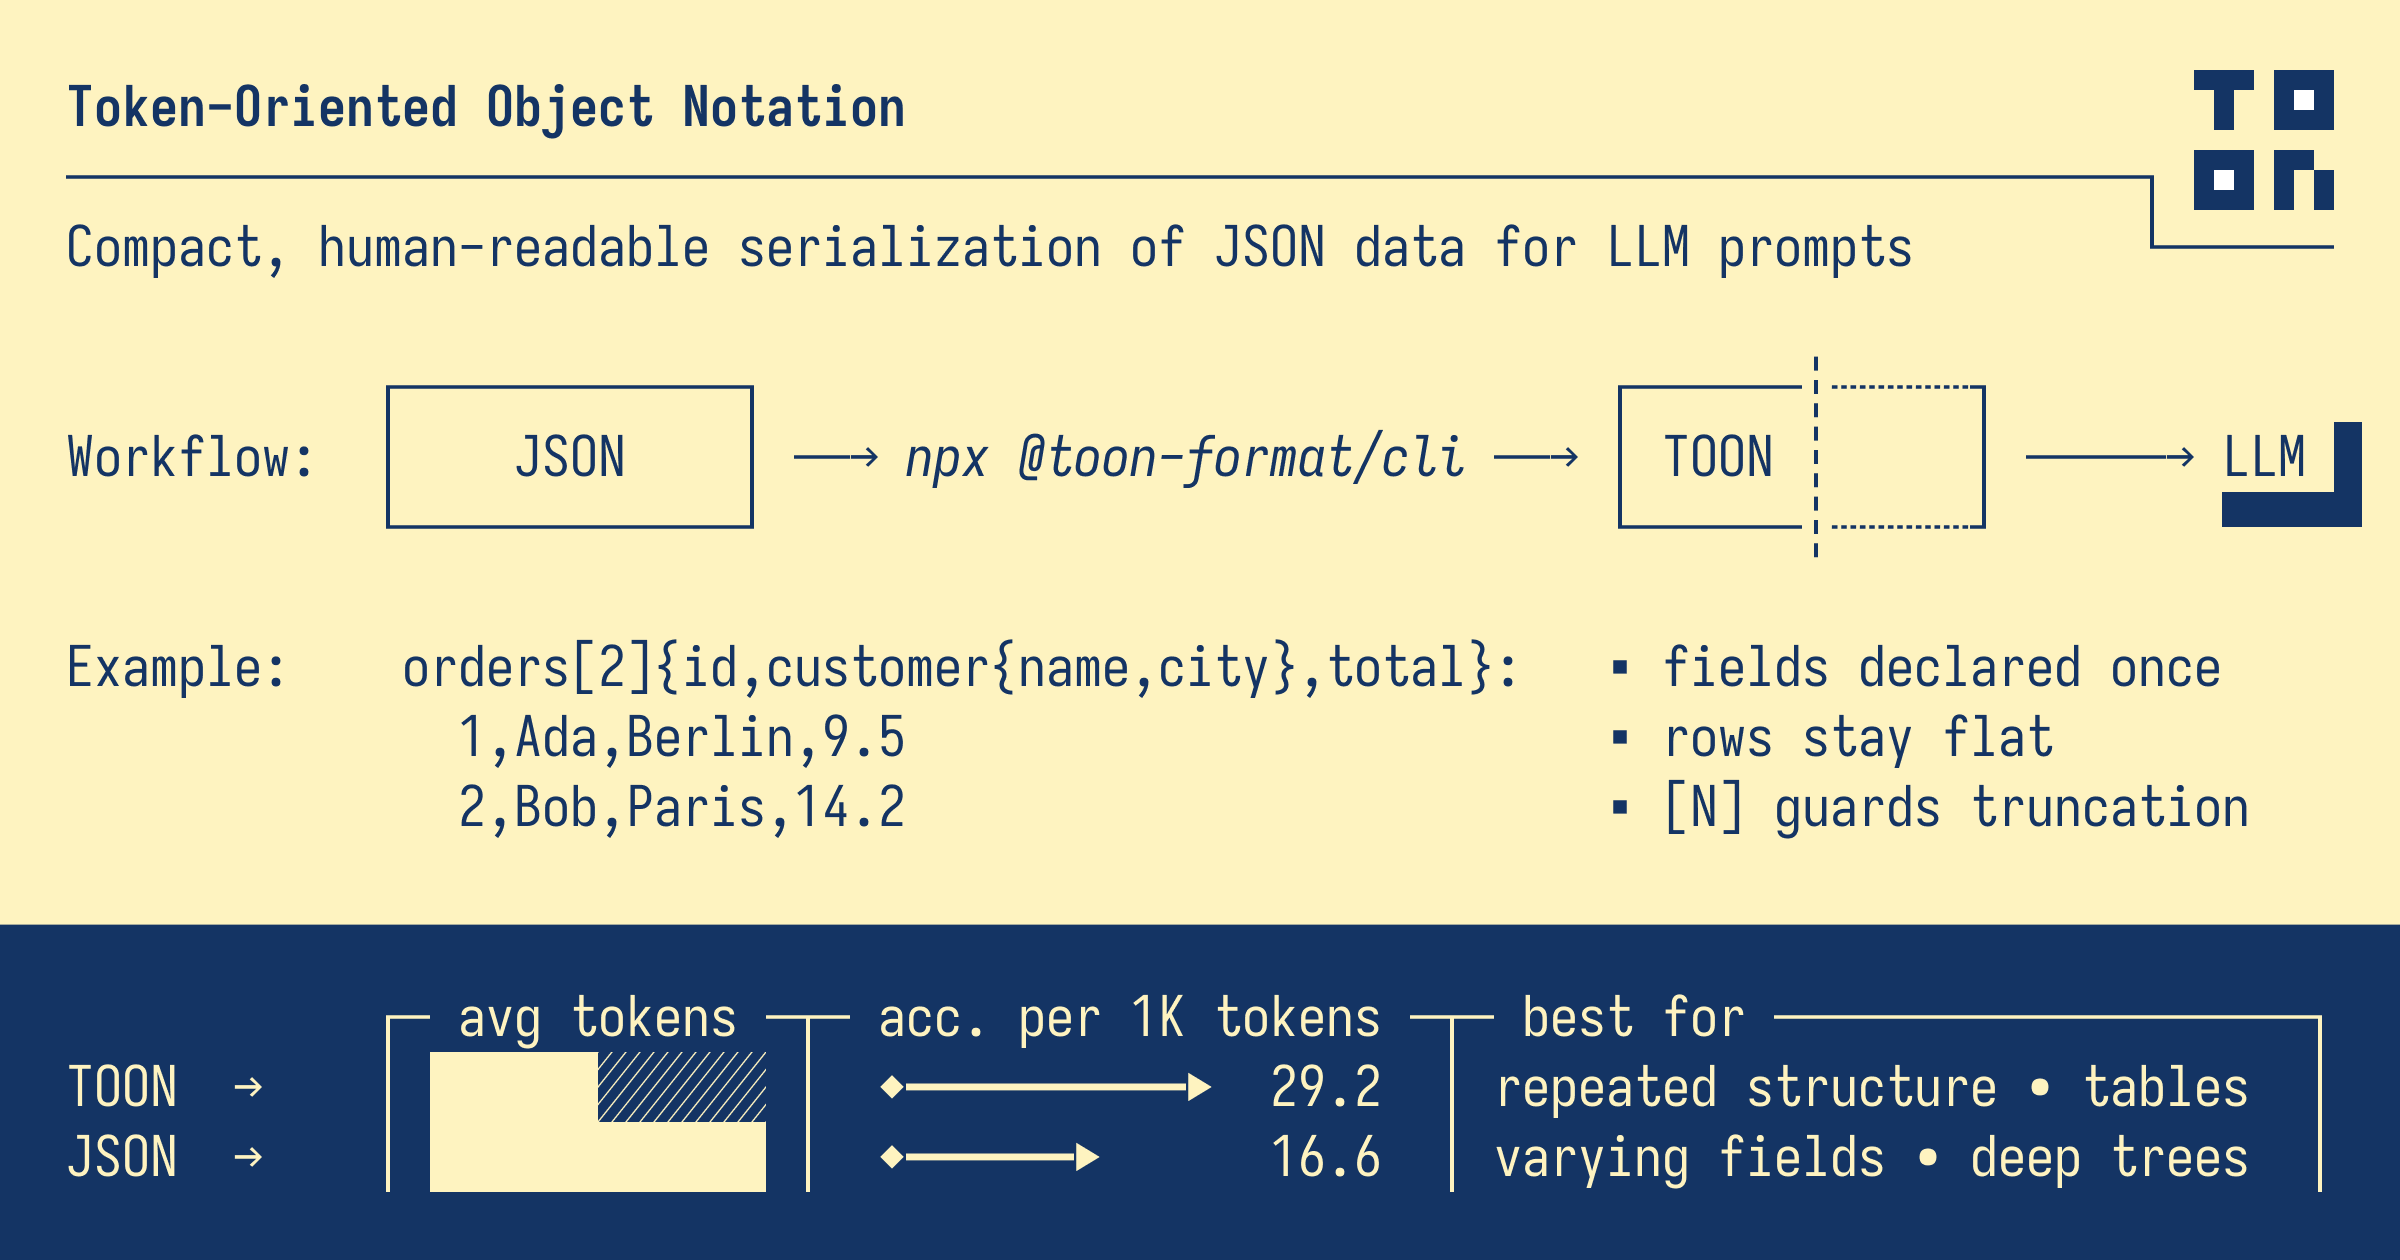
Token-Oriented Object Notation (TOON)


Token-Oriented Object Notation is a compact, human-readable encoding of the JSON data model that minimizes tokens and makes structure easy for models to follow.
TOON combines YAML's indentation-based structure for nested objects with CSV-style tabular forms for uniform data. Its sweet spot is uniform objects – same fields across items, whether in an array or keyed by ID – reaching CSV-like compactness while adding explicit structure that helps LLMs parse and validate data reliably. For deeply nested or non-uniform data, JSON may be more efficient.
Think of it as a translation layer: use JSON programmatically, and encode it as TOON for LLM input – a drop-in, lossless representation of the JSON you already have.
[!TIP] The TOON format is stable, but also an idea in progress. Nothing's set in stone – help shape where it goes by contributing to the spec or sharing feedback.
Table of Contents
- Why TOON?
- Key Features
- When Not to Use TOON
- Benchmarks
- Installation & Quick Start
- CLI
- Using TOON with LLMs
- Ecosystem
- Documentation
- Media Type & File Extension
- 📋 Full Specification
Why TOON?
LLM tokens cost money – and JSON spends a lot of them on structure. A weather forecast in TOON:
location:
  city: Berlin
  country: DE
  units: metric
alerts[2]: frost,wind
forecast[3]{day,temp{min,max},condition,rainChance}:
  Mon,-2,4,snow,80
  Tue,1,7,cloudy,20
  Wed,3,11,sunny,5
The same data as JSON – ~117 tokens against TOON's ~66:
{
  "location": {
    "city": "Berlin",
    "country": "DE",
    "units": "metric"
  },
  "alerts": [
    "frost",
    "wind"
  ],
  "forecast": [
    {
      "day": "Mon",
      "temp": {
        "min": -2,
        "max": 4
      },
      "condition": "snow",
      "rainChance": 80
    },
    {
      "day": "Tue",
      "temp": {
        "min": 1,
        "max": 7
      },
      "condition": "cloudy",
      "rainChance": 20
    },
    {
      "day": "Wed",
      "temp": {
        "min": 3,
        "max": 11
      },
      "condition": "sunny",
      "rainChance": 5
    }
  ]
}
Three things are happening at once in the TOON above. Two are forms – one rendering of a value, picked automatically from the data's shape – and the third is a header feature:
alerts[2]: frost,windis inline form: a primitive array on its header line.forecast[3]{day,…}:is tabular form: the field list is declared once in the header, then one row per element.temp{min,max}inside that header is a nested field group: the uniform nestedtempobjects fold into the header while rows stay flat.
The third form is keyed tabular, for objects whose values are uniform objects – config maps, feature flags, records by ID. The colon after the length ([2:]) marks it, and each row carries its own key:
| JSON | TOON |
|---|---|
| |
Anything that fits none of these – mixed types, non-uniform objects – falls back to the fourth form, list form: one - item per element, or a bare - for an empty object. Those four cover the shapes; the Format Overview covers the rest.
[!TIP] Try it on your own data – no install required:
cat data.json | npx @toon-format/cli --statsIt prints the TOON alongside what the conversion saved – on the weather forecast above, that's:
ℹ Token estimates: ~117 (JSON) → ~66 (TOON)
✔ Saved ~51 tokens (-43.6%)
Key Features
- 📊 Token-Efficient & Accurate: Matches JSON's retrieval accuracy with fewer tokens – see Benchmarks.
- 🔁 JSON Data Model: Encodes the same objects, arrays, and primitives as JSON with deterministic, lossless round-trips.
- 🛤️ LLM-Friendly Guardrails:
[N]declares how many rows,{fields}how wide – so truncated or malformed output can't slip through. - 📐 Minimal Syntax: Uses indentation instead of braces and minimizes quoting, giving YAML-like readability with CSV-style compactness.
- 🧺 Tabular Forms: Uniform objects – in an array or under keys – declare the field list once, then stream one row each.
- 🌐 Multi-Language Ecosystem: Official implementations, plus dozens of community ports, all targeting one spec with a shared conformance test suite.
When Not to Use TOON
TOON excels with arrays of uniform objects. Reach for something else when:
- Structures are deeply nested or non-uniform (tabular eligibility ≈ 0%) – compact JSON often wins outright.
- Arrays are semi-uniform (~40–60% eligibility) – savings shrink; stay on JSON if your pipeline already speaks it.
- Data is purely tabular – CSV is smaller. TOON's ~5–10% overhead buys declared lengths, field lists, and delimiter scoping, which is a reliability trade, not a size one.
- Latency dominates – some deployments (notably local or quantized models) process compact JSON faster despite the higher token count. Measure TTFT and total time on your own setup.
Benchmarks below quantify the token and accuracy trade-offs; latency is the one you have to measure yourself.
Benchmarks
Two tracks, so every comparison is like-for-like:
- Mixed-Structure Track: Nested and semi-uniform datasets (TOON vs JSON, YAML, XML). CSV is excluded – it cannot represent these structures without lossy flattening.
- Flat-Only Track: Flat, fully tabular-eligible datasets, where CSV is a fair competitor.
Retrieval Accuracy
Benchmarks test LLM comprehension across different input formats using 244 data retrieval questions on 4 models.
Show Dataset Catalog
Dataset Catalog
| Dataset | Rows | Structure | CSV Support | Eligibility |
|---|---|---|---|---|
| Uniform employee records | 100 | uniform | ✓ | 100% |
| E-commerce orders with nested structures | 50 | nested | ✗ | 33% |
| Time-series analytics data | 60 | uniform | ✓ | 100% |
| Top 100 GitHub repositories | 100 | uniform | ✓ | 100% |
| Semi-uniform event logs | 75 | semi-uniform | ✗ | 50% |
| Deeply nested configuration | 1 | deep | ✗ | 0% |
| Valid complete dataset (control) | 20 | uniform | ✓ | 100% |
| Array truncated: 3 rows removed from end | 20 | uniform | ✓ | 100% |
| Extra rows added beyond declared length | 20 | uniform | ✓ | 100% |
| Inconsistent field count (missing salary in row 10) | 20 | uniform | ✓ | 100% |
| Missing required fields (no email in multiple rows) | 20 | uniform | ✓ | 100% |
| Feature flags keyed by name | 40 | uniform | ✗ | 100% |
| Contacts with nested address and plan groups | 50 | nested | ✗ | 100% |
Structure classes:
- uniform: All objects have identical fields with primitive values
- semi-uniform: Mix of uniform and non-uniform structures
- nested: Objects with nested structures (nested objects or arrays)
- deep: Highly nested with minimal tabular eligibility
CSV Support: ✓ (supported), ✗ (not supported – would require lossy flattening)
Eligibility: Percentage of arrays and keyed maps that qualify for TOON's tabular forms (uniform records whose fields are primitives or uniform nested objects folded into nested field groups)
Efficiency Ranking (Accuracy per 1K Tokens)
Each format ranked by efficiency (accuracy percentage per 1,000 tokens):
TOON           ████████████████████   29.2 acc%/1K tok  │  72.2%  ±2.8 acc  │  2,474 tokens
JSON compact   ████████████████░░░░   23.8 acc%/1K tok  │  69.0%  ±2.9 acc  │  2,892 tokens
YAML           ██████████████░░░░░░   20.1 acc%/1K tok  │  70.1%  ±2.9 acc  │  3,487 tokens
JSON           ███████████░░░░░░░░░   16.6 acc%/1K tok  │  71.4%  ±2.8 acc  │  4,308 tokens
XML            ██████████░░░░░░░░░░   14.4 acc%/1K tok  │  70.7%  ±2.9 acc  │  4,909 tokens
Efficiency score = (Accuracy % ÷ Tokens) × 1,000. Higher is better.
[!TIP] TOON achieves 72.2% accuracy (vs JSON's 71.4%) while using 42.6% fewer tokens.
[!NOTE] CSV is excluded from the ranking as it only supports 109 of 244 questions (flat tabular data only). While CSV is highly token-efficient for simple tabular data, it cannot represent nested structures that other formats handle.
Accuracy on Flat Datasets
Every format answers the same 109 flat-dataset questions per model, so CSV can be compared on equal footing here.
| Format | Accuracy | Correct/Total | Avg Tokens |
|---|---|---|---|
toon |
63.1% ±4.5 | 275/436 | 1,994 |
csv |
62.2% ±4.5 | 271/436 | 1,851 |
json-pretty |
60.3% ±4.6 | 263/436 | 3,950 |
xml |
60.1% ±4.6 | 262/436 | 4,516 |
yaml |
59.9% ±4.6 | 261/436 | 3,270 |
json-compact |
58.0% ±4.6 | 253/436 | 2,718 |
Per-Model Accuracy
Accuracy across 4 LLMs on 244 data retrieval questions:
claude-haiku-4-5-20251001
→ TOON           █████████████░░░░░░░    65.6% ±5.9 (160/244)
  JSON           █████████████░░░░░░░    63.5% ±6.0 (155/244)
  XML            ████████████░░░░░░░░    62.3% ±6.0 (152/244)
  YAML           ████████████░░░░░░░░    62.3% ±6.0 (152/244)
  JSON compact   ████████████░░░░░░░░    61.9% ±6.0 (151/244)
  CSV            ██████████░░░░░░░░░░    49.5% ±9.2 (54/109)

gemini-3.6-flash
→ TOON           ██████████████░░░░░░    69.3% ±5.8 (169/244)
  JSON           ██████████████░░░░░░    68.4% ±5.8 (167/244)
  YAML           ██████████████░░░░░░    67.6% ±5.8 (165/244)
  XML            █████████████░░░░░░░    65.2% ±5.9 (159/244)
  JSON compact   █████████████░░░░░░░    63.5% ±6.0 (155/244)
  CSV            ████████████░░░░░░░░    57.8% ±9.1 (63/109)

gpt-5.4-nano
  XML            ████████████░░░░░░░░    59.4% ±6.1 (145/244)
  JSON           ███████████░░░░░░░░░    57.4% ±6.2 (140/244)
→ TOON           ███████████░░░░░░░░░    57.0% ±6.2 (139/244)
  JSON compact   ███████████░░░░░░░░░    54.9% ±6.2 (134/244)
  YAML           ███████████░░░░░░░░░    54.5% ±6.2 (133/244)
  CSV            █████████░░░░░░░░░░░    46.8% ±9.2 (51/109)

grok-4.5
→ TOON           ███████████████████░    97.1% ±2.2 (237/244)
  JSON           ███████████████████░    96.3% ±2.5 (235/244)
  XML            ███████████████████░    95.9% ±2.6 (234/244)
  YAML           ███████████████████░    95.9% ±2.6 (234/244)
  JSON compact   ███████████████████░    95.5% ±2.7 (233/244)
  CSV            ███████████████████░    94.5% ±4.5 (103/109)
[!NOTE] Accuracy figures include Wilson 95% confidence intervals (±); when two formats' intervals overlap, the difference between them is not statistically meaningful. CSV answers only the 109 flat-dataset questions, so its per-model cells cover a smaller, easier population than the other formats.
Performance by dataset and question type
Performance by Question Type
| Question Type | TOON | JSON | XML | YAML | JSON compact | CSV |
|---|---|---|---|---|---|---|
| Field Retrieval | 97.8% | 99.2% | 99.2% | 99.7% | 98.9% | 100.0% |
| Aggregation | 48.4% | 48.4% | 46.0% | 46.0% | 45.2% | 32.8% |
| Filtering | 38.0% | 41.1% | 37.5% | 40.1% | 38.0% | 33.3% |
| Structure Awareness | 90.3% | 84.0% | 84.0% | 79.2% | 78.5% | 82.8% |
| Structural Validation | 100.0% | 50.0% | 80.0% | 50.0% | 45.0% | 80.0% |
Performance by Dataset
Uniform employee records
| Format | Accuracy | Tokens | Correct/Total |
|---|---|---|---|
csv |
64.6% | 2,336 | 106/164 |
toon |
62.8% | 2,537 | 103/164 |
json-compact |
62.2% | 3,919 | 102/164 |
yaml |
64.0% | 4,982 | 105/164 |
json-pretty |
62.2% | 6,326 | 102/164 |
xml |
61.0% | 7,286 | 100/164 |
E-commerce orders with nested structures
| Format | Accuracy | Tokens | Correct/Total |
|---|---|---|---|
json-compact |
70.7% | 6,875 | 116/164 |
toon |
71.3% | 7,344 | 117/164 |
yaml |
72.0% | 8,456 | 118/164 |
json-pretty |
71.3% | 10,842 | 117/164 |
xml |
74.4% | 12,180 | 122/164 |
Time-series analytics data
| Format | Accuracy | Tokens | Correct/Total |
|---|---|---|---|
csv |
64.2% | 1,408 | 77/120 |
toon |
63.3% | 1,595 | 76/120 |
json-compact |
59.2% | 2,351 | 71/120 |
yaml |
62.5% | 2,951 | 75/120 |
json-pretty |
65.0% | 3,678 | 78/120 |
xml |
62.5% | 4,386 | 75/120 |
Top 100 GitHub repositories
| Format | Accuracy | Tokens | Correct/Total |
|---|---|---|---|
toon |
57.6% | 9,017 | 76/132 |
csv |
54.5% | 8,726 | 72/132 |
json-compact |
53.8% | 11,650 | 71/132 |
yaml |
53.8% | 13,350 | 71/132 |
json-pretty |
55.3% | 15,350 | 73/132 |
xml |
53.8% | 17,304 | 71/132 |
Semi-uniform event logs
| Format | Accuracy | Tokens | Correct/Total |
|---|---|---|---|
json-compact |
56.7% | 4,793 | 68/120 |
toon |
60.8% | 5,814 | 73/120 |
json-pretty |
60.0% | 6,759 | 72/120 |
yaml |
55.0% | 5,798 | 66/120 |
xml |
50.8% | 7,668 | 61/120 |
Deeply nested configuration
| Format | Accuracy | Tokens | Correct/Total |
|---|---|---|---|
json-compact |
91.4% | 562 | 106/116 |
yaml |
93.1% | 675 | 108/116 |
toon |
91.4% | 669 | 106/116 |
json-pretty |
94.8% | 918 | 110/116 |
xml |
94.0% | 1,007 | 109/116 |
Valid complete dataset (control)
| Format | Accuracy | Tokens | Correct/Total |
|---|---|---|---|
toon |
100.0% | 566 | 4/4 |
json-compact |
100.0% | 772 | 4/4 |
yaml |
100.0% | 984 | 4/4 |
json-pretty |
100.0% | 1,259 | 4/4 |
xml |
0.0% | 1,441 | 0/4 |
csv |
0.0% | 473 | 0/4 |
Array truncated: 3 rows removed from end
| Format | Accuracy | Tokens | Correct/Total |
|---|---|---|---|
csv |
100.0% | 408 | 4/4 |
toon |
100.0% | 498 | 4/4 |
xml |
100.0% | 1,229 | 4/4 |
json-pretty |
0.0% | 1,075 | 0/4 |
yaml |
0.0% | 841 | 0/4 |
json-compact |
0.0% | 660 | 0/4 |
Extra rows added beyond declared length
| Format | Accuracy | Tokens | Correct/Total |
|---|---|---|---|
csv |
100.0% | 547 | 4/4 |
toon |
100.0% | 644 | 4/4 |
xml |
100.0% | 1,663 | 4/4 |
json-pretty |
0.0% | 1,452 | 0/4 |
yaml |
0.0% | 1,135 | 0/4 |
json-compact |
0.0% | 893 | 0/4 |
Inconsistent field count (missing salary in row 10)
| Format | Accuracy | Tokens | Correct/Total |
|---|---|---|---|
csv |
100.0% | 470 | 4/4 |
toon |
100.0% | 563 | 4/4 |
json-compact |
75.0% | 767 | 3/4 |
xml |
100.0% | 1,432 | 4/4 |
yaml |
75.0% | 977 | 3/4 |
json-pretty |
75.0% | 1,251 | 3/4 |
Missing required fields (no email in multiple rows)
| Format | Accuracy | Tokens | Correct/Total |
|---|---|---|---|
csv |
100.0% | 442 | 4/4 |
toon |
100.0% | 535 | 4/4 |
xml |
100.0% | 1,386 | 4/4 |
yaml |
75.0% | 941 | 3/4 |
json-pretty |
75.0% | 1,207 | 3/4 |
json-compact |
50.0% | 732 | 2/4 |
Feature flags keyed by name
| Format | Accuracy | Tokens | Correct/Total |
|---|---|---|---|
toon |
97.1% | 931 | 66/68 |
json-compact |
94.1% | 1,264 | 64/68 |
yaml |
92.6% | 1,443 | 63/68 |
json-pretty |
95.6% | 1,873 | 65/68 |
xml |
95.6% | 2,306 | 65/68 |
Contacts with nested address and plan groups
| Format | Accuracy | Tokens | Correct/Total |
|---|---|---|---|
toon |
94.4% | 1,444 | 68/72 |
json-compact |
91.7% | 2,357 | 66/72 |
yaml |
94.4% | 2,797 | 68/72 |
json-pretty |
97.2% | 4,014 | 70/72 |
xml |
98.6% | 4,534 | 71/72 |
Run Configuration
- Models tested:
claude-haiku-4-5-20251001,gemini-3.6-flash,gpt-5.4-nano,grok-4.5 - Formats compared: TOON, JSON, XML, YAML, JSON compact, CSV
- Token counting: Using
gpt-tokenizerwitho200k_baseencoding (GPT-5 tokenizer). Other providers tokenize differently, so absolute counts are tokenizer-specific; relative differences between formats hold directionally. - Reasoning: Disabled via the AI SDK's universal
reasoning: 'none'(Gemini 3 floors at minimal thinking,grok-4.5atlow) - Temperature: Not set (models use their defaults)
- Total evaluations: 244 questions × 6 formats × 4 models = 5,856 LLM calls
What the datasets contain, how the questions are generated, and how answers are validated is documented in the benchmark README.
Token Efficiency
Token counts are measured using the GPT-5 o200k_base tokenizer via gpt-tokenizer. Savings are calculated against formatted JSON (2-space indentation) as the primary baseline, with additional comparisons to compact JSON (minified), YAML, and XML. Actual savings vary by model and tokenizer.
The benchmarks test datasets across different structural patterns (uniform, semi-uniform, nested, deeply nested) to show where TOON excels and where other formats may be better.
Mixed-Structure Track
Datasets with nested or semi-uniform structures. CSV excluded as it cannot properly represent these structures.
🛒 E-commerce orders with nested structures  ┊  Tabular: 33%
   │
   TOON                █████████████░░░░░░░    72,832 tokens
   ├─ vs JSON          (−32.9%)               108,611 tokens
   ├─ vs JSON compact  (+5.6%)                 68,944 tokens
   ├─ vs YAML          (−14.0%)                84,701 tokens
   └─ vs XML           (−40.4%)               122,119 tokens

🧾 Semi-uniform event logs  ┊  Tabular: 50%
   │
   TOON                █████████████████░░░   154,084 tokens
   ├─ vs JSON          (−15.0%)               181,201 tokens
   ├─ vs JSON compact  (+19.9%)               128,529 tokens
   ├─ vs YAML          (−0.8%)                155,397 tokens
   └─ vs XML           (−25.2%)               205,859 tokens

🧩 Deeply nested configuration  ┊  Tabular: 0%
   │
   TOON                █████████████░░░░░░░       589 tokens
   ├─ vs JSON          (−34.9%)                   905 tokens
   ├─ vs JSON compact  (+6.7%)                    552 tokens
   ├─ vs YAML          (−11.0%)                   662 tokens
   └─ vs XML           (−40.9%)                   997 tokens

📊 Feature flags keyed by name  ┊  Tabular: 100%
   │
   TOON                █████████░░░░░░░░░░░    10,503 tokens
   ├─ vs JSON          (−54.6%)                23,141 tokens
   ├─ vs JSON compact  (−32.8%)                15,635 tokens
   ├─ vs YAML          (−41.3%)                17,905 tokens
   └─ vs XML           (−63.3%)                28,655 tokens

📊 Contacts with nested address and plan groups  ┊  Tabular: 100%
   │
   TOON                ███████░░░░░░░░░░░░░    26,726 tokens
   ├─ vs JSON          (−66.5%)                79,779 tokens
   ├─ vs JSON compact  (−42.9%)                46,791 tokens
   ├─ vs YAML          (−51.8%)                55,475 tokens
   └─ vs XML           (−70.4%)                90,306 tokens

──────────────────────────────────── Total ────────────────────────────────────
   TOON                █████████████░░░░░░░   264,734 tokens
   ├─ vs JSON          (−32.7%)               393,637 tokens
   ├─ vs JSON compact  (+1.6%)                260,451 tokens
   ├─ vs YAML          (−15.7%)               314,140 tokens
   └─ vs XML           (−40.9%)               447,936 tokens
Flat-Only Track
Datasets with flat, fully tabular-eligible data where CSV is applicable.
👥 Uniform employee records  ┊  Tabular: 100%
   │
   CSV                 ███████████████████░    47,153 tokens
   TOON                ████████████████████    49,978 tokens   (+6.0% vs CSV)
   ├─ vs JSON          (−60.7%)               127,061 tokens
   ├─ vs JSON compact  (−36.8%)                79,057 tokens
   ├─ vs YAML          (−50.0%)               100,054 tokens
   └─ vs XML           (−65.9%)               146,605 tokens

📈 Time-series analytics data  ┊  Tabular: 100%
   │
   CSV                 ██████████████████░░     8,383 tokens
   TOON                ████████████████████     9,115 tokens   (+8.7% vs CSV)
   ├─ vs JSON          (−59.0%)                22,245 tokens
   ├─ vs JSON compact  (−35.9%)                14,211 tokens
   ├─ vs YAML          (−49.0%)                17,858 tokens
   └─ vs XML           (−65.8%)                26,616 tokens

⭐ Top 100 GitHub repositories  ┊  Tabular: 100%
   │
   CSV                 ███████████████████░     8,711 tokens
   TOON                ████████████████████     8,937 tokens   (+2.6% vs CSV)
   ├─ vs JSON          (−41.7%)                15,337 tokens
   ├─ vs JSON compact  (−23.2%)                11,640 tokens
   ├─ vs YAML          (−33.0%)                13,337 tokens
   └─ vs XML           (−48.3%)                17,294 tokens

──────────────────────────────────── Total ────────────────────────────────────
   CSV                 ███████████████████░    64,247 tokens
   TOON                ████████████████████    68,030 tokens   (+5.9% vs CSV)
   ├─ vs JSON          (−58.7%)               164,643 tokens
   ├─ vs JSON compact  (−35.2%)               104,908 tokens
   ├─ vs YAML          (−48.2%)               131,249 tokens
   └─ vs XML           (−64.3%)               190,515 tokens
Token counts use gpt-tokenizer with o200k_base encoding (GPT-5 tokenizer). Other providers tokenize differently, so absolute counts are tokenizer-specific; relative differences between formats hold directionally.
Show detailed examples
📈 Time-series analytics data
Savings: 13,130 tokens (59.0% reduction vs JSON)
JSON (22,245 tokens):
{
  "metrics": [
    {
      "date": "2025-01-01",
      "views": 6138,
      "clicks": 174,
      "conversions": 12,
      "revenue": 2712.49,
      "bounceRate": 0.35
    },
    {
      "date": "2025-01-02",
      "views": 4616,
      "clicks": 274,
      "conversions": 34,
      "revenue": 9156.29,
      "bounceRate": 0.56
    },
    {
      "date": "2025-01-03",
      "views": 4460,
      "clicks": 143,
      "conversions": 8,
      "revenue": 1317.98,
      "bounceRate": 0.59
    },
    {
      "date": "2025-01-04",
      "views": 4740,
      "clicks": 125,
      "conversions": 13,
      "revenue": 2934.77,
      "bounceRate": 0.37
    },
    {
      "date": "2025-01-05",
      "views": 6428,
      "clicks": 369,
      "conversions": 19,
      "revenue": 1317.24,
      "bounceRate": 0.3
    }
  ]
}
TOON (9,115 tokens):
metrics[5]{date,views,clicks,conversions,revenue,bounceRate}:
  2025-01-01,6138,174,12,2712.49,0.35
  2025-01-02,4616,274,34,9156.29,0.56
  2025-01-03,4460,143,8,1317.98,0.59
  2025-01-04,4740,125,13,2934.77,0.37
  2025-01-05,6428,369,19,1317.24,0.3
⭐ Top 100 GitHub repositories
Savings: 6,400 tokens (41.7% reduction vs JSON)
JSON (15,337 tokens):
{
  "repositories": [
    {
      "id": 132750724,
      "name": "build-your-own-x",
      "repo": "codecrafters-io/build-your-own-x",
      "description": "Master programming by recreating your favorite technologies from scratch.",
      "createdAt": "2018-05-09T12:03:18Z",
      "updatedAt": "2026-07-23T18:57:15Z",
      "pushedAt": "2026-07-14T19:25:58Z",
      "stars": 530712,
      "watchers": 6778,
      "forks": 50205,
      "defaultBranch": "master"
    },
    {
      "id": 21737465,
      "name": "awesome",
      "repo": "sindresorhus/awesome",
      "description": "😎 Awesome lists about all kinds of interesting topics",
      "createdAt": "2014-07-11T13:42:37Z",
      "updatedAt": "2026-07-23T18:57:24Z",
      "pushedAt": "2026-06-30T18:21:16Z",
      "stars": 488074,
      "watchers": 8292,
      "forks": 36010,
      "defaultBranch": "main"
    },
    {
      "id": 28457823,
      "name": "freeCodeCamp",
      "repo": "freeCodeCamp/freeCodeCamp",
      "description": "freeCodeCamp.org's open-source codebase and curriculum. Learn math, programming,…",
      "createdAt": "2014-12-24T17:49:19Z",
      "updatedAt": "2026-07-22T07:01:33Z",
      "pushedAt": "2026-07-21T18:00:51Z",
      "stars": 452380,
      "watchers": 8590,
      "forks": 45624,
      "defaultBranch": "main"
    }
  ]
}
TOON (8,937 tokens):
repositories[3]{id,name,repo,description,createdAt,updatedAt,pushedAt,stars,watchers,forks,defaultBranch}:
  132750724,build-your-own-x,codecrafters-io/build-your-own-x,Master programming by recreating your favorite technologies from scratch.,"2018-05-09T12:03:18Z","2026-07-23T18:57:15Z","2026-07-14T19:25:58Z",530712,6778,50205,master
  21737465,awesome,sindresorhus/awesome,😎 Awesome lists about all kinds of interesting topics,"2014-07-11T13:42:37Z","2026-07-23T18:57:24Z","2026-06-30T18:21:16Z",488074,8292,36010,main
  28457823,freeCodeCamp,freeCodeCamp/freeCodeCamp,"freeCodeCamp.org's open-source codebase and curriculum. Learn math, programming,…","2014-12-24T17:49:19Z","2026-07-22T07:01:33Z","2026-07-21T18:00:51Z",452380,8590,45624,main
Installation & Quick Start
npm install @toon-format/toon
To keep the CLI around instead of invoking it through npx, install it globally:
npm install -g @toon-format/cli
Example usage:
import { encode } from '@toon-format/toon'

const data = {
  users: [
    { id: 1, name: 'Ada', role: 'admin' },
    { id: 2, name: 'Bob', role: 'user' }
  ]
}

console.log(encode(data))
// users[2]{id,name,role}:
//   1,Ada,admin
//   2,Bob,user
Streaming large datasets:
import { encodeLines } from '@toon-format/toon'

const largeData = await fetchThousandsOfRecords()

// Memory-efficient streaming for large data
for (const line of encodeLines(largeData)) {
  process.stdout.write(`${line}\n`)
}
[!TIP] For streaming decode APIs, see
decodeFromLines()anddecodeStream().
Transforming values with replacer:
import { encode } from '@toon-format/toon'

// Remove sensitive fields
const user = { name: 'Ada', password: 'secret', email: '[email protected]' }
const safe = encode(user, {
  replacer: (key, value) => key === 'password' ? undefined : value
})
// name: Ada
// email: [email protected]
[!TIP] The
replacerfunction provides fine-grained control over encoding, similar toJSON.stringify's replacer but with path tracking. See the API Reference for more examples, including verbatim output withrawString.
CLI
Command-line tool for quick JSON↔TOON conversions, token analysis, and pipeline integration. Auto-detects format from file extension, supports stdin/stdout workflows, and offers delimiter options (comma, tab, pipe) that trade readability for fewer tokens.
# Encode JSON to TOON (auto-detected)
npx @toon-format/cli input.json -o output.toon

# Decode TOON to JSON (auto-detected)
npx @toon-format/cli data.toon -o output.json

# Pipe from stdin (no argument needed)
cat data.json | npx @toon-format/cli
echo '{"name": "Ada"}' | npx @toon-format/cli

# Output to stdout
npx @toon-format/cli input.json

# Show token savings
npx @toon-format/cli data.json --stats
[!TIP] See the full CLI documentation for all options, examples, and advanced usage.
Using TOON with LLMs
TOON works best when you show the format instead of describing it. Once a model sees one tabular example, the header – [N] length plus {fields} field list – tells it how to read the rest. Wrap data in ```toon code blocks for input, and show the expected header template when asking models to generate TOON. Tab delimiters buy further token savings. Full-line # comments are stripped on decode, so hand-annotated prompt data – and model output with explainer lines – still decodes cleanly.
Follow the detailed LLM integration guide for strategies, examples, and validation techniques.
Ecosystem
Playgrounds – the official playground converts JSON or YAML to TOON in real time, compares token counts, and shares experiments by URL. Community alternatives: Format Tokenization Playground, TOON Tools.
Editors – the official VS Code extension (code --install-extension toon-format.toon) adds syntax highlighting; the community TOON Language Support adds validation, conversion, and token analysis. tree-sitter-toon covers Neovim, Helix, Emacs, and Zed; toon.nvim is a Lua-native alternative. Elsewhere, YAML highlighting is a close approximation.
Tooling – Tooner is an MCP proxy that converts JSON tool responses to TOON.
Documentation
Guides and the API and CLI references live at toonformat.dev; ports to other languages are listed under Implementations. The Glossary gives each concept one name, for contributors and tooling.
Media Type & File Extension
TOON files use the .toon extension and the provisional media type text/toon (UTF-8) – see spec §17.
Credits
- Logo design by 鈴木ックス(SZKX)
License
MIT License © 2025-PRESENT Johann Schopplich
Explore related projects
affaan-m/ECC
The agent harness performance optimization system. Skills, instincts, memory, security, and research-first development for Claude Code, Codex, Opencode, Cursor and beyond.
297,161 starsNousResearch/hermes-agent
The agent that grows with you
260,525 starsmultica-ai/andrej-karpathy-skills
A single CLAUDE.md file to improve Claude Code behavior, derived from Andrej Karpathy's observations on LLM coding pitfalls.
229,450 starsfirecrawl/firecrawl
Supercharge your AI agents with data from the web and beyond. Building the library for superintelligence. 🔥
198,458 stars