
stevenpjg/ddpg-aigym
stevenpjg/ddpg-aigym has 275 GitHub stars and 71 forks. GitHot measured 0 stars in 24 hours and 0 in 7 days. Last checked 2026-11-22 05:36 UTC. Last push 2018-03-22.
What you can do
- Batch Normalization (improvement in learning speed)
- Grad-inverter (given in arXiv: arXiv:1511.04143)
Measured star growth
- in 24h
- 0
- in 7 days
- 0
- in 15 days
- Collecting history
- in 1 month
- Collecting history
Net star changes over overlapping periods, not daily totals. Missing measurements are left blank. Stars measure attention, not software quality.
About
Continuous control with deep reinforcement learning - Deep Deterministic Policy Gradient (DDPG) algorithm implemented in OpenAI Gym environments
Machine LearningREADME.md
Originalddpg-aigym
Deep Deterministic Policy Gradient
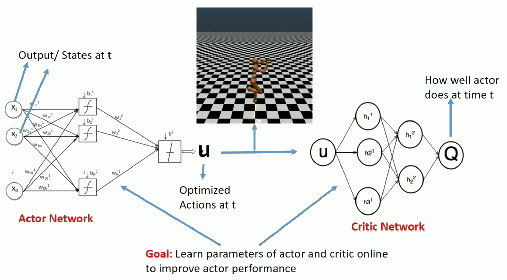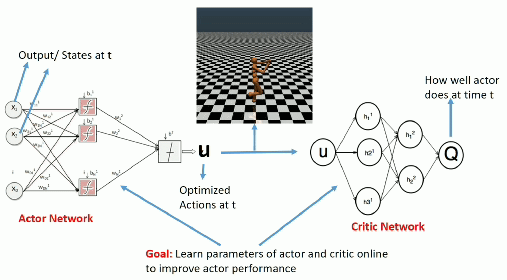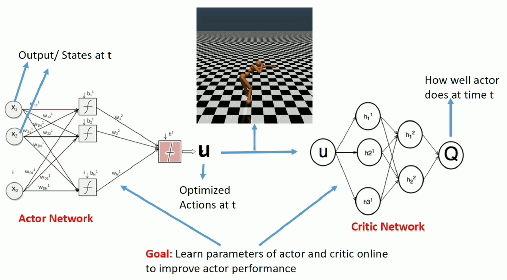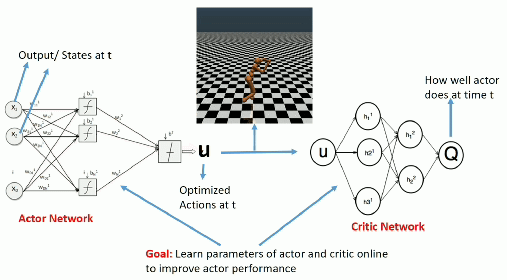
Implementation of Deep Deterministic Policy Gradiet Algorithm (Lillicrap et al.arXiv:1509.02971.) in Tensorflow
How to use
git clone https://github.com/stevenpjg/ddpg-aigym.git
cd ddpg-aigym
python main.py
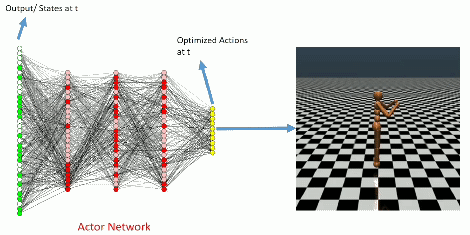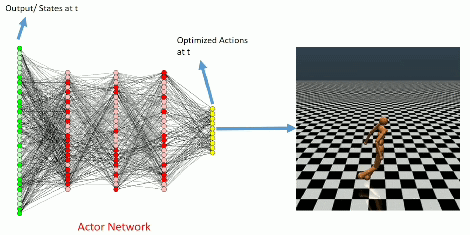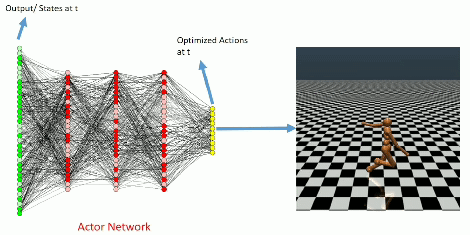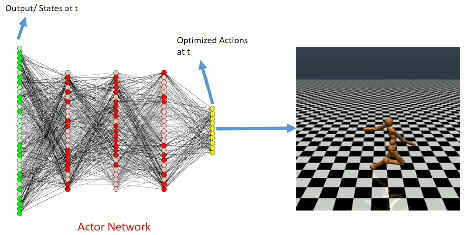
During training
Once trained
Learning Curve
The learning curve for InvertedPendulum-v1 environment.
Dependencies
- Tensorflow (Developed in tensorflow version 0.11.0rc0 [CPU version] [GPU version])
- OpenAi gym
- Mujoco
Features
- Batch Normalization (improvement in learning speed)
- Grad-inverter (given in arXiv: arXiv:1511.04143)
Note
To use different environment
experiment= 'InvertedPendulum-v1' #specify environments here
To use batch normalization
is_batch_norm = True #batch normalization switch
Let me know if there are any issues and clarifications regarding hyperparameter tuning.
Explore related projects
Loading…