
skydiscover-ai/jitengine
skydiscover-ai/jitengine has 44 GitHub stars and 1 forks. GitHot measured 0 stars in 24 hours. Last checked 2026-11-14 21:37 UTC. Last push 2026-11-04.
Measured star growth
- in 24h
- 0
- in 7 days
- Collecting history
- in 15 days
- Collecting history
- in 1 month
- Collecting history
Net star changes over overlapping periods, not daily totals. Missing measurements are left blank. Stars measure attention, not software quality.
About
LLM serving engines that SkyDiscover builds on the fly for specific AI models and hardware: Qwen3.6-35B-A3B, Qwen3.8-Flash-Next and Flint on Apple silicon Macs
AIREADME.md
Original
LLM serving, synthesized for your Mac



JITEngine is a collection of LLM serving engines that SkyDiscover builds on the fly for specific AI models and hardware (Apple silicon Macs in this case). The six engines featured here decode up to 2.72 times faster than the best alternative server tested on the exact same Mac.
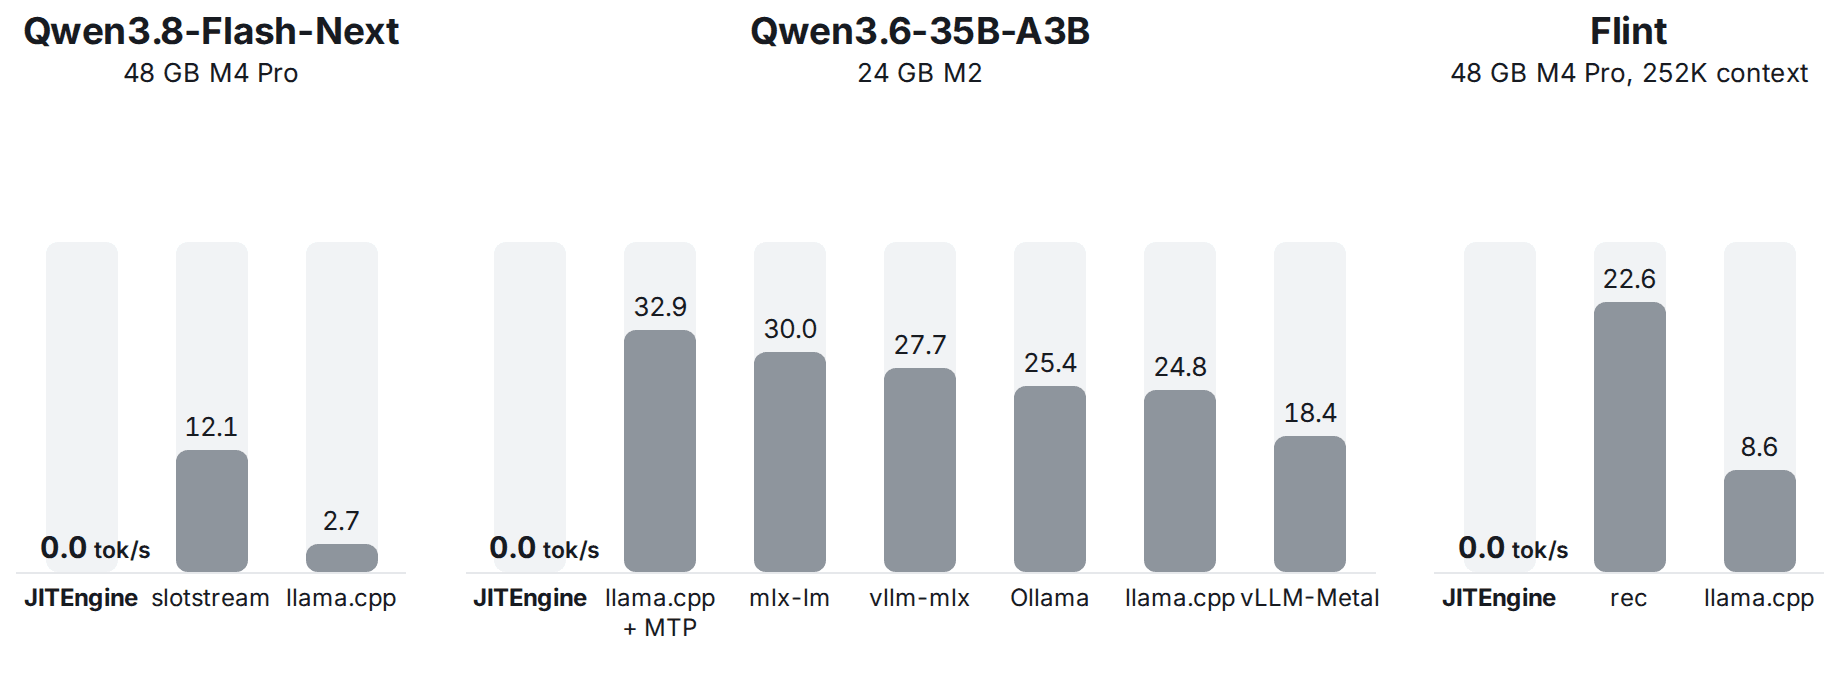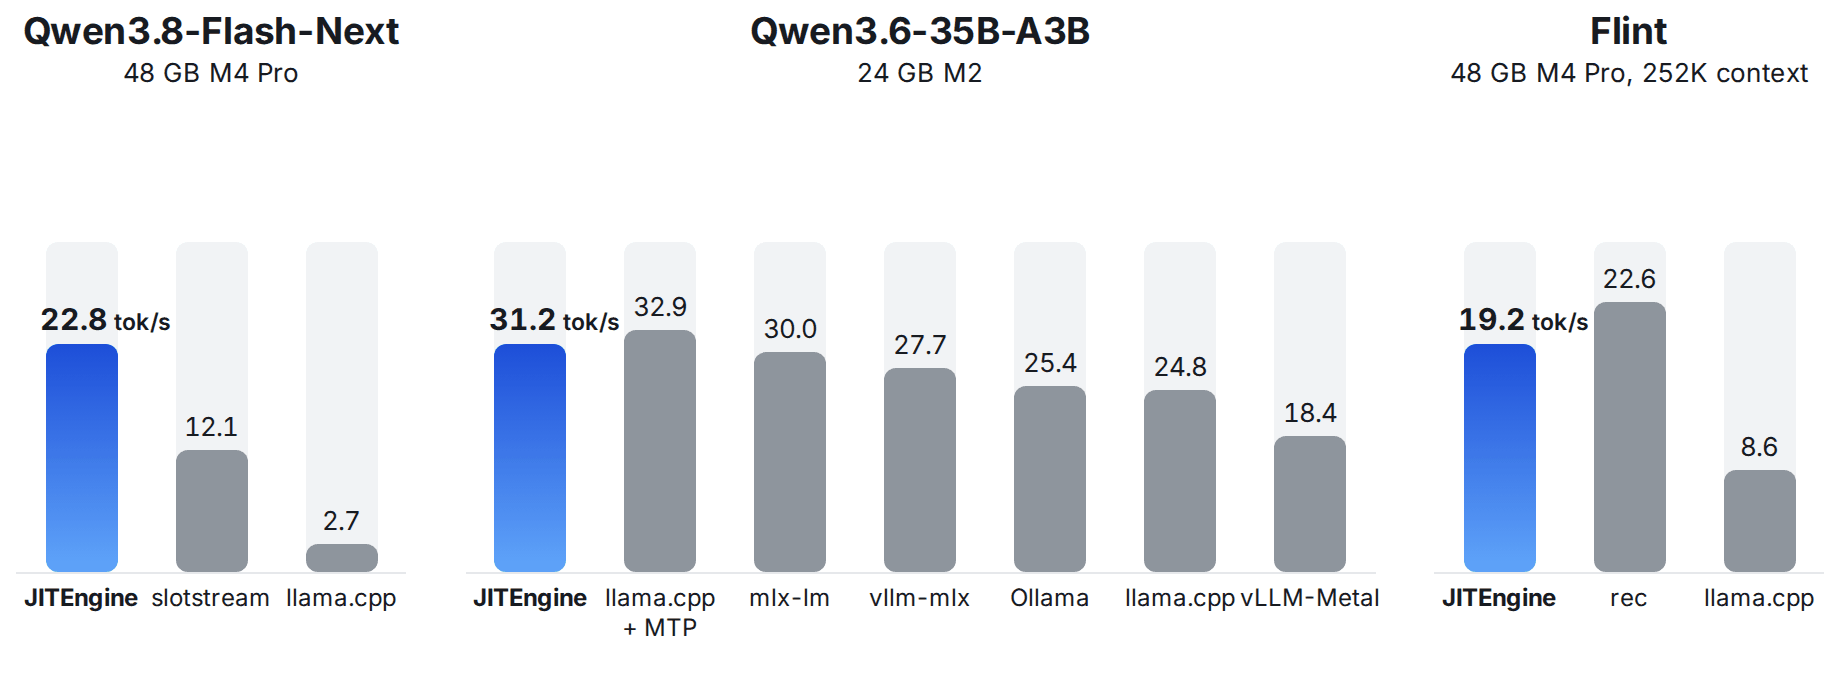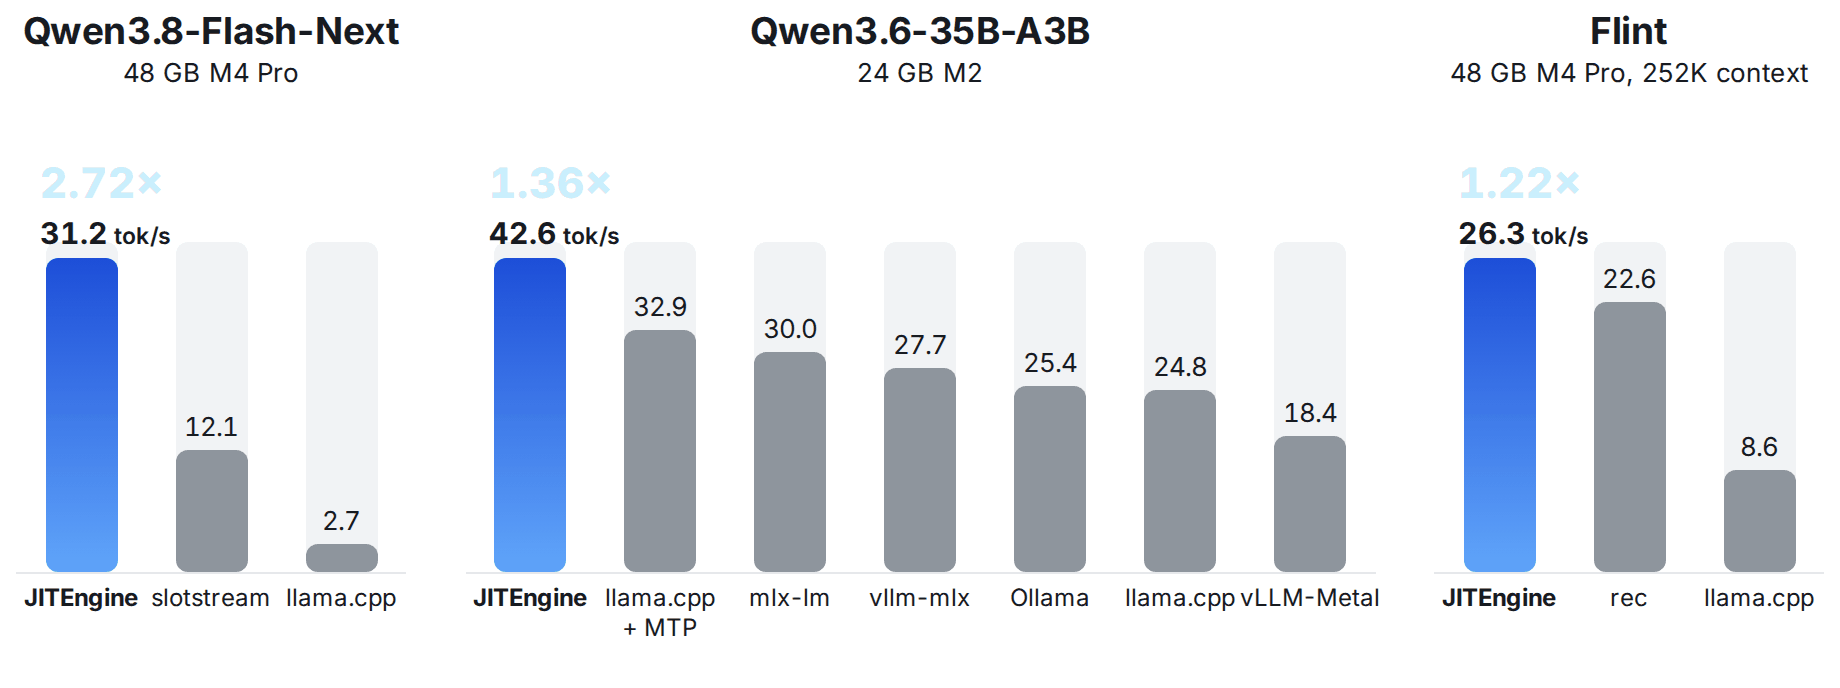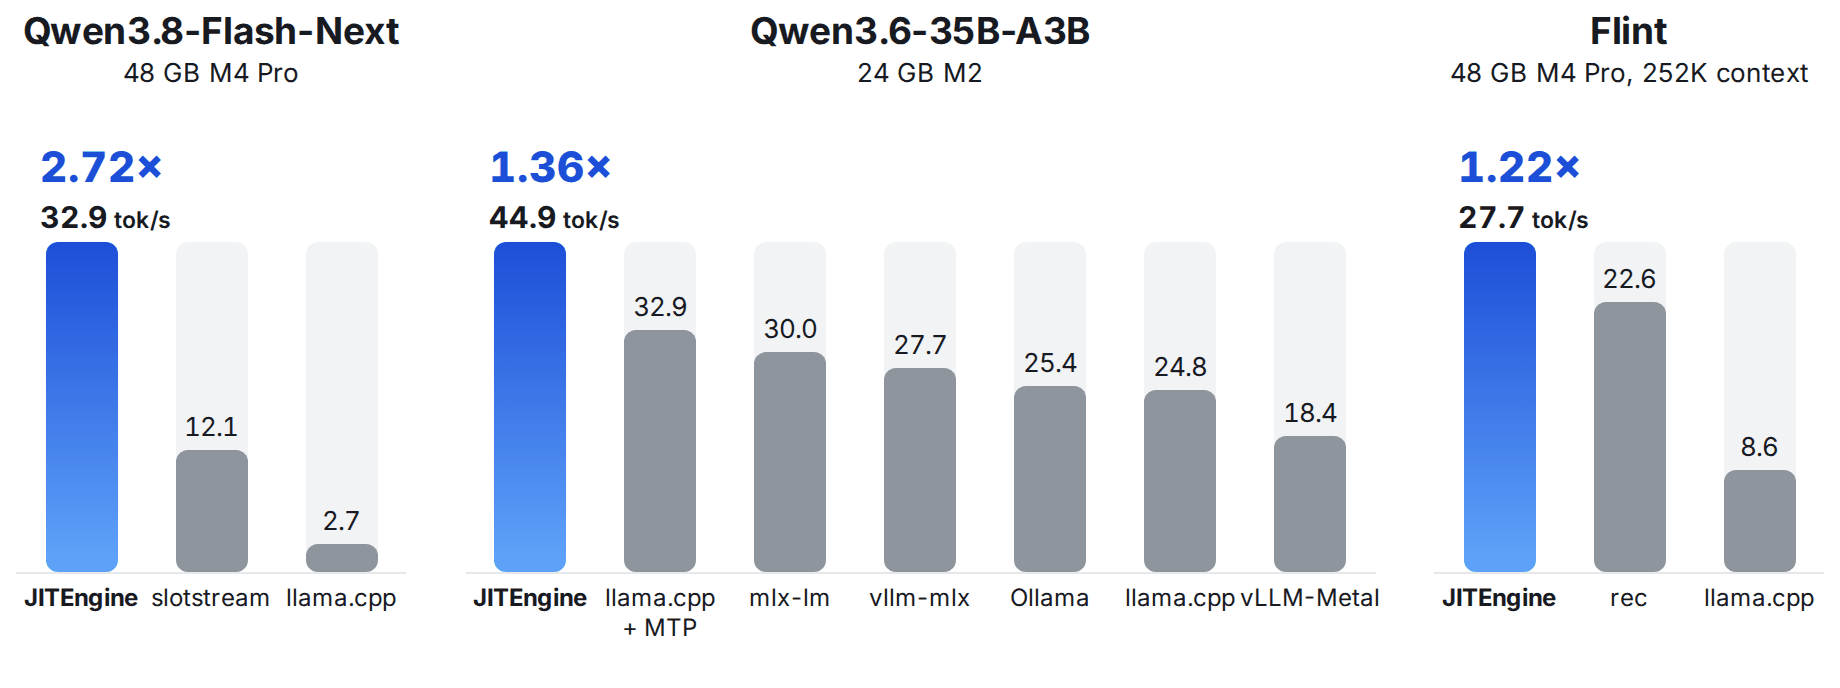
Decode speed for one user, against the other servers on the same Mac.
Quick start
Install the build for your Mac's chip and memory (the one that measured faster on our two Macs) with its model, then serve it, or run a coding agent on it:
curl -fsSL https://jitengine.ai/install.sh | bash -s -- flint    # or qwen3.6, flash-next
jitengine start      # serve it on port 8080, in the background
jitengine claude     # or run a coding agent on it: claude, codex, opencode or pi
The engine serves the OpenAI and Anthropic APIs:
curl http://127.0.0.1:8080/v1/chat/completions \
  --json '{"messages": [{"role": "user", "content": "Hello!"}]}'
jitengine.ai gives the commands for your Mac and model, with the speeds we measured on our two Macs.
More install details: disk, memory, sudo, and installing by hand
Flash-Next needs about 220 GB free on the internal SSD (290 GB for the M4 Pro build with its optional pack16 file)
and builds its expert packs once. jitengine status, logs, restart and stop manage the engine, and
jitengine serve runs it in the terminal instead.
If less memory is free than the engine's default budget, jitengine starts it with the largest budget that fits; the
engine then reads more experts from the SSD and runs slower, and in our tests the output stayed the same. Set
JITENGINE_BUDGET_GIB to choose the budget yourself. For Flint on a 24 to 36 GB Mac and Qwen3.6 on a 32 or 36 GB
Mac, jitengine asks for sudo to raise the GPU's wired memory limit until the Mac restarts.
Each engine's README has the steps to install it by hand, with Python 3.14.
Engines
| Engine | Mac | Key idea | Speedup |
|---|---|---|---|
| Qwen3.6‑35B‑A3B 3‑bit | 24 GB M2 | Its own exact 3-bit GPU kernels | 1.36× vs llama.cpp + MTP |
| Qwen3.6‑35B‑A3B 4‑bit | 48 GB M4 Pro | Speculative decoding, exact by default | 1.10× vs oMLX, 8 agents |
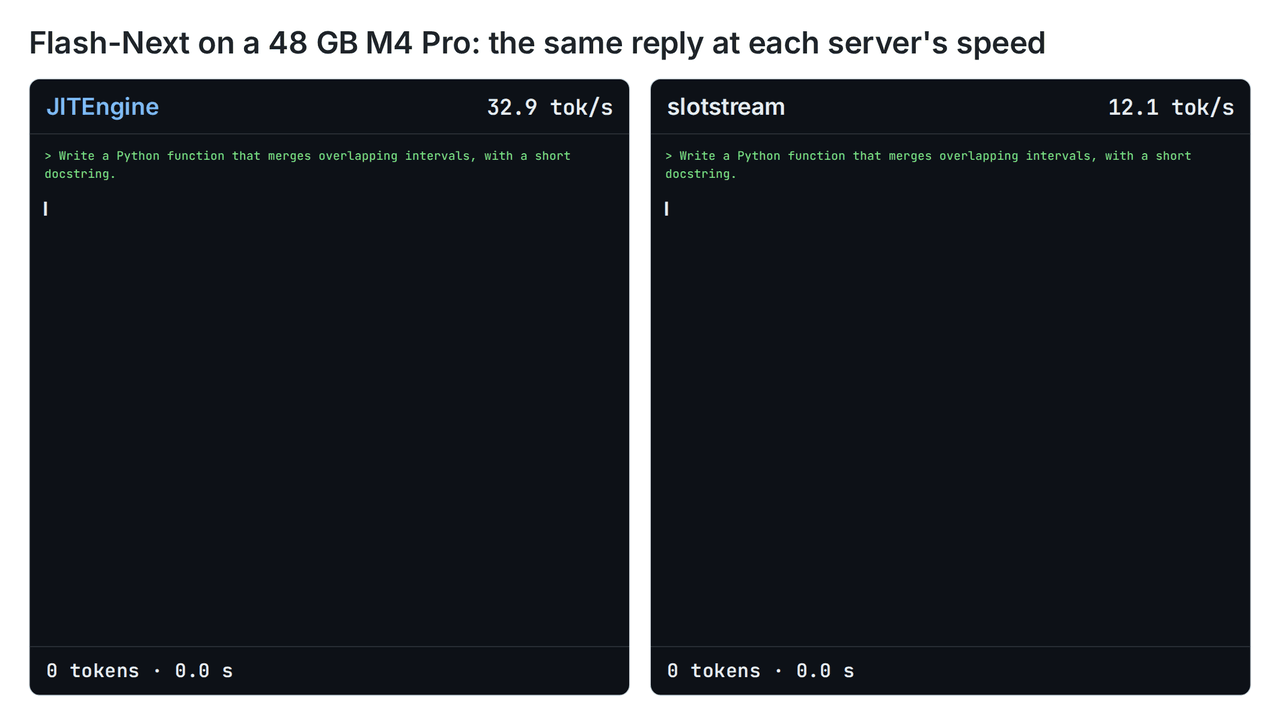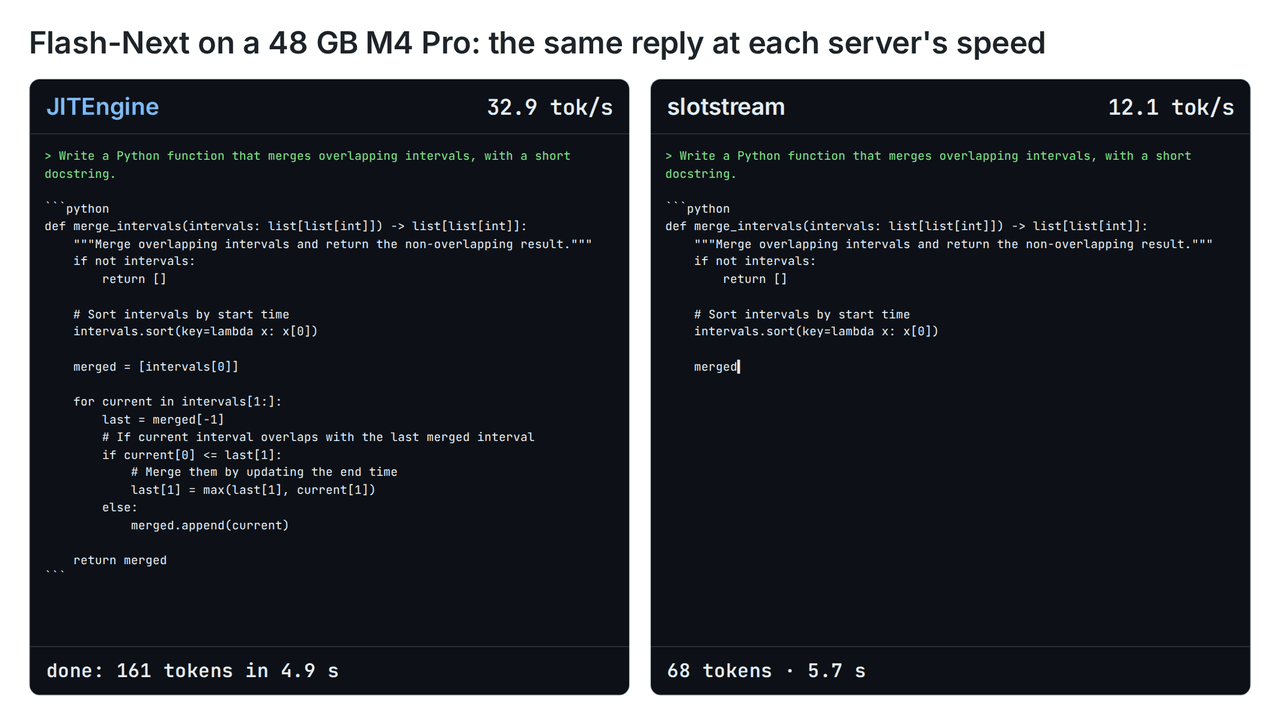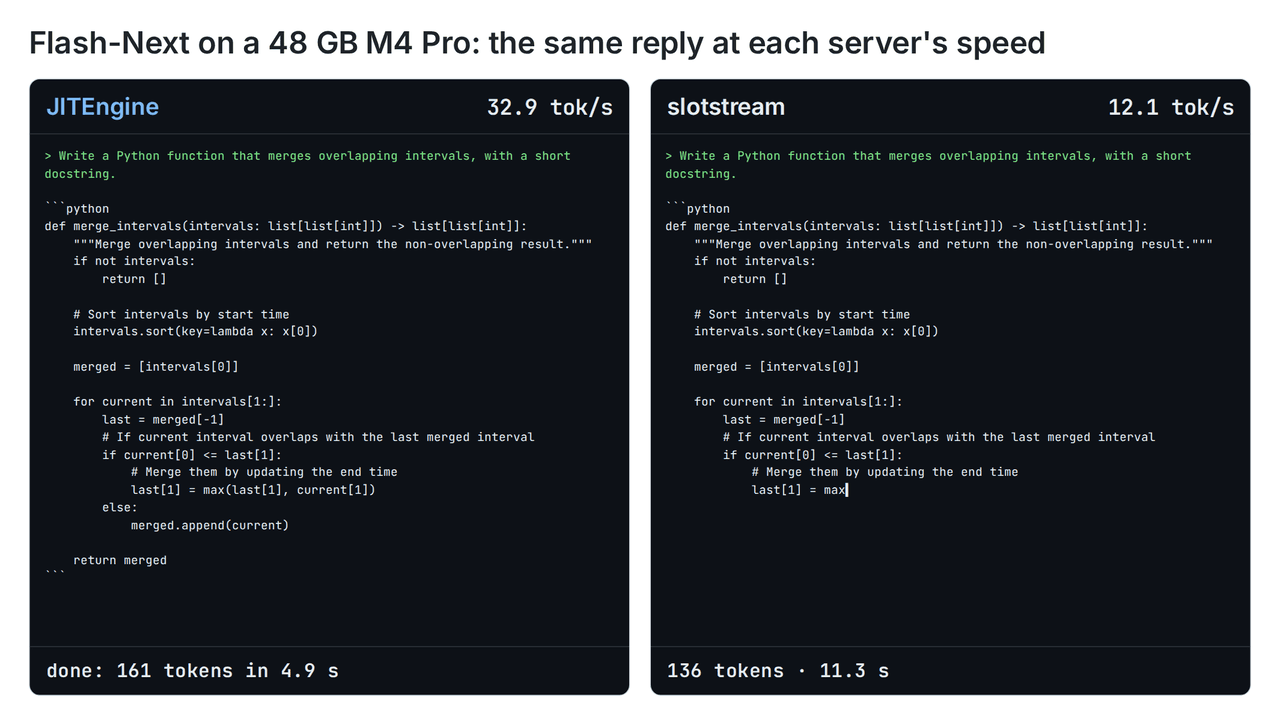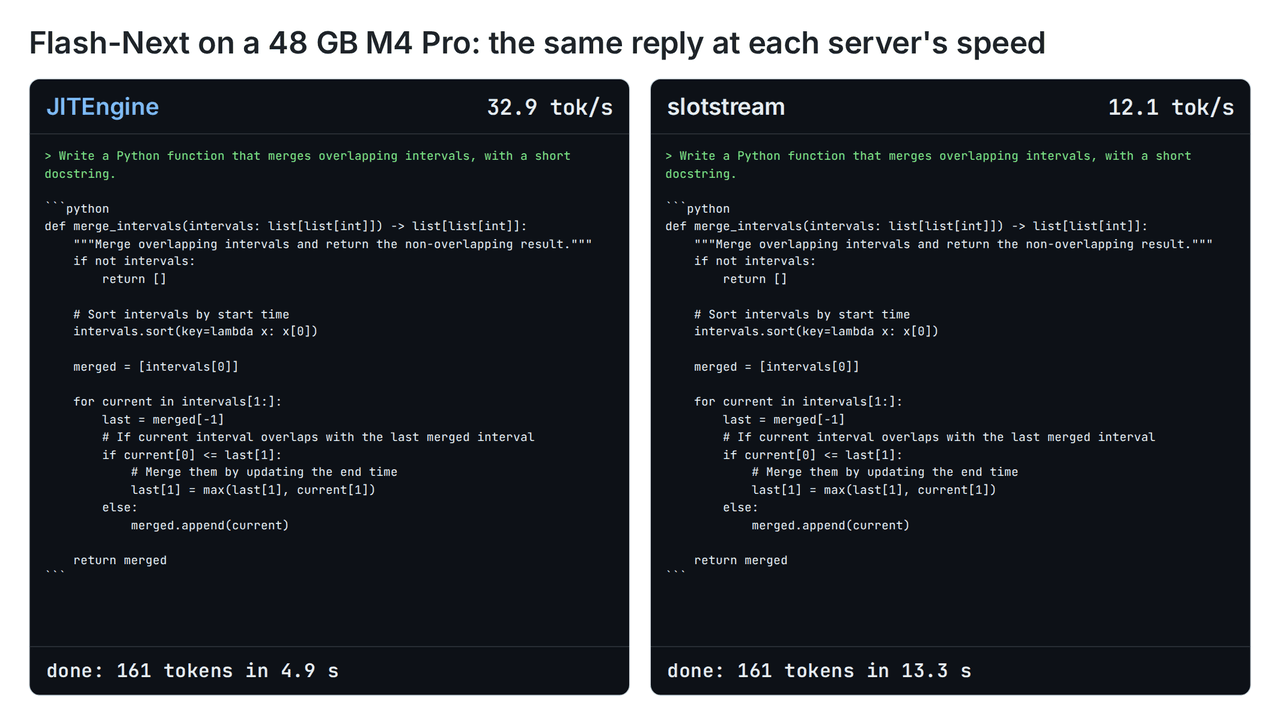
| Qwen3.8‑Flash‑Next | 48 GB M4 Pro | Hot experts in memory, lossless MTP | 2.72× vs slotstream |
| Qwen3.8‑Flash‑Next | 24 GB M2 | Evicts the experts needed last | 1.62× vs slotstream |
| Flint int4 | 48 GB M4 Pro | One KV read for all heads | 1.22× vs rec, 252K context |
| Flint int4 | 24 GB M2 | SSD streaming, GPU clock held high | 2.1× vs llama.cpp, raw decode at 1K |
Speedups are for one user unless the row says otherwise. We ran both builds of each model on both Macs;
engines/ says how the two builds differ and which one install.sh picks for each chip and memory size.
Use it with a coding agent
jitengine claude      # Claude Code
jitengine codex       # Codex
jitengine opencode    # OpenCode
jitengine pi          # Pi
Each command starts the engine if it is not running, then the agent on the local model for that session only; nothing is written to the agent's config. Install the agent itself first: Claude Code, Codex, OpenCode or Pi.
For another agent, set http://127.0.0.1:8080/v1 as its OpenAI base URL or http://127.0.0.1:8080 as its Anthropic
one; both APIs serve tool calls. launch/ has each agent's setup by hand, jit-launch for an engine
installed without the one-liner, and the serve flags agents need, such as Qwen3.6's --max-context 32768.
How they were built
In SkyDiscover, coding agents edit the engine, run tests, and benchmark each build against the current best in the same session. SkyDiscover keeps a build only when it passes every check and wins that head-to-head benchmark by a clear margin. In the Flash-Next run on the M4 Pro, every kept build produced output bit-identical to the first. In some runs, a separate auditor agent hunted for benchmark cheats; it found none, and turned the coverage gaps it uncovered into new tests. Flash-Next on the M4 Pro shows one run build by build, and each engine's README explains what made it fast.
Citation
@misc{cemri2026jitengine,
  author = {Mert Cemri and Shubham Agarwal and Shu Liu and Alexander Krentsel and
            Sidharth Sankhe and Alexandros G. Dimakis and Ion Stoica},
  title  = {Your Mac Deserves Its Own LLM Engine},
  year   = {2026},
  month  = nov,
  url    = {https://skydiscover-ai.github.io/blog-jitengine.html}
}
Developed at the UC Berkeley Sky Computing Lab. Apache 2.0.