
sk8erboi17/DStudio
sk8erboi17/DStudio has 36 GitHub stars and 3 forks. GitHot measured 0 stars in 24 hours. Last checked 2026-11-10 02:03 UTC. Last push 2026-11-03.
Fully local: chat, a coding agent, and a design studio in one private desktop app.
What you can do
- Run DeepSeek V4/V4.1, GLM 5.3 Flash, Laguna S 2.1 and Qwen locally through one native interface and model picker; DStudio selects ds4, llama.cpp or MLX for you.
- Use a private AI chat with reasoning display, prefix-cache reuse, citations from optional Web Search and local history.
- Use Learn to build an interactive learning path from a goal, PDFs and links, and open a dedicated Tutor for any block.
- Run Web Search or Deep Research through DStudio's local browser helper, with read-page evidence and source cards.
Measured star growth
- in 24h
- 0
- in 7 days
- Collecting history
- in 15 days
- Collecting history
- in 1 month
- Collecting history
Net star changes over overlapping periods, not daily totals. Missing measurements are left blank. Stars measure attention, not software quality.
README.md
Original
DStudio: Local AI Studio
Run open-weight models such as DeepSeek V4, GLM 5.3, Laguna and Qwen on your own Mac and put them to work on your files: chat, a coding agent, document work, web research, learning paths, design, images and video, in one native app. Where it can, DStudio checks the model's work against tool results and sources instead of taking its word. No cloud account required.




Status: work in progress, tested on one Apple M2 Max (96 GB). There is no downloadable build: build from source to use it. What works today and what does not.
DStudio is one desktop application for local AI. It runs large open-weight models on your own machine behind a single interface: private Chat, Learn paths with a Tutor, a coding Agent (with Plan, GSA and RSA workflows), document-focused Cowork, a Design studio, local image understanding/generation/editing and optional MiniMax H3 video. Model execution, project files and generated artifacts stay under your control.
Who it is for. People with a high-memory Apple Silicon Mac who want capable AI on their own code and documents without uploading them: developers, researchers, students and anyone working with files they would rather keep local. If no model fits your machine, a DeepSeek API key or another OpenAI-compatible endpoint can provide inference while every tool keeps running locally. DStudio is early: Linux and Windows builds are prepared but untested, and most models are integrated without being fully qualified.
Contents
- What DStudio can do · Why DStudio · Can my Mac run it?
- Current status: what works today and what does not
- Install
- Modes: Chat, Learn, Search, Agent, Cowork, Design
- Supported models and limitations
- Harnesses: every engine with every agent loop
- Measured results
- Requirements
- Development and tests
- Network access · How it works · Security
- Contributing
- WIP checklist
- Project layout
What DStudio can do
- Run DeepSeek V4/V4.1, GLM 5.3 Flash, Laguna S 2.1 and Qwen locally through one native interface and model picker; DStudio selects ds4, llama.cpp or MLX for you.
- Use a private AI chat with reasoning display, prefix-cache reuse, citations from optional Web Search and local history.
- Use Learn to build an interactive learning path from a goal, PDFs and links, and open a dedicated Tutor for any block.
- Run Web Search or Deep Research through DStudio's local browser helper, with read-page evidence and source cards.
- Check PDF sources: open the cited page with the quoted words highlighted and recheck simple calculations.
- Send image pixels directly to DeepSeek V4 Flash Vision-Exp, GLM 5.3 native vision or Qwen3.8-27B; generate images with Ideogram 4 FP8, edit them with HunyuanImage 3 NF4, and create video with the optional MiniMax H3 pipeline.
- Use a local coding agent that reads, edits and verifies files in a folder you choose, with an Open IDE view, Open Blueprint code maps and automatic Task Graph checks; or run pi or OpenCode as the agent loop.
- Use Cowork for source-grounded spreadsheet, PDF, document and presentation work with native Office tools and no arbitrary shell.
- Toggle Plan for a Markdown execution plan, keep working towards a saved /goal, and add context while a turn runs.
- Create Skills: private instruction packs for Agent, Cowork and Design.
- Run Guided Security Analysis (GSA) for authorized reviews or Reverse Structure Analysis (RSA) for public websites.
- Generate and refine complete interfaces in Design, with 25 offline design systems, measured layout checks and export.
- Use an optional DeepSeek API or remote endpoint for inference while all tools keep running locally, and reach the UI from another device on your LAN.
Why DStudio
- Your files stay on your machine. Models run locally by default; the app has no telemetry and listens only on localhost unless you enable LAN access. Model downloads, web research, harness dependencies and the optional remote API are separate, documented outbound paths, used only when you ask for them. Network · Security
- It checks instead of trusting. An Agent action on your workspace counts as done only after a real tool result and a completion receipt. A PDF citation opens the original page with the quoted words highlighted. Comparison-table cells keep their source excerpt, Blueprint diagrams cite file lines that DStudio checks against the bytes, and Design renders each page at three widths before accepting it. These checks prove that the evidence exists, not that the model's interpretation is right.
- Not only a chat box. Work happens in views made for it: an IDE that shows the agent's edits while it writes them, a canvas for Design, an editable roadmap for Learn, real Office files and source-backed tables in Cowork, and a task graph you can pause, resume and reopen.
- One app for several engines and agents. Choose a model and DStudio picks and starts its engine (ds4, llama.cpp or MLX); there is no engine to configure. The engine sources ship in this repository and build or install offline. Agent mode can also run pi or OpenCode on the same model and folder.
- Results keep their failures. On 50 diverse workspace tasks, DStudio's checked Agent, pi and OpenCode each completed 50/50, against 42/50 for the same agent without checks. Search and Deep Research answers met the checked requirements on 4/4 questions instead of 2/4, but took longer; Design shows no overall win yet. These are small samples on one Mac, not rankings, and failed runs stay in the published charts. All results
Can my Mac run it?
The memory a model needs follows from its engine: llama.cpp and MLX keep the whole model in memory, so pick a file comfortably smaller than your RAM, with room left for context and macOS. Only a 96 GB M2 Max has been tested.
| Starting point | Engine | Download | Memory | Status on the 96 GB test Mac |
|---|---|---|---|---|
| Qwen3.8-27B Q6_K_XL + projector | llama.cpp | 26.2 GB | Whole model in memory | Real workflow checks 6/6 on the previous llama.cpp pin, not yet rerun on b11836; Design is slow |
| Qwen3.6-35B-A3B Q6_K_XL | llama.cpp | 31.8 GB | Whole model in memory | Real workflow checks 6/6 |
| Qwen3.6-35B-A3B MXFP8 (macOS 26) | MLX | 36.7 GB | Whole model in memory | Real workflow checks 6/6 |
| Laguna S 2.1 Q4_K_M | ds4 | ~68 GB | Must fit entirely (no SSD streaming) | Experimental; engine acceptance 10/12 (September) |
| DeepSeek V4 Flash Q2 | ds4 | ~87 GB | ~96–128 GB RAM | Engine acceptance 11/12 (September); most agent benchmarks ran on it |
| GLM 5.3 Flash Q2 | ds4 | ~96.5 GB | Runs only with SSD streaming on 96 GB | Qualification blocked on this Mac |
Smaller Qwen quantizations (from 7.1 GB for the 27B and 10.0 GB for Qwen3.6) can be downloaded but have not been individually verified. Qwen3.8-Flash-Next (147–177 GB), DeepSeek V4.1 Flash and DeepSeek V4 Pro (~430 GB, ~512 GB RAM) are experimental or not validated on the test Mac. Details and limits: Supported models · Requirements.
Current status (October 3, 2026)
This is an in-progress source tree, not a qualified release. There is no downloadable build; to use it today, build from source.
Recent changes
- ds4 main moved to
890898c(November 3). The bundled main engine follows upstream's November 2 revision; DStudio's patches were rebased and the native runtimes rebuilt on it (no real-model runs yet). An installedds4/at0aaea5amust be reinstalled; move it aside rather than deleting it, because itsgguf/folder holds your models. Steps. - Breaking for existing source installs (October 27). Older installations are not upgraded: reinstall the bundled engines and restart unfinished Qwen downloads. Details.
- Qwen moved to bundled engines. Qwen3.6-35B-A3B and Qwen3.8-27B run on
llama.cpp
b11836; Qwen3.6 also runs on MLX on Apple Silicon. The former Qwen side engines (vagrillo/ds4 and Ninnix/q36) are retired. Qwen3.8-Flash-Next runs on ds4 main. - Every mode on every engine. Chat, Agent, Cowork and Design work on ds4, llama.cpp and MLX models alike. Design talks to the llama.cpp/MLX models with structured tool calls, and files being written stream live in every mode and harness.
- pi and OpenCode inside DStudio. Settings → Harnesses lets Agent mode run pi or OpenCode instead of DStudio's agent, with the same model, workspace and transcript. DeepSeek works with both (pi through pi-ds4).
- One owner for local servers. DStudio starts
llama-serverand the MLX server itself, marks them ready only when they report exactly the model you chose, and stops them on Stop, model switch, quit or crash. - Linux and Windows prepared for llama.cpp the way Ollama builds it (CPU variants plus CUDA, ROCm or Vulkan when installed). Compiled, not run on those systems yet.
- Sessions survive restarts on llama.cpp/MLX. Agent, Cowork and Design save their transcript after every turn and restore it after a restart; the server reads it again (no KV snapshot).
- Scanned PDFs are read with local OCR on macOS (Apple Vision, offline), labelled as OCR everywhere, with OCR line highlights for citations.
- Cowork: exact text copies (a lost final newline made copies fail), comparison tables up to 5,000 rows, 128 columns and 512 files, and Cowork from a phone or tablet through an explicitly shared, paired session.
- LAN hardening: web tools refuse the host's loopback addresses for LAN
devices, unknown
Hostnames are refused (DNS rebinding), CORS is limited to DStudio pages on private addresses, and LAN chat mirrors are bounded. - Earlier in this cycle: Open IDE and Open Blueprint for Agent, live Design building in the IDE, 25 offline Design systems, automatic Task Graph checks, goals and mid-turn context, PDF source checking and faster PDF reading.
Checked with real weights on an Apple M2 Max (96 GB)
| What ran | Result |
|---|---|
| DStudio's own modes on Qwen3.6 (llama.cpp): Agent, recall, Cowork, Design, Chat with thinking on/off, no leftover server after a killed host | 6/6 |
| The same six checks on Qwen3.8-27B (llama.cpp) | 6/6 (Design took 37 minutes with thinking on) |
| The same six checks on Qwen3.6 (MLX) | 6/6 |
| pi and OpenCode × {Qwen3.6 llama.cpp, Qwen3.6 MLX, Qwen3.8-27B, DeepSeek V4 Flash}, three independently checked tasks each | 24/24 |
| Cowork on DeepSeek V4 Flash Vision-Exp IQ2XXS (native, 393,216-token context, Max thinking): stop after a tool result and resume; restart and restore the saved session | 2/2 |
| The same Cowork model, long profile (October 4; interrupted on request): 11 of 16 cases run | 10/11; 1 failure, 5 not run |
make check-fast (model-free gate) and the macOS bundle smoke test |
pass |
Failed runs that led to fixes are kept, not replaced: see docs/HARNESSES.md and tests/README.md. These are focused development checks, not a quality score or a ranking.
Not done yet
- The Cowork long profile is incomplete.
ambiguous-editfailed: the model found no duplicates, then reasoned in a loop for over 25,000 tokens without asking which file was meant, until the test's one-hour limit. A second sample was stopped on request.path-escape,long-seed,long-followup,long-revisionandlong-deckhave not run. - KV snapshots for the llama.cpp/MLX models. Agent, Cowork and Design sessions on these models are now restored after a restart from their saved transcript, but the server then reads the whole conversation again (a fresh prefill). pi/OpenCode sessions on these models are not restored.
- The 100-task quality corpus has not been rerun on llama.cpp/MLX; the published Qwen scores were measured on the retired engines.
- Linux, Windows, CUDA, ROCm and Vulkan have not been run. pi and OpenCode are not available on Windows.
- pi/OpenCode were not run with GLM, Laguna, Qwen3.8-Flash-Next, DeepSeek V4.1 or a cloud endpoint, nor with Plan, GSA or RSA.
- Twelve proposed modules and improvements (Agent harness guards, KV slots for llama.cpp, a reasoning-budget pause, constrained JSON and more); none is started. See the list.
- Learn/Tutor, PDF/vision, long tasks, the native desktop matrix, generated Design projects and final release admission. See the WIP checklist, remaining work and PLAN.MD.
Install
DStudio is installed from source; there is no downloadable build. On macOS the
build produces DStudio.app (double-click to open); on Windows a portable
folder. The UI is a single vanilla index.html embedded in a small C launcher:
no Electron, no framework build, no CDN and no telemetry. Network access is
explicit: model and harness-dependency downloads, Web Search/Research and the
optional DeepSeek API backend are the documented outbound paths, used only when
you request or configure them.
Build from source
make
open DStudio.app        # macOS
# or: ./dstudio         # Linux / headless
make windows produces the portable Windows x64 folder; run DStudio.exe.
First launch
The first-run screen installs the pinned ds4 engine into
~/Library/Application Support/DStudio (copied from the bundled sources and
compiled locally), then offers the supported models with their real download
sizes. A local system check covers the engine, selected model, Chat and
Agent/Cowork/Design runtimes, Cowork's Office helper, Web Search and network
state; each missing piece has a direct Choose, Download, Install,
Start or Settings action. Engines, models, harnesses and optional tools
stay outside the signed app, so updating or moving DStudio.app does not
delete them.
llama.cpp is built the first time you start a Qwen3.6 or 27B GGUF (about a minute and a half on an M-series Mac; CMake required). MLX is installed the first time you start or download the MLX model (about 15 seconds; macOS 26 and Python 3.12–3.14 required). Both happen offline, in the background.
DStudio offers only the publishers' official weights. Abliterated, “uncensored” or otherwise safety-modified derivatives cannot be downloaded from the app and are not selectable even if such a file is already in the model folder; DStudio leaves that file untouched.
Modes
A sidebar switches between Chat, Agent, Cowork, Design and Learn. Plan, GSA and RSA are Agent workflows; Tutor rooms live inside Learn; image and video generation are routed from Chat and Design. Every mode has reopenable local history. Restorable on-disk engine sessions depend on the engine: ds4 models have them, the llama.cpp and MLX Qwen models do not yet.
Chat
Streaming chat backed by the selected local model: context lives in the engine's cache (prefix reuse is shown as cached tokens) and every message is saved locally. You get live tokens/s, collapsible reasoning, native MathML for LaTeX, syntax-highlighted code, file artifacts, image/PDF attachments and optional Web Search sources. A configured DeepSeek API key or remote endpoint can replace local inference without moving DStudio's workspace tools into the cloud.
The composer model picker has search, quantization/size details and the current model highlighted. Choose a model and DStudio selects its engine automatically. Download progress stays in Settings → Models.
With DeepSeek Vision-Exp or GLM 5.3 and the matching encoder installed, image
attachments stay multimodal: DStudio sends PNG/JPEG pixels to the engine; Agent
and Cowork use ds4's view_image, and Design uses its native see_image.
Qwen3.8-27B reads images through its own projector on llama.cpp. There is no
text-description detour or secondary visual model. Text-only models (older
DeepSeek checkpoints, Laguna, Qwen3.6) expose no image tools and read only PDF
text layers.
Check PDF sources
For newly read PDF attachments in local Chat, DStudio adds a source-checking workflow inspired by NanoIndex:
- See where a quotation comes from. Click a PDF citation in the answer to open the original physical page, with the exact words highlighted. Zoom in for small text or tables.
- Handle repeated references. If the model uses
[P1]for several passages, the modal lets you choose the intended passage instead of guessing. Identical entries are merged. Internal evidence JSON is hidden, including malformed output; unreadable source details show an explanation, not a verification badge. Saved replies are reparsed too. - Know when a source cannot be located. Missing or repeated quotations are reported without selecting a misleading highlight. On a scanned page, a quotation is searched in the page's local OCR reading: whole recognized lines are highlighted and labelled as OCR, and they never count as an exact passage for calculations.
- Move around the document. The attachment preview offers recognized numbered chapter/section headings, nested section hints and explicit “see section…” links. These are text-based hints, not a complete outline or a semantic knowledge graph.
- Check the arithmetic. “Check passages and calculations” first locates the cited passages, then recalculates supported sums, differences, products, ratios and percentages using the quoted numbers. It shows the operands, sources, rounding and any difference from the answer. It does not verify units, whether the right numbers were chosen, or the answer’s interpretation.
No extra model or cloud OCR service is added. Citations and calculations appear
when the answering model supplies the structured source information;
unsupported or malformed output is not silently marked as verified. Original
PDFs are kept in a local cache limited to 32 documents / 2 GiB; source
identity is checked against the PDF bytes, and an evicted or changed original
must be attached again. This is host-local on macOS/Linux (not exposed to
LAN clients) and needs Poppler and shasum or sha256sum.
make test-pdf-evidence exercises real Poppler extraction/rendering, citation
matching, identity, calculations and the browser viewer with no model
loaded; it is an implementation test, not a model-quality benchmark.
Multimodal PDFs
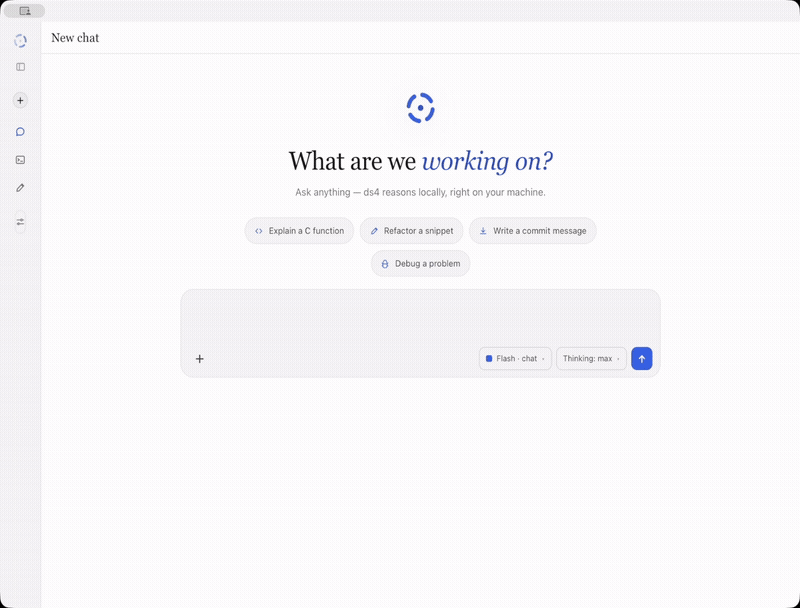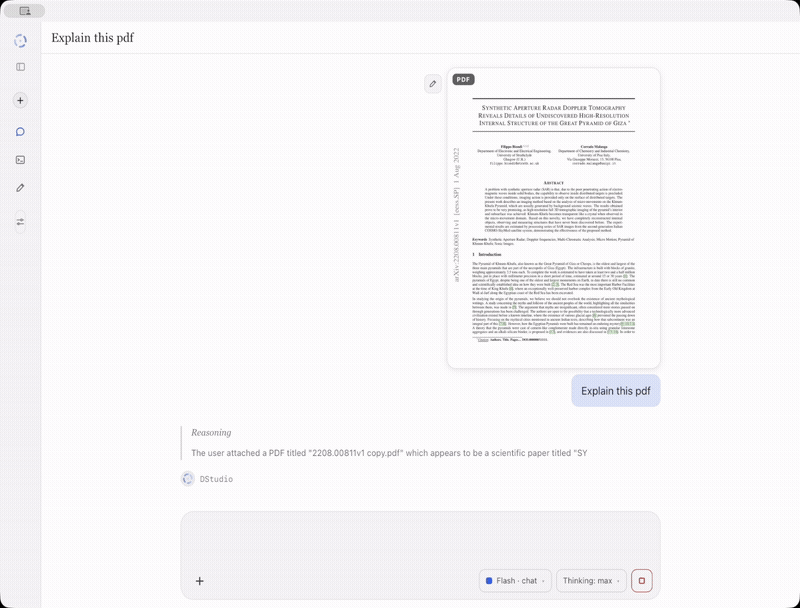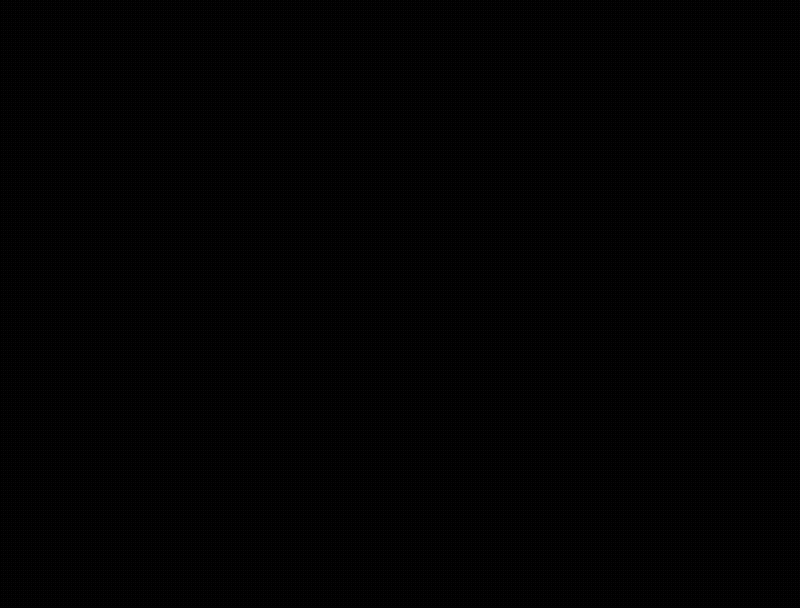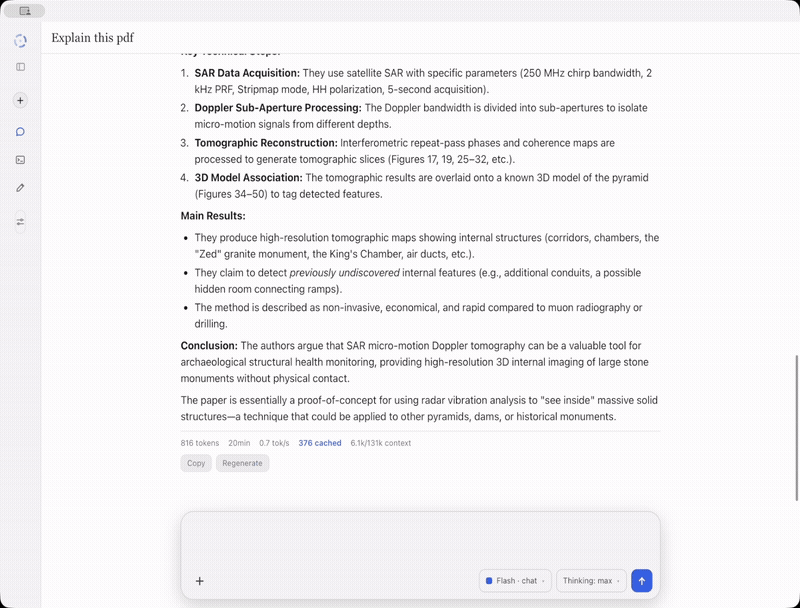
Attach a PDF and ask in any language. When all its text fits, DStudio reads it directly: no extra model turn to choose pages and no embedding index to build. All physical pages, extracted text, numbers and citation links are kept. This applies to Chat, Learn attachments and Cowork.
Long PDFs, scans and uncertain text layers use the planner: the active model decides whether to build a bounded overview, read exact physical pages or search semantically. DStudio extracts text locally and uses the small pinned Qwen3-Embedding-0.6B only as a text embedding index, never as a visual router. With DeepSeek Vision-Exp or GLM 5.3 active, up to four selected pages are rendered and sent to that model's native encoder. Text-only models receive the extracted text and report any image-only pages they could not read.
Scanned pages. On macOS, pages without a text layer are read with local
OCR: the page is rendered on the Mac and recognized with Apple's Vision
framework, offline. These pages are labelled OCR wherever their text appears,
because recognition can misread characters: on a generated test scan it read
"Applied" as "AppLiea" while reporting full confidence. One read recognizes at
most 64 new pages (about 1 second each on an M2 Max); recognized pages are
cached, and the reply says which page range to ask for next. Linux and Windows
builds have no OCR yet and keep reporting scanned pages as unread.
make test-pdf-ocr runs the real reader and Vision on generated scans, with no
model.
make test-pdf-complete checks complete text against Poppler byte for byte,
fallbacks, real citation highlights and upload-to-Chat behavior with a
simulated answering model: it proves extraction and routing, not answer
accuracy or a speed multiplier. See PDF reading.
Learn — interactive learning paths
Describe what you want to learn and optionally attach PDFs, notes or public links. Every Learn path starts with mandatory Deep Research, even when the prompt contains no link. Discovery tries Google first in DStudio's Chrome session and falls back to Brave, Bing and DuckDuckGo when a search page blocks it; every search page and selected source is opened through Chrome (CDP), and dynamic pages are scrolled until their content stabilizes before extraction. DStudio looks for authoritative curricula, current documentation, prerequisite evidence, practical exercises, assessment criteria and common pitfalls; your links and PDFs are included as evidence but never treated as the whole plan. Only after at least five substantial pages from four independent hosts and fifteen grounded curriculum facts does a semantic judge decide whether the knowledge gaps are closed; failed browser reads do not count as progress.
The generated path records cross-topic prerequisites, key concepts, effort estimates, observable outcomes, practice, mastery checks, stage objectives, checkpoints and a final project. There is no preset topic catalogue or fixed quota: a broad field becomes several stages or branches, a narrow skill stays compact. A structural gate rejects shallow or truncated drafts; a separate adversarial factual audit checks every stage and then the whole path, and only a factually clean draft reaches the independent curriculum judge (coverage, sequencing, granularity, practice, assessment, sources, capstone). Repairs are audited again until both pass or you press Stop. The result opens as an editable graph inspired by roadmap.sh: complete, reorder or delete blocks, or add one and let the model write a coherent outcome and exercise for it. The graph is saved with its history and exports as PNG, PDF or JSON.
Study with a dedicated Tutor
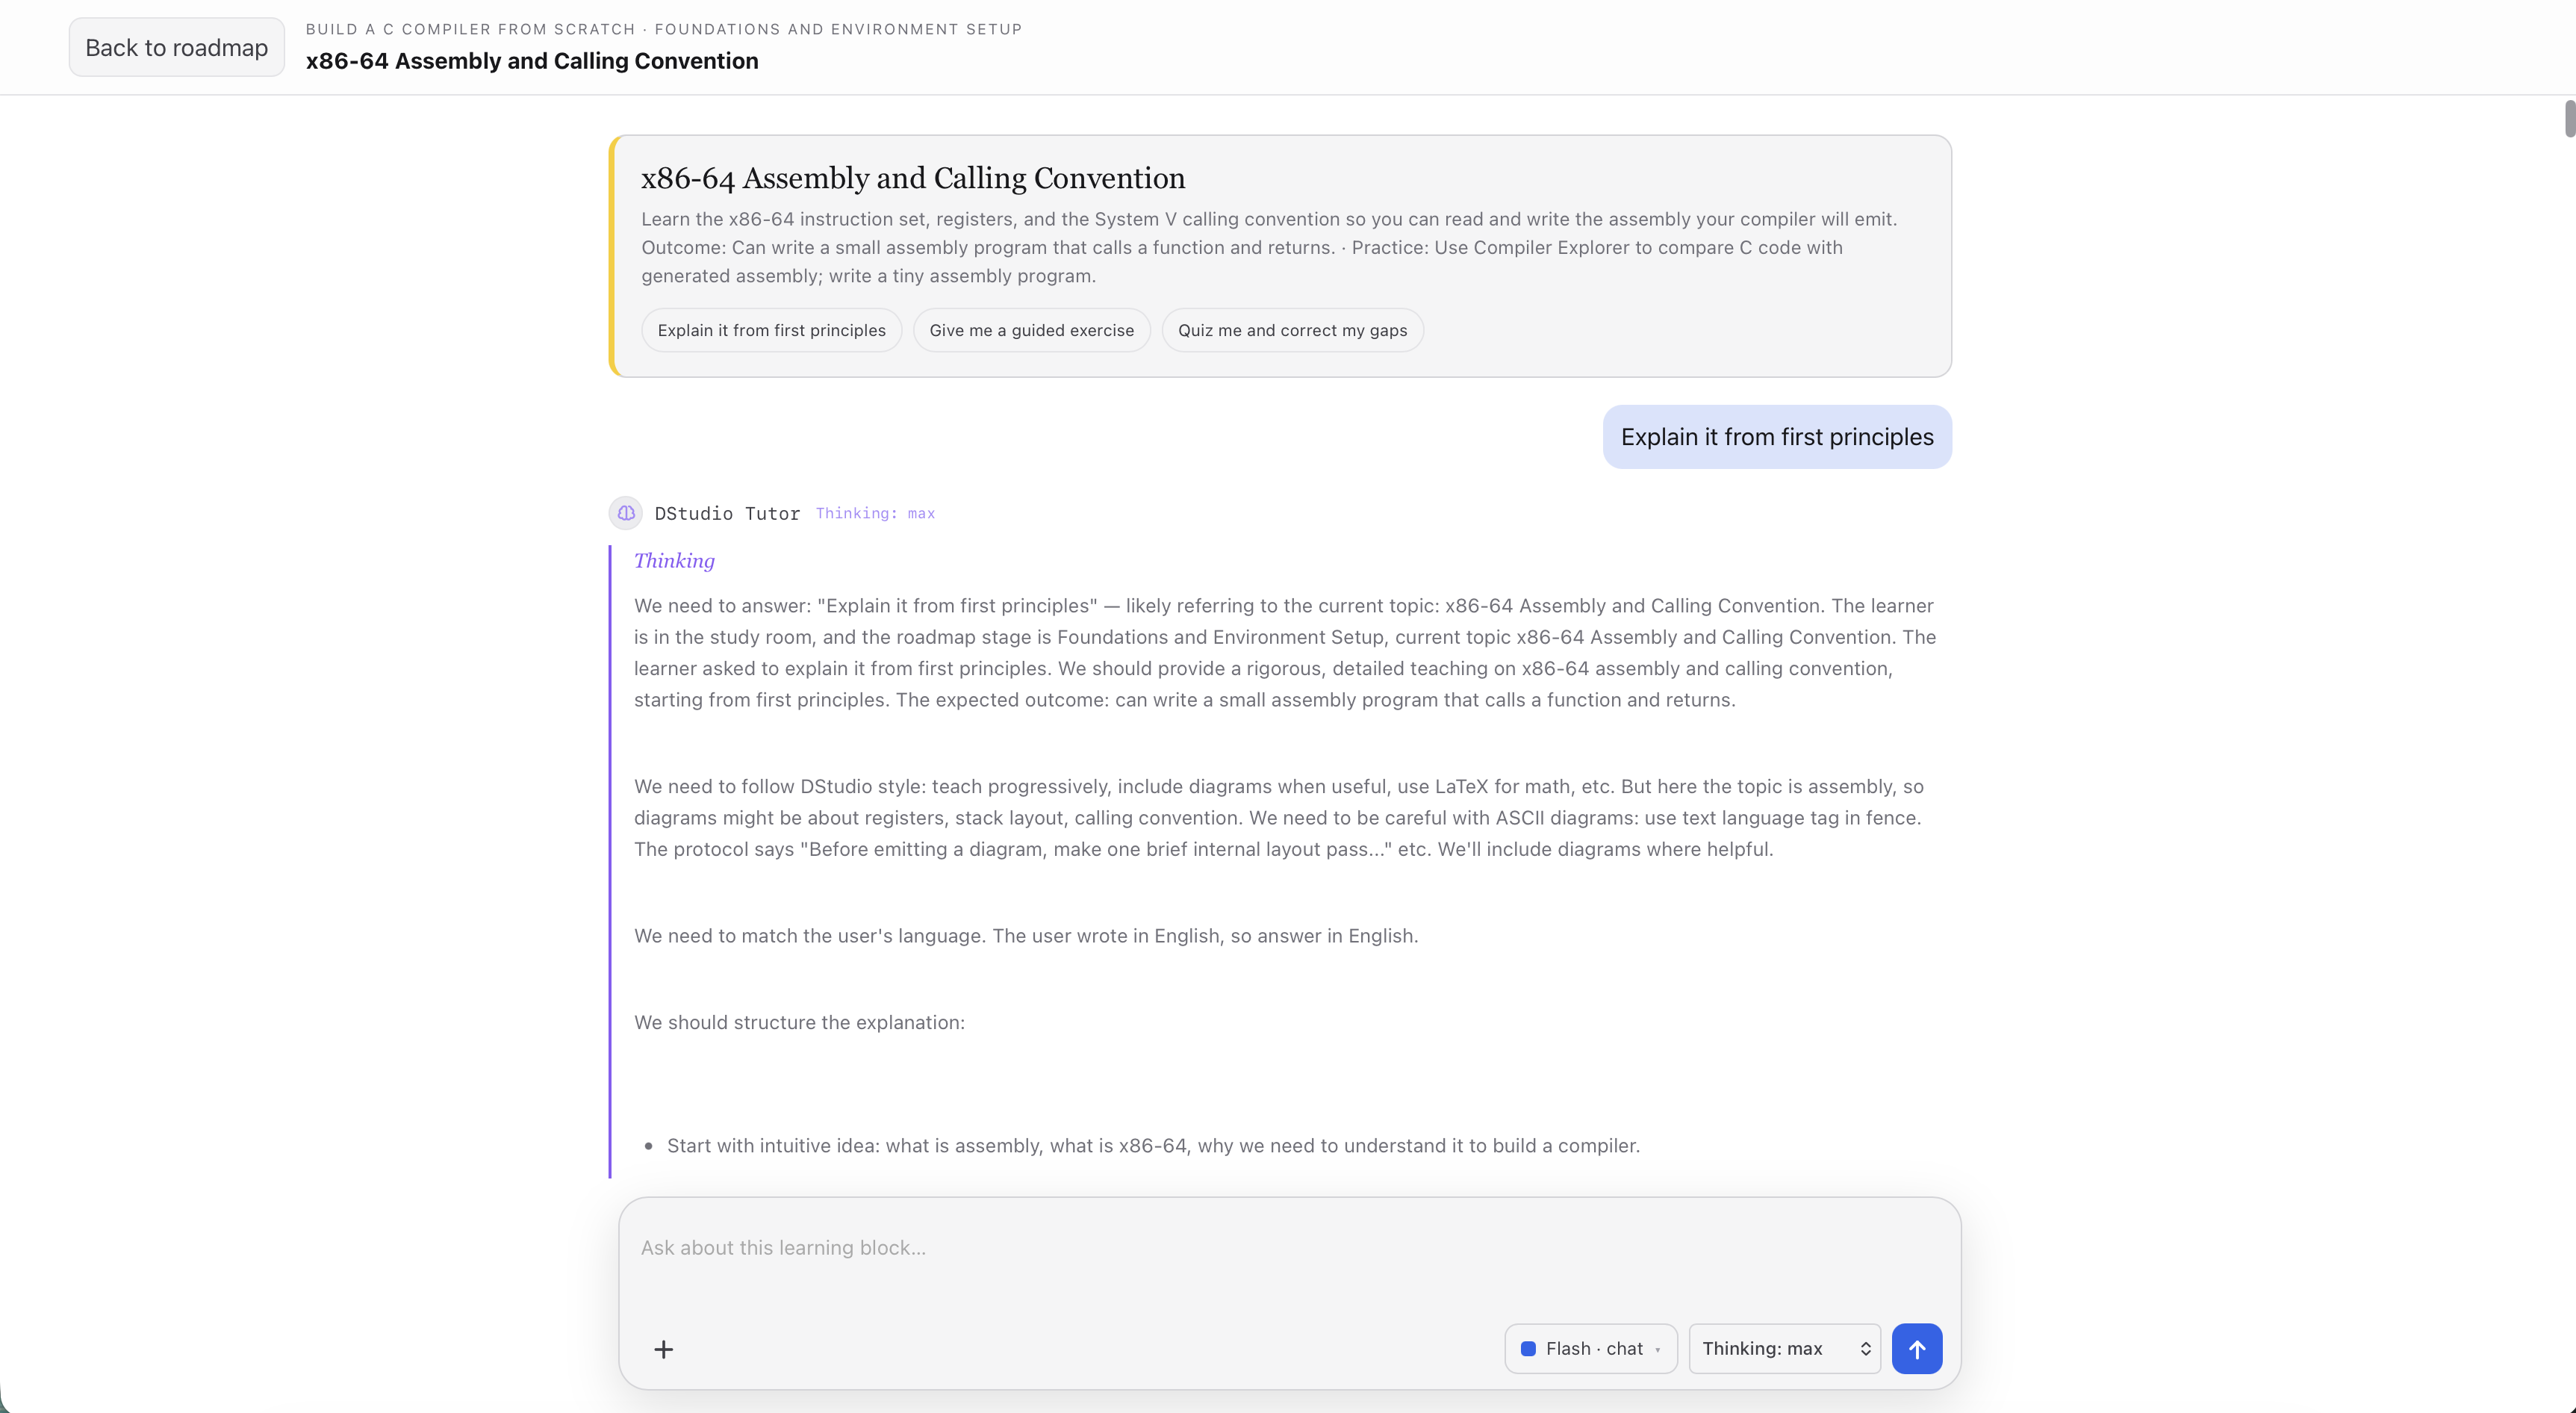
Every stage, topic and final project has a Study button that opens a full-screen Tutor chat for that block. The Tutor already knows the goal, stage, prerequisites, outcome, practice task and sources, so it can teach from first principles, answer follow-ups, give guided and independent exercises, run quizzes and correct your work. It keeps the normal Chat tools (Thinking, files, PDFs and images, LaTeX, ASCII diagrams, hints, canvas previews). Each block owns its transcript and attachments, so Study resumes the same lesson.
Learn generation and its verification roles use Thinking: max. Local ds4 needs at least 393,216 context tokens for Max, so DStudio temporarily launches the Learn pipeline at that size when your Chat context is smaller, without changing the saved setting. Learn has not been qualified on the llama.cpp/MLX Qwen models.
Local Image Generation
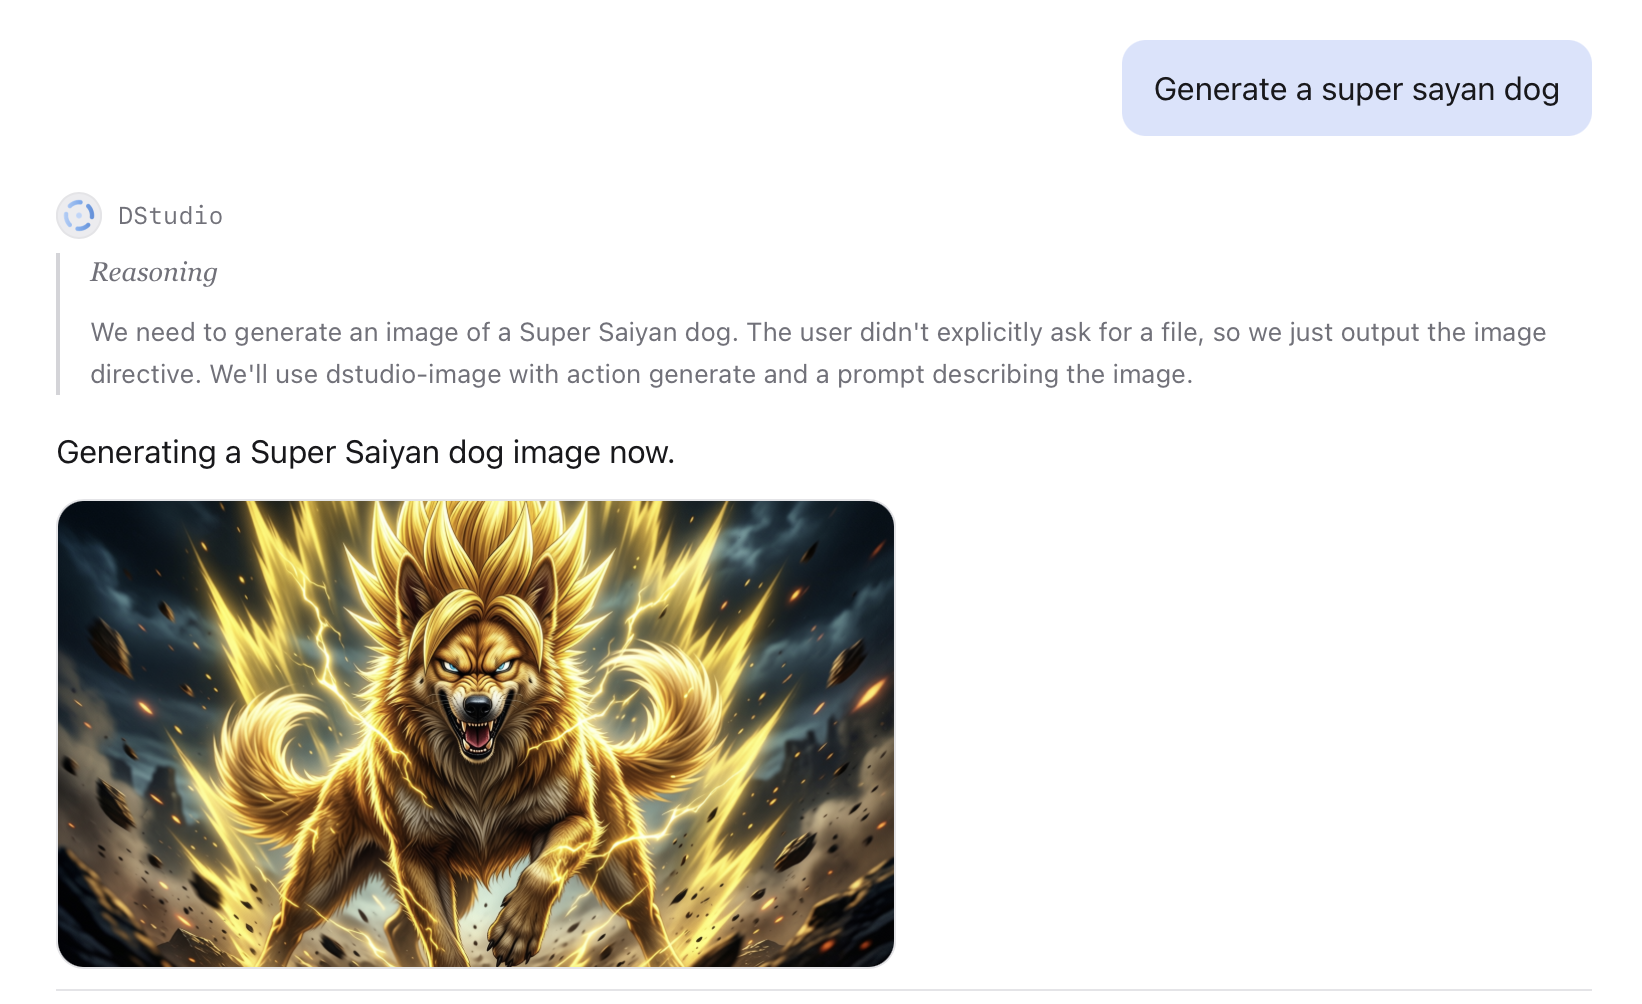
Ask for an image in any language. DeepSeek Vision-Exp or GLM 5.3 interprets the
request and any source pixels, then emits an explicit generate or edit
directive. generate goes to Ideogram 4 FP8 with your image preset; edit goes
to the full, non-distilled HunyuanImage-3.0-Instruct model (NF4 so it fits the
96 GB reference Mac, with critical layers and compute in BF16, think_recaption
and 50 diffusion steps through Tencent's official implementation). Text-only
models cannot issue source-dependent edits.
The reply gets a placeholder immediately while DStudio reports real load, reasoning, sampling and decode phases. Presets are explicit choices, never an automatic downgrade. One lock serializes Ideogram, Hunyuan and H3, and the media-memory lease evacuates a resident chat/Design model when required. Generated files stay local and are attached to the conversation.
Image presets
Choose Settings → Vision → Image preset. It controls new Chat images, generated video opening frames and new Design sessions; changing it does not restart a model or alter a render in progress.
| Preset | Intended use | Generation steps | Landscape image (16:9) |
|---|---|---|---|
| Low | Quick drafts and composition checks | 12 | 1024 × 576 |
| Medium | A balance of detail and waiting time | 20 | 1024 × 576 |
| High | More refinement at the same size | 48 | 1024 × 576 |
| MAX | A larger, natively generated image | 48 | 2048 × 1152 |
MAX preserves DStudio's previous default. Low, Medium and High use Ideogram's Turbo-12, Default-20 and Quality-48 samplers; MAX uses Quality-48 at twice the width and height, not an upscale. More steps or pixels do not guarantee better prompt adherence.
Measured on an M2 Max with 96 GiB, with other apps left running:
| Preset | Classical illustration | Headphone portrait |
|---|---|---|
| Low | 4m 31s | 6m 37s |
| Medium | 6m 51s | 10m 13s |
| High | 15m 46s | 24m 35s |
| MAX | 78m 01s | 123m 33s |
These times include failed outputs. All eight attempts finished, but only four produced illustrations; the other four returned refusal-message images, and the illustrations missed details of the brief. This small comparison does not establish a quality winner or guaranteed waiting times.
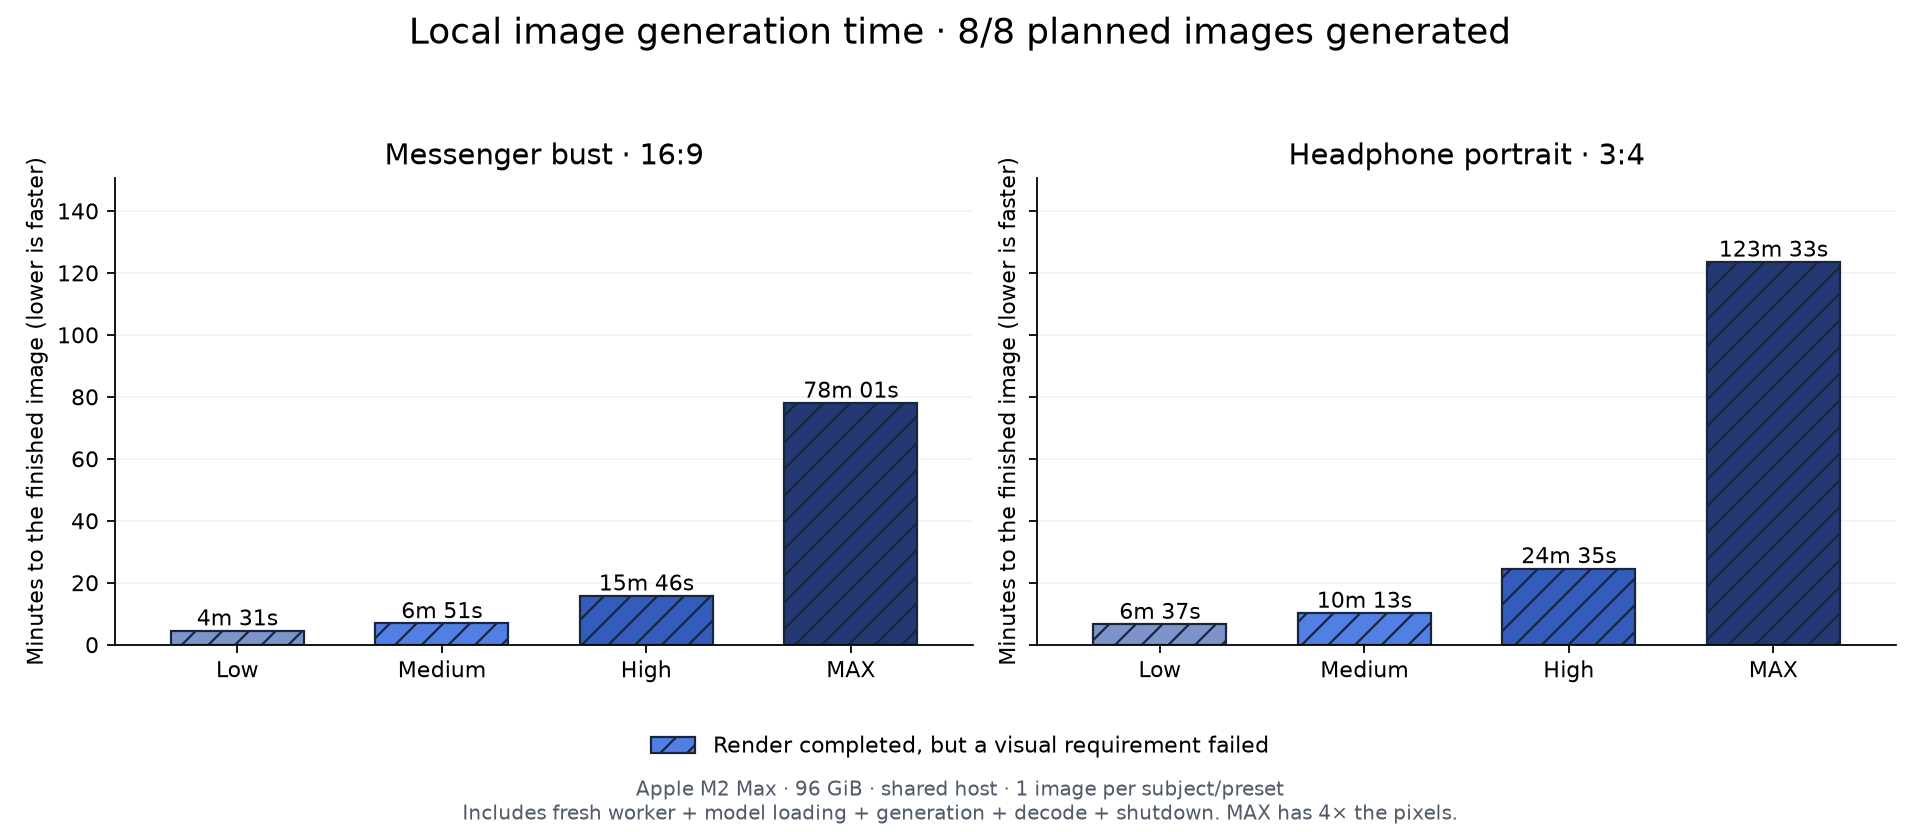
Full preset benchmark: every original image, findings, exact settings and reproduction steps.
Local Video Generation (MiniMax H3)
DStudio runs the downloadable MiniMax H3 weights through a pinned antirez/h3.c checkout: a native C/Objective-C engine on Metal, MPSGraph and Accelerate, without ComfyUI or PyTorch. Ask for a video in Chat; DStudio routes it to the one-shot executable, optionally uses a recent image as the first frame, reports h3.c's real progress and returns a locally streamed MP4. You can also ask for an opening image first (Ideogram 4) and then animate it. No hosted generation API is used.
Work in progress — two-photo H3 references. With MiniMax H3 selected, two attached images become ordered Ref2VA inputs (
<Picture 1>,<Picture 2>). Settings has a separate preparation action for the official Ref2VA transformer (about 61.7 GiB / 66 GB on top of FL2VA). This path has not yet completed end-to-end validation.
Open Settings → Video before the first generation, review the upstream
terms, confirm that your territory and use are authorized, then select
Prepare local H3. Setup compiles an immutable h3.c revision and downloads
only the official FL2VA/ files (about 134 GiB / 144 GB, resumable) into
~/.dstudio/minimax-h3. Three render profiles expose h3.c's controls:
Quality (default; all 50 blocks, no reuse, 768p-class), Balanced
(--layers 45 --reuse 2, ~512-class) and Preview (40/50 blocks, reuse 3,
upscaled). DStudio never switches profile on its own. M3 and older GPUs use the
portable BF16/MPS path; M5-class hardware can use Metal 4/TensorOps paths.
Search & Deep Research
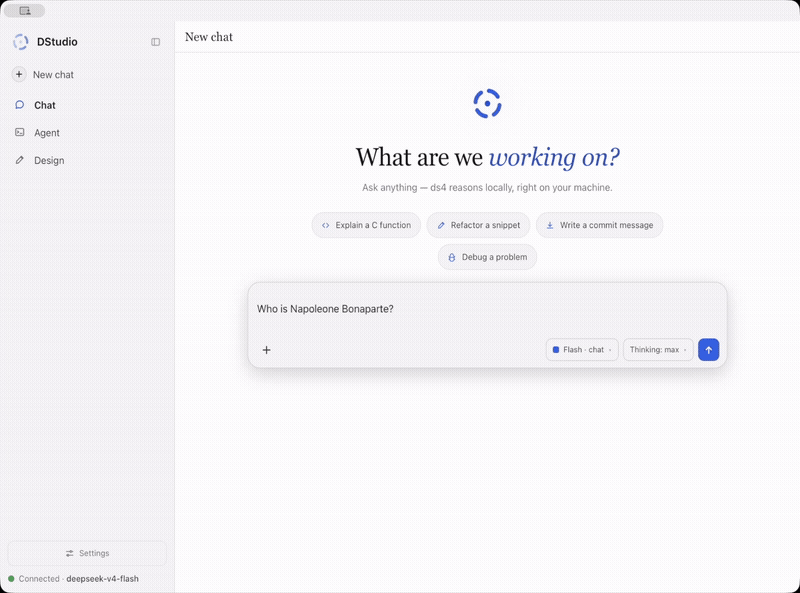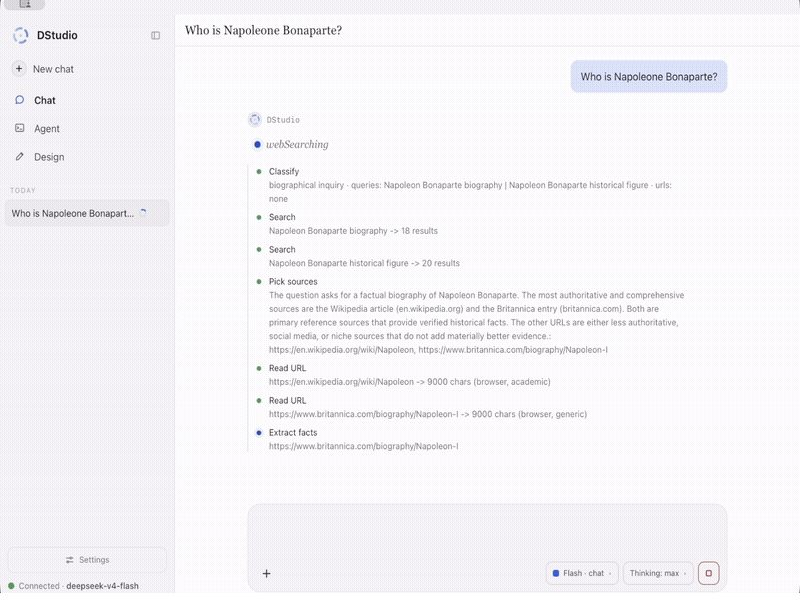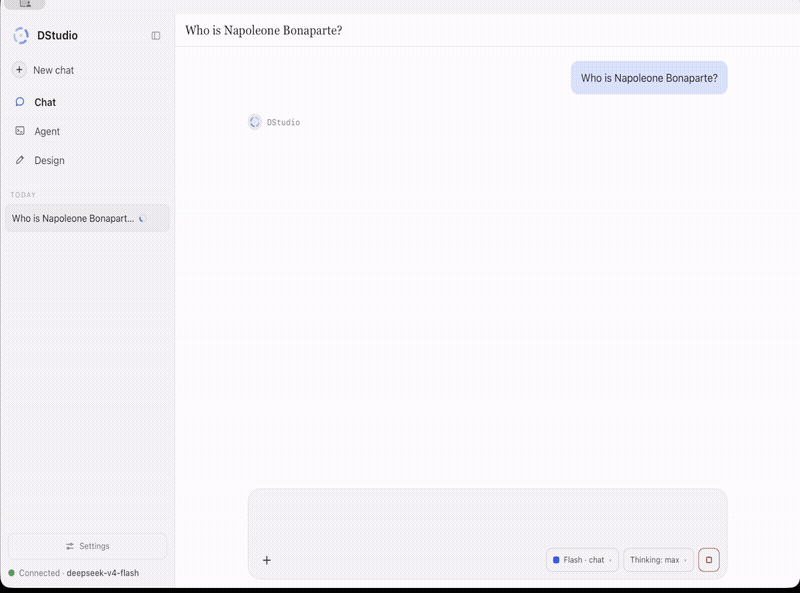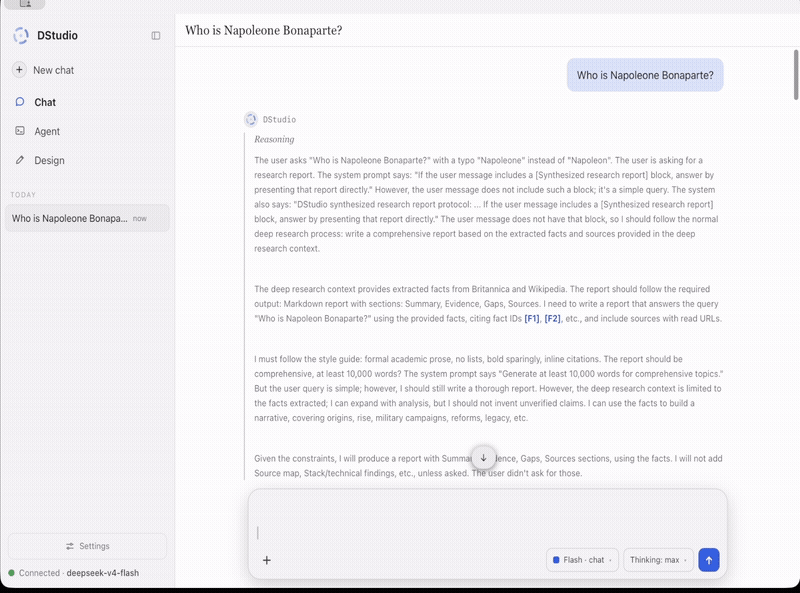
Search runs through DStudio's local web helper, not a hosted browsing service. Web Search plans targeted queries, reads the best pages, extracts facts and answers with clickable citations. Deep Research runs a longer evidence loop: classify the request, search, read primary sources, extract facts, judge sufficiency, write a grounded report and keep the source cards.
Before delivering a Deep Research answer, DStudio checks it against the collected evidence and the request; it can revise unsupported claims, missing details or undisclosed disagreements, and counts explicit word limits. A failed review is shown as an incomplete draft, not a verified result. The reviewer is the local model too: it helps catch errors but cannot guarantee truth.
Relevant details can come from later page sections, and with an active native vision model research can inspect real pixels of an image or chart (one viewport per page, three captures per run). Settings → Web research lets you set separate page-read and candidate-source limits for Search and Deep Research. Defaults are 8 reads / 96 candidates for Search and 24 reads / 256 candidates for Deep Research, including learning-path research. Each mode accepts 1–512 page reads and 1–4096 candidates; changes apply to new runs. These are ceilings, not targets: sufficient evidence can end discovery earlier. Query/action budgets also remain bounded: Search admits up to 6 queries; Deep Research up to 18 queries and 12 follow-up actions. Source selection and report writing, including reviewed revisions, omit application output-token caps. The engine's context/output limits and retained-draft size bounds still apply. There is no application elapsed-time cutoff on discovery, writing or review: a slow valid local-model request continues until it completes, fails or you press Stop. Measured scope and limits.
Agent
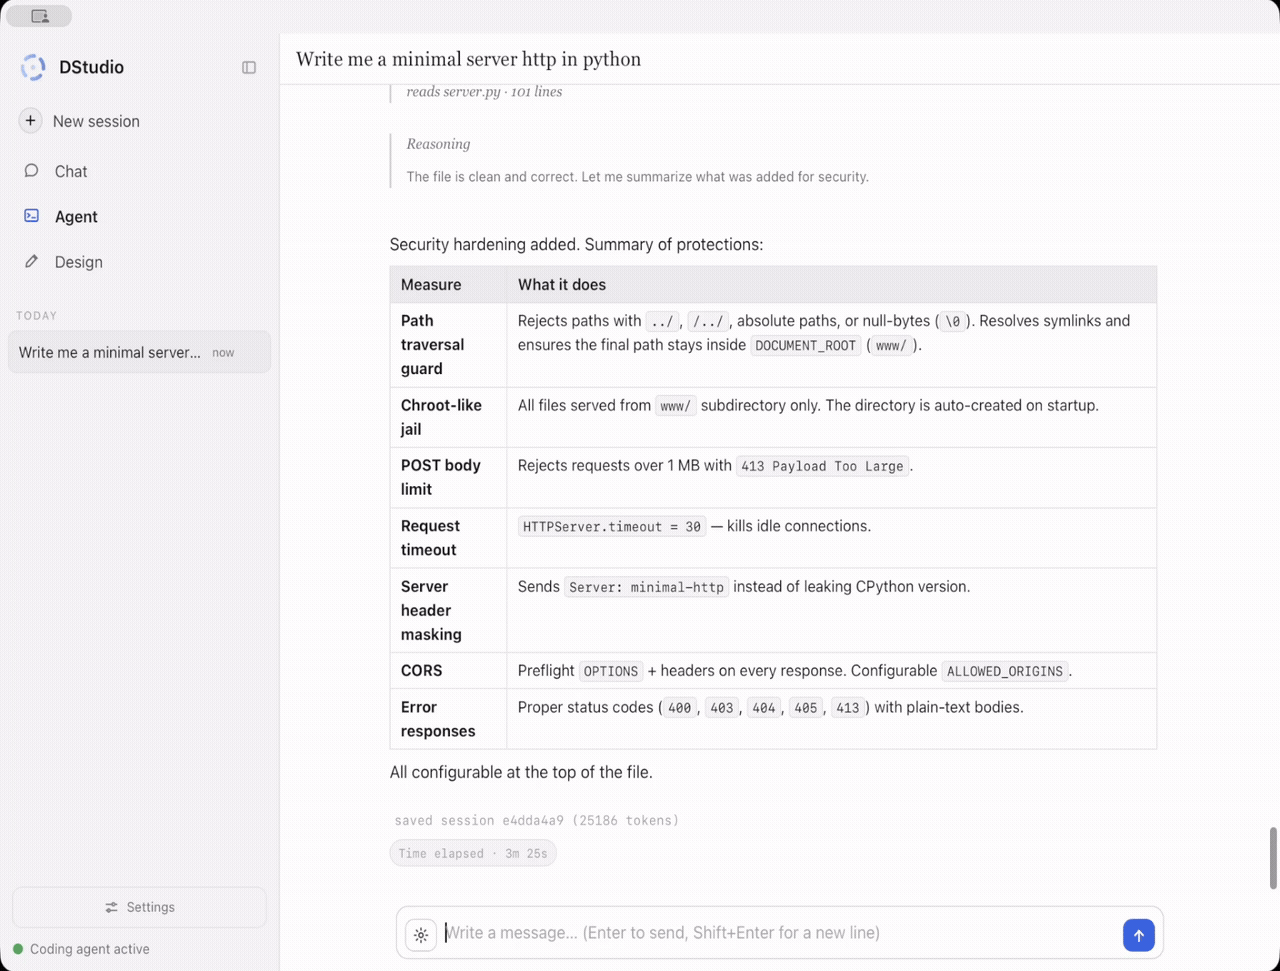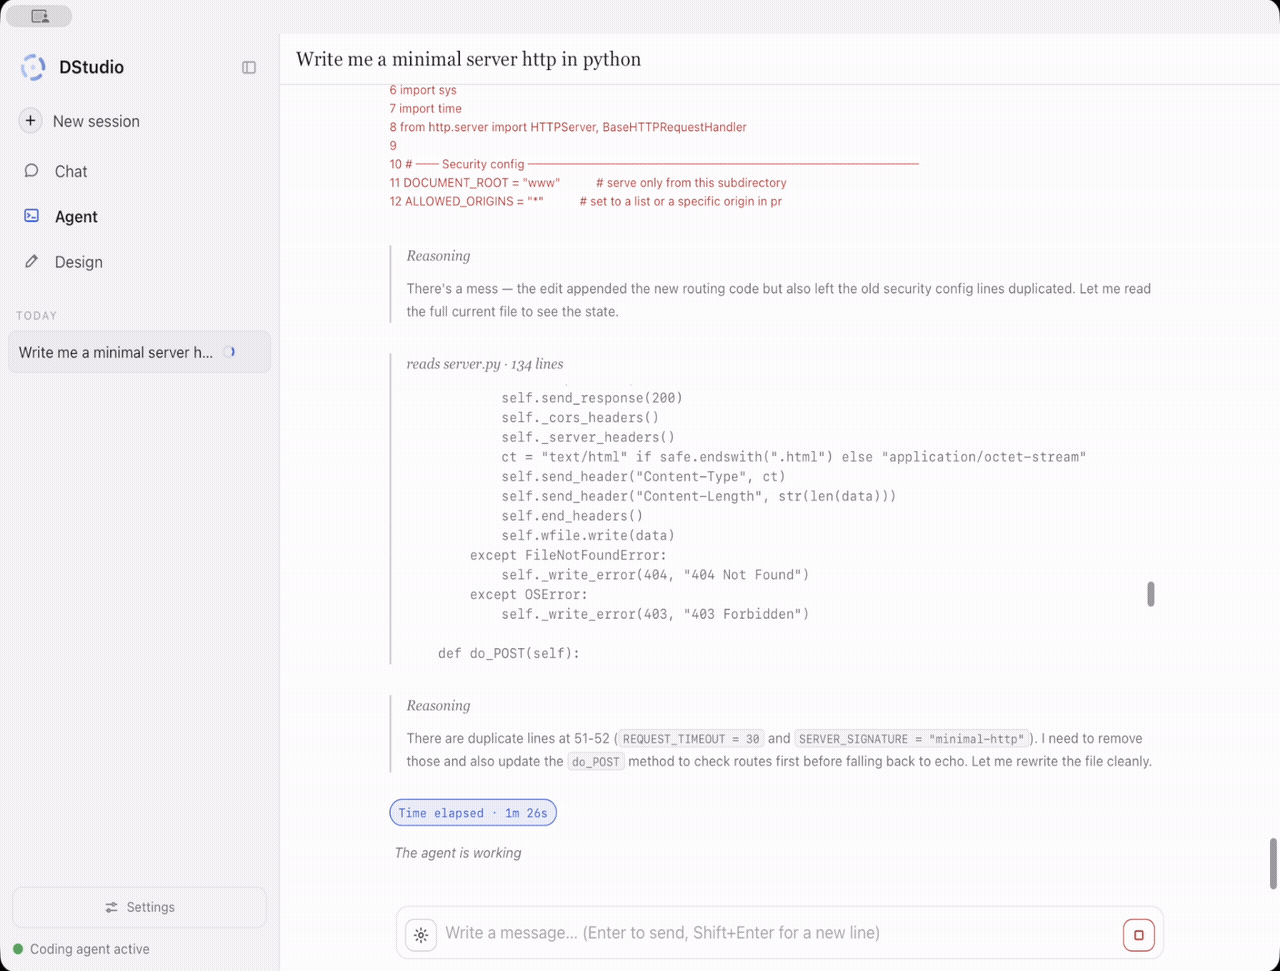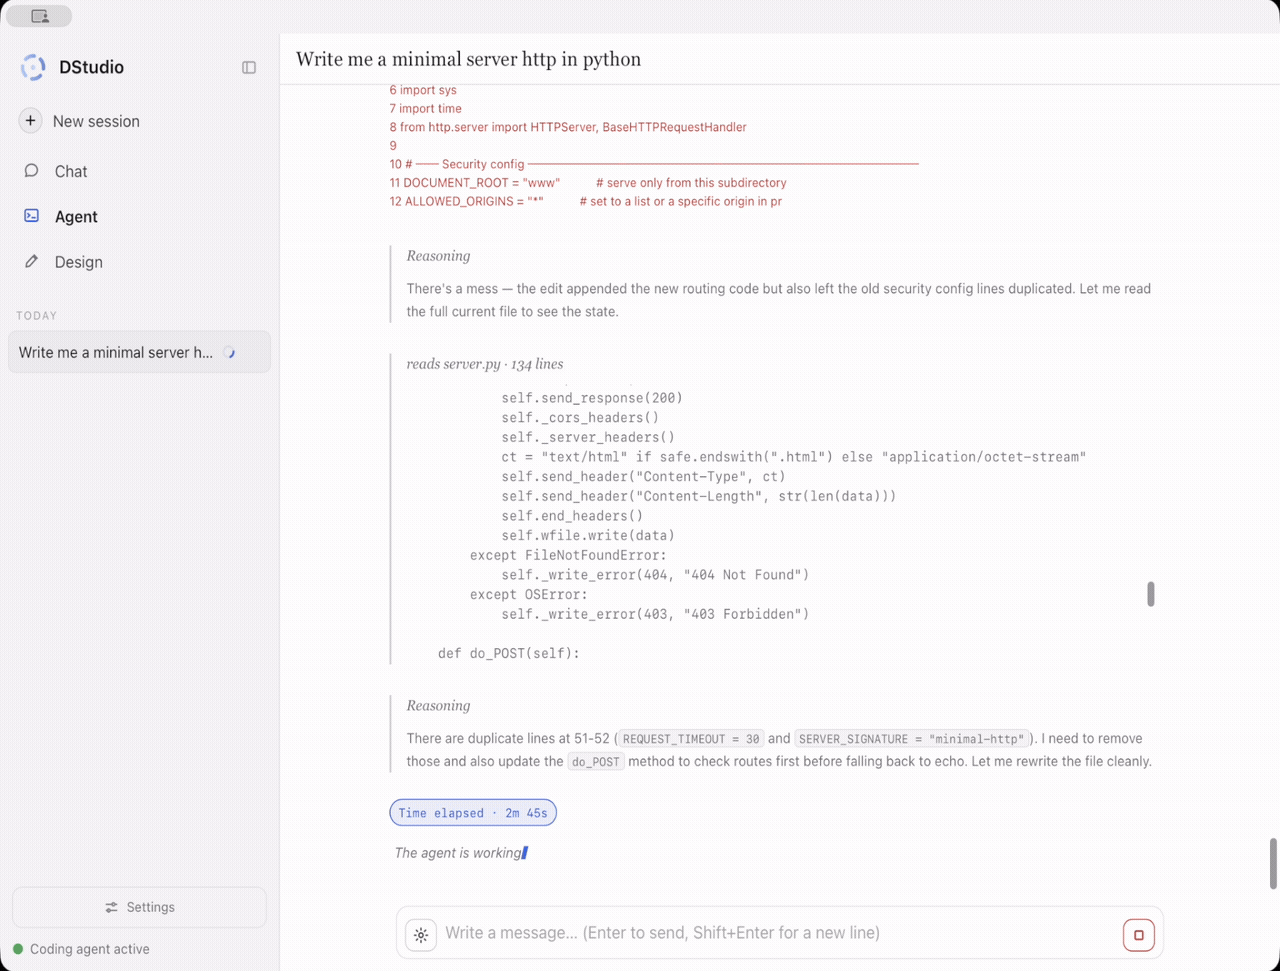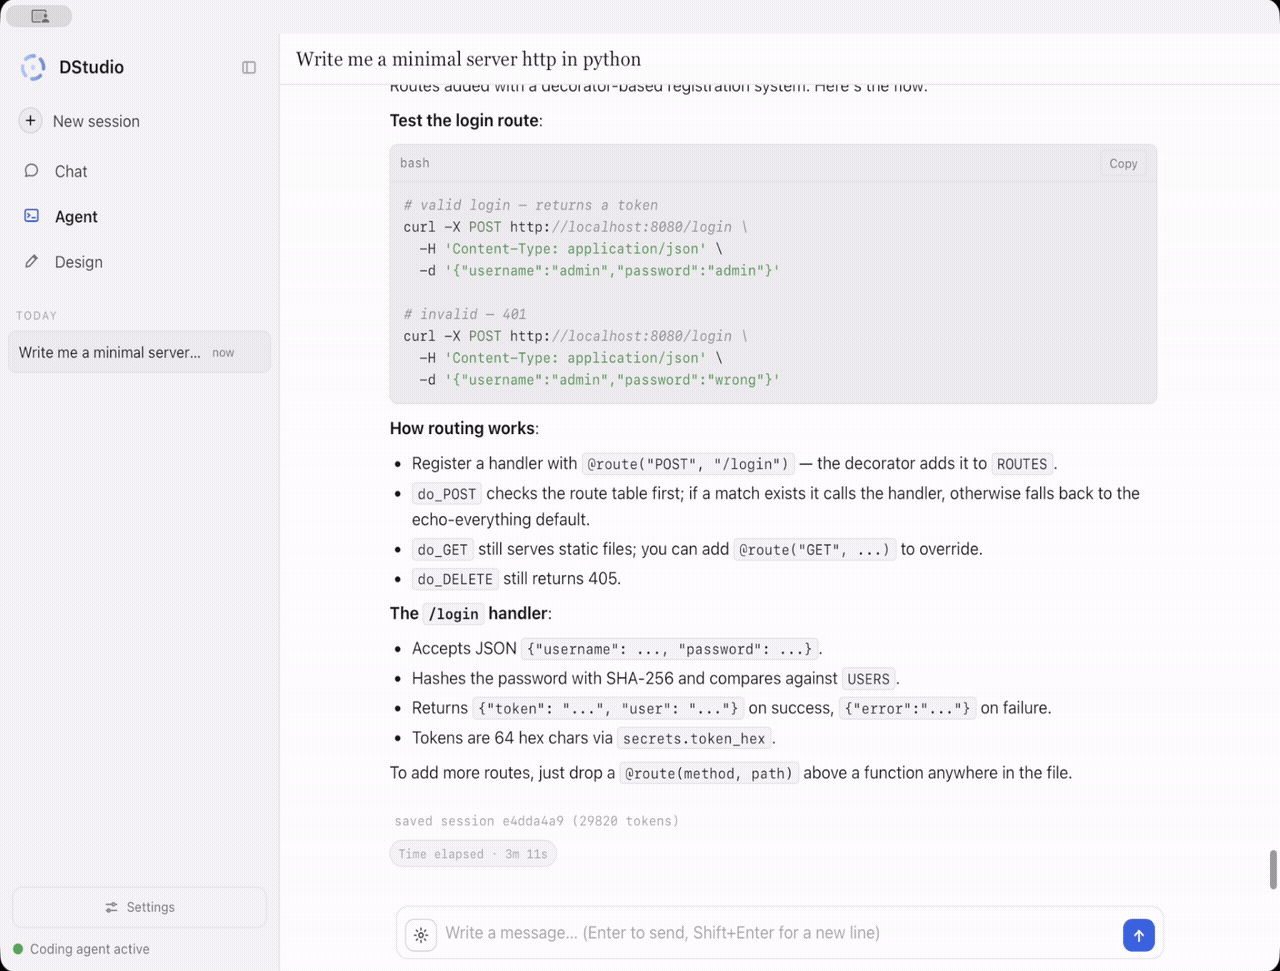
Agent is a local coding agent: it reads and edits files, runs commands inside a
working directory you choose, streams its answer while it works, folds private
reasoning into a Thought disclosure and groups tool calls into a compact
action timeline. The header shows the mode, model and working folder;
/help, /list, /save, /new and /compact are available below the
composer. A post-edit verifier catches common syntax errors so the model can
repair them in the same turn. By default this is DStudio's own agent;
pi or OpenCode can run instead.
Open IDE. The header's Open IDE replaces the conversation with a VS
Code-style view of the working folder: file tree, tabs, a syntax-highlighted
editor and a terminal panel with the agent's bash commands and output. While
the agent writes a file, a cursor labelled with the active model shows the text
as it is generated and Follow keeps the editor on that file. While the model
reasons, a thought bubble shows the newest words of that reasoning. Streamed
text is marked not on disk yet until the tool finishes and the IDE re-reads
the file. After the turn you can edit and save (⌘S); DStudio refuses the save if
the agent started again or the file changed on disk, and asks which version to
keep. Limits: UTF-8 text up to 2 MB, links open read-only, not available on
Windows yet; runtimes that do not stream tool results show the files when the
turn ends.
Open Blueprint. Turns the working folder into interactive diagrams the
Agent maps from the code: Architecture, Workflow, Sequence,
Data flow or Lifecycle, optionally focused on a question. The Agent
writes a typed blueprint (dstudio.blueprint/1) to .dstudio/blueprints/,
citing a file, a line range and a quoted line for every node and relationship.
DStudio checks every citation against the file's bytes and shows how many claims
are backed; click a node for its evidence, Trace what it reaches, find a
Route between nodes, search with /, open a citation in the IDE, and
Export HTML, SVG or JSON. Send to Design starts Design in a design/
folder with the blueprint attached; Implement code asks the Agent to build
what the blueprint describes, in dependency order, running the build and tests
after each group. The check proves that quoted lines exist, not that the model
described the behaviour correctly. The idea follows
Archify (MIT); no Archify code is included.
Thinking defaults to high. Selecting max below ds4's 384k-token threshold explains the required context and estimated memory cost before restarting; declining changes nothing.
Prompt lookup (experimental, ds4 Chat / Agent / Cowork). The managed ds4 runtimes can reuse text already in the conversation as candidate output, checked by the same model. It helps when copying or preserving existing text; it does not invent new answers faster. Normal generation stays the default; accelerated batching is opt-in. Modes and tests.
Prompt lookup: real-engine results
The clearest benefit was in Chat; it was not a general Agent speedup. The actual DeepSeek V4 Flash engine ran on an M2 Max with 96 GB, Minecraft left running and SSD streaming off: 78 tasks (13 cases × 3 modes × 2 repetitions). Faster but incorrect results did not count.
| Workspace | Checks passed in each mode | Experimental PLD vs disabled, in this run |
|---|---|---|
| Chat | 14/14 | 2.84× observed speed, comparing the same correct outputs |
| Agent | 6/6 | About the same overall; long copies helped, new code did not |
| Cowork | 2/6 | No useful overall conclusion: document-fidelity failures remained (fixed since: see below) |
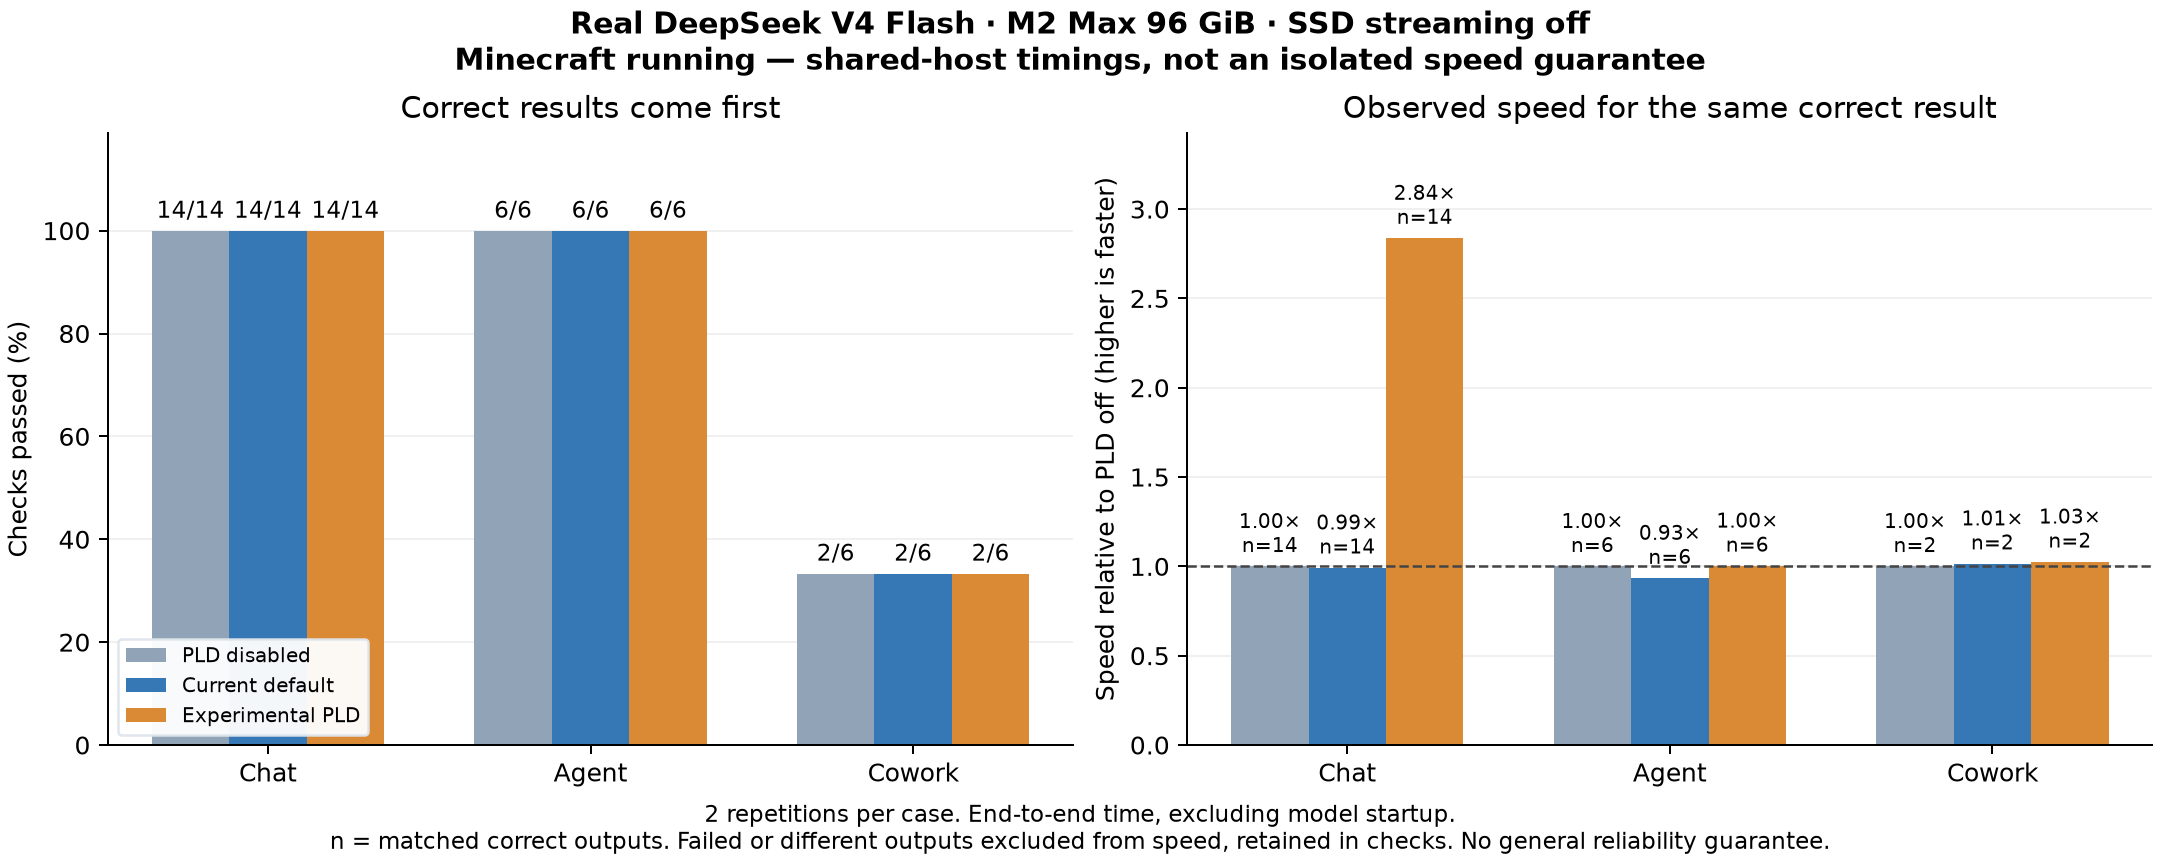
Median Chat copy time fell from 30.0 to 12.3 seconds; an Agent file copy from 86.0 to 75.0 seconds, while a small edit stayed around 36.7 seconds and a new function became slower (21.8 to 28.3 seconds). 66/78 checks passed: the 12 failures were the same Cowork copy cases in every mode (a lost final newline). Method and per-task results · data.
Cowork copies, fixed (October 3). Rerun on DeepSeek V4 Flash Vision-Exp
IQ2XXS at 16k context, 2 runs per case: copies and revisions of files that end
with a newline went from 0/2 to 2/2, and a new case copying a file
without a final newline stays 2/2. The model still drops the trailing
newline; write_document now ends a text document with one unless
final_newline=false, and the runtime now forwards that argument.
Details, retained failures and data.
Cowork
Cowork turns the selected local model into a knowledge-work partner for a folder of real files. It reads PDF, DOCX, PPTX, ODT, RTF, Markdown and text; inspects, reads and writes XLSX, CSV and TSV; creates verified documents, paginated PDFs and 16:9 presentations; and reopens its outputs before reporting completion. Uploaded names are sanitized, macro-enabled formats are rejected, writes are atomic and file access is confined to the workspace, including symlink and traversal checks.
The Office bridge is a small standard-library Python helper invoked with a
bounded JSON request; there is no command shell or arbitrary Python in Cowork.
Cowork's tool list no longer offers the shell tools it refuses (bash,
bash_status, bash_stop). Before this, models called them and got an error.
Spreadsheet and document text is framed as untrusted source content, so
embedded instructions are not treated as tasks. Cowork uses the context size
from Settings and the same conversation surface, Thinking view and action
timeline as Agent.
Cowork can also turn several documents into a source-backed comparison table, for example “Compare these course programs by topic, duration and prerequisites.” Each cell can show its original excerpt, file and page; missing and conflicting values stay explicit; sources are rechecked on inspection and export (expandable HTML or an Excel workbook with data, status and evidence sheets). A source match confirms the quote and value occur in the document, not that the interpretation is correct. Limits: text-layer PDFs and Office/text sources (scanned PDF pages are read with local OCR on macOS, and quotes matched in OCR text are marked for review), up to 5,000 rows, 128 columns and 100,000 cells per table, and 512 files (PDFs up to 2,000 pages). Extracted text is cached by content in the user's cache folder, so a recheck does not extract unchanged files again. In the scale test, a 5,000 × 20 table built from 512 synthetic text files took 8–13 seconds per create, recheck or export, with a peak of about 0.5 GB of memory. That was one run on an M2 Max shared with a running game; it is not a speed guarantee. Document-table tests exercise real files without a model; they are not an extraction-accuracy benchmark.
Skills: local task recipes
Create a recipe, pick it, and the next Agent, Cowork or Design turn inherits its workflow, constraints and quality bar without restarting the model. There is no skill marketplace: every skill is a local Markdown pack written by you, stored in your user data directory and injected only when selected. GSA and RSA use their own deterministic phase templates instead.
GSA: guided security analysis
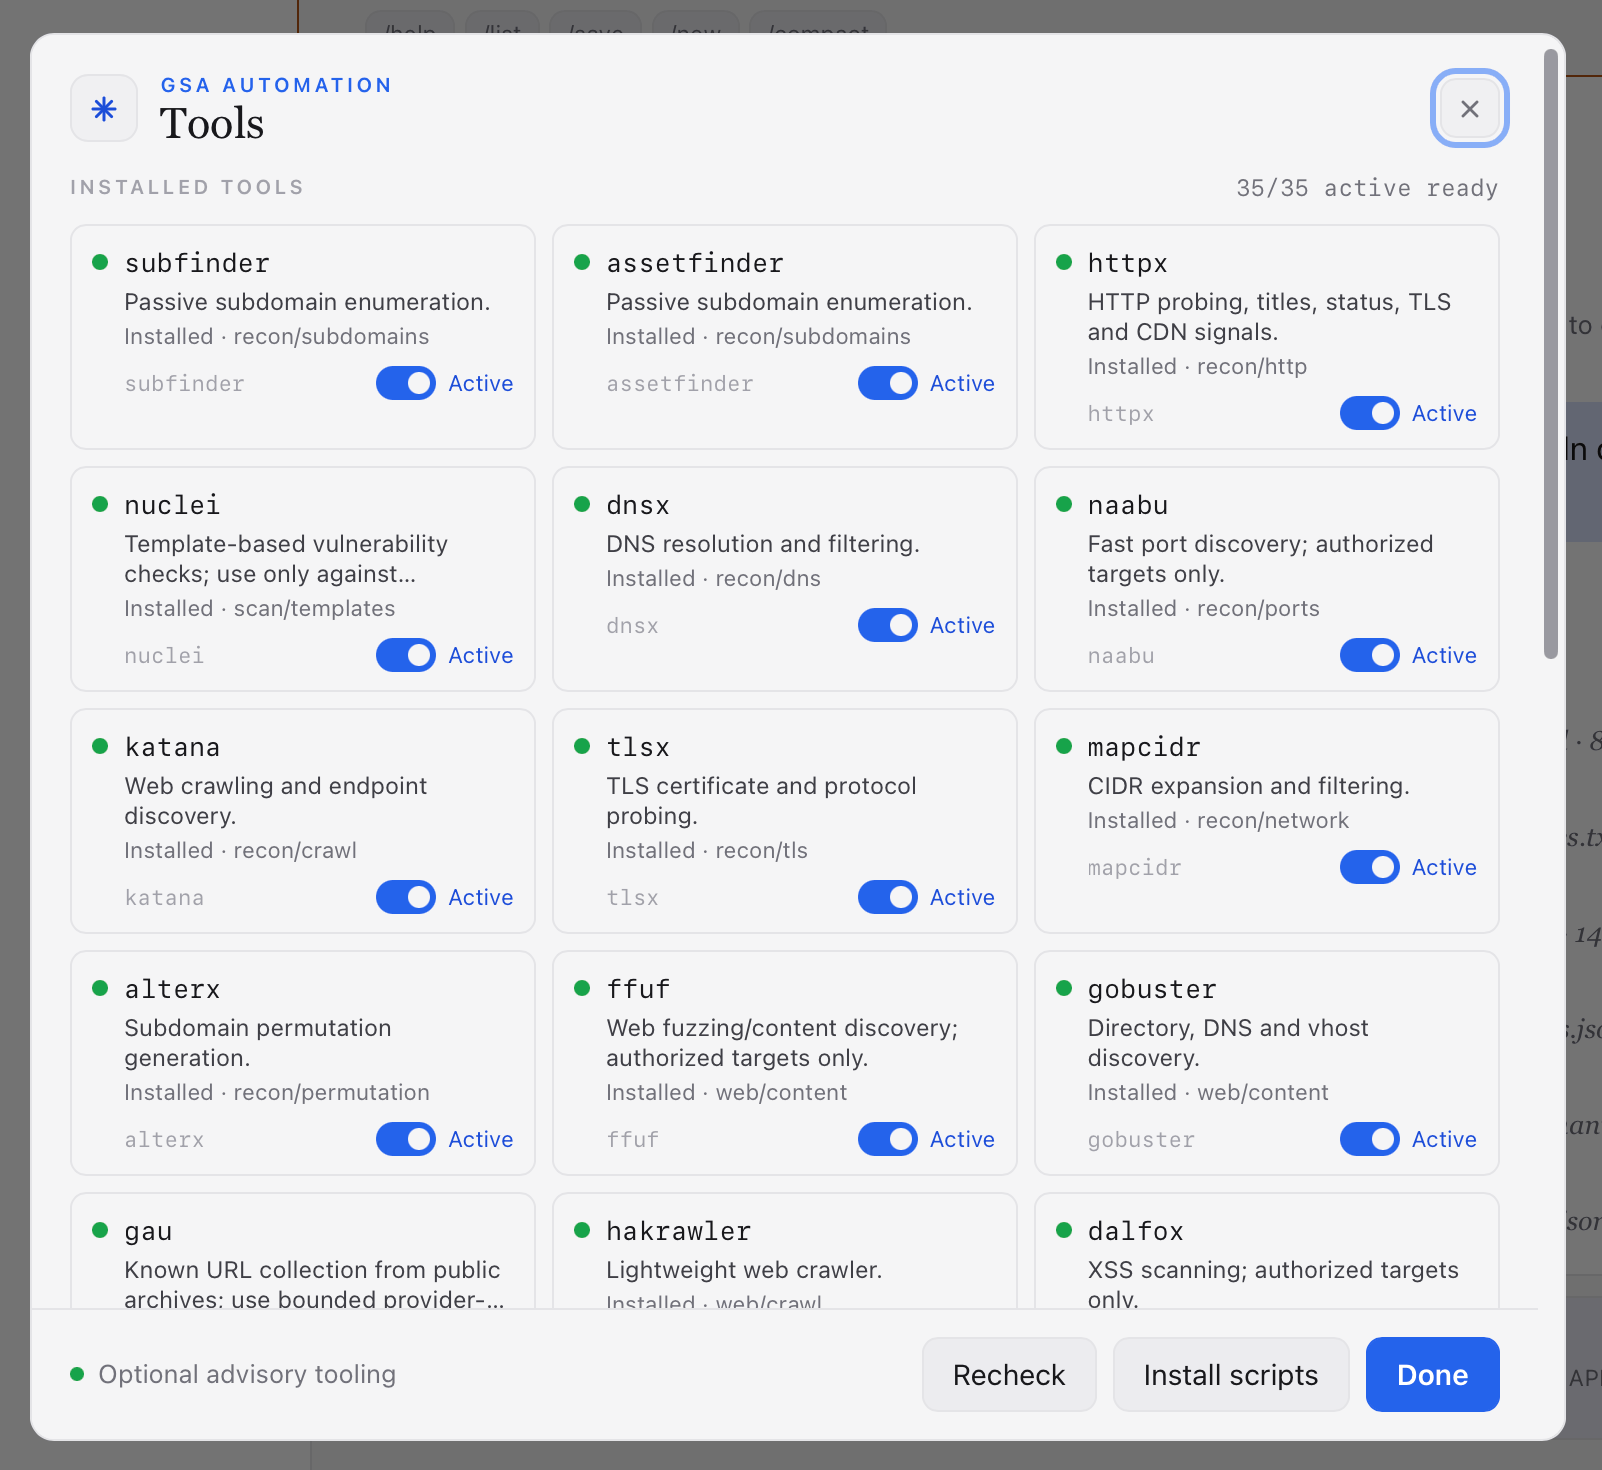
GSA gives the Agent a security-analysis operating mode. Open RSA/GSA beside Open IDE, choose GSA, describe an authorized mission and optionally a target URL. The run goes through selection (files and hypotheses), preflight (evidence, trust boundaries, safe checks), validation (concrete proof with bounded scripts or optional local tools) and report (verdict, sources, limits, next actions). Security profiles distinguish passive, blue-team, explicitly authorized red-team and purple-team work; authorization is never inferred from the prompt. External tools are listed, can be disabled and have their invocations, parameters and output recorded verbatim; Install missing runs a supervised background installer. Each phase is committed through a structured control call validated by the host, and a slow evidence collector is not killed as idle. See the GSA/RSA workflow.
RSA is the non-security reverse-structure workflow: it inventories a public
site's visible routes and assets, captures ordinary browser evidence and writes
STRUCTURE.MD, labelling claims VERIFIED, INFERRED or UNKNOWN. It
never scans, fuzzes, brute-forces or calls private endpoints.
GSA, RSA and Plan were developed and tested with DStudio's own Agent; they are not qualified with pi or OpenCode.
Design: a local design studio
Design is a separate local design agent that runs a designer's pipeline end to
end. ds4-design is DStudio's own harness
(src/harness/design/ds4_design.c): it has
its own system prompt, tools and structured events, and runs on ds4 models
(DSML tool protocol), on the llama.cpp/MLX Qwen models (structured function
calls) and on remote endpoints.
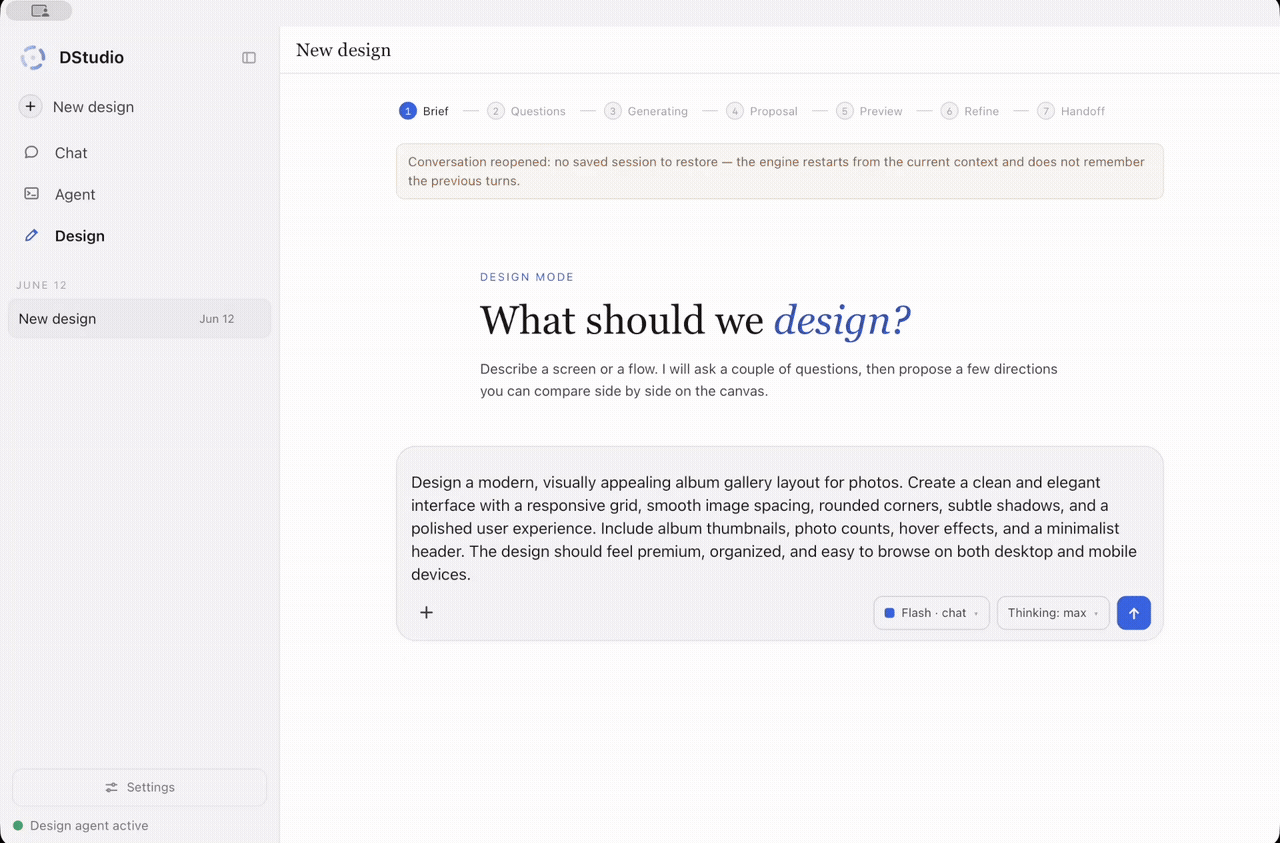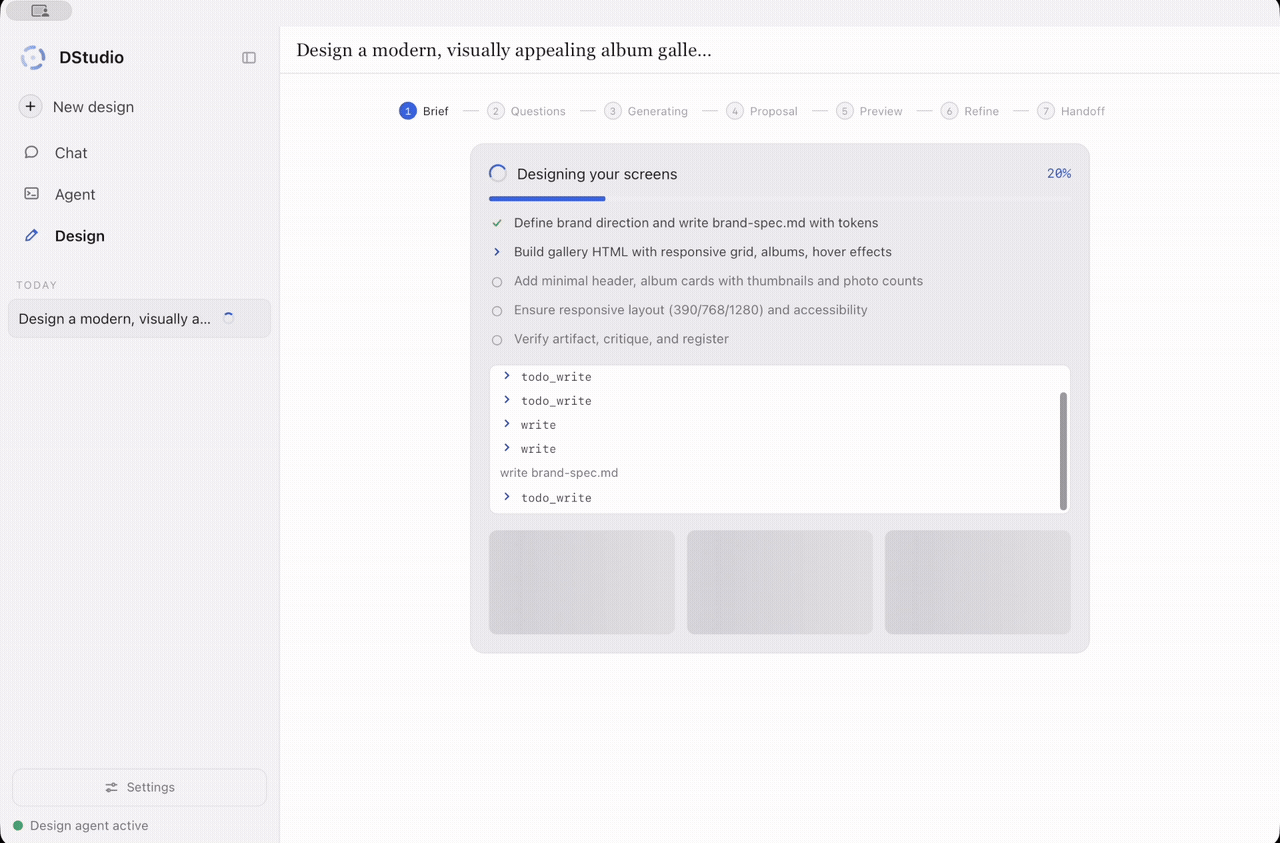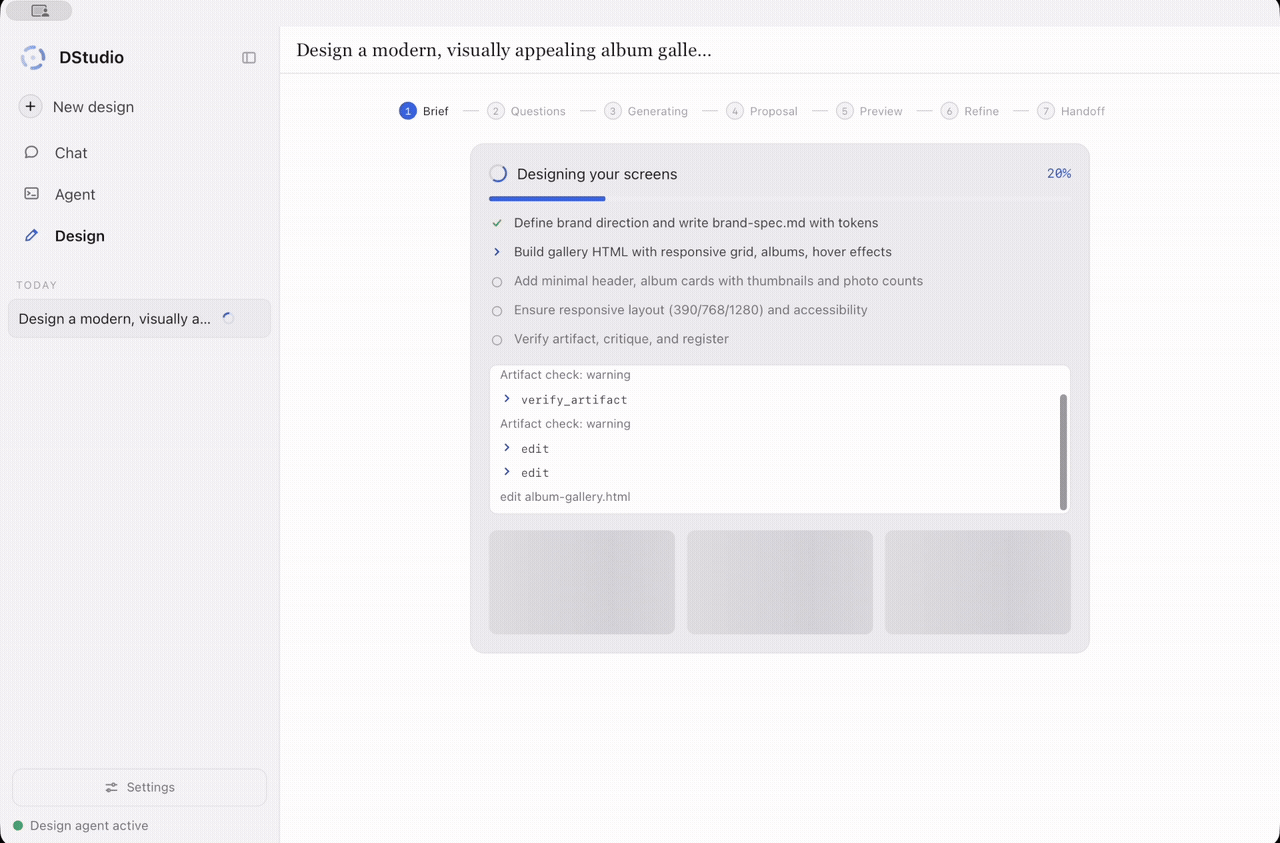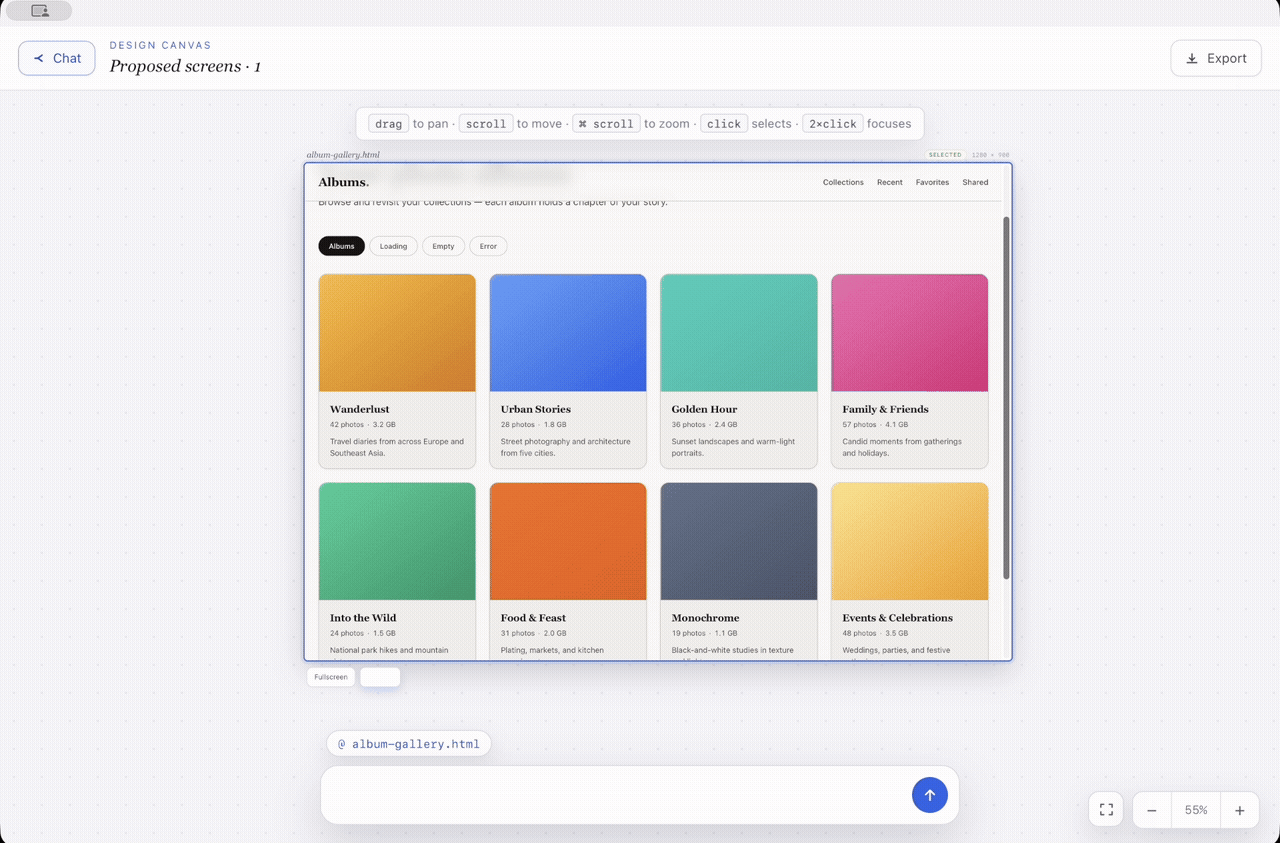
- 1 · Brief. A new design opens on “What should we design?” with Visual starting points: one card per bundled design system with its real palette and type. Filter, search and load a system's brief into the composer. Design can start in any folder; clearing the project removes only files the design run created.
- 2 · Questions and building. The designer's questions appear above the composer, thinking folds into Thought, and every action lands in one Working timeline, with proposals and finished screens as cards.
- Open IDE with a live design. Code · Split · Design views: while the model writes an HTML file, the Design pane builds the page from the streamed bytes (scripts off), updated in place so you can scroll while it grows. After the turn the pane shows the saved file with scripts on, and you can edit it.
- 25 original visual systems, offline: editorial, operational, portfolio, service, event, commerce, community, map, editor, finance, correspondence, planning, inventory, documentation, recipe, media and product-landing directions, each with light/dark colors, interactive examples and behaviour contracts. Catalog, tests and remaining qualification: authored previews pass their checks; model-generated projects are not yet qualified.
- Measured layout checks. Before registering HTML, Design renders it at 1280, 768 and 390 px and blocks page overflow, overlapping controls and distorted media; a missing renderer is reported, not counted as a pass.
- Reliable delivery. Incomplete writes are rejected with recovery guidance; unfinished answers are not marked complete. Before/after experiment: individual improvements, no overall quality win established.
- Reasoning control. Thinking effort and context are independent; Design honors your context (32k minimum) even at Max.
- 3 · Proposal. Distinct directions side by side, each with a rationale.
- 4 · Native visual loop. With DeepSeek Vision-Exp or GLM 5.3, Design can generate a PNG with Ideogram 4 or edit pixels with HunyuanImage, then inspect the result with the same model's encoder and grade the composed page against deterministic desktop/mobile evidence. Text-only models skip this loop.
- 5 · Quality gate, canvas and export. Deterministic checks plus a role-weighted critique (minimum 8.5) gate artifact registration; accepted screens land on the canvas for refinement and zip export. Select to edit in the full-screen preview sends the exact element and your comment back to Design.
Plan, goals and Task Graph
Plan. Toggle Plan in Agent mode, describe the outcome, and DStudio
writes a Markdown planning file (plan.md or <topic>-plan.md) with objective,
assumptions, milestones, tasks, decisions, risks, validation checklist and next
actions. It plans; it does not build.
Adding context while working. In Agent, Cowork and Design, sending while a turn runs adds context to the current turn after the current model/tool round; it does not press Stop or repeat an executed tool. Chat keeps the partial answer and continues with the new context.
Goals. In Agent, /goal <objective> keeps working across turns towards one
saved objective (default limit 8 turns, no default elapsed-time cutoff).
/goal pause, /goal resume and /goal clear are also buttons above the
composer. A goal needs a successful verification command and a completion
receipt; this checks execution evidence, not whether the chosen test covers
every requirement. Behavior and limits.
Task Graph is part of Agent automatically. A normal question takes the direct path; a request to inspect, edit or test the workspace runs inside a checked graph around the same agent. An action is not marked successful because the model stopped talking: DStudio requires a real tool result followed by a completion receipt. You can watch the graph, pause, resume and reopen it after a restart; automatic undo is offered only when DStudio can prove exactly what will be restored. Implementation and local API.
| Native Agent baseline | Agent with automatic checks | |
|---|---|---|
| When used | Simple questions, or the benchmark baseline | Workspace actions, selected automatically |
| Completion | The agent decides when it is done | Tool evidence and a completion gate are required |
| Rules | Normal tool permissions | Every action checked against the graph's rules |
| Interruption | Continue manually | Pause, resume and recover from the saved journal |
| Undo | Depends on what the agent changed | Exact writes get checkpoints; uncertain effects are reported |
Supported models and limitations
Under the interface DStudio owns three inference engines and picks the right one for the model you choose:
- ds4, antirez's native engine, for DeepSeek V4/V4.1, GLM 5.3 Flash, Laguna S 2.1 and Qwen3.8-Flash-Next;
- llama.cpp for Qwen3.6-35B-A3B and Qwen3.8-27B;
- MLX for Qwen3.6-35B-A3B on Apple Silicon.
Their sources ship inside this repository and are built or installed offline; setup never clones an engine. Agent mode can use DStudio's own agent or the third-party pi and OpenCode harnesses, with any of those engines.
Listed here means integrated, not equally tested. “All four modes” means Chat, Agent, Cowork and Design. You pick a model; DStudio picks its engine. There is no engine or branch selector.
| Model | Engine | Modes | Size and important limits |
|---|---|---|---|
| DeepSeek V4 Flash | ds4 main | All four | ~87 GB. Standard checkpoints are text-only. |
| DeepSeek V4 Flash Vision-Exp | ds4 main | All four, with images | Experimental; needs its matching vision encoder. |
| DeepSeek V4 Pro | ds4 main | All four (integrated) | About 430 GB; not validated on the reference 96 GB Mac. |
| DeepSeek V4.1 Flash | ds4 main | Experimental; qualification in progress | macOS Metal, full power. Q2 is 365.7 GB on SSD including disk-backed Engram tables; no DSpark or non-Metal qualification. |
| GLM 5.3 Flash | ds4 main | All four; images with its encoder | ~96.5 GB Q2. Full-model QA of the M2 optimization remains open. |
| Laguna S 2.1 | ds4 laguna-s2.1 |
All four, text only | Experimental, macOS Metal; needs resident weights (no forced SSD streaming). |
| Qwen3.8-Flash-Next | ds4 main | Experimental Chat, Agent, Cowork | Single-file Q2 (147.2 GB) or Q4 (177.3 GB); old base + PLE files are incompatible. Design and vision unqualified. |
| Qwen3.6-35B-A3B | llama.cpp | All four, text only | 31.8 GB Q6_K_XL. Real workflows and a Design page pass. Sessions restore from their transcript (no KV snapshot). The other 23 published GGUF quantizations (10.0–69.4 GB) are downloadable but not individually verified. |
| Qwen3.6-35B-A3B (MLX) | MLX | All four, text only | 36.7 GB MXFP8 folder; Apple Silicon with macOS 26. Real workflows and a Design page pass. Sessions restore from their transcript (no KV snapshot). 4/5/6/8-bit, BF16, MXFP4 and NVFP4 folders are downloadable but not individually verified. |
| Qwen3.8-27B | llama.cpp | All four; images in Chat, Agent and Cowork | 25.3 GB Q6_K_XL + 0.93 GB projector. Real workflows pass; Design is slow (37 min on an M2 Max with thinking on). Learn and PDF workflows unqualified. The other 24 published GGUF quantizations (7.1–55.6 GB with the projector) are downloadable but not individually verified. |
| Qwen3.8-27B (MLX) | MLX | All four, text only (images refused) | New engine combination: 4-bit, 8-bit, BF16, MXFP4, MXFP8 and NVFP4 folders (15.2–54.7 GB); Apple Silicon with macOS 26. Not yet run on real weights. |
Separate media workers provide Ideogram 4 image generation, HunyuanImage 3 image editing and MiniMax H3 video; they are not chat models. A remote OpenAI-compatible or DeepSeek API endpoint can replace local inference while every tool keeps running locally.
Memory modes. ds4 launches default to expert SSD streaming Off; Metal keeps the whole model resident when it fits and otherwise uses the engine's lazy memory-mapped path. DStudio never lowers your context to force residency. On remains an explicit option for compatible models. llama.cpp and MLX keep all weights in memory and have no expert streaming; Qwen3.8-Flash-Next keeps its backbone in RAM and reads its BF16 n-grams from SSD. Image, editing and video workers are one-shot: DStudio evacuates the chat model before loading one and restores it afterwards.
Qwen3.6 and Qwen3.8-27B on llama.cpp
Both checkpoints run on llama.cpp b11836 (f5027fb), shipped in
src/engines/llama.cpp. DStudio builds llama-server
from those sources the first time you start one of them, without the network,
and reuses the build afterwards. The weights live in the shared ds4/gguf/
folder.
DStudio starts the server, checks that it really loaded the model you chose (path, context, build and image projector) before marking it ready, and stops it when you switch models, press Stop or quit. If DStudio crashes, a small guard process stops the server too, so tens of GB are not left in memory. Chat, Agent, Cowork and Design share the loaded model: switching between them does not reload it.
- Thinking is one switch, on or off; there is no separate Max level. Agent and Cowork use Qwen's published sampling (thinking on: temperature 0.6, top_p 0.95; off: 0.7, 0.8).
- Design receives its tools as structured function calls; Qwen did not follow Design's DSML text protocol reliably.
- Not available: power throttling, expert SSD streaming, DSpark, prompt lookup, and KV disk checkpoints (the tools reach the model through DStudio's model RPC and hold no engine session to save). Agent, Cowork and Design save their transcript after every turn and restore it after a restart; the server then reads the conversation again. Chat history is saved and the running server reuses its live prompt cache.
- The 27B needs its matching F16 projector; DStudio downloads and checks both files and admits images in Chat, Agent and Cowork.
On October 3, 2026, on llama.cpp b11371, a real run through the production
host passed 6/6 on each model: an Agent turn computes a generated CSV total with real tool calls and
writes it, recalls a fact from a workspace file, Cowork writes a document,
Design saves a page with the exact requested heading, Chat answers with thinking
on and off, and a killed DStudio leaves no server behind. Retained failures
include a thinking-off arithmetic error (Qwen3.6) and the 27B Design run that
hit the test's former one-hour bound before finishing.
After the move to b11836 on October 23, Qwen3.6 passed the same six checks
again; Qwen3.8-27B has not been rerun on b11836 yet.
Qwen3.6 on MLX (Apple Silicon)
On Apple Silicon with macOS 26, Qwen3.6-35B-A3B can also run on MLX,
Apple's machine-learning framework, from the MXFP8 folder
mlx-community/Qwen3.6-35B-A3B-mxfp8. MLX ships as verified PyPI wheels
(mlx 0.32.4, mlx-lm 0.32.2) in src/engines/mlx: nothing is
compiled or fetched. The first start installs them offline into a private
Python environment (Python 3.12–3.14 must be installed, for example from
Homebrew); a later Python upgrade that removes the old version triggers a
reinstall instead of a broken launch.
Download the weights from Settings → Models (Qwen3.6-35B-A3B · MLX
MXFP8, 36.7 GB) or with ./download-model.sh qwen36-mlx; each of the 20 files
is checked against its pinned SHA-256 and transfers resume after Stop. If you
already have this folder, link it as ds4/mlx/Qwen3.6-35B-A3B-mxfp8; DStudio
checks it and never copies or moves it.
It behaves like the llama.cpp models: one server owned by DStudio, shared by all four modes, ready only when it reports exactly the folder you chose, stopped on Stop, model switch, quit or crash. Two small versioned patches make the MLX server serve only that model and report its reasoning in the field DStudio reads (patch notes). MLX has no expert streaming and no disk KV cache. It is not available on Intel Macs, older macOS, Linux or Windows; use the GGUF there.
The October 3 real run passed 6/6. Three earlier failed runs are kept with their fixes (a folder not recognized as a model, an HTTP/1.0 readiness reply, and a 512-token default reply limit plus a renamed reasoning field) in tests/README.md.
Every Qwen3.6 and Qwen3.8-27B quantization
Besides the defaults above, every standard quantization the publishers released
can be downloaded from Settings → Models or with ./download-model.sh:
all 24 unsloth GGUFs of Qwen3.6-35B-A3B and all 25 of Qwen3.8-27B on llama.cpp
(UD-IQ1 … UD-Q8_K_XL, Q4_0/Q4_1/Q8_0, MXFP4_MOE for 3.6, and BF16), and the
standard mlx-community MLX folders: 4-bit, 5-bit, 6-bit, 8-bit, BF16, MXFP4,
MXFP8 and NVFP4 for Qwen3.6, and 4-bit, 8-bit, BF16, MXFP4, MXFP8 and NVFP4 for
Qwen3.8-27B. Modified repositories (abliterated, uncensored, fine-tunes,
pruned/REAP, MTP or other draft builds, DWQ, OptiQ and similar) are not offered.
- Pinned like the defaults. One catalog,
scripts/qwen-variants.json, records each variant's repository revision and every file's size and SHA-256 (63 variants, about 1.4 TB in total). It ships with DStudio and is never fetched; a maintainer regenerates it withscripts/update-qwen-variants.py, which reads only Hugging Face metadata at explicit revisions. Each file is resumable and verified before it is published; nothing existing is overwritten. - What each variant needs. Every 27B GGUF downloads with the same pinned F16
projector, which images on llama.cpp require. The split BF16 GGUFs are two
files in
ds4/gguf/; only the first appears in the model picker, and both must be present. MLX folders live inds4/mlx/and are Apple Silicon only. - 27B on MLX is text only. MLX loads its language model without the vision tower; DStudio refuses image attachments with that model rather than dropping them.
- Verification. Q6_K_XL (both models) and MXFP8 (Qwen3.6 on MLX) remain the qualified selections. The other variants share the engine, tokenizer, chat template and tool format of a checked variant but use other quantization kernels (and the split BF16 another loading path and about 69 GB of memory): they are downloadable but not individually verified. Five representative real-weight checks are planned (UD-Q4_K_M, UD-IQ4_XS and MXFP4_MOE GGUFs of Qwen3.6, Qwen3.6 MLX NVFP4 and Qwen3.8-27B MLX 4-bit); they have not run yet; see the remaining work.
The existing ids (qwen36-q6, qwen27-q6, qwen36-mlx), file names and
partial downloads are unchanged.
Qwen3.8-Flash-Next on ds4 main
Flash Next shares ds4 main (pinned at
890898c);
there is no separate engine to install. Download the single-file Q2
(147.2 GB) or Q4 (177.3 GB): each includes the original BF16 n-grams read
from SSD, with the backbone resident in Metal memory. The older base + PLE
files are not supported, recognized or converted. It exposes
experimental Chat, Agent and Cowork with its native tool format; Design and
vision remain unavailable. The Q4 baseline answered 75/100 corpus questions and
8/8 long-context cases; wrong answers stay in the denominator. See the
migration report and the
Qwen checkpoint.
DeepSeek Vision-Exp, GLM 5.3 and Laguna
- DeepSeek V4 Flash Vision-Exp is a separate language checkpoint, not an
encoder for the older 0731 GGUF. Choose Vision-Exp · IQ2_XXS (~86.7 GB plus
its 0.93 GB encoder), mixed Q2/Q4 (~97.6 GB) or MXFP4 (~156 GB). DStudio
passes
--visionautomatically; Chat sends image blocks directly, Agent and Cowork use ds4'sview_image, Design inspects pixels natively. Its own DSpark support file isds4f-vision-dspark; if model, DSpark and context exceed the estimated Metal budget, DStudio explains the risk and asks before launch. - GLM 5.3 Flash runs on ds4 main with the same binaries and model store.
The optional native encoder (
glm53-vision, ~1.13 GB) enables images in all modes.--poweris dropped (unsupported by GLM). With SSD streaming on, DStudio uses the full-layer prefill path and a 32 GB expert cache; the macOS build includes the M2 Max decode patch, whose full-model QA is still open. - Laguna S 2.1 runs on ds4's pinned
laguna-s2.1branch in./ds4-laguna-s21, sharing./ds4/gguf. The ~68 GB Q4_K_M download has Stop/Resume and Delete partial. It is macOS Metal-only, text-only and needs full residency; image drops are rejected rather than routed elsewhere.
Downloading models
Every download is real, large and resumable, and every model lands in the
shared ./ds4/gguf/ store (the MLX folder in ./ds4/mlx/). Settings → Models
shows engine preparation, transfer and verification separately; Stop keeps
partial data for Resume, and a download never changes your selected model.
From the project root:
./download-model.sh --help
./download-model.sh ds4f-q2        # DeepSeek V4 Flash
./download-model.sh ds4f-vision-q2 # DeepSeek V4 Flash Vision-Exp + encoder
./download-model.sh ds41f-q2       # DeepSeek V4.1 Flash 1017 Q2 (needs hf with Xet)
./download-model.sh ds41f-1017-vision # its 1017 vision encoder
./download-model.sh glm53-q2       # GLM 5.3 Flash (glm53-vision for its encoder)
./download-model.sh laguna-q4      # Laguna S 2.1
./download-model.sh qwen38-q2      # Qwen3.8-Flash-Next Q2 (qwen38-q4k for Q4)
./download-model.sh qwen36-q6      # Qwen3.6 Q6_K_XL, 31.8 GB, llama.cpp
./download-model.sh qwen27-q6      # Qwen3.8-27B + projector, 26.2 GB, llama.cpp
./download-model.sh qwen36-mlx     # Qwen3.6 MXFP8 folder, 36.7 GB, MLX
./download-model.sh qwen36-q4_k_m  # any other pinned Qwen quantization, e.g. UD-Q4_K_M
./download-model.sh qwen27-mlx-4bit # Qwen3.8-27B 4-bit MLX folder (text only)
./download-model.sh --list-qwen    # every pinned Qwen variant, engine and size
DeepSeek V4, GLM and Laguna show a visible <model>.gguf.part while a transfer
is incomplete. The pinned Qwen downloads verify size and SHA-256 per file before
the model becomes selectable. Hugging Face/Xet transfers (Qwen3.8, V4.1) keep
partial data in the Hugging Face cache until they are verified in full.
Linux and Windows (prepared, not tested)
On Linux and Windows DStudio builds llama.cpp the way Ollama does: one server
plus a loadable module per backend. Every CPU variant is built and llama.cpp
picks the best one for the processor; CUDA, ROCm and Vulkan modules are added
when their toolkit is installed (DSTUDIO_LLAMA_BACKENDS can request or limit
them). Layers go to the GPU memory that is actually free, the rest to the CPU;
your context setting is never lowered. On Windows the server runs inside a Job
Object, so it stops with DStudio. This code is cross-compiled for Linux and
Windows, and the same dynamic build layout was built and run for real on macOS
with a correct Qwen3.6 answer, but it has not been run on Linux, Windows,
CUDA, ROCm or Vulkan. ds4 itself must be built for your platform; MLX and the
pi/OpenCode harnesses are not available on Windows.
Harnesses: every engine with every agent loop
A harness is the agent loop around a model: it decides which tool to call,
runs it and feeds the result back. DStudio's own harnesses (Agent, Cowork,
Design, GSA and RSA) live in src/harness/, next to pinned
source snapshots of pi, OpenCode and pi-ds4.
Choose Settings → Harnesses → Agent harness: DStudio, pi or OpenCode. The next Agent launch keeps the same model, engine, context and workspace; only the loop changes. The transcript, diff cards, Stop, Task Graph receipts and the saved conversation work as before. pi comes in two forms, chosen from the model: pi-ds4 when ds4 serves it (DeepSeek, GLM, Qwen Next, Laguna) and plain pi with llama.cpp, MLX or a remote endpoint.
| Harness | DeepSeek and other ds4 models | Qwen3.6 / 27B (llama.cpp) | Qwen3.6 (MLX) | Remote endpoint |
|---|---|---|---|---|
| DStudio Agent, Cowork, Design | yes | yes | yes | yes |
| pi | yes, through pi-ds4 | yes | yes | yes (not run live) |
| OpenCode | yes | yes | yes | yes (not run live) |
- Install. Settings → Harnesses → Install (or
python3 scripts/install-harness.py --root <install root> --harness pi|opencode). The sources ship with DStudio; their JavaScript dependencies do not. This one explicit step downloads them, pinned by each project's lockfile (Node and npm required; OpenCode also uses a private Bun 1.3.14), applies DStudio's versioned patches and builds in a private folder. About 3 minutes for pi and 6 for OpenCode on an M2 Max. Launching afterwards is offline. - How it connects. A small bridge speaks DStudio's runtime protocol and
gives the harness one loopback model endpoint protected by a per-process
token. Behind it: the host's model RPC for llama.cpp, MLX and remote models
(the harness never sees an API key), or a
ds4-serverthe bridge starts for ds4 models. The endpoint applies DStudio's model identity, sampling and thinking choice. - Confinement. pi always loads a guard that blocks file tools outside the workspace (real paths, so a symlink cannot escape); OpenCode runs with external directories denied and a patch that makes the workspace itself, not its enclosing git repository, the boundary. Shell commands are not sandboxed in any harness, including DStudio's own.
- Streaming. Text, reasoning and tool calls stream as they are generated: a file being written appears in the transcript and in Open IDE while the model writes it, in every harness and on every engine. The executed call is still the validated complete one.
- Offline and private. pi runs with
--offlineand no telemetry; OpenCode runs with its model-catalog fetch, auto-update, sharing, LSP downloads and external skills disabled, in a private config directory. - Limits. pi and OpenCode replace Agent mode only; Cowork and Design keep DStudio's tools. Mid-turn steering is not forwarded to them, their sessions live in memory while the Agent runs (DStudio still saves the transcript), and very long sessions can exceed the model RPC's 32,768-token request validation.
Results, process ownership, patches and the full list of what was not run: docs/HARNESSES.md.
Latest measured results
These are separate experiments, not one product score. All charts use Matplotlib; scripts and reviewed JSON are committed next to the reports. Private documents and raw user data are not published. Every result names the engine and date it was measured on.
50 diverse tasks: DStudio, Pi and OpenCode
Measured on September 4, 2026 on DeepSeek V4 Flash (ds4), with pi 0.84.1 and
OpenCode 1.18.18 as standalone CLIs against ds4-server, before they were
integrated as DStudio harnesses. Ten task families × five different fixtures;
a task passed only when a real tool completed, the required answer followed, an
independent file or Python check passed and nothing outside the declared scope
changed. Same 86.72 GB model, 8,192-token context, power 70, thinking off, SSD
streaming off.
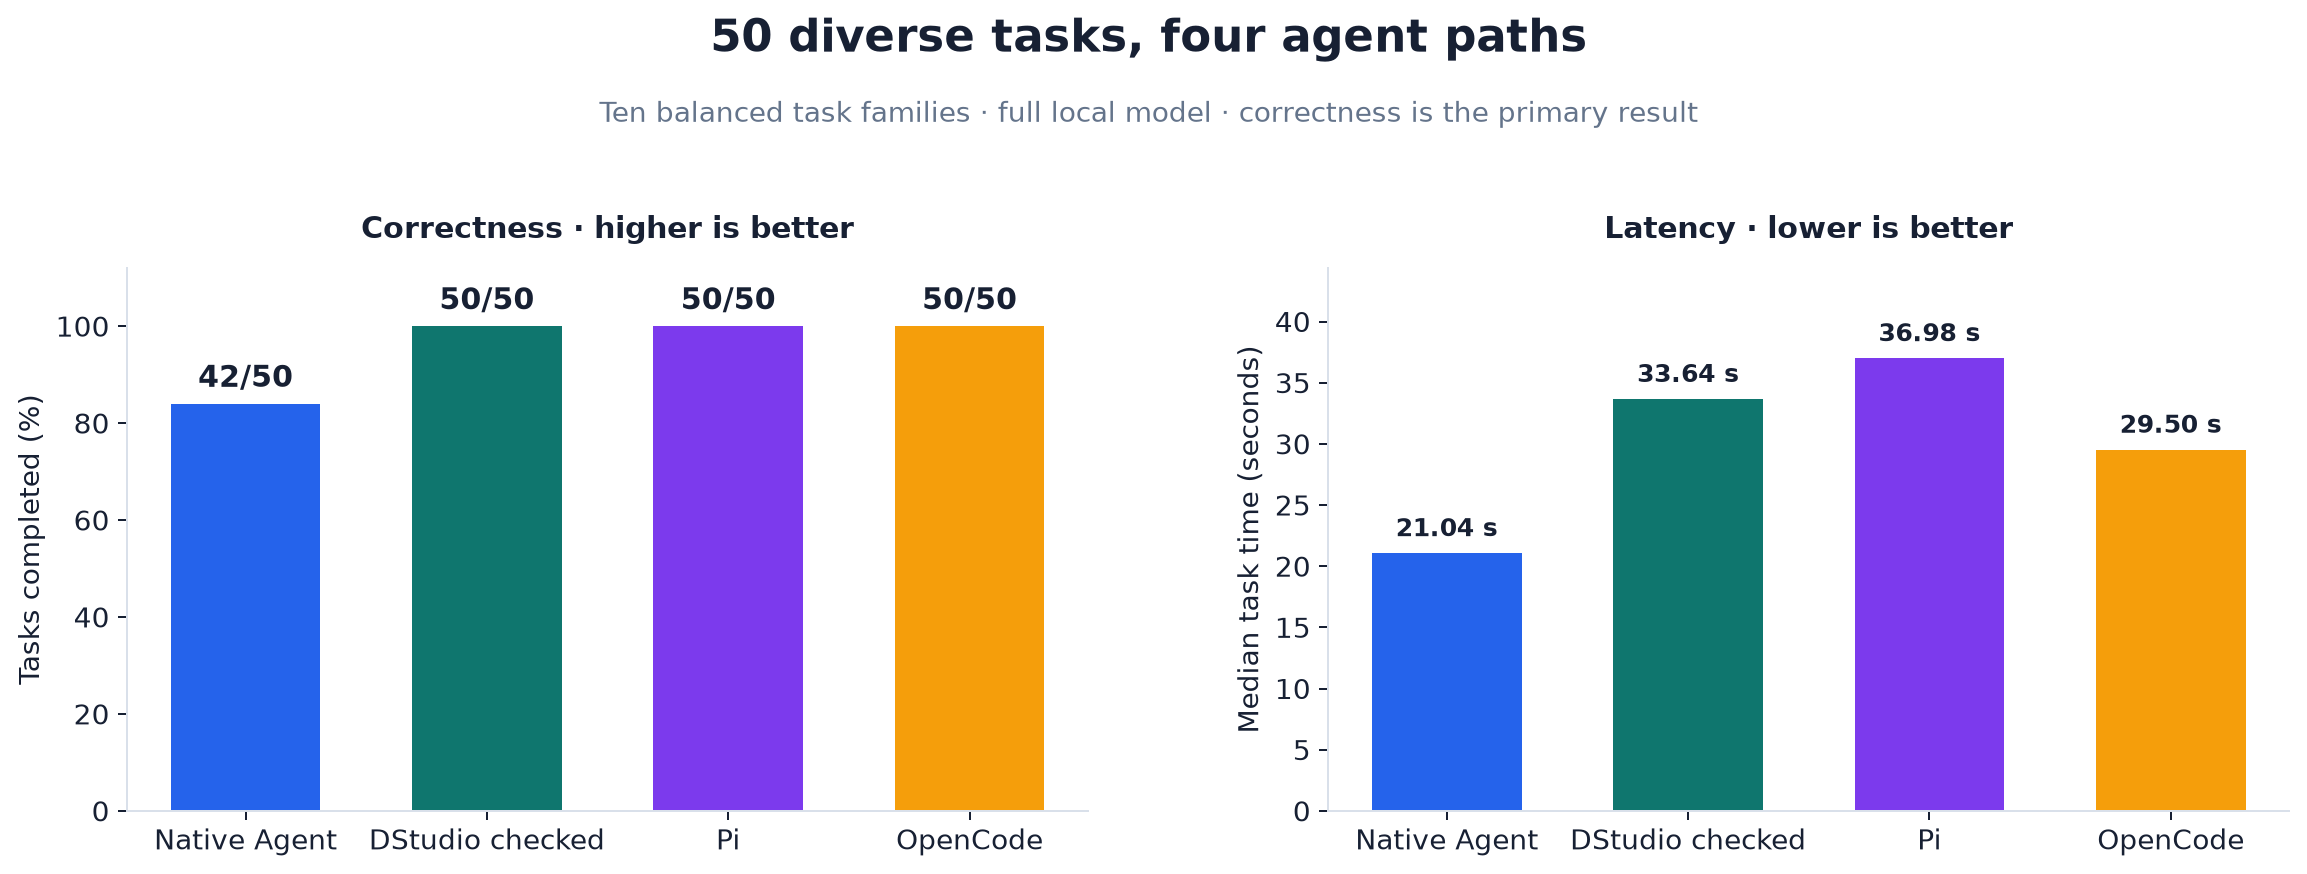
| Agent path | Tasks completed | Median task time | Mean tool calls |
|---|---|---|---|
| Native Agent baseline | 42/50 | 21.04 s | 2.22 |
| DStudio Agent | 50/50 | 33.64 s | 2.60 |
| Pi 0.84.1 | 50/50 | 36.98 s | 3.14 |
| OpenCode 1.18.18 | 50/50 | 29.50 s | 2.76 |
The honest result is a three-way correctness tie between DStudio, Pi and OpenCode. DStudio improves the Native baseline by eight tasks (all five code repairs, one cross-file calculation, one JSON edit, one constrained diagnosis), is faster than Pi and 4.15 seconds slower than OpenCode at the median.
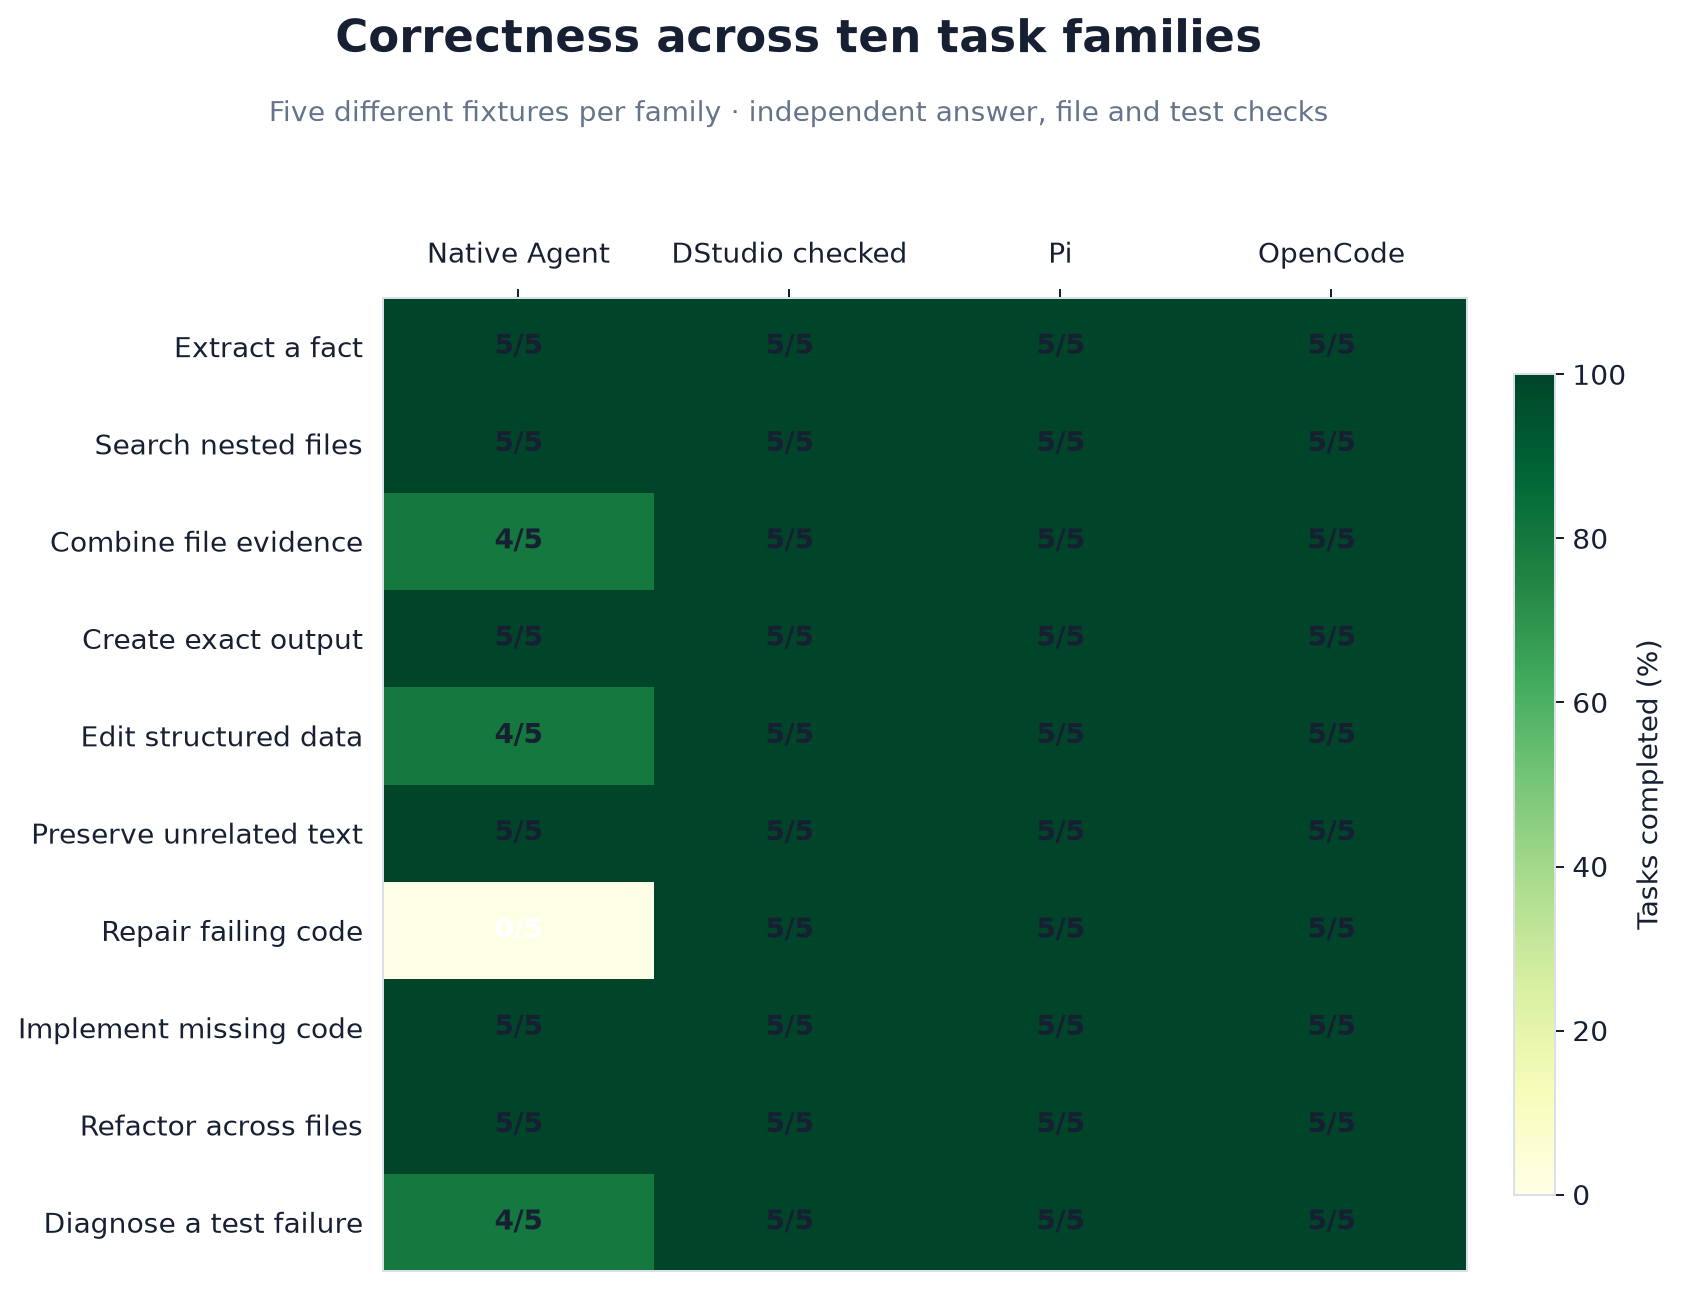
The suite does not cover network/browser work, multimodal judgment, very long autonomous tasks, parallel agents or interrupted token streams. It is one M2 Max/96 GB sample, not a guarantee for other prompts, versions or computers; the publication gate rejects a result if the checked path loses any task Native completes.
Method, raw results and reproduction
Every variant started with a fresh session. Native and checked DStudio
alternated against one loaded ds4-agent-jsonl; Pi and OpenCode alternated
against one loaded ds4-server whose verifier rejected every model id except
ds4. Pi and OpenCode had read, write/edit and shell tools; plugins, external
skills, LSP, formatters, MCPs, sharing and catalog updates were disabled, with a
1,024-token response limit. The DStudio phase took 56 min 11 s and the
Pi/OpenCode phase 1 h 2 min 36 s.
DSTUDIO_RELIABILITY_CASES=50 make test-task-graph-reliability-real
DSTUDIO_RELIABILITY_CASES=50 make test-task-graph-cli-competitors-real
node extension/task-graph/bench/publish-reliability.mjs \
  tests/.artifacts/task-graph-reliability-real/result.json \
  extension/task-graph/bench/results/2026-09-04-m2-max-diverse-reliability-no-ssd.json
node extension/task-graph/bench/publish-cli-comparison.mjs \
  tests/.artifacts/task-graph-cli-competitors-real/result.json \
  extension/task-graph/bench/results/2026-09-04-m2-max-diverse-reliability-no-ssd.json \
  extension/task-graph/bench/results/2026-09-04-m2-max-diverse-agent-comparison-no-ssd.json
python3 extension/task-graph/bench/plot-cli-comparison.py
Engines and harnesses on real weights (October 3, 2026)
Focused functional checks through the production host on an M2 Max, with generated tasks and independent checks; summarized in Current status and detailed in docs/HARNESSES.md. They show that each engine/harness path works end to end; they are not a quality or speed comparison between engines.
Qwen3.8-27B: 100 checked tasks (retired engine)
Measured on September 9, 2026 on the retired q36 engine, not on llama.cpp; it has not been rerun there. 61 of 100 tasks passed: 31 answers failed their checks and eight long requests ended in an engine error or timeout. Instruction following and language tasks worked well; arithmetic, debugging patches and long contexts need more work.
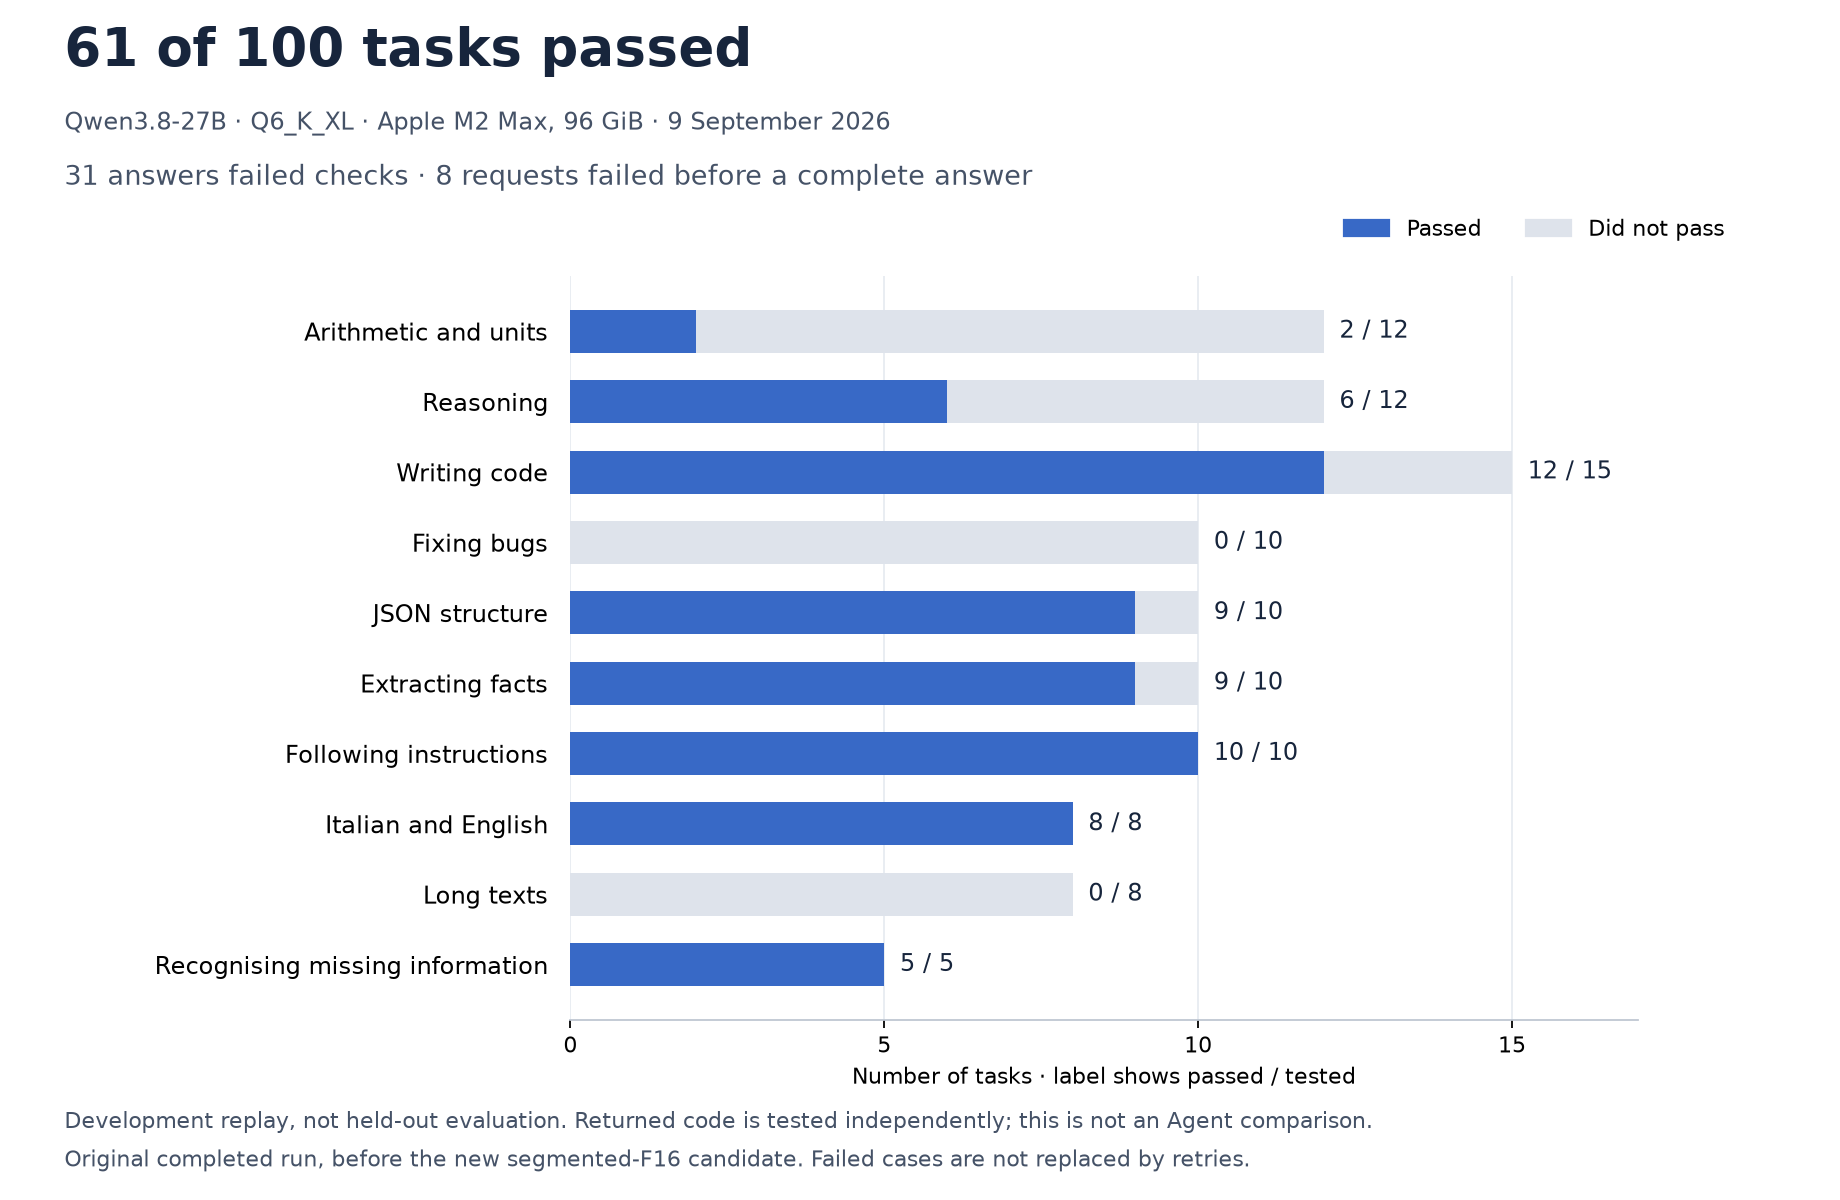
A development replay, not a held-out score. Method, data and Matplotlib script.
Web evidence: can it find the detail and read the chart?
In eight small controlled questions with a real local model, correct evidence increased from 3/8 to 8/8: details near the end of long pages, current vs obsolete information and two simple graphics. It was not consistently faster. Development checks of page reading, not a Search ranking.
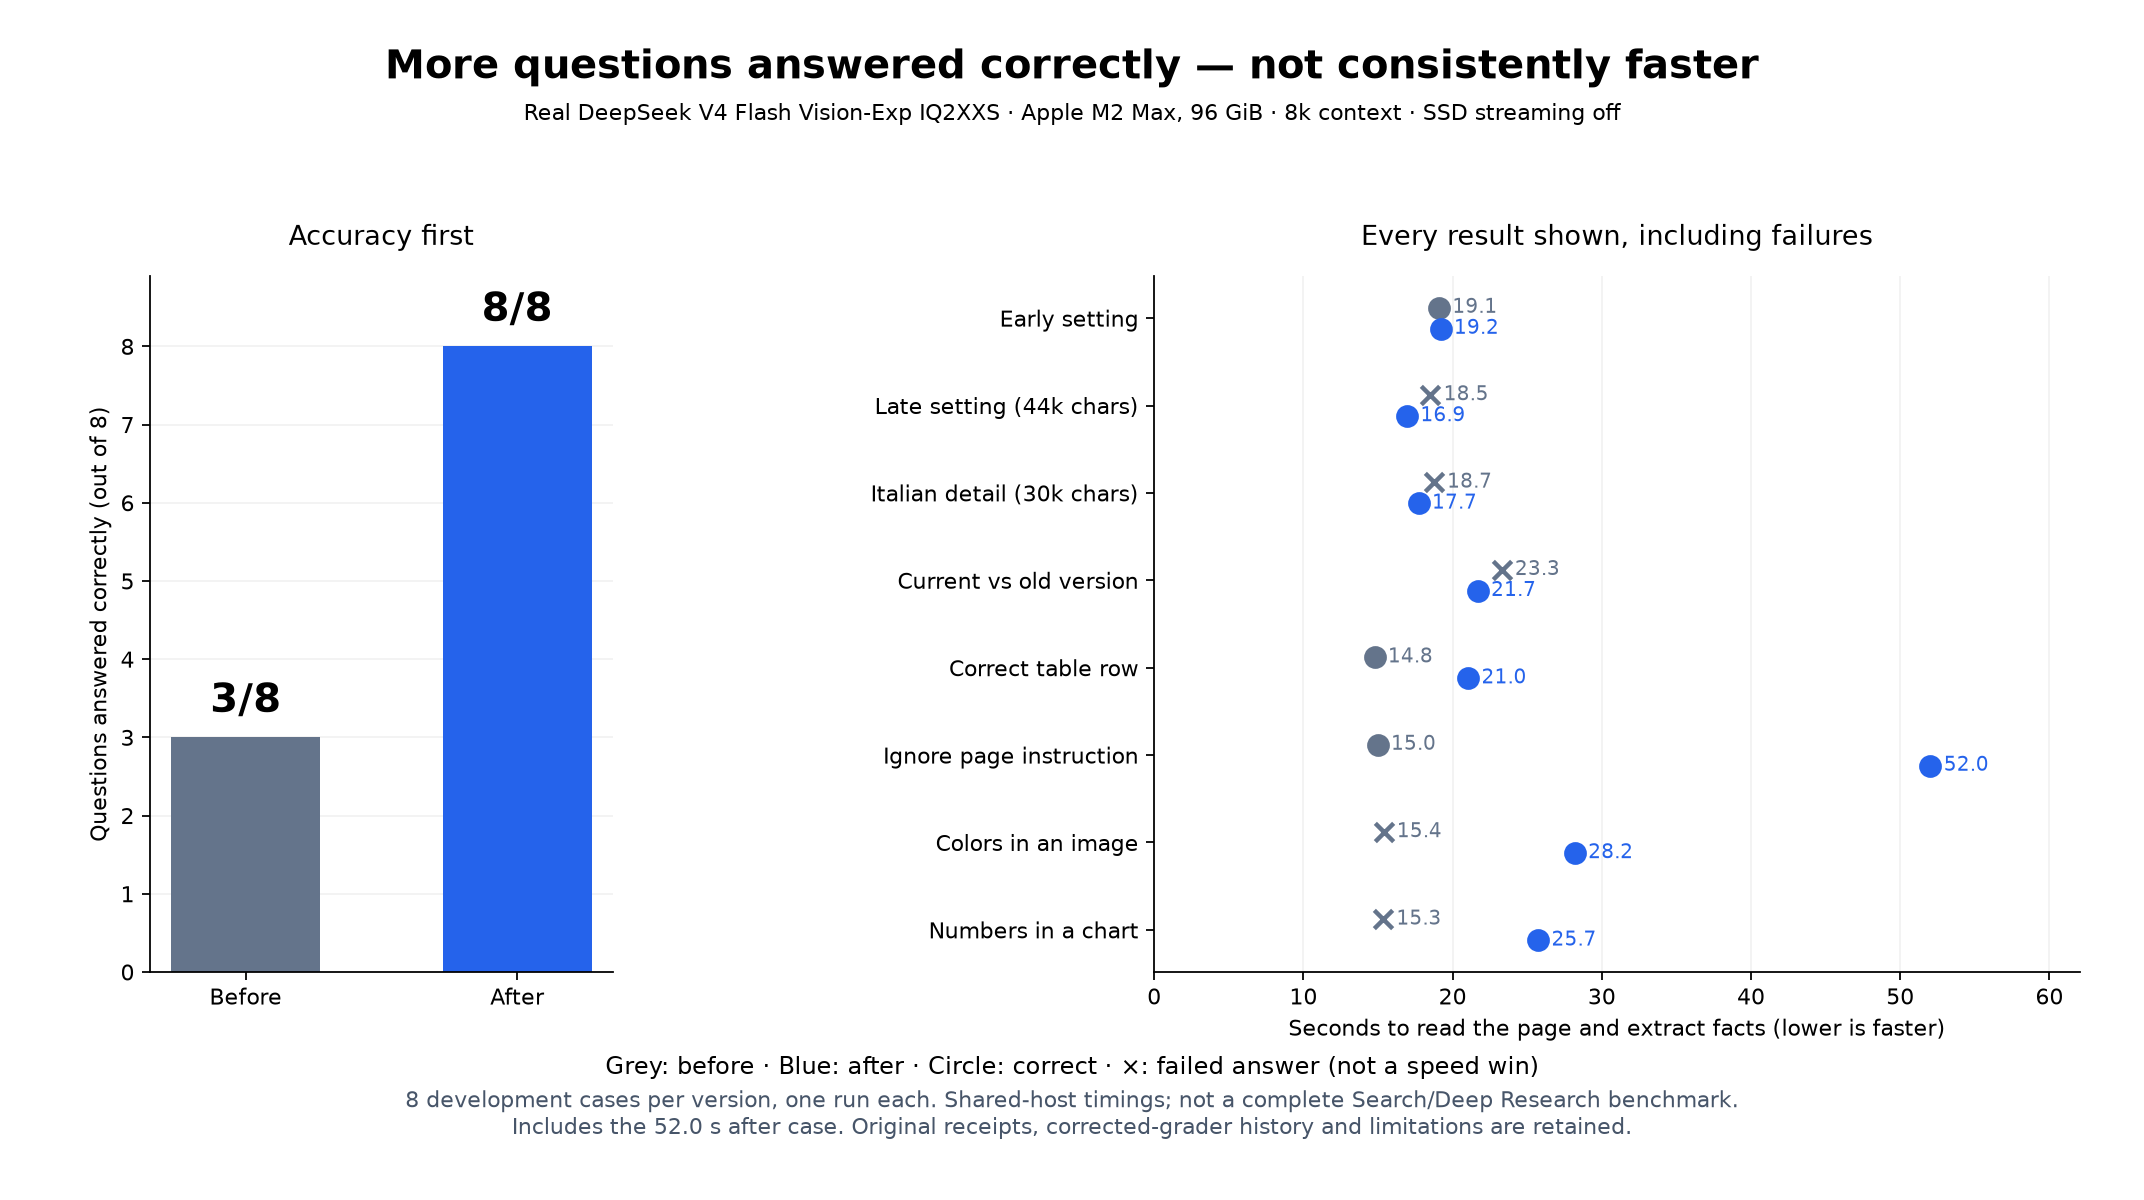
Questions, answers, settings and original failures.
Complete research: are the final answers correct and concise?
The latest real public-web run meets the checked requirements on 4/4 questions, versus 2/4 before (two Search, two Deep Research). It is not faster: the two Research answers took about 312 and 293 seconds, versus 247 and 255 for the previous failed answers. All three rejected update attempts stay in the chart. Four known development questions, not a held-out score.
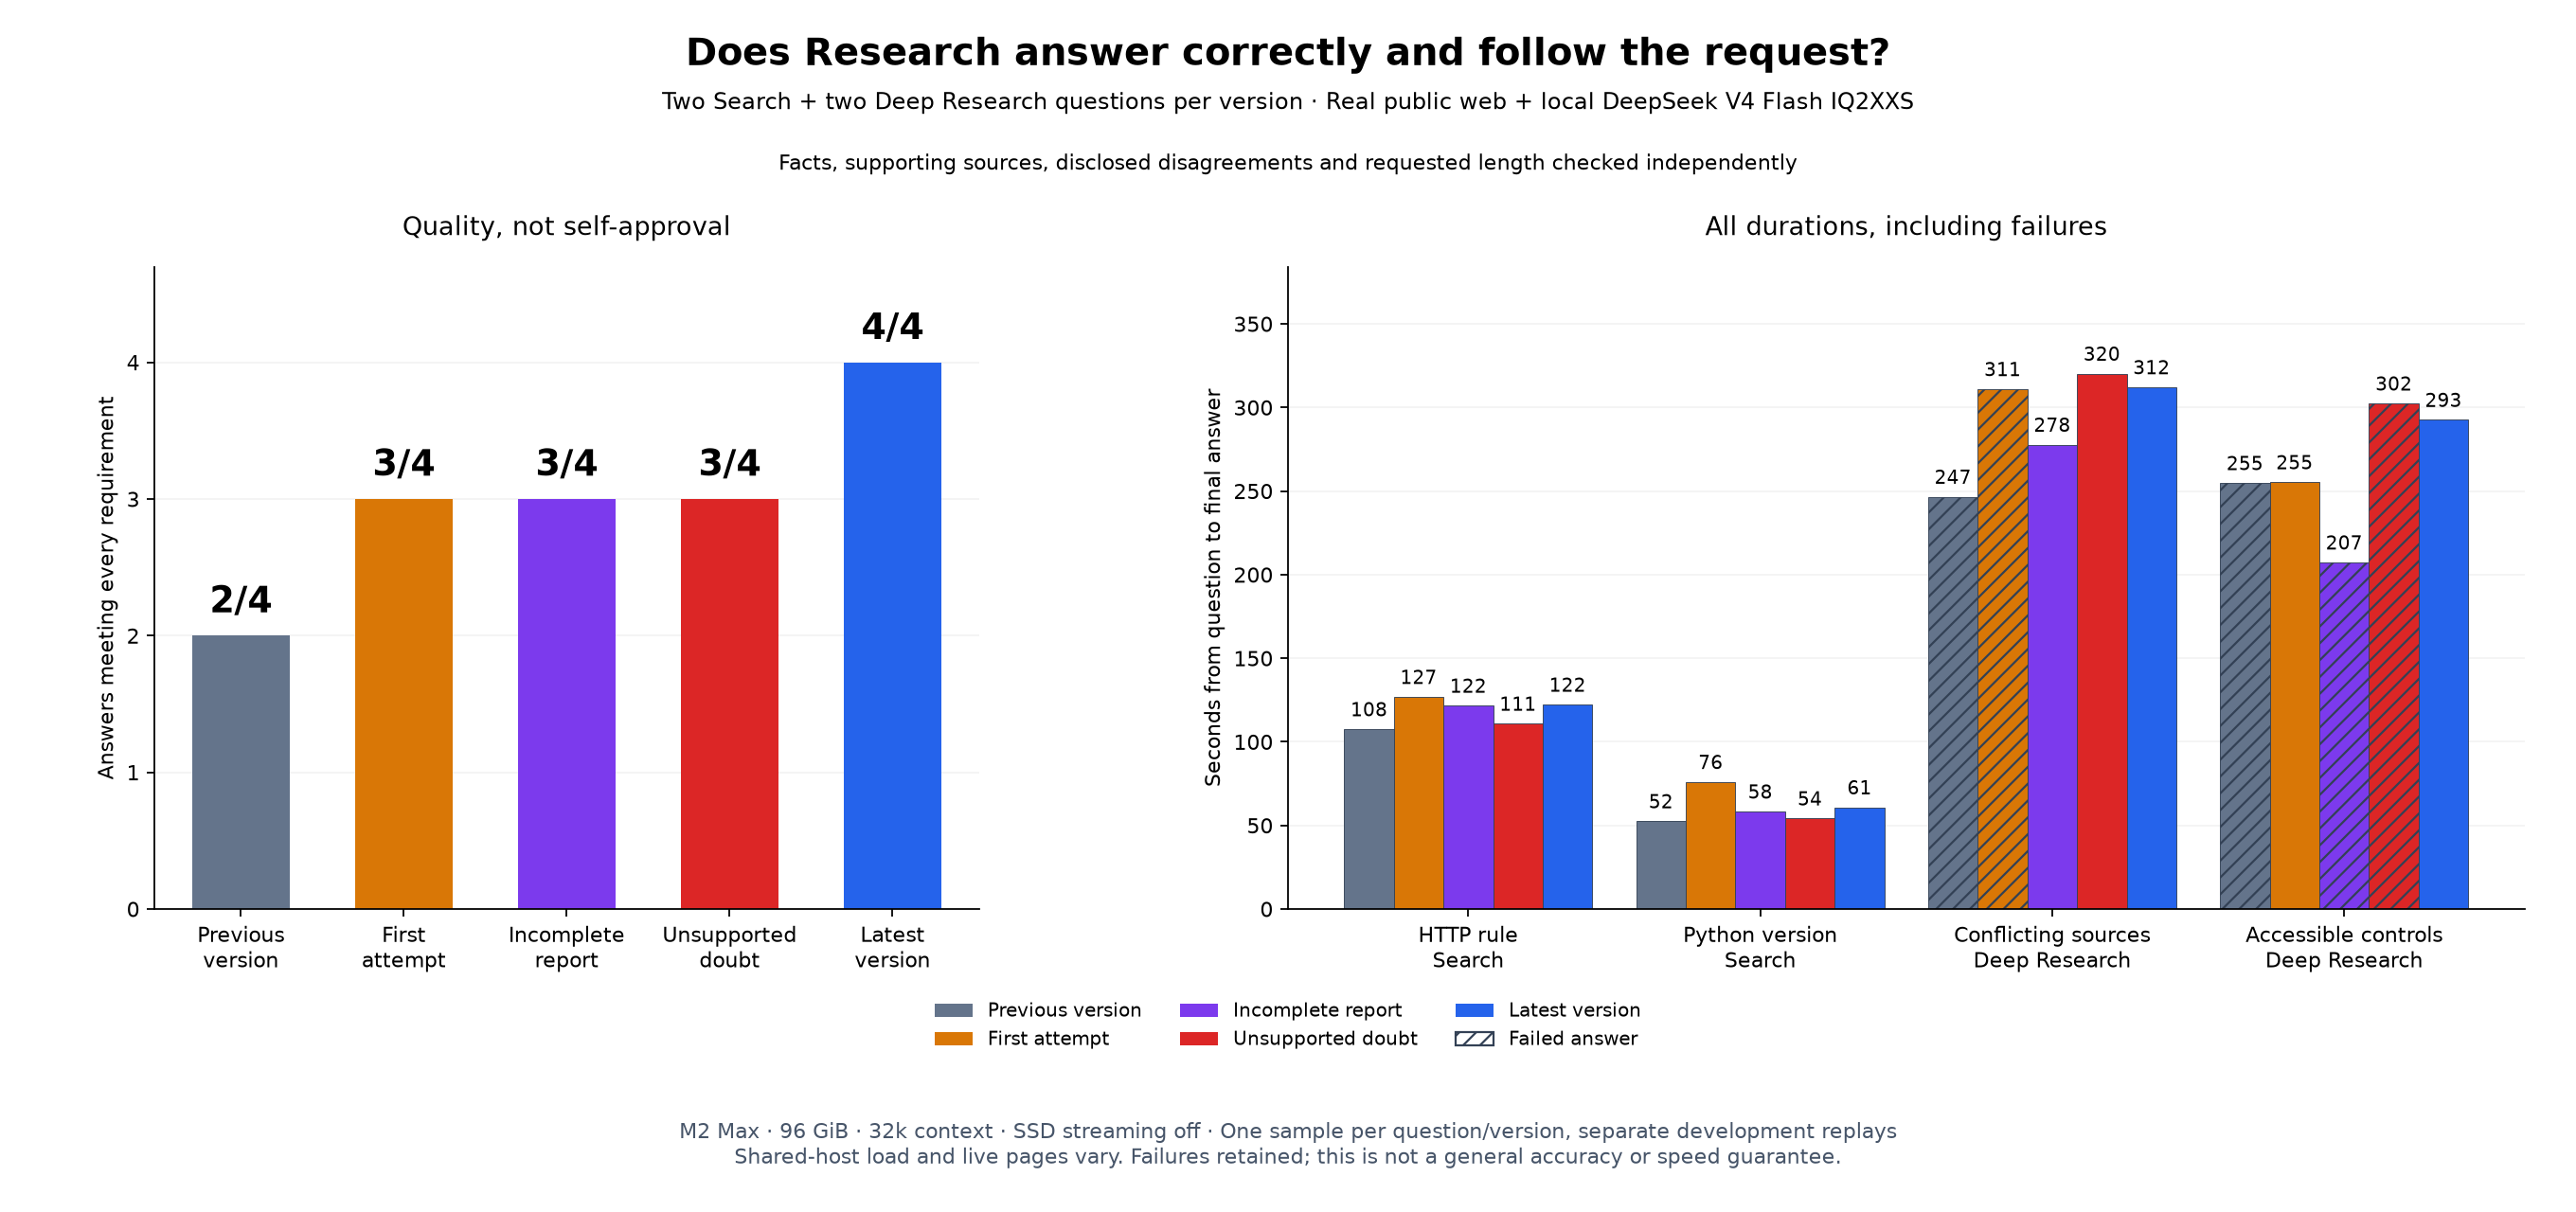
Prompts, reviews, timings and Matplotlib script.
Real tasks against OpenWork and OpenDesign
On the same local model, DStudio and OpenWork both fixed the code and produced the correct document plan; DStudio took 110 vs 212 seconds for code and 109 vs 170 seconds for the plan. DStudio's website passed the tested controls; OpenDesign reached the 15-minute limit with broken controls. DStudio's original output had misaligned radio buttons: a functional pass is not a visual-quality pass. Three small development tasks, not a ranking.
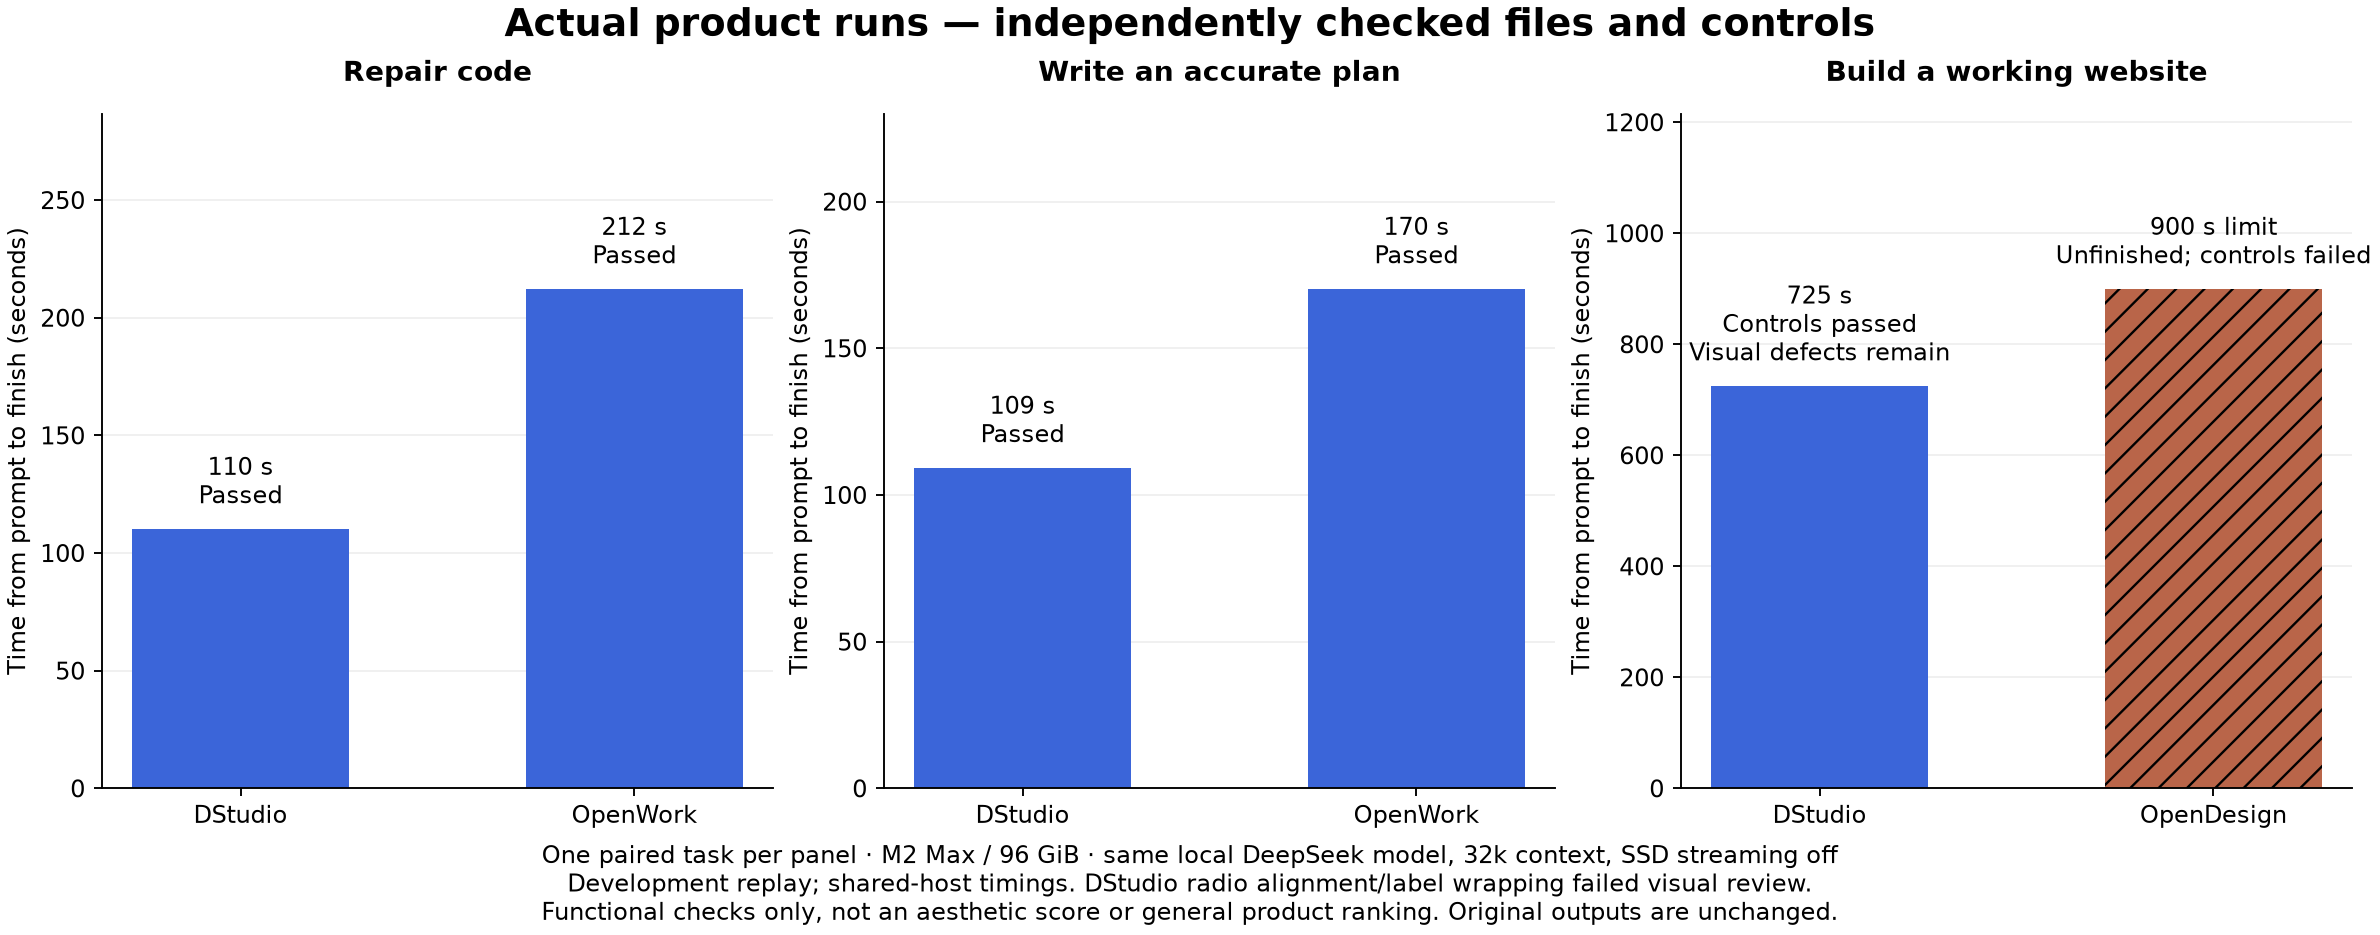
The page below was regenerated by the real ds4 Design agent from an empty workspace with the same brief and no human HTML repairs; its controls pass independent Chromium/WebKit tests, but the agent hit the 15-minute limit while iterating on its own tests, so the replay is not counted as a completed run.
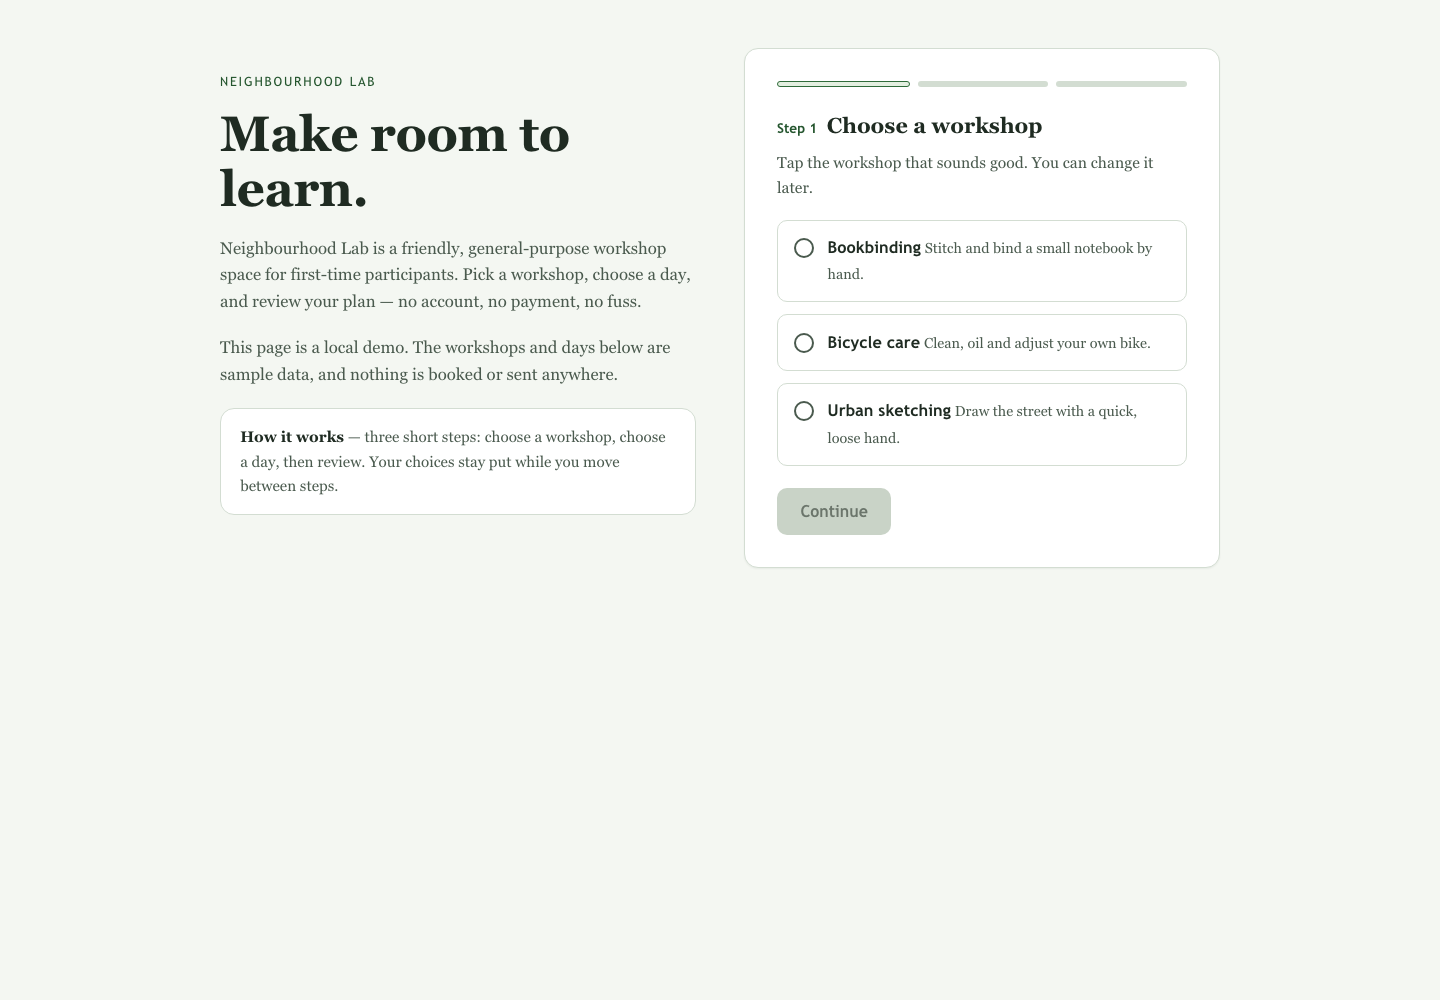
Phone screenshot · HTML · Prompts, screenshots and limitations.
Engine update: reading prompts and writing responses
DeepSeek in RAM stays near 21 tokens/s writing these responses; GLM with SSD streaming varies around 5–9 tokens/s. No clear speed gain in this shared-host run. All 36 measured answers pass, but four auxiliary checks fail: 44/48.
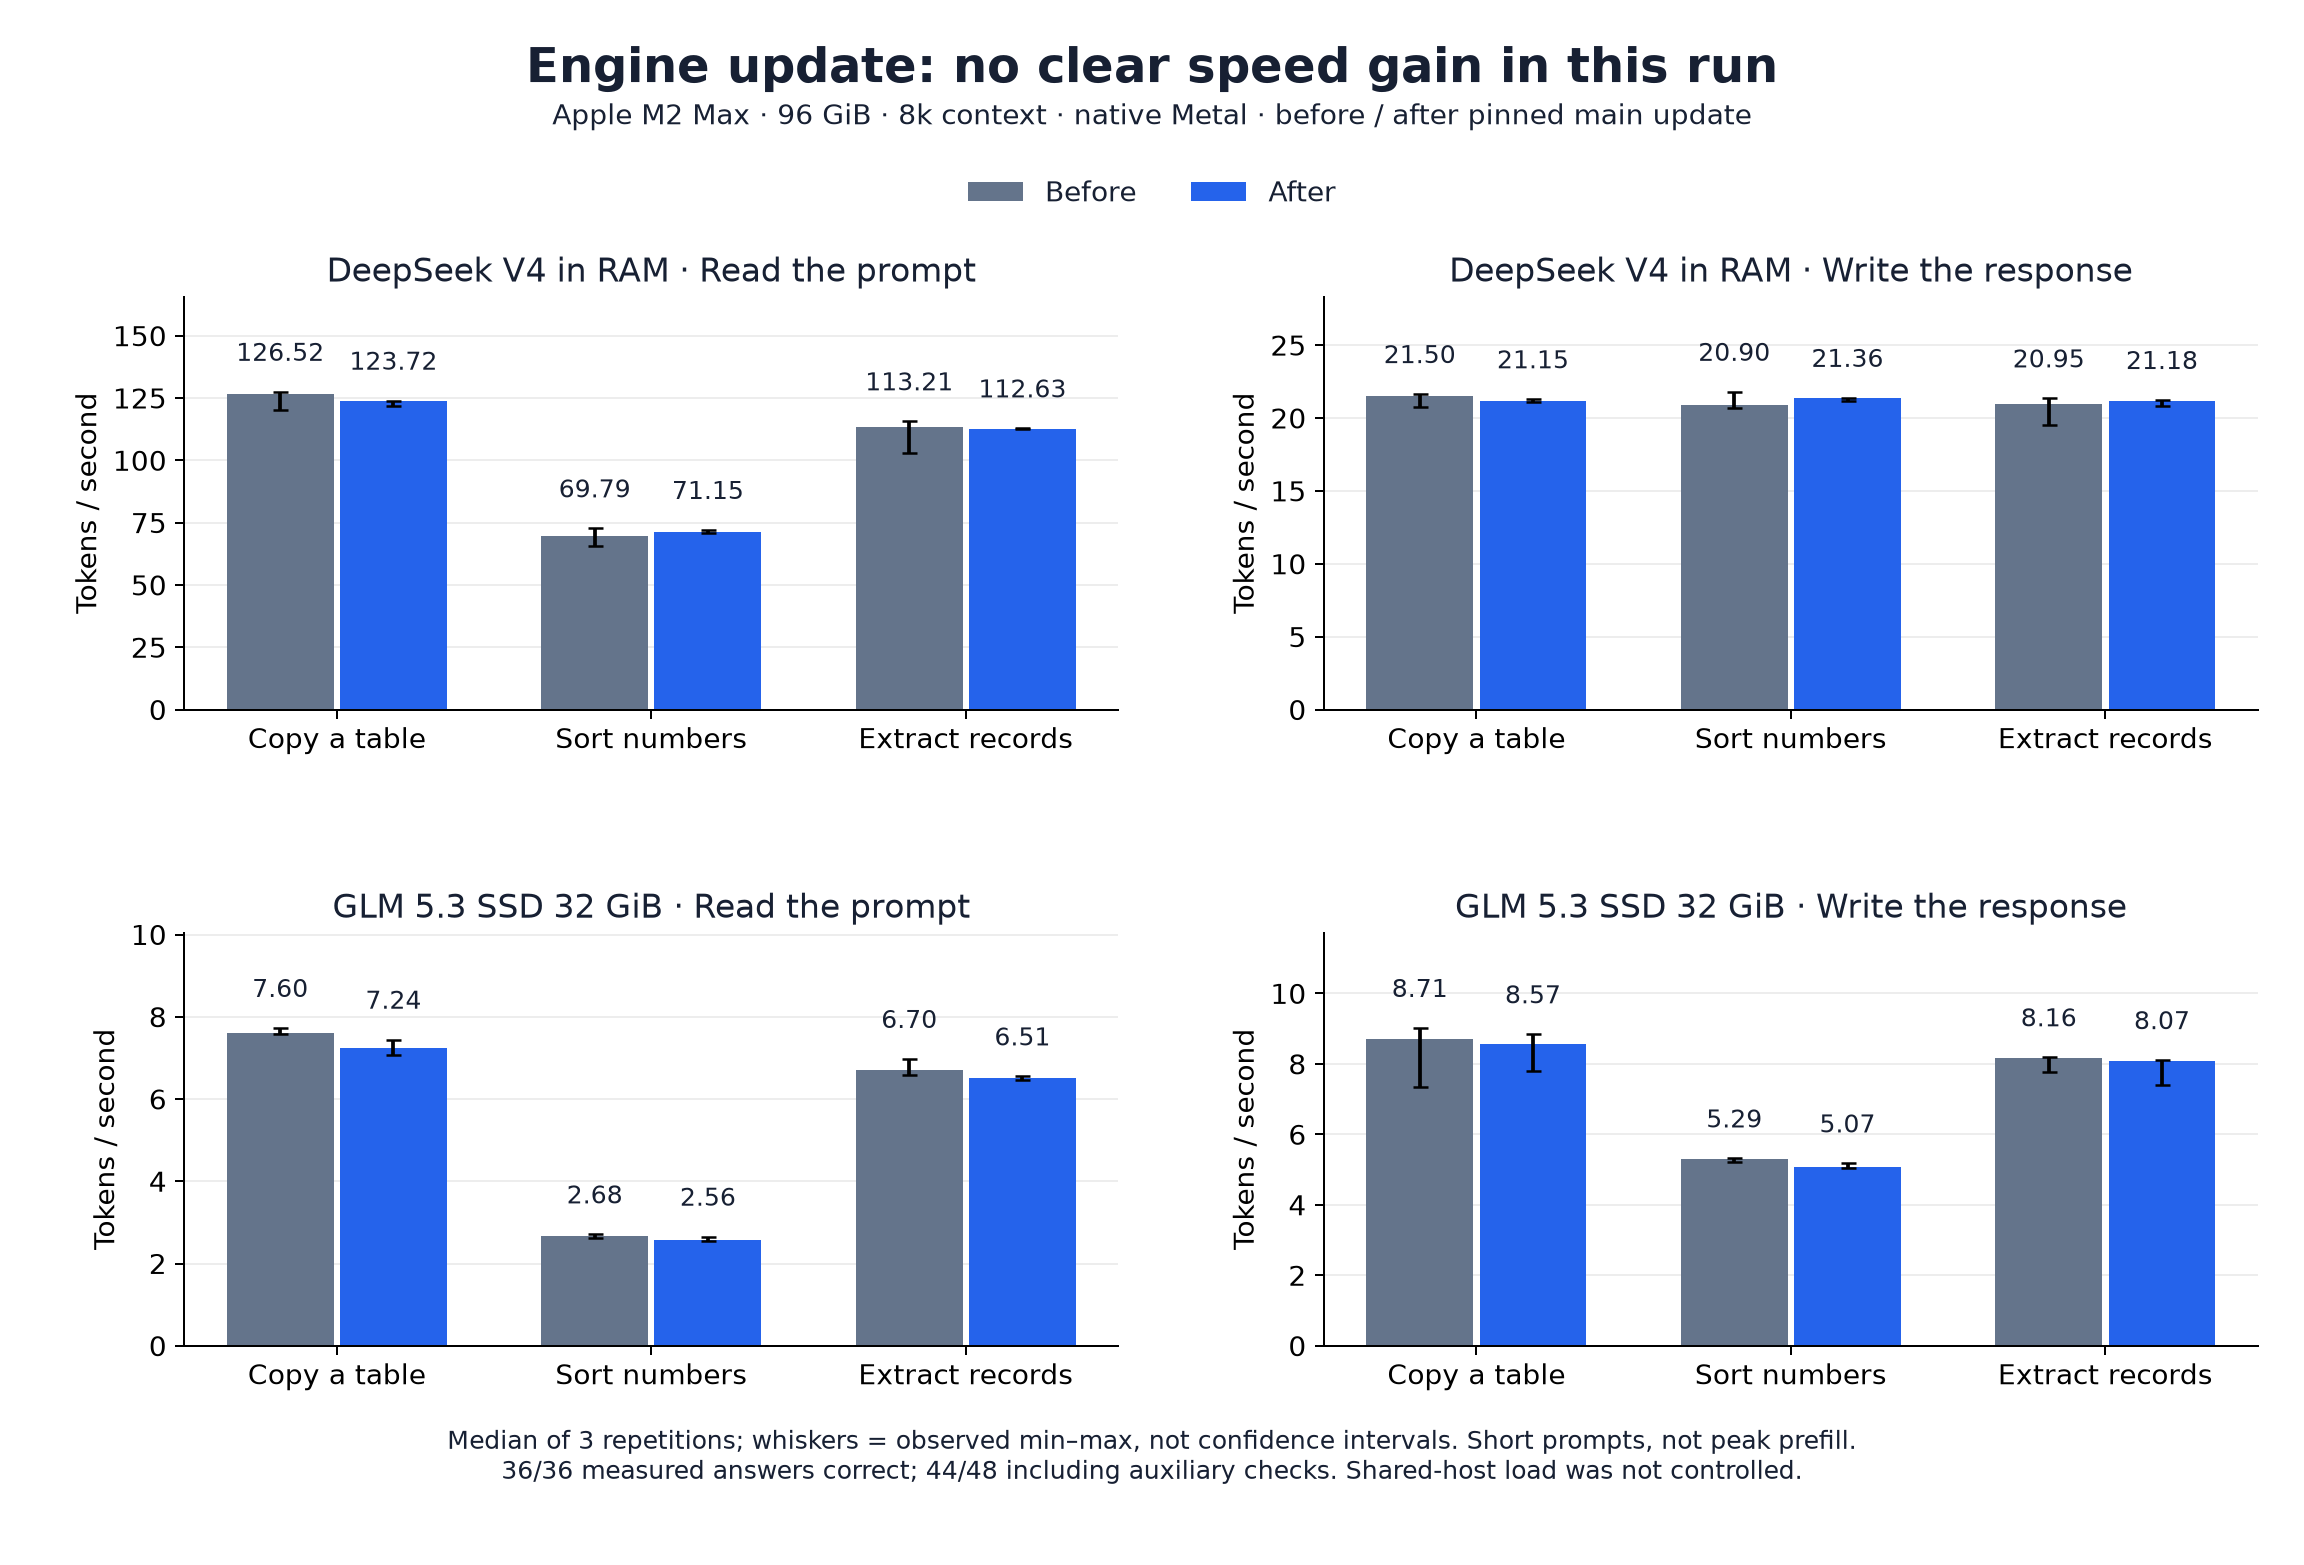
Settings, limitations and measurements.
PDF library: can it find the right source?
Across 78 PDFs and 84 questions, the expected page and quote were found in 75/84 cases; citation highlight coordinates worked in 50/75 attempts. This tests search and source matching, not answer correctness.
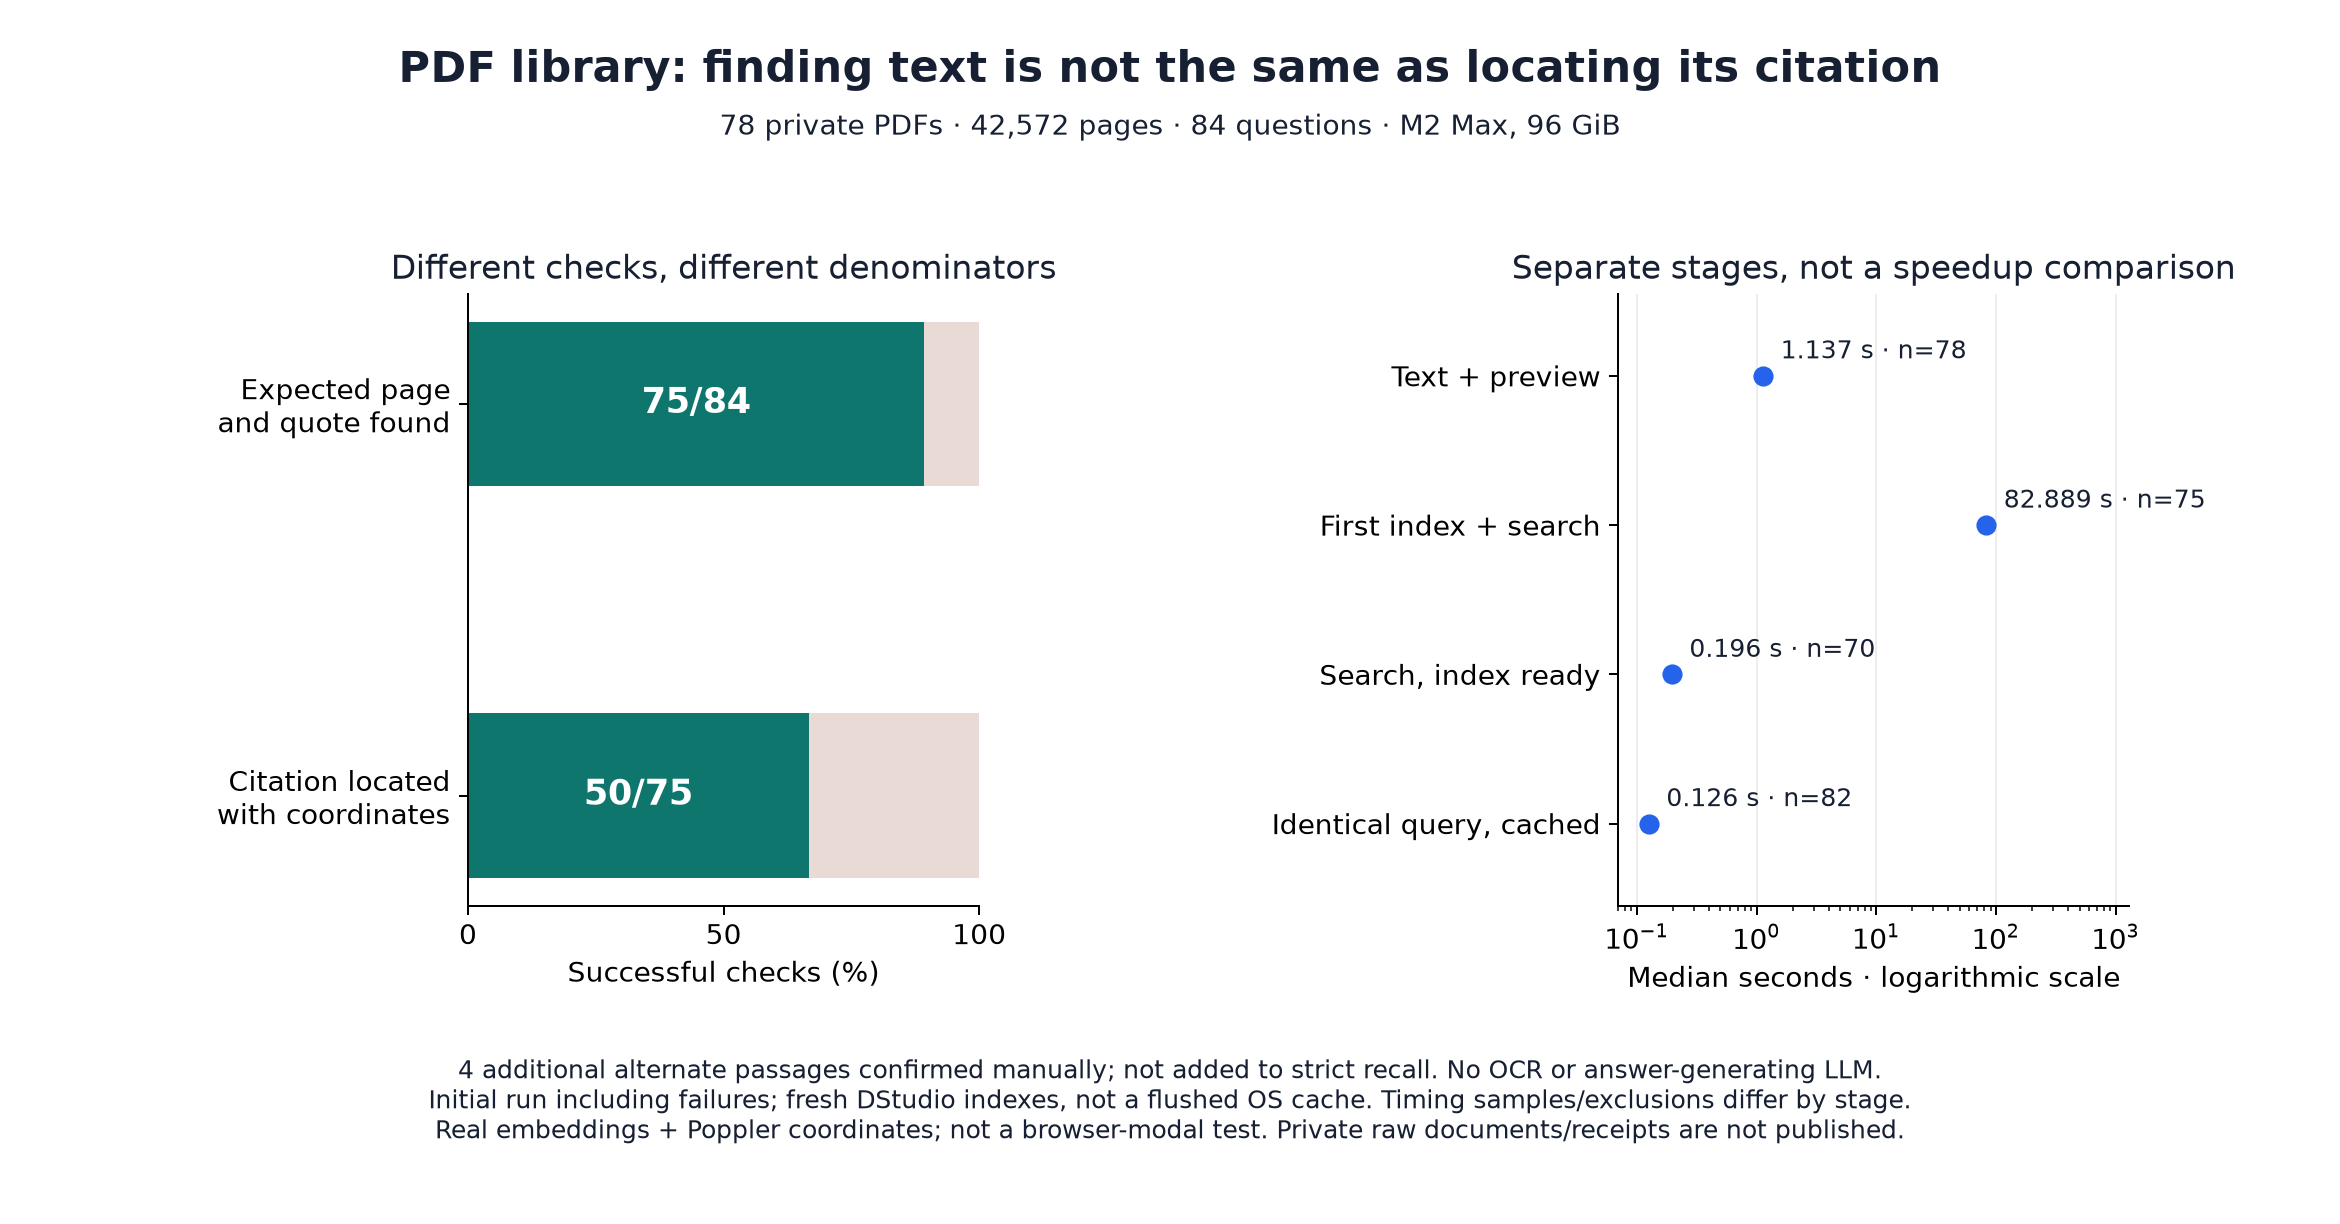
Method, anonymous aggregates and timing exclusions.
Design: does it deliver a working project?
In the initial three-brief comparison both versions delivered 2/3 projects and 1/3 passed every independent browser check. No overall win yet; functional checks are not an aesthetic score.
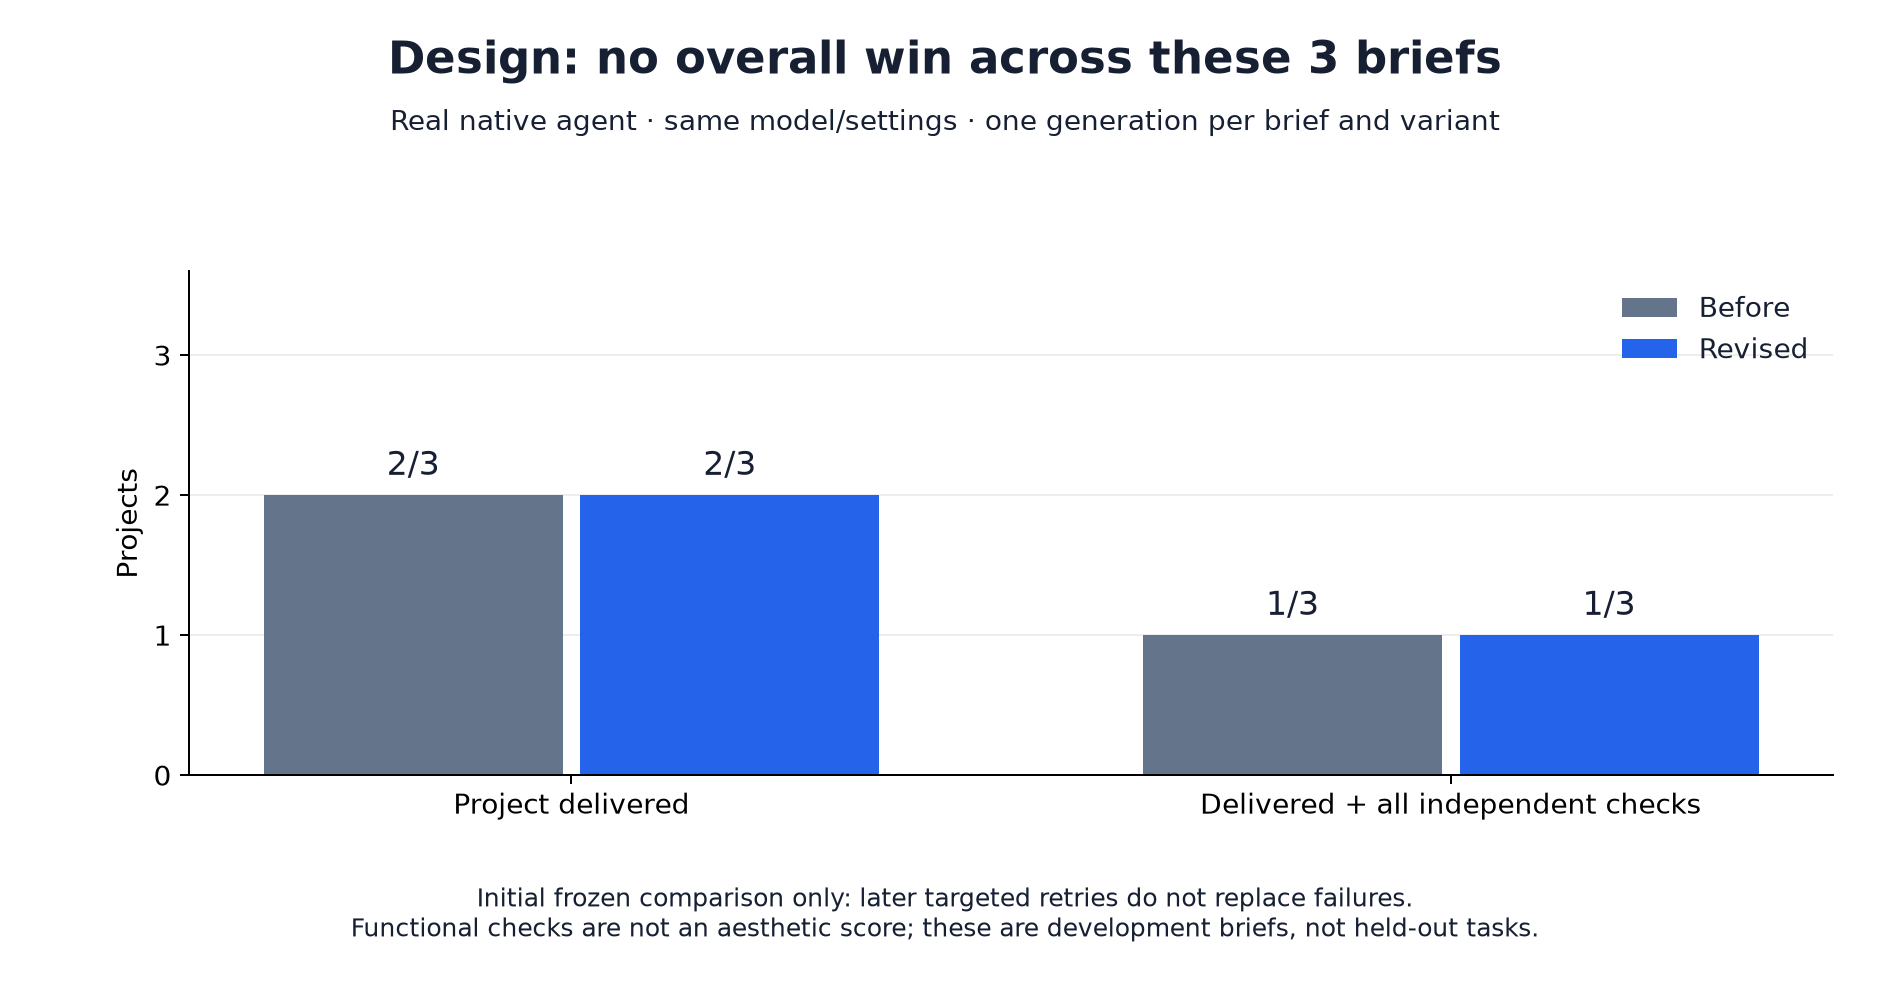
Failures, review and later targeted checks.
Regenerate these charts without running a model:
python3 tests/support/publish_benchmark_charts.py  # Requires Matplotlib
python3 extension/search/bench/plot-results.py
Requirements
DStudio removes product friction, not physics: the local models are large.
- OS. macOS on Apple Silicon is the primary tested target (DStudio.app).
Linux builds a
dstudiobinary with WebKitGTK/GTK3 (webkit2gtk-4.1);make windowsbuilds a portable Windows x64 folder. Linux and Windows are much less exercised. - Memory and disk. Choose a model that fits: DeepSeek V4 Flash ~87 GB on disk and ~96–128 GB RAM; Pro ~430 GB and ~512 GB RAM; Qwen3.6 ~32–37 GB; the 27B ~26 GB. If nothing fits, the DeepSeek API backend can provide inference while workspace tools stay local.
- Build tools. Apple Command Line Tools (
xcode-select --install) or another C compiler,makeand Python 3. First-run setup verifies, copies and builds the pinned engine sources included in this repository; Git is used only for local patch application, never to fetch an engine. - Per engine. CMake for llama.cpp (found on
PATH, Homebrew, CMake.app orC:\Program Files\CMake). For MLX: macOS 26 or later on Apple Silicon and Python 3.12–3.14. For Qwen3.8 and DeepSeek V4.1 downloads: the Hugging FacehfCLI with Xet. - Harnesses (optional). Node and npm, plus a network connection once for the pinned JavaScript dependencies.
- Features. Poppler for PDF features;
ffmpeg/ffprobeand at least 145 GiB free for MiniMax H3 video (Apple Silicon only); Node and Playwright only for browser tests.
Engine pins: ds4 main 890898c, Laguna 448d569, llama.cpp b11836
(f5027fb), mlx 0.32.4 / mlx-lm 0.32.2, with per-file provenance in
docs/BUNDLED_ENGINES.md. DeepSeek V4.1 status:
update checkpoint.
Windows notes
For normal use, run DStudio.exe from the folder make windows produces. Keep
DStudio.exe, ds4-server.exe, ds4-agent-jsonl.exe, ds4-cowork.exe,
ds4-agent-jsonl.ver, ds4-design.exe and the packaged src/harness/cowork
helper together. Cowork also needs a reachable Python 3.
To build DStudio or use Agent/Cowork/Design from a LAN client with your own ds4
checkout, install the Microsoft Edge WebView2 Runtime, MSYS2 build tools
(pacman -S make patch gcc) and Visual Studio Build Tools or clang-cl.
msys-gcc_s-seh-1.dll was not found means the MSYS2 runtime is missing: install
MSYS2 in C:\msys64 (DStudio adds it to PATH); do not copy MSYS/Cygwin DLLs
next to the ds4 binaries. Windows installation of the current source tree has
not been rerun.
Development and tests
make run        # build + start on http://127.0.0.1:5500
make check-fast # deterministic unit, HTTP, UI and fixture checks; no model
make check      # check-fast plus explicitly configured real-model suites
make dist-macos VERSION=x.y.z  # bundle smoke + upstream admission + release zip/checksum
make run PORT=8080 DS4_DIR=/path/to/ds4 or ./dstudio [web_port] [ds4_dir]
set the port and engine folder. DS4UI_PAGE_FROM_DISK=1 ./dstudio serves
web/index.html from disk for hot editing; DS4UI_NO_WINDOW=1 runs headless.
Useful focused targets (see tests/README.md for all of them):
| Area | Targets |
|---|---|
| Bundled sources and installers | test-engine-sources test-engine-pins test-llama-install-profile test-mlx-install-unit |
| Resident llama.cpp/MLX owner | test-resident-unit test-resident-guard |
| Harnesses | test-harness-bridge test-harness-patches |
| Downloads | test-qwen27-download-host test-mlx-download-host |
| Task Graph | test-task-graph-unit test-task-graph-http test-task-graph-bench-validate |
| Cowork / Design / PDF | test-cowork, test-design-runtime, test-pdf-complete test-pdf-evidence |
| macOS packaging | test-macos-bundle, test-first-launch-e2e (offline, isolated) |
Real installation and inference checks
The important distinction: can a clean installation build the included engine sources without the network, and does a real loaded model complete checked tasks? These targets use real weights, run one at a time and refuse to start when the test engine port is busy:
make test-setup-live            # build bundled main, Laguna and llama.cpp in an empty directory
make test-mlx-install           # real offline MLX install with outbound network denied
make test-llama-resident-live DSTUDIO_LLAMA_MODELS=qwen36   # or qwen27, qwen36mlx
make test-harness-live          # pi/OpenCode x models (DSTUDIO_HARNESSES, DSTUDIO_HARNESS_MODELS)
make test-first-launch-e2e      # fresh headless .app + real WebKit clicks, offline engine builds
make test-inference-live        # real DeepSeek/Laguna weights with checked answers
They retain requests, answers, failures and timings; wrong answers, missing weights and interrupted output are not passes. They are acceptance checks, not proof that every inference is correct. Browser tests with a simulated model are labelled as such.
Earlier receipts, measured on September 5, 2026 (M2 Max / 96 GB):
| What was checked | DeepSeek Flash | Laguna S 2.1 | Qwen3.8-Flash-Next (former fork) |
|---|---|---|---|
| Fresh source install, real build and startup | Passed | Passed | Passed |
| Checked answers and protocol behavior | 11/12 | 10/12 | 12/12 |
DeepSeek missed one strict output-format check; Laguna missed that check and returned one wrong value. Results and limits. The headless first-launch check also loaded every chat model installed on the test Mac at 8k context and checked exact answers and a rendered Chat reply; results and model list.
Network (LAN)
DStudio is localhost-only by default. The web/LAN port can be changed in
Settings → Network → DStudio port. To use it from a phone, tablet or another
computer on the same Wi-Fi, choose Settings → Network access → Enable on the
LAN; the app shows the address to open, e.g. http://192.168.1.207:5500.
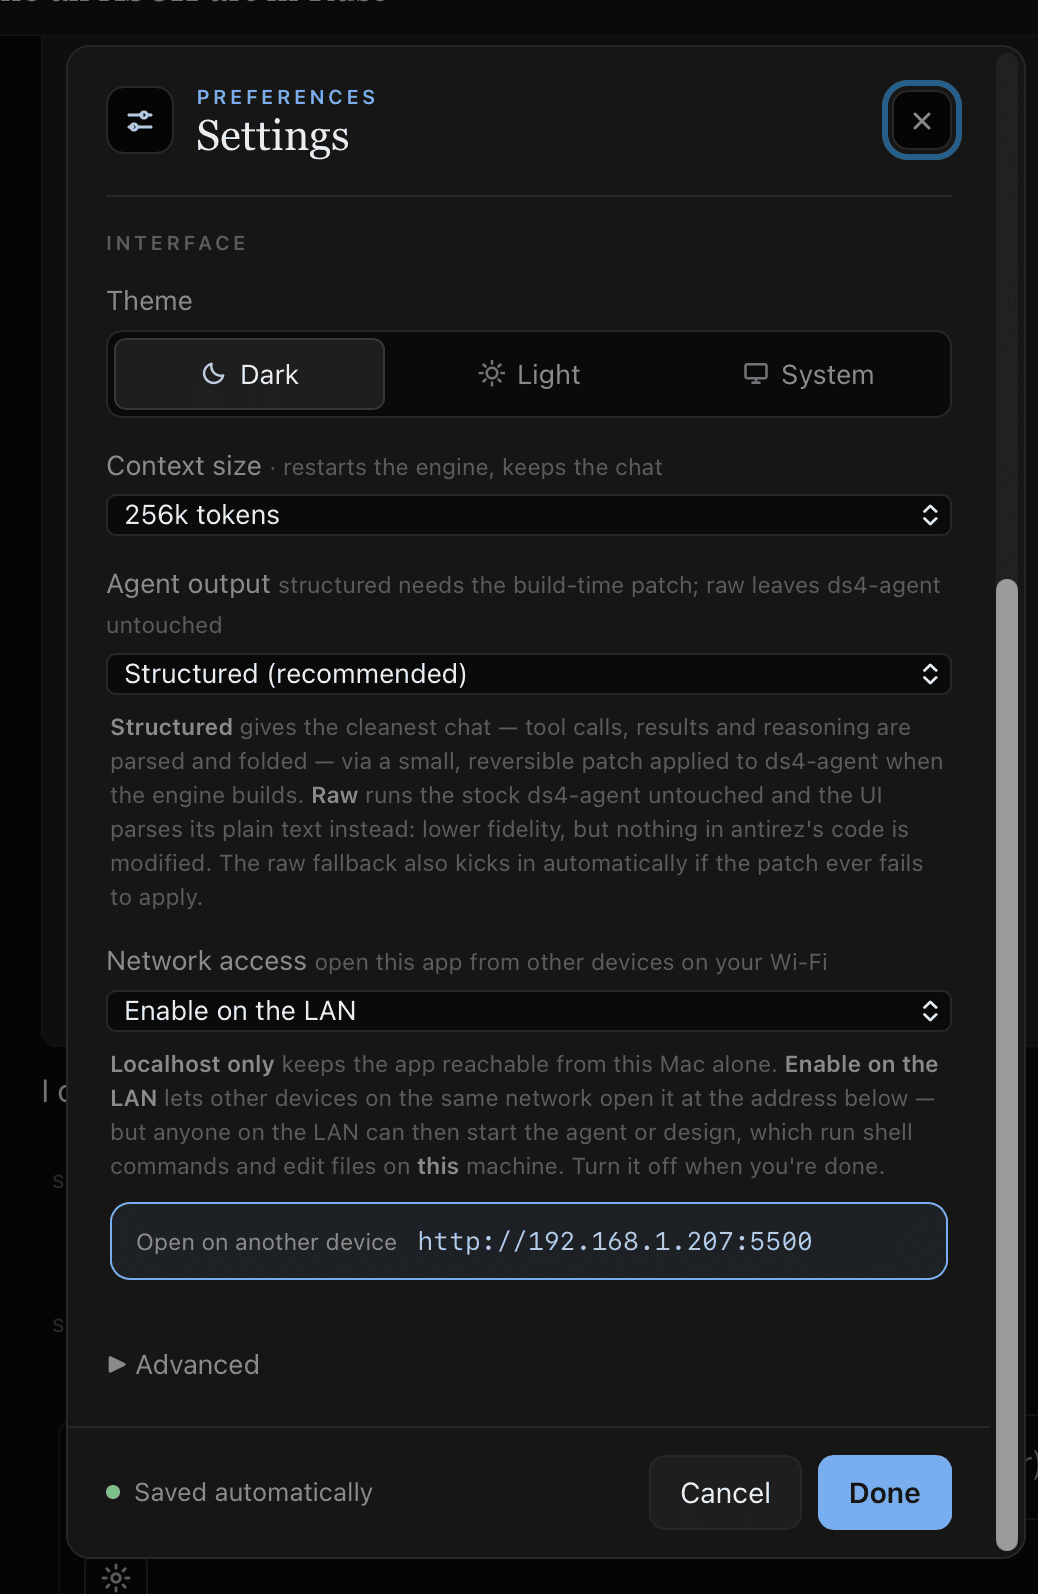
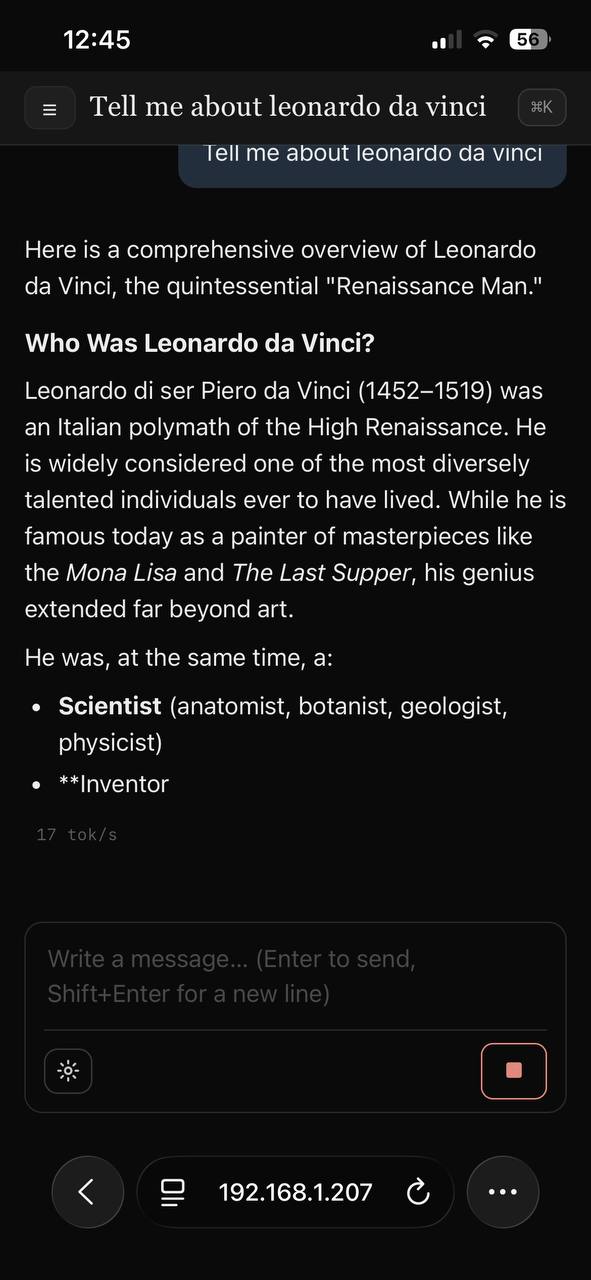
One toggle in Settings (left) → open the address on your phone (right). The model streams over the network, with no app to install on the device.
DStudio reverse-proxies the engine API (/v1), so the engine itself never
leaves 127.0.0.1: a LAN client only talks to DStudio.
⚠️ With LAN enabled, anyone on that network can reach the shared chat/model proxy. Workspace, settings, store and Agent/Cowork/Design tool APIs remain local-only, but use trusted networks and turn LAN access off when finished.
What the host enforces, LAN on or off:
- Web tools from another device. When a LAN device asks DStudio to probe or read a page, the host does not connect to its own loopback services (DStudio's API, engines, other local servers), the unspecified address or link-local/metadata addresses. This holds for any spelling of the address and through redirects. DStudio checks every resolved address, connects only to the address it checked, and checks each redirect again. For a LAN device, pages are read with curl, without the browser (no JavaScript rendering).
- Host names (DNS rebinding). DStudio answers only when the
Hostis an IP address,localhost, or this machine's own name (name/name.local). This stops a web page that points its own domain at127.0.0.1from using the local API. To allow another name, for example behind a reverse proxy, list it inDS4UI_ALLOWED_HOSTS(comma separated). - Cross-site callers. CORS is granted only to DStudio pages on loopback or
private-network addresses (
10/8,172.16/12,192.168/16,100.64/10, link-local, IPv6 ULA) and allowed names. A public web site opened on a LAN device gets no grant. - LAN chat mirrors. Snapshots that LAN devices publish need DStudio's request header. The host keeps at most 32 devices and 256 MiB in memory and drops the least recently published one first. A dropped device reappears when it next publishes.
Cowork from a phone or tablet. A browser on another device can use the host's running Cowork session, which is off until the host user shares it:
- On the Mac, start Cowork in the folder to share, then choose Settings → Network → Cowork on the LAN → Share the running Cowork folder. An 8-digit pairing code appears.
- On the device, open the LAN address, choose Cowork and type the code.
The code works once, for 10 minutes, and five wrong attempts void it. The
device then holds its own token; the host stores only a hash of it and can
revoke it in the same pane. A paired device can send prompts, read the
answers, stop a turn and add files, only in the shared folder and only while
the host runs Cowork there. Commands (/list, /switch, …), goals, Agent,
Design, settings and other folders stay on the host. Sharing turns off at every
restart; paired devices are kept until revoked. Sharing is a shared session: the
device sees the conversation running in that folder. Not available in the
Windows build. make test-http-lan and tests/browser/ui_lan_cowork_playwright_test.mjs
check pairing, scope, the forced folder, pausing and revocation with the real
host and Cowork runtime and a simulated model.
How it works
- C launcher, not a script.
src/dstudio.cis the local HTTP server and the process supervisor: it starts and stops the engines and runtimes, runs the setup doctor, proxies/v1, serves Web Search and exposes a small local API.src/app.ccopens a WKWebView (macOS) or WebKitGTK (Linux) window around the embedded page. - Three engines, one owner per model. ds4 models run
ds4-serverfor Chat and the ds4 Agent/Cowork/Design runtimes. llama.cpp and MLX models run one resident server per model, started through a small guard process that leads its own process group, holds a shared installation lease and stops the server when DStudio stops it or dies. Readiness is the server's own report (/propsfor llama.cpp,/v1/modelsfor MLX) matching the admitted model. - Model RPC. Agent, Cowork, Design and the pi/OpenCode bridge reach llama.cpp, MLX and remote models through the host's model RPC: one request at a time, validated, cancellable by Stop, without exposing API keys to runtimes.
- Harness bridge.
src/harness/bridgeruns pi (RPC mode) or OpenCode (servewith SSE) behind DStudio's runtime protocol, so the transcript, Stop and Task Graph work unchanged. - Bundled, pinned sources. Engine and harness sources ship in
src/enginesandsrc/harnesswith per-file SHA-256 manifests, verified before every build. Adaptations to other projects are versioned.patchfiles inpatch/, applied withgit apply --checkfirst; a drifted source fails instead of being rewritten. Patches exist only for the bundled engine revisions: an engine checkout at any other revision is refused, not adapted. - The ds4 agent patch. ds4's agent is a separate, fast-moving codebase. DStudio keeps its structured Agent/Cowork adaptations as versioned patches: verify the pinned revision, apply to private source copies, build separately named runtimes and publish only the verified result, preserving the existing runtimes if anything fails. Build receipts include source, patch, compiler and shared-runtime identities.
- Durable Task Graph. Multi-step Agent work uses real tool/check/approval
executors, loop detection, exact-write undo receipts and a live graph with
pause/resume; its
events.jsonljournal is authoritative. - Native vision only. DeepSeek Vision-Exp and GLM 5.3 use their ds4 native encoders; Qwen3.8-27B uses its matching projector on llama.cpp. No secondary VLM, visual router or fallback is installed.
- KV cache. Chat re-sends its history behind a stable prefix that compatible
engines reuse (the blue cached count). Agent, Cowork and Design use
independent named KV sessions where the engine supports them (ds4). On the
llama.cpp and MLX models they save the transcript instead: after a restart
/switchrestores it and the server prefills it again; no KV is restored.
Security
- Localhost by default (
DS4UI_HOSToverrides the boot host); the page is served from a fixed path and no client path touches the filesystem. - Engines, runtimes and harnesses are spawned with
fork+execand an argument array (no shell); the model comes from a fixed set and integer parameters are range-checked. - Mutating local APIs require the anti-CSRF header
X-Requested-With: ds4web. - Outbound traffic is feature-scoped: model downloads from pinned Hugging Face revisions, harness dependencies at your explicit request, Web Research for requested public sources, and the optional DeepSeek API only after you supply a key and select it. Engine installation is offline.
⚠️ Agent, Design, pi and OpenCode can run shell commands autonomously; use a trusted project folder. File tools are confined to the workspace, shell commands are not sandboxed. Cowork has no arbitrary shell and confines its file/Office tools to the workspace.
Project roadmap
Ideas, not promises:
- Sharper Design studio: broader visual-diversity corpus and a second independent local render judge.
- Sharper Plan mode: richer plans with clearer acceptance criteria.
- MCP: Model Context Protocol support for external tools and data sources.
Contributing
DStudio is early, hardware-hungry and built for the local-AI crowd. The most useful contributions:
- Hardware reports. Open an issue with your machine and memory, the model and quantization, the mode and what happened. Failures are as useful as passes, especially on Linux, Windows, CUDA, ROCm and Vulkan (prepared but not yet run), and from any Apple Silicon Mac that can qualify GLM 5.3 and DeepSeek V4.1 (how to help).
- Reproducible agent failures and Design output examples.
- Small PRs that reduce first-run friction.
Read AGENTS.md for the contribution rules. If you want open-source local AI tools outside cloud subscriptions, a ⭐ helps the project reach the right testers.
License
BSD 3-Clause © 2026 Giuseppe Perrotta. Bundled third-party sources keep their own licenses: see THIRD_PARTY_NOTICES.md.
WIP checklist — October 27, 2026
The macOS/Apple Silicon campaign is incomplete. Checked items mean the stated implementation or scoped verification is complete; they do not qualify every model or a release. Exact acceptance criteria and retained failures are in the remaining WIP and PLAN.MD.
Completed implementation and scoped checks
- Bundle pinned engine sources with provenance and versioned adaptations; build/install from an empty offline profile without fetching sources. Sources and verification.
- Replace the Qwen side engines with bundled llama.cpp for Qwen3.6 and Qwen3.8-27B, with a guarded resident owner; real 6/6 on each model, including Design. Retirement record.
- Add MLX for Qwen3.6 on Apple Silicon: offline wheels, pinned weight download, readiness check; real 6/6 with retained earlier failures.
- Run Design on llama.cpp/MLX models with structured tool calls.
- Add pi and OpenCode as Agent harnesses with pi-ds4 for DeepSeek, versioned patches, workspace confinement and a Settings pane; real 24/24 across four models. Harness results.
- Stream files being written (live tool-call previews) in Agent, Cowork, Design, pi and OpenCode on llama.cpp, MLX and ds4; real write-streaming checks pass on every path. Results.
- Fix llama.cpp/MLX starts in the desktop app (the server guard was not dispatched by the app binary); the bundle smoke now runs the guard test on it.
- Prepare Linux/Windows llama.cpp builds (dynamic backends, Job Object, parent-death signal); cross-compiled, and the dynamic layout built and run on macOS.
- Move Qwen Next onto unified main and record the Q4 baseline: 75/100 corpus answers and 8/8 long-context cases. Qwen evidence.
- Remove automatic elapsed-work cutoffs from model preparation, inference, PDF planning and Research, keeping Stop, count/byte/concurrency bounds and explicit Task Graph budgets.
- Correct Research progress, streamed writer output and visible incomplete outcomes. Remaining real-answer checks.
- Share transcript selection/scroll handling across modes and fix image, native-window and Learn/Tutor regressions; the simulated UI matrix passes 54/54. Coverage.
- Ship 25 offline Design systems with guides and recipes; 402/402 authored preview checks pass in Chromium/WebKit (no model ran). Catalog.
- Offer DeepSeek V4.1 Flash 1017 Q2 (the official file) with its vision
sidecar; each V4.1 checkpoint opens only with its own sidecar, and the
original Q2 stays resumable.
make test-v41-vision-pairing-livechecks the real engine on published headers (no weights read, no inference). - Offer only the publishers' official weights; modified derivatives are refused and left untouched on disk.
- Offer every published standard quantization of Qwen3.6-35B-A3B and
Qwen3.8-27B on llama.cpp and MLX (63 variants) from one pinned catalog, with
per-file size/SHA-256 verification; 27B on MLX is text only. Fixture-based
checks only (
make test-qwen-variants); no variant other than the defaults has run on real weights. - Update the bundled MLX to mlx 0.32.4 and mlx-lm 0.32.2: real offline install reaching Metal, and real Qwen3.6 MXFP8 tool-call streaming in Agent, Cowork and Design. Two earlier Design attempts failed on the test client's start limit; their receipts are kept.
- Download every Qwen variant, the three original ones included, through
one verified downloader (
scripts/download-qwen-variant.py). Remove host routes and UI code that nothing called. - Keep patches only for the bundled engine revisions (ds4 main
0aaea5a, Laguna448d569): the variants for earlier main revisions and the retired Qwen Next fork, with its fixtures and tests, are deleted (about 19,000 lines). The patch stack applies and restores byte for byte on the bundled sources. Patch notes. - Breaking (October 27, 2026): no backward compatibility with older
installations. An engine at another revision, an older DStudio patch state
(the former M2 Max batch-limit upgrade and Design label normalization), a
leftover
ds4-qwen38/ds4-glm5.3folder without a DStudio receipt or the old Qwen Next base + PLE files get no special handling or upgrade: they fail as drift or are treated like any other folder or file. Half-finished Qwen downloads from before this change do not resume (their staging folder is now.dstudio-qwen-downloads); partial files are left on disk. Reinstall the bundled engines and restart those downloads.
Still required
- Restore Agent, Cowork and Design sessions on llama.cpp/MLX (and a LAN
host) after a restart: the transcript is saved after every turn and
/switchrebuilds it; old tool calls can never run again. Real runtimes across a restart with simulated model frames:make test-remote-session. - KV snapshots for llama.cpp/MLX sessions (a restored session is prefilled again), and saved sessions for pi/OpenCode on these models.
- Refuse SSRF to the host's loopback from LAN devices, DNS rebinding and
cross-site CORS; bound and protect LAN chat mirrors.
make test-http-lan(real host, requests from the LAN address). - Read scanned PDF pages with local OCR on macOS; labelled pages, bounded
work per read, cached readings, OCR line evidence.
make test-pdf-ocr. Linux/Windows OCR: not implemented. - Raise Cowork comparison-table limits (5,000 rows, 128 columns, 100,000
cells, 512 sources) with a content-addressed extraction cache.
make test-document-table-scale. - Fix Cowork text-copy fidelity (a lost final newline); real A/B on DeepSeek V4 Flash Vision-Exp. Results.
- Cowork from a LAN browser through an explicitly shared, paired session.
make test-http-lan,tests/browser/ui_lan_cowork_playwright_test.mjs. - Run the five representative real-weight checks of the newly downloadable Qwen variants (Qwen3.6 UD-Q4_K_M, UD-IQ4_XS and MXFP4_MOE GGUFs, Qwen3.6 MLX NVFP4, Qwen3.8-27B MLX 4-bit; about 98 GB) with the production-host gate, one at a time. NOT RUN yet (no weights downloaded for them). Plan.
- Rerun the 100-task corpus and the long requests on llama.cpp and MLX (published Qwen scores come from retired engines); qualify Next Q2 independently.
- Run Linux, Windows, CUDA, ROCm and Vulkan for real; make pi/OpenCode available on Windows.
- Run pi/OpenCode with GLM, Laguna, Qwen3.8-Flash-Next, DeepSeek V4.1 and a cloud endpoint, and qualify Plan/GSA/RSA with them.
- Complete Agent/Cowork dependency signatures, crash-safe runtime-pair publication and verified legacy-source recovery.
- Complete Learn/Tutor, including on the llama.cpp/MLX models, and the retained Next reasoning-setting incident.
- Complete selected-model Agent/Goals/Cowork long tasks, steering, pause/resume, durable recovery, exactly-once effects and reopened exports.
- Independently qualify native PDF/vision inputs (at least 30 PDFs and 20 images per vision checkpoint, negative text-model cases) across all modes.
- Complete the native-model desktop workflows (each model × Chat, Agent, Learn, Cowork, Design), switching, cancellation and final-build regressions.
- Qualify the remaining Design domain auditors and generate, operate and review the frozen projects; add generated-project qualification for the sixteen newer Design systems.
- Complete installation/upgrade/failure/recovery coverage and final engine admission with qualifying receipts for every required gate.
- Complete held-out Search/Research evaluation and native-vision webpage checks.
- Qualify DeepSeek V4.1 1017 Q2, V4.1 Q4 and GLM 5.3 across modes, vision, memory and SSD settings. The original Q2's retained format failure does not transfer to the 1017 file. Contributor hardware wanted: on the maintainer's M2 Max (96 GB) they run only with SSD streaming and their complete qualification is left to contributors; they stay BLOCKED, not passed. How to help.
- Complete the six-agent/two-lane comparison with held-out cases, phase profiling, matched baselines and reviewed Matplotlib publication.
- Validate the two-photo MiniMax H3 path end to end.
Proposed modules and improvements (not started)
Candidates added October 25, outside the campaign; what exists today and what is missing for each is in PLAN.MD.
- Guards for the pi/OpenCode harnesses: duplicate-call breaker, read-only Plan mode and mid-turn steering.
- Disk KV slots for llama.cpp and an MLX prefix cache.
- A pre-action reasoning budget that pauses with a clarifying question.
- Constrained JSON for structured internal steps, per engine.
- A read-only local state audit in Doctor.
- Independent edit receipts and restore for Office files in Cowork.
- A stream integrity check, report-only first.
- A mastery ledger with graded assessments in Learn.
- An import/include index and JSON Canvas export for Open Blueprint.
- A PDF ↔ web claim agreement matrix in Search.
- Conversation branches instead of a destructive Regenerate.
- An opt-in watched drop folder for Cowork.
Private prompts, documents, transcripts, weights and raw receipts remain ignored. Publishing this checkpoint does not qualify any unchecked requirement.
Explore related projects
affaan-m/ECC
The agent harness performance optimization system. Skills, instincts, memory, security, and research-first development for Claude Code, Codex, Opencode, Cursor and beyond.
300,313 starsNousResearch/hermes-agent
The agent that grows with you
262,134 starsmultica-ai/andrej-karpathy-skills
A single CLAUDE.md file to improve Claude Code behavior, derived from Andrej Karpathy's observations on LLM coding pitfalls.
231,460 starsfirecrawl/firecrawl
Supercharge your AI agents with data from the web and beyond. Building the library for superintelligence. 🔥
200,178 stars