
salikhussain71-code/PAKGOV-RAG-project
salikhussain71-code/PAKGOV-RAG-project has 131 GitHub stars and 7 forks. GitHot measured 0 stars in 24 hours and +1 in 7 days. Last checked 2026-11-18 03:44 UTC. Last push 2026-11-07.
What you can do
- BM25 + dense fused with RRF beats both alone - Refuses when evidence is missing - Raw outputs committed, one command regenerates results - Urdu, English and mixed queries
Measured star growth
- in 24h
- 0
- in 7 days
- +1
- in 15 days
- Collecting history
- in 1 month
- Collecting history
Net star changes over overlapping periods, not daily totals. Missing measurements are left blank. Stars measure attention, not software quality.
About
Research project on bilingual Urdu-English retrieval-augmented generation for Pakistani government and legal documents, with OCR, hybrid retrieval, citation grounding, and evaluation.
AIREADME.md
Original
Bilingual (Urdu + English) Retrieval-Augmented Generation over Pakistani Government & Legal Documents
Hybrid retrieval · Citation-grounded answers · Failures reported openly






Demo · Recognition · Results · Done vs Remaining · Architecture · Reproduce · Limitations · Roadmap · Author
🖼️ Live Demo
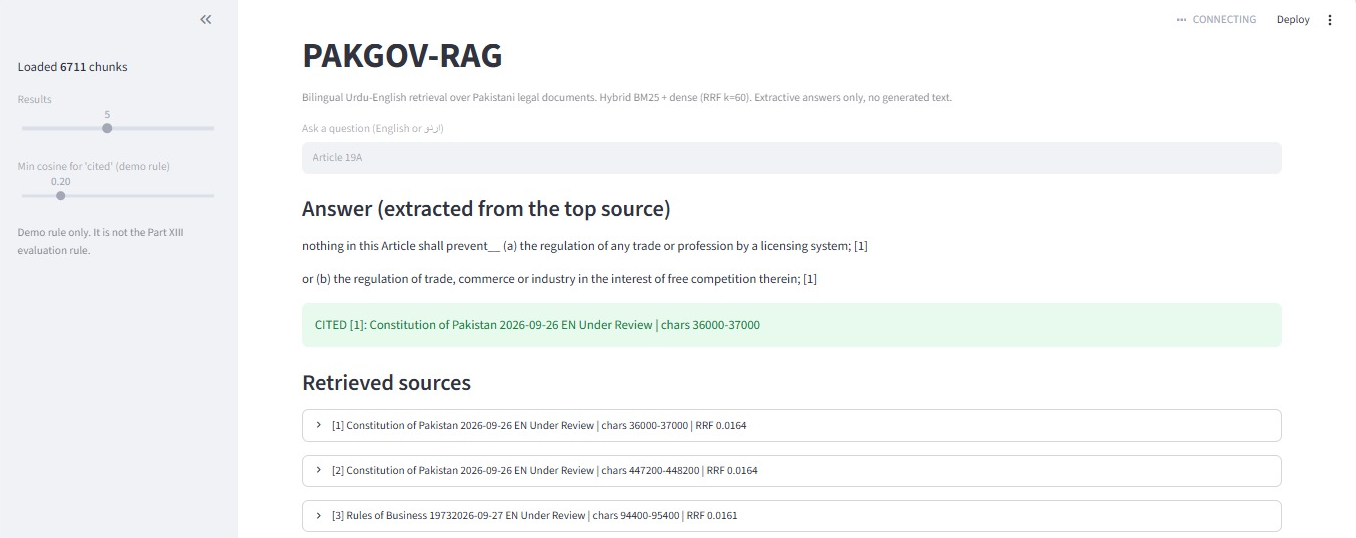
Query "Article 19A" returns an extracted answer, its citation, and the top 5 retrieved sources with RRF scores.
⚡ At a Glance
| 📚 Corpus | 🧪 Eval Set | 🎯 Best R@5 | 📈 Best MRR | ✅ Grounded | 🌐 Languages |
|---|---|---|---|---|---|
| 6,711 chunks | 50 questions | 0.740 | 0.605 | 74% | 3 (UR / EN / mixed) |
🏅 Open-Source Recognition
| 🌐 Listed On | 🏆 Recognition |
|---|---|
| olud.ai | PAKGOV-RAG is listed in the olud.ai AI project directory. |
| XERJ Corpus Hub | PAKGOV-RAG was selected for the indexed corpus hub, with attribution. |
💬 Independent platforms have indexed and credited this project, which makes it easier for other researchers to find and verify the work.
🎯 Overview
PAKGOV-RAG answers questions about the Constitution of Pakistan in English, Urdu, or a mix of both.
- It retrieves the most relevant passages (BM25 + dense, fused with Reciprocal Rank Fusion).
- It extracts the answer only from retrieved passages, with no free-form generation.
- It cites the source passage.
- If the evidence does not contain the answer, it says "insufficient evidence" instead of guessing.
It is also a small, honest study of retrieval quality on a low-resource language. Three retrievers are compared on the same question set, and every failure is logged.
💡 Why this matters
- Government and legal documents are hard for ordinary citizens to search, especially in Urdu.
- Most RAG demos report only their successes. This project publishes its failures too.
- Urdu is under-served by NLP tooling, so measuring where retrieval breaks is useful in itself.
⭐ Project Highlights
| 🔎 Hybrid search | 🛡️ No guessing | 🧾 Fully reproducible | 🌍 Low-resource focus |
|---|---|---|---|
| BM25 + dense fused with RRF beats both alone | Refuses when evidence is missing | Raw outputs committed, one command regenerates results | Urdu, English and mixed queries |
📊 Results
All numbers come from the same 50-question evaluation set, so the comparison is like for like.
| Retriever | R@1 | R@3 | R@5 | R@10 | MRR |
|---|---|---|---|---|---|
| BM25 (baseline) | 0.360 | 0.580 | 0.640 | 0.680 | 0.469 |
| Dense (multilingual MiniLM) | 0.440 | 0.600 | 0.620 | 0.740 | 0.535 |
| Hybrid RRF (k=60) | 0.500 | 0.660 | 0.740 | 0.820 | 0.605 |
Recall@5
BM25    ████████████████░░░░░░░░░  0.640
Dense   ███████████████░░░░░░░░░░  0.620
Hybrid  ██████████████████░░░░░░░  0.740  ← best
MRR
BM25    ███████████░░░░░░░░░░░░░░  0.469
Dense   █████████████░░░░░░░░░░░░  0.535
Hybrid  ███████████████░░░░░░░░░░  0.605  ← best
🔑 Key findings
- Hybrid RRF is the strongest on every metric.
- At R@5 it is 10 points above BM25 and 12 points above dense retrieval.
- Dense retrieval beats BM25 at R@1, R@10 and MRR, but BM25 is slightly ahead at R@5 (0.640 vs 0.620).
🛡️ Grounded answers (50 questions)
| Outcome | Count | Share |
|---|---|---|
Answer with [Source: Constitution.pdf p.X] citation |
37 | 74% |
insufficient evidence returned |
13 | 26% |
The 13 refusals match the 13 questions where the gold source was not in the top 5, so the system declines instead of hallucinating.
🌐 Multilingual checks
- Urdu text is NFC-normalized
- Embedding shape is
[5, 384]on the test batch - Urdu–English cross-lingual similarity on the test pair: 0.8370
🧪 Evaluation Set
| Property | Value |
|---|---|
| Questions | 50, with manually verified gold sources |
| English | 15 |
| Urdu | 15 |
| Mixed-language | 20 |
| Corpus | 6,711 chunks from Constitution of Pakistan PDFs, with page and article metadata preserved |
| Metrics | Recall@1, Recall@3, Recall@5, Recall@10, MRR |
✅ Project Status: Done vs Remaining
Summary: the core research pipeline, evaluation, demo and open-source setup are complete. Remaining work is extending coverage (OCR, more documents) and improving retrieval quality.
Core pipeline & evaluation   ████████████████████  100%  DONE
Demo application             ████████████████████  100%  DONE
Open-source setup            ████████████████████  100%  DONE
Recognition                  ████████████████████  100%  DONE
Senate corpus extension      ██████████████░░░░░░   80%  IN PROGRESS (8 of 10 PDFs readable)
Retrieval improvements       ░░░░░░░░░░░░░░░░░░░░    0%  PLANNED
Public deployment & paper    ░░░░░░░░░░░░░░░░░░░░    0%  PLANNED
✅ Done (everything completed so far)
| # | Area | What was completed |
|---|---|---|
| 1 | Ingestion | PDF text extraction with PyMuPDF and pdfplumber, cleaning, Unicode NFC normalization of Urdu text |
| 2 | Chunking | 6,711 chunks from the Constitution PDFs, with page and article metadata preserved |
| 3 | Embeddings | paraphrase-multilingual-MiniLM-L12-v2, 384-dimensional vectors (test batch shape [5, 384]) |
| 4 | Lexical retrieval | BM25 baseline with rank_bm25 |
| 5 | Dense retrieval | FAISS semantic search over the multilingual embeddings |
| 6 | Hybrid retrieval | Reciprocal Rank Fusion (k=60) combining BM25 and dense rankings |
| 7 | Evaluation set | 50 questions (15 English, 15 Urdu, 20 mixed) with manually verified gold sources |
| 8 | Metrics | Recall@1/3/5/10 and MRR for all three retrievers on the same set |
| 9 | Grounded answers | Extractive answers with [Source: …] citations; 37 of 50 answered, 13 returned insufficient evidence |
| 10 | Failure analysis | All 13 R@5 misses written up in failure_analysis_50.md |
| 11 | Urdu checks | urdu_unicode_report.json plus a cross-lingual similarity check (0.8370) |
| 12 | Reproducibility | Raw .jsonl results and .json metrics committed; python app/eval/final_table.py regenerates the table |
| 13 | Demo app | Streamlit app with result-count slider, citation threshold, extracted answer, citation box and expandable retrieved sources with RRF scores |
| 14 | Senate extension | 10 official senate.gov.pk PDFs downloaded, extracted, chunked (1,080 chunks) and indexed (1,080 FAISS vectors) |
| 15 | Robustness | 2 scanned PDFs handled without crashing the pipeline (placeholders written) |
| 16 | Repository structure | Organized into app, data, docs, evaluation, generation, ingestion, retrieval, scripts, tests, .github |
| 17 | Open-source setup | MIT license, contributing guide, security policy |
| 18 | Documentation | Professional README with results, architecture diagram, limitations and demo screenshot |
| 19 | Recognition | Listed on olud.ai; selected for the XERJ Corpus Hub with attribution |
| 20 | Community traction | 129 stars and 5 forks on GitHub |
🔜 Remaining (everything still to do)
| # | Priority | Task | Why it matters | Done when |
|---|---|---|---|---|
| 1 | 🔴 High | OCR the 2 scanned Senate PDFs with Tesseract (Joint Sittings Rules 1973, Finance Committee Rules 1973) | Both currently contribute only placeholder text (198 and 197 chars) | Both PDFs produce real text and are re-chunked and re-indexed |
| 2 | 🔴 High | Larger, more varied evaluation set | With 50 questions, one question is worth 2 points, so rankings are only indicative | A bigger set is built and all three retrievers are re-evaluated |
| 3 | 🔴 High | Evaluate on the Senate corpus | Shows whether results carry beyond the Constitution | Recall and MRR reported for the Senate documents |
| 4 | 🟠 Medium | Cross-encoder reranker | Targets the 13 questions that miss at R@5 | Reranked results compared against Hybrid RRF on the same set |
| 5 | 🟠 Medium | Stronger multilingual embeddings | MiniLM-L12 is fast but not the strongest option for Urdu | At least one larger encoder compared to MiniLM-L12 |
| 6 | 🟠 Medium | Article-aware chunking | Keeps each article intact to reduce retrieval misses | New chunking evaluated against the current 6,711-chunk setup |
| 7 | 🟡 Planned | Fix low text yield in Senate_Secretariat_Service_Rules_2021 (26 pages, only 3,286 chars) |
Likely a partial scan or extraction issue | Text yield matches the page count |
| 8 | 🟡 Planned | Unified index across the Constitution and Senate documents | One search over all documents | One index, one demo, all documents searchable |
| 9 | 🟡 Planned | Synthesized answers across sources | The demo is extractive and uses only the top source | Multi-source answers with citations for each claim |
| 10 | 🟡 Planned | Public deployment of the demo | Anyone can try it without installing | A public link works |
| 11 | 🟡 Planned | Short write-up or paper on Urdu legal retrieval | Turns the evaluation into a citable result | A write-up is published |
| 12 | 🟡 Planned | Extension to other Pakistani government documents | Broadens coverage beyond legal texts | At least one new document family ingested and evaluated |
🏗️ Architecture
flowchart LR
    A[PDF Documents] --> B[Extraction<br/>PyMuPDF / pdfplumber]
    B --> C[Cleaning +<br/>Unicode NFC]
    C --> D[Chunking<br/>page + article metadata]
    D --> E[Embedding<br/>MiniLM-L12 · 384d]
    D --> F[BM25 Index]
    E --> G[FAISS Index]
    Q[User Question<br/>Urdu / English / Mixed] --> F
    Q --> G
    F --> H[Reciprocal Rank Fusion<br/>k=60]
    G --> H
    H --> I{Evidence<br/>found?}
    I -- Yes --> J[Extracted Answer<br/>+ Citation]
    I -- No --> K[Insufficient Evidence]
| Stage | Implementation |
|---|---|
| Ingestion | PDF text extraction (PyMuPDF / pdfplumber), cleaning, Unicode NFC normalization |
| Chunking | 6,711 chunks with page and article metadata |
| Embedding | sentence-transformers/paraphrase-multilingual-MiniLM-L12-v2 (384 dimensions) |
| Lexical retrieval | BM25 (rank_bm25) |
| Dense retrieval | FAISS |
| Fusion | Reciprocal Rank Fusion, k=60 |
| Answering | Extractive: answers come only from retrieved chunks, with citations |
| Evaluation | Recall@1/3/5/10 and MRR on the fixed 50-question set |
🛠️ Tech Stack
▶️ Run the Demo
pip install streamlit sentence-transformers faiss-cpu rank_bm25
python -m streamlit run app/demo/app.py --server.port 8501
Example queries
What is Right to Information?
Article 19A
آرٹیکل 19 اے کیا ہے؟
Each result shows the question, detected language, status (grounded or insufficient evidence), the answer, and its citation.
🔁 Reproduce the Results
python app/eval/final_table.py
This regenerates the results table and writes evaluation/retrieval/FINAL_RESULTS.md.
Repository evidence
Raw evaluation outputs are committed so the numbers can be checked directly.
data/interim/
├── bm25_results_50.jsonl
├── dense_results_50.jsonl
├── hybrid_rrf_results_50.jsonl
└── grounded_answers_50.jsonl

evaluation/retrieval/
├── bm25_metrics_50.json
├── dense_metrics_50.json
├── hybrid_rrf_metrics_50.json
├── grounded_metrics.json
├── failure_analysis_50.md
├── urdu_unicode_report.json
└── FINAL_RESULTS.md

app/
├── demo/app.py
└── eval/final_table.py
🏛️ Senate Extension (1–2 Oct 2026)
Extended the pipeline to 10 official PDFs from senate.gov.pk (Publications → Rules and Acts), saved in data/raw/senate/.
| File | Pages | Characters | Status |
|---|---|---|---|
| Rules_Procedure_Conduct_Business_Senate_2012_2026 | 111 | 219,683 | ✅ readable (updated 6 Feb 2026) |
| Constitution_Pakistan_2025_11_14 | 176 | 454,525 | ✅ readable (updated 14 Nov 2025) |
| Chairman_Speaker_Salaries_Act_1975 | 11 | 28,231 | ✅ readable |
| Dy_Chairman_Dy_Speaker_Salaries_Act_1975 | 11 | 26,020 | ✅ readable |
| Enhancement_Role_Powers_Senate_2017 | 32 | 34,908 | ✅ readable |
| Members_Parliament_Salaries_Act_1974_Medical_Rules_1990 | 44 | 66,423 | ✅ readable |
| Senate_Secretariat_Service_Act_2017 | 15 | 25,532 | ✅ readable |
| Senate_Secretariat_Service_Rules_2021 | 26 | 3,286 | ⚠️ readable, low text yield |
| Parliament_Joint_Sittings_Rules_1973 | 23 | 0 (placeholder 198) | ⏳ scanned, Tesseract OCR pending |
| Senate_Finance_Committee_Rules_1973 | 10 | 0 (placeholder 197) | ⏳ scanned, Tesseract OCR pending |
Pipeline run
python ingestion/extract.py --input data/raw/senate --output data/interim/senate_raw.jsonl
python ingestion/chunking/chunk_documents.py --input data/interim/senate_raw.jsonl --output data/processed/senate_chunks.jsonl
python retrieval/embed.py --input data/processed/senate_chunks.jsonl --output data/processed/senate_faiss
Outcome: 10 PDFs processed (8 readable + 2 placeholders), 2 scanned PDFs handled without crashing, 1,080 chunks saved, and a FAISS index built with 1,080 vectors. Embedding 1,080 chunks took 4 min 43 s.
Source: Senate of Pakistan, © 2019–2026.
⚠️ Limitations
- Small evaluation set. With 50 questions, one question is worth 2 points. A 10-point gap at R@5 is 5 questions, so treat the ranking as indicative, not definitive.
- Single main corpus. Main results are for the Constitution only and may not carry over to other legal or government documents.
- Failures are real. 13 of 50 questions (26%) miss at R@5. The system refuses rather than hallucinates, but it does not yet recover them. See
evaluation/retrieval/failure_analysis_50.md. - Lightweight embedding model. MiniLM-L12 is fast but not the strongest option for Urdu. Larger multilingual encoders and rerankers are the obvious next step.
- Extractive only. Answers are pulled from the top source, not synthesized across several sources.
- Senate OCR pending. Two scanned Senate PDFs are not yet searchable.
🗺️ Roadmap
- BM25 / Dense / Hybrid RRF comparison on 50 questions
- Citation-grounded answers with refusal on weak evidence
- Failure analysis published
- Streamlit demo
- Senate documents ingested, chunked, and embedded (1,080 chunks)
- MIT license, contributing guide, security policy
- Listed on olud.ai and selected for the XERJ Corpus Hub
- OCR (Tesseract) for the 2 scanned Senate PDFs
- Larger, more varied evaluation set
- Evaluation on the Senate corpus
- Cross-encoder reranker
- Stronger multilingual embeddings
- Article-aware chunking
- Fix low text yield in Senate_Secretariat_Service_Rules_2021
- Unified index across all documents
- Multi-source synthesized answers
- Public deployment
- Short write-up on Urdu legal retrieval
- Extension to other Pakistani government documents
🎓 Skills Demonstrated
| Area | Evidence in this repo |
|---|---|
| Information retrieval | BM25, dense retrieval, Reciprocal Rank Fusion |
| NLP for low-resource languages | Urdu NFC normalization, cross-lingual similarity checks |
| Evaluation methodology | Fixed question set, Recall@k and MRR, honest failure analysis |
| Data engineering | PDF extraction, scanned-PDF handling, chunking with metadata |
| Reproducible research | Committed raw outputs, one-command result regeneration |
| Applied ML engineering | FAISS indexing, sentence-transformers, Streamlit app |
| Open-source practice | MIT license, contributing guide, security policy, public repo |
📈 Star History
👤 Author
Salik Hussain
Research interest: Urdu NLP and low-resource language AI

📄 License
MIT License. Copyright (c) 2026 Salik Hussain. See LICENSE.
⭐ If this project helps your research, please star the repo.