
rootSunc/CNEquity
rootSunc/CNEquity has 984 GitHub stars and 109 forks. GitHot measured +7 stars in 24 hours. Last checked 2026-11-09 23:10 UTC. Last push 2026-11-03.
开源中国股市(A股)本地数据湖:沪深股票行情、A股股票数据与金融数据,面向量化研究、量化交易与回测,含财务数据、期货数据、资金流向、公告、指数行业与宏观。55 个日更数据集,复权与历史成分内置,行级溯源、PIT,MCP 原生。免注册、免 Token,自托管。Open-source China stock market data lake for quant research, backtesting and AI agents.
Measured star growth
- in 24h
- +7
- in 7 days
- Update delayed
- in 15 days
- Update delayed
- in 1 month
- Update delayed
Net star changes over overlapping periods, not daily totals. Missing measurements are left blank. Stars measure attention, not software quality.
README.en.md
Original
CNEquity · A local data foundation for China-market research
No registration or token · Adjustment and PIT built in · Delisted stocks kept · Row-level provenance · MCP-native
CNEquity is an open-source local data lake for China A-share stock market data: Shanghai and Shenzhen prices, stock data, financials and futures data, for quant research, quantitative trading and backtesting. 57 datasets land in local Parquet, with incremental resume, and MCP so an AI can query A-shares directly.





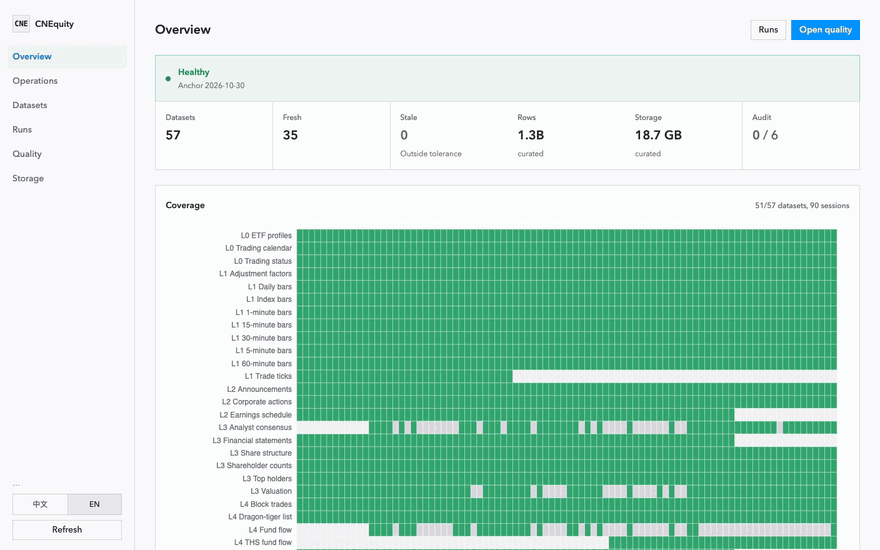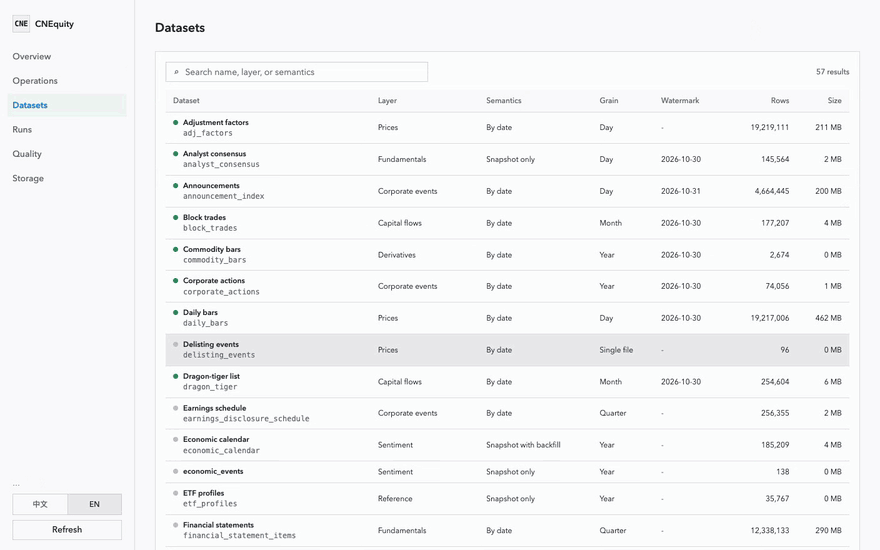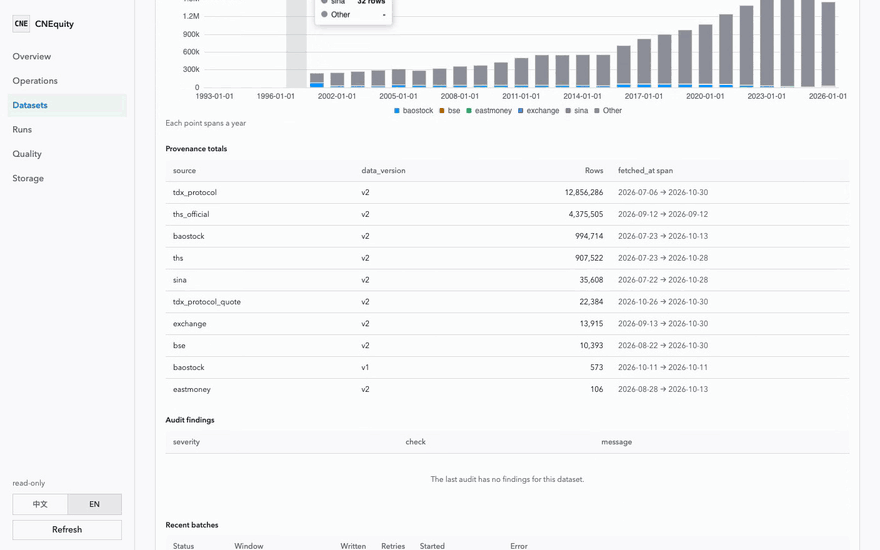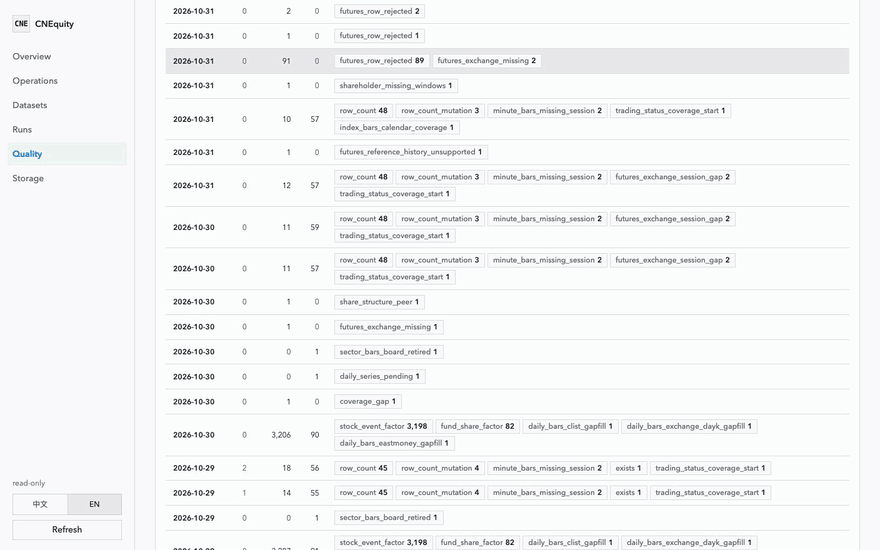
A real recording of the cne serve dashboard.
Why CNEquity
How it differs from common data tools (full write-up in the comparison):
| AKShare | Tushare Pro | Baostock | CNEquity | |
|---|---|---|---|---|
| Account and token | Not needed | Registration + token, unlocked by points | Not needed, anonymous login | Not needed for basic collection |
| Storage and increments | Caller's job | Caller's job | Caller's job | Local Parquet with built-in increments and resume |
| Delisted stocks and PIT financials | Depends on the interface | Depends on the interface | Partly provided | Delisted stocks kept; financials strictly PIT by announcement date |
| Row-level provenance | None | None | None | Every row carries source, version and fetch time |
| Use by AI | Wrap it yourself | Wrap it yourself | Wrap it yourself | Read-only via cne mcp |
Quick start
Requires Python 3.10+ on macOS, Linux or Windows. No account or token needed.
① Try it in a minute. Fetch the last 30 trading days for 5 stocks from live sources into a separate directory that never touches your real lake:
pip install cnequity
cne init --profile demo   # about a minute; prints the bars, a sample query and the command to hand it to an AI agent
cne serve --config configs/cnequity.demo.toml   # open the dashboard shown above
② Let an AI agent query A-shares. Connect the lake read-only to Claude, ChatGPT, Codex, Gemini CLI, Cursor, VS Code or any other MCP client (give --config as an absolute path). With Claude Code:
claude mcp add cnequity -- cne mcp --config /abs/path/to/configs/cnequity.demo.toml
See the MCP guide for every client; ChatGPT only reaches public URLs, so it connects through cne mcp --http --token and a tunnel. Then ask: "Which day had CATL's highest close in the last 30 trading days?"
Real MCP tool calls and results on the demo lake; closes are unadjusted.
③ Build the full lake. Every Shanghai, Shenzhen and Beijing A-share, last 3 years:
cne init     # the first run can take hours; if it stops, run it again and nothing already downloaded is fetched twice
             # a few-second network preflight runs first; a failure in a non-critical step such as corporate actions does not stop the build, and the summary lists what is left
cne check    # confirm the data is complete and usable
from cnequity.query import load

bars = load("daily_bars", symbols=["600519.SH"])
print(bars.tail())
Then run cne run daily once a day to stay current. For longer history, or what init does step by step, see the initialization guide.
What can you research?
| Question | Data and example |
|---|---|
| Returns across dividends and splits | daily_bars + adj_factors · adjustment recipe |
| Financial facts visible on a rebalance date | financial_statement_items · PIT recipe |
| Historical universes and pre-delisting prices | instruments, trading_status, delisting_events · profiles |
| Valuation, flows and sector rotation | Valuation, capital and structure datasets · query guide |
| Futures curves, option chains and Greeks | Contract-level prices and derived datasets · derivatives |
Data coverage
57 datasets (49 curated, 8 derived), organized into L0–L9. Fields, keys, history starts and sources are in the catalog and source notes.
| Tier | Research use | Representative datasets |
|---|---|---|
| L0 | Reference | Instruments, trading calendar, trading status |
| L1 | Market data | Daily and index bars, adjustment factors, optional minutes and trade snapshots, delisting events |
| L2 | Corporate events | Actions, announcement index, disclosure schedule |
| L3 | Fundamentals | Financials, valuations, share structure, holders, consensus |
| L4 | Capital and flows | Northbound, margin trading, dragon-tiger lists, block trades, fund flows |
| L5 | Industry structure | Index constituents, industry and sector membership, industry index |
| L6 | Macro | Indicators and market breadth |
| L7 | News and rotation | News, wires, sentiment, rankings, sector prices and flows |
| L8 | Risk and regulation | Share unlocks and regulatory events |
| L9 | Derivatives | Futures and options contracts, contract bars, continuous futures, Greeks and minutes |
Minutes, trade snapshots, futures/options, and best-effort datasets such as money flow, news and popularity ranks are off by default. Turn them on when you need them.
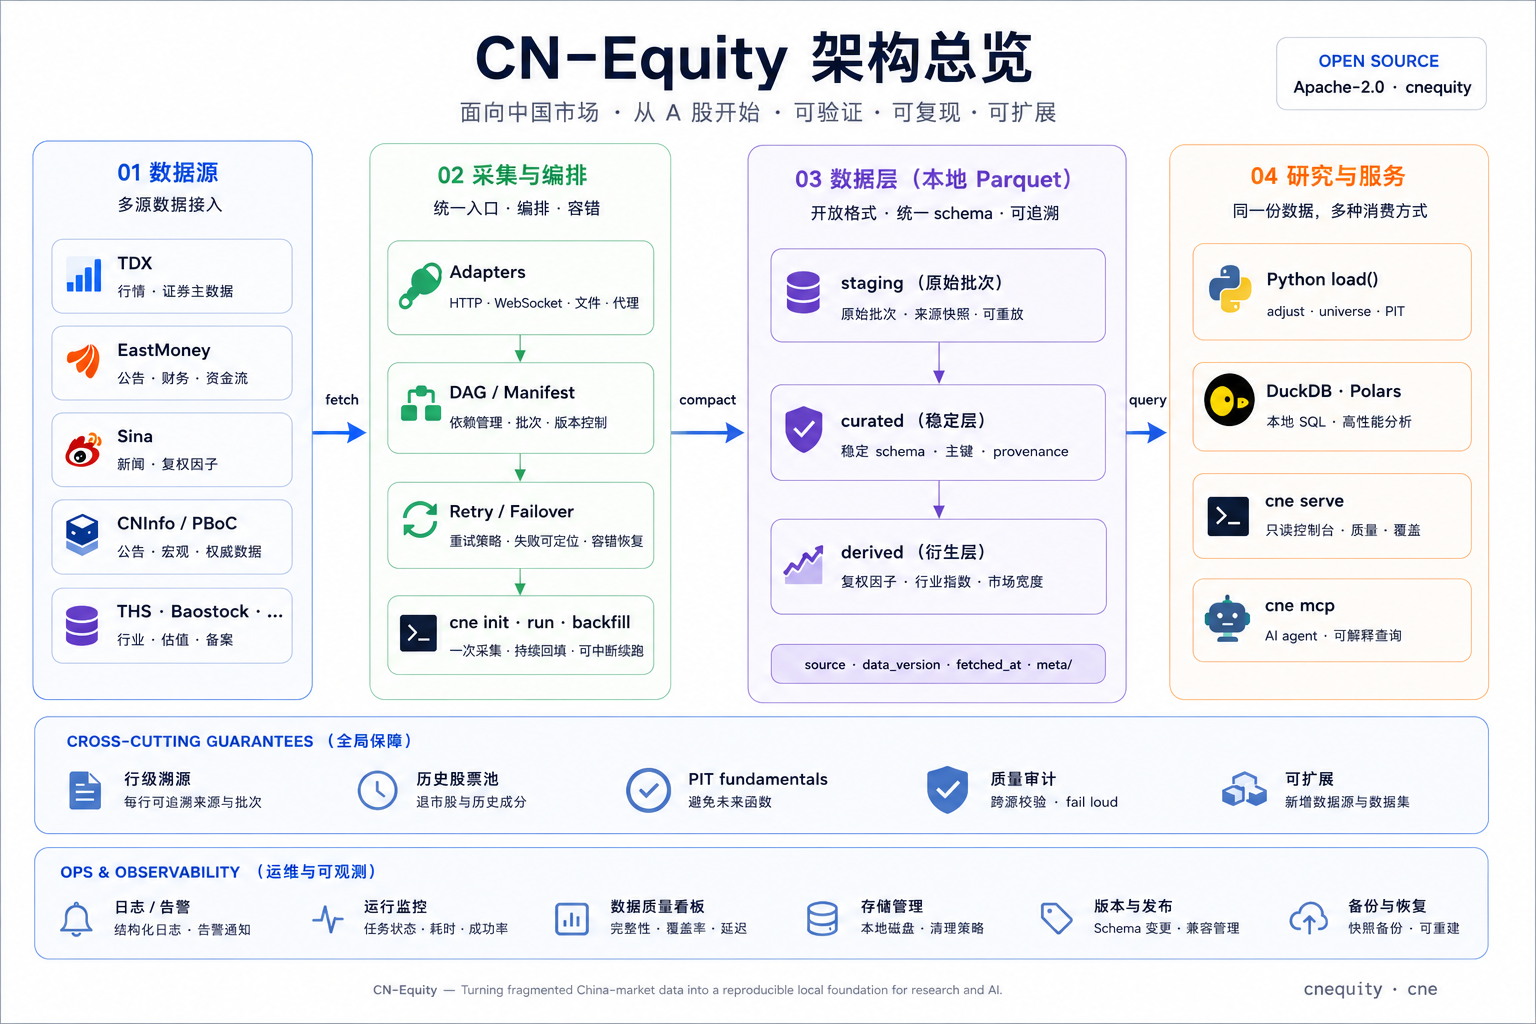
Architecture
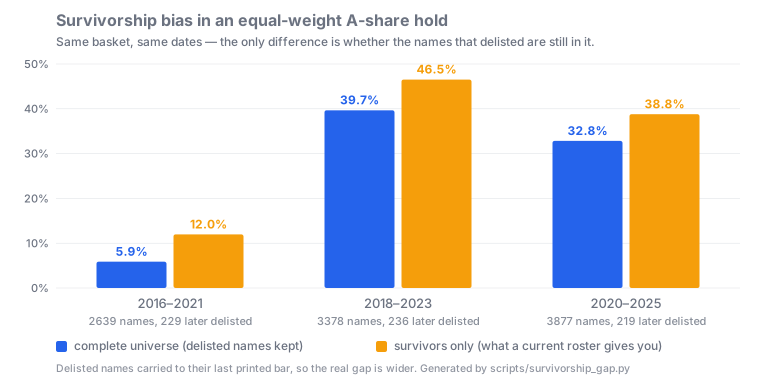
Survivorship bias
Today's roster is not a historical universe.
Daily updates and upgrades
cne schedule install   # install a daily job for the current user (macOS / Linux / Windows)
cne run daily          # or run this yourself once a day
cne check              # acceptance; exits non-zero on gaps or quality errors
To upgrade: pip install -U cnequity, then cne config upgrade and cne migrate (preview first, then add --apply). Scheduling, the operations page and failure follow-up are in the runbook; scope and resume in initialization.
Fit and limits
CNEquity fits ongoing history, repeated queries and self-hosted data.
The project is in 0.x, with no backtesting engine or order execution. Code is Apache-2.0; upstream data has separate terms. No data lake is distributed with the repository.
Documentation and contributions
| Task | Read |
|---|---|
| Install and get a result | Installation · Quickstart |
| FAQ | Free A-share historical data · Avoiding look-ahead bias · Ask AI about A-shares · AKShare, Tushare or Baostock |
| Understand the data | Catalog · Schemas · Recipes |
| Find a command | CLI · Options · Network/write effects |
| Operate the lake | Runbook · Fetch policy · Troubleshooting |
| Product direction and feedback | Product overview · Upgrades and feedback |
Issues with minimal reproductions, documentation fixes and adapter PRs are welcome. Cite CITATION.cff for research; report vulnerabilities privately using the security policy.
Useful to you? Star CNEquity, or share it with someone maintaining China-market data.
Explore related projects
affaan-m/ECC
The agent harness performance optimization system. Skills, instincts, memory, security, and research-first development for Claude Code, Codex, Opencode, Cursor and beyond.
300,664 starsNousResearch/hermes-agent
The agent that grows with you
262,378 starsmultica-ai/andrej-karpathy-skills
A single CLAUDE.md file to improve Claude Code behavior, derived from Andrej Karpathy's observations on LLM coding pitfalls.
231,784 starsfirecrawl/firecrawl
Supercharge your AI agents with data from the web and beyond. Building the library for superintelligence. 🔥
200,178 stars