
rongxinzy/RongxinAI
rongxinzy/RongxinAI has 162 GitHub stars and 8 forks. GitHot measured 0 stars in 24 hours and +1 in 7 days. Last checked 2026-11-09 21:59 UTC. Last push 2026-11-01.
Open-source desktop AI agent: built-in free model, local GGUF models via llama.cpp, dispatch tasks from WeChat/Feishu/DingTalk. Files, browser & MCP tools. | 开源桌面 AI 智能体:内置免费模型,llama.cpp 本地 GGUF 模型,微信/飞书/钉钉直接派任务。
Measured star growth
- in 24h
- 0
- in 7 days
- +1
- in 15 days
- Update delayed
- in 1 month
- Update delayed
Net star changes over overlapping periods, not daily totals. Missing measurements are left blank. Stars measure attention, not software quality.
README.md
Original
ZhiYuan Agent
The open-source, local-first desktop AI agent — start free with a built-in model, run GGUF models locally, and assign tasks from WeChat, Feishu or DingTalk.
Repo: rongxinzy/RongxinAI · Product: ZhiYuan Agent · Site: rongxzyai.com






⬇️ Download · Quick start · Build from source · 中文
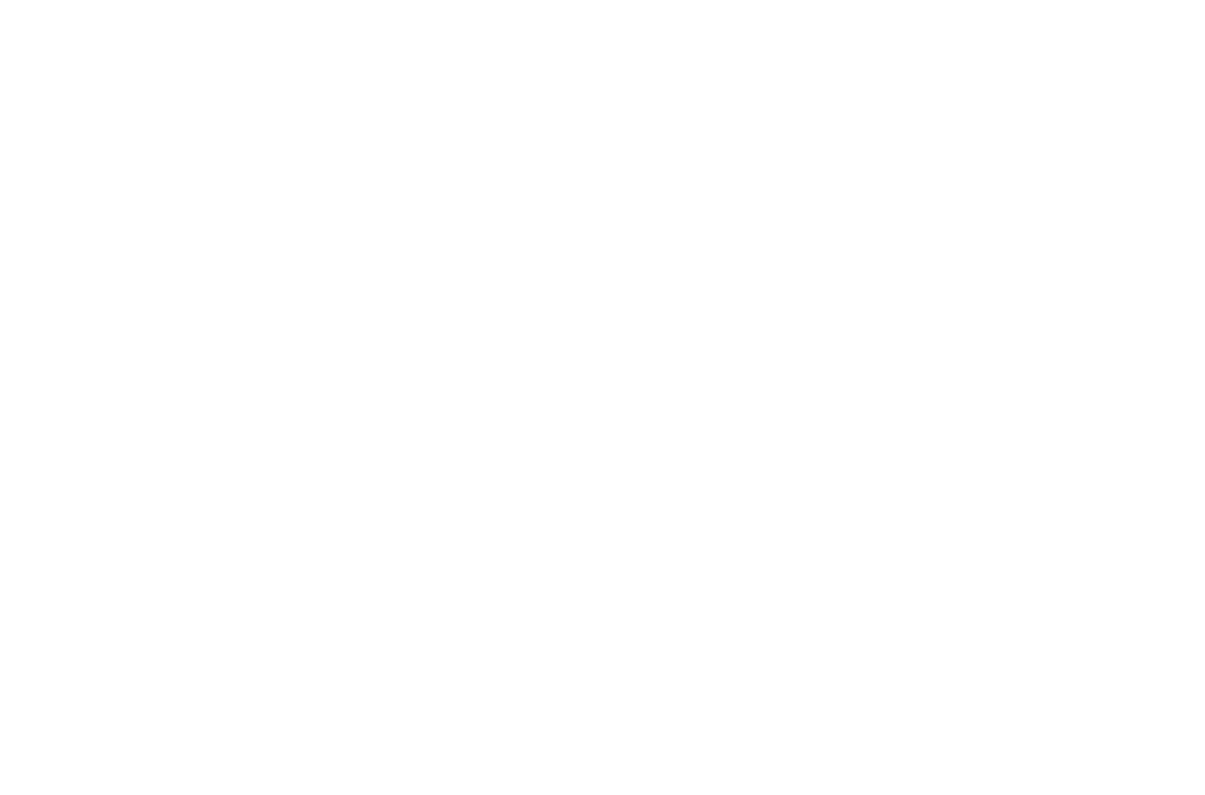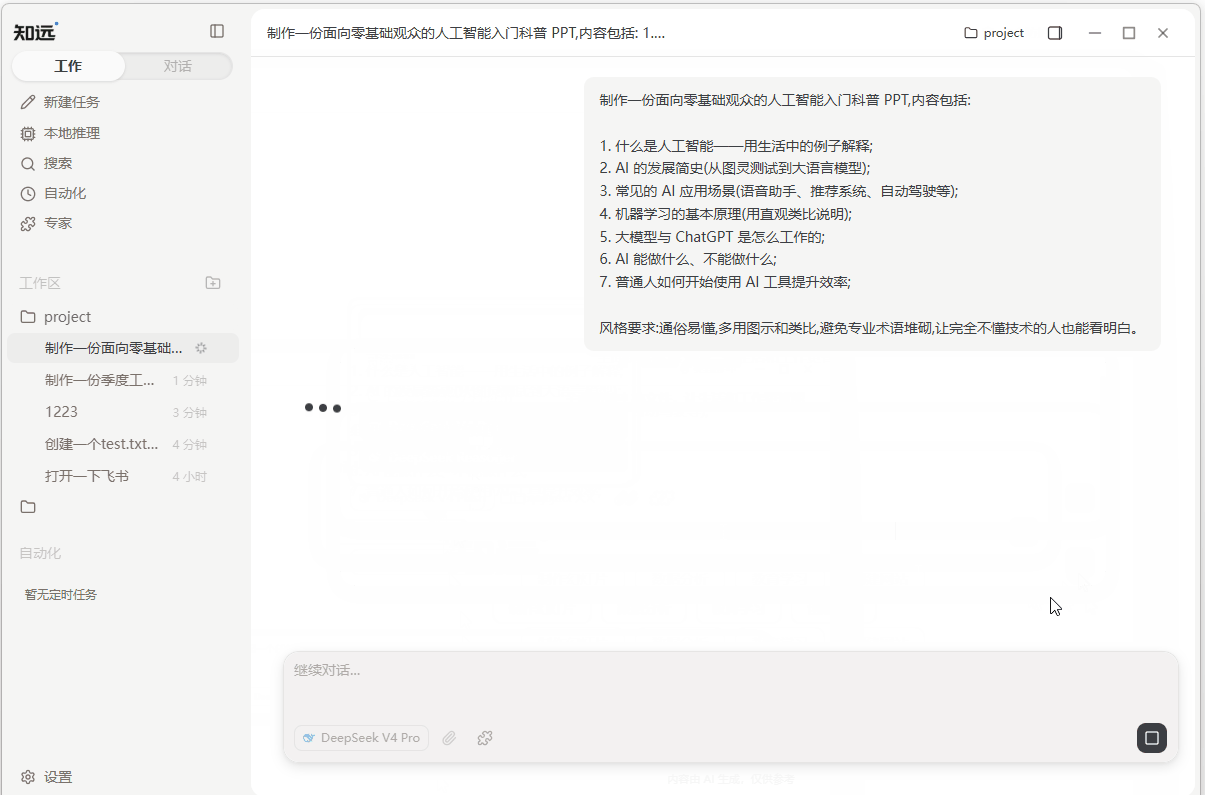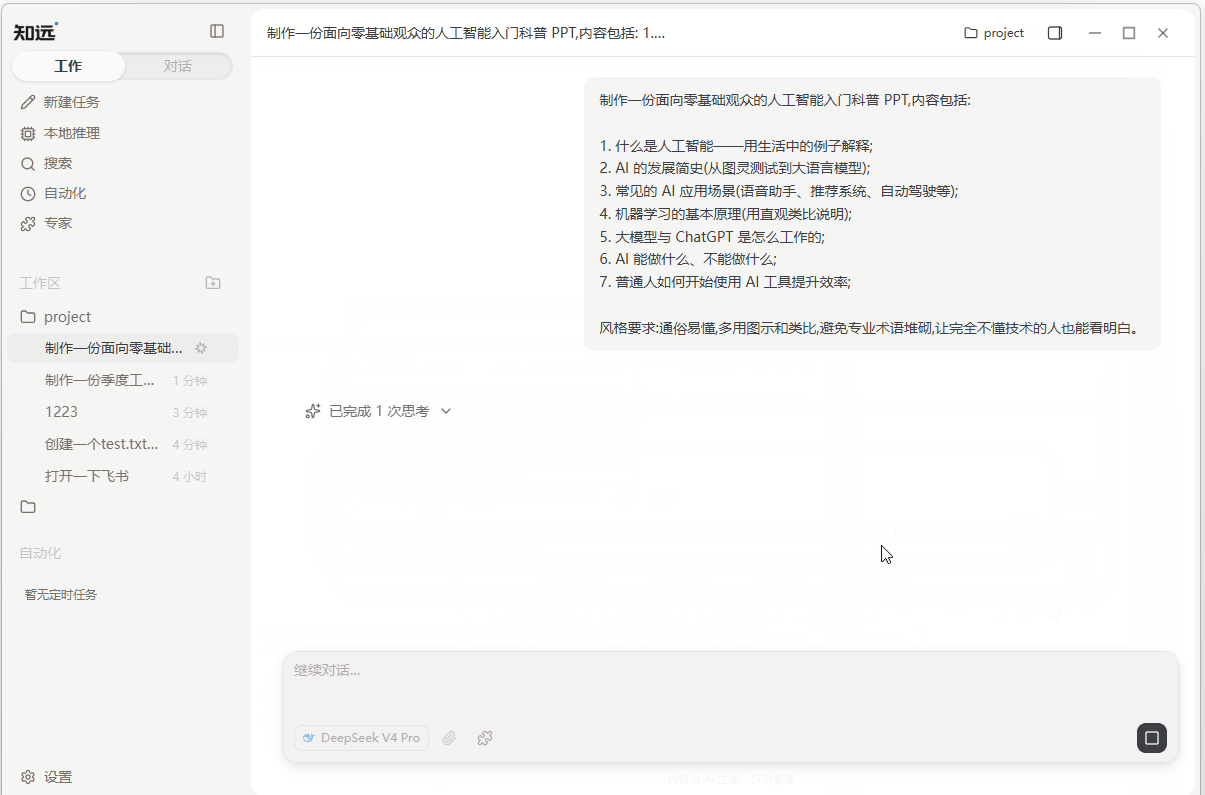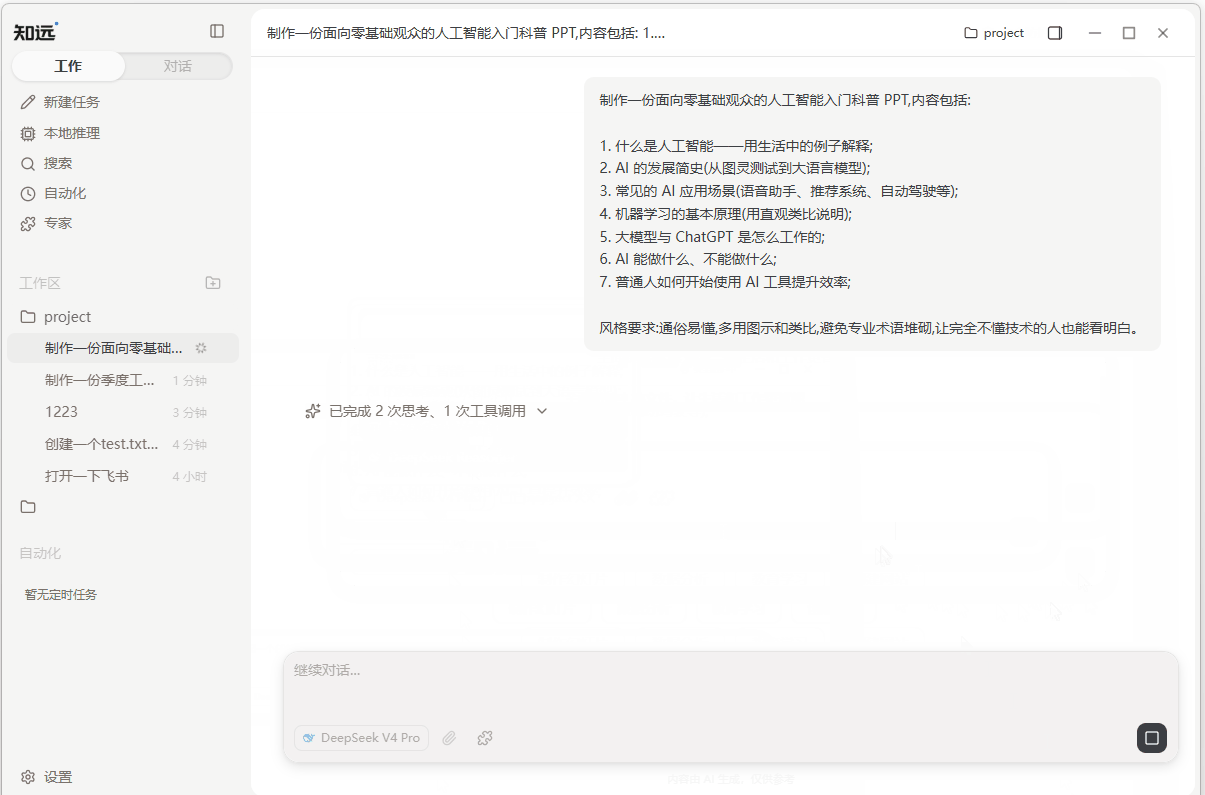
Why ZhiYuan
- 🆓 Free to start — built-in ZhiYuan free model, no third-party API key needed (network required; limits shown in app). Bring your own provider anytime.
- 💻 Runs local models — browse a model marketplace, pick a GGUF model & quantization, tune context / GPU / threads, powered by llama.cpp runtime.
- 🛠️ Actually does the work — reads & writes files, runs commands, operates a browser through the Playwright connector; creates PPT, Word, PDF, Excel outputs.
- 💬 Lives in your chat apps — WeChat, WeCom, DingTalk, Feishu/Lark, QQ, Telegram, Discord; plus an email (IMAP/SMTP) skill.
- 🧩 Extensible — Experts, Skills and MCP; scheduled recurring tasks.
- 🔒 Local first — sessions, config and task metadata stored locally; approval modes for tool execution.
Get started
- Download from the official website or GitHub Releases: Windows x64 lite, CPU, and CUDA installers (
.exe); macOS Apple Silicon and Intel CPU builds (.dmgand.zip); Linux x64 CPU and CUDA packages (.deband AppImage). - Open the app and chat with the built-in free model — no API key required.
- Pick a project folder, describe your task, then follow progress and approve actions as it works.
Developers iterating on the UI can start with bun run web:preview after installation (Node 24.x, Bun 1.4.0). See Developer quick start for setup and desktop development commands.
The free model requires a network connection; availability and usage limits are shown in the app. For architectures or editions without a published installer, run from source.
Use local models
Open the local inference workspace, browse the model marketplace, and choose a GGUF model and quantization suited to your hardware. Install the model and start its service. Adjust context length, GPU allocation, threads, and other options, then use a running local model for agent tasks.
Local models reduce reliance on cloud inference. Web search, model downloads, remote MCP services, and messaging channels still require their respective network services.
Data and permissions
Sessions, configuration, and task metadata are stored locally. The desktop execution environment accesses local files. When you use a cloud model or remote tool, the content needed for that request is sent to the corresponding service.
Tool execution follows the permission mode chosen in the task composer. Ask before sensitive actions (the default) requests your approval before sensitive actions; Allow all runs tool calls without prompting, including irreversible ones. Progress and results remain visible in the workspace.
How it compares
| ZhiYuan | Manus | Claude Desktop | Cherry Studio | Open Interpreter | |
|---|---|---|---|---|---|
| Assign tasks from WeChat / Feishu / DingTalk | ✅ (also WeCom, QQ, email) | ❌ (Slack, Gmail connectors) | ❌ (Slack connector) | ❌ | ❌ |
| Open-source desktop app | ✅ AGPL-3.0 | ❌ closed source | ❌ closed source | ✅ AGPL-3.0 | ❌ Apache-2.0 terminal app; GUI is a separate project |
| Installers for Windows, macOS, and Linux | ✅ | ❌ | ✅ | ✅ | ❌ |
| Built-in GGUF model market (no Ollama needed) | ✅ llama.cpp runtime | ❌ cloud only | ❌ cloud only | ❌ via Ollama / LM Studio | ❌ via Ollama / LM Studio |
| Free model + local model + fully open source | ✅ all three | ❌ free tier only (300 credits/day) | ❌ free tier only | ✅ CherryAI free (Qwen3-8B) + Ollama/LM Studio | ❌ no built-in free model |
| Agent: files + commands + browser | ✅ | ✅ | ✅ paid plans only (Cowork) | ? | ✅ (browser via QA skill) |
⭐ If ZhiYuan helps you, please star the repo — it helps more people find it and keeps us shipping.
Star History
Choose your workspace appearance
ZhiYuan ships one registered theme plugin, Zenith, with paired light and dark appearances. Zenith is a premium futuristic design system: subtle glassmorphism, crisp typography, efficient spacing, and semantic tokens that define backgrounds, control recipes, and interaction states as a single package.
In Settings → Appearance, pick the Zenith preview card (shown when only one plugin is bundled) and choose light, dark, or system mode. The preview follows the selected mode. Configurations that still reference removed theme IDs (Codex, Daming Fenghua, Changan Fengwu, Weiyang Jinshi, and earlier styles) resolve to Zenith automatically.
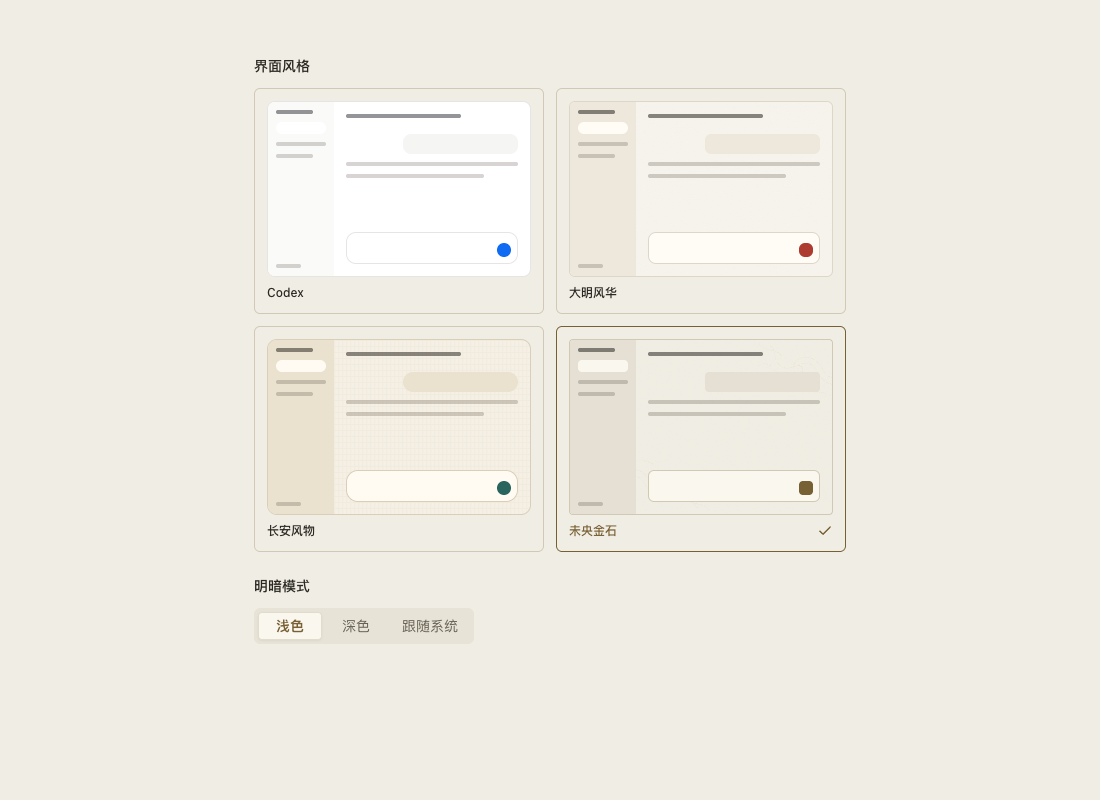
To add another bundled theme later, start with the theme authoring guide and design specification. Theme plugins supply presentation data; shared components retain interaction and state ownership.
Developer quick start
Install Git, Node.js 24.x, and Bun 1.4.0, as pinned in package.json. Native dependencies may require Python and a C/C++ toolchain when prebuilt binaries are unavailable. See the contributing guide for Windows build requirements.
git clone https://github.com/rongxinzy/RongxinAI.git ZhiYuanAgent
cd ZhiYuanAgent
bun install
bun run web:preview
Open the Vite URL in a browser to iterate on the renderer with hot reload, without starting Electron. To verify real desktop and IPC flows, run bun run electron:dev; it prepares the channel and memory runtimes, then starts Vite and Electron. Initial runtime preparation requires network access. Development runs use an isolated ZhiYuanAgentDev (enterprise: ZhiYuanAgentEnterpriseDev) profile so a running dev instance never holds the installed build's single-instance lock; set ZHIYUAN_DEV_SHARED_USER_DATA=1 to reuse the installed profile instead (the two builds then exclude each other). To use local inference, download the inference runtime for your host separately:
bun run llamacpp:runtime:download
To develop the enterprise client from the same clone, run:
bun run electron:dev:enterprise
This builds enterprise/, loads this worktree's extension, and starts the same Vite/Electron development flow. Start AEP separately; the default endpoint is http://localhost:8080. Set ZHIYUAN_AEP_BASE_URL to use another endpoint and optionally ZHIYUAN_AGENT_CONTROL_BASE_URL for split deployments. The command generates development configuration under the ignored .work/enterprise-dev/ directory. To use an existing configuration file instead, set ZHIYUAN_ENTERPRISE_CONFIG_DEV_PATH. Packaged applications always use their bundled configuration and ignore this development override. Rerun the command after changing enterprise sources to rebuild the extension and its renderer.
Useful commands
| Command | Purpose |
|---|---|
bun run build |
Typecheck, build production assets, and verify runtime dependencies |
bun run test |
Run the project test script with native-module preparation and Electron dependency restoration |
bun run lint |
Check code, generated theme consistency, and style ownership |
bun run format:check |
Check formatting |
bun run test:bundle-budget |
Check the built renderer's bundle size |
bun run theme:generate |
Regenerate CSS after changing theme definitions |
bun run compile:electron |
Compile the Electron main process, including native dependency preparation |
Packaging
Every installer bundles a pinned model gateway that is built from source with an exact Go SDK before packaging. See CONTRIBUTING.md for the prerequisites and build commands.
Editions
The edition is selected with ZHIYUAN_UPDATE_VARIANT and decides which bundled llama.cpp runtime ships. All editions bundle the offline components; nothing is downloaded on demand.
| Edition | Platforms | Bundled local inference |
|---|---|---|
lite |
Windows x64 only | None (no llama.cpp) |
cpu |
Windows x64, Linux x64, macOS arm64 and x64 | llama.cpp CPU + Vulkan on Windows/Linux; Metal on macOS |
cuda |
Windows x64, Linux x64 | llama.cpp built for RTX 40 (sm_89) with CUDA 12.4, the CUDA runtime libraries it needs, and a CPU fallback. Windows x64 cuda also bundles the Strata dual-engine (Qwen + DeepSeek CUDA13 engines + control runtime); see STRATA-DUAL-ENGINE.md. |
| Command | Output |
|---|---|
bun run dist:win / dist:win:offline / dist:win:lite |
Unsigned Windows x64 lite build: the WebView2 installer ZhiYuanAgent-Setup-<version>.exe plus the NSIS updater |
bun run dist:win:cpu / dist:win:cuda |
Same, cpu or cuda edition |
bun run dist:win:signed / dist:win:signed:cpu / dist:win:signed:cuda |
Certum-signed lite / cpu / cuda; requires CERTUM_CERT_THUMBPRINT, used by the release workflow |
bun run dist:linux:cpu / dist:linux:cuda |
Linux deb + AppImage, cpu or cuda (dist:linux:cuda compiles the CUDA llama-server locally with scripts/build-llamacpp-cuda-rtx40.sh) |
bun run dist:mac:arm64 / dist:mac:x64 |
macOS packages; the release workflow builds them as the cpu edition |
Packaging also involves platform runtimes, resources, and signing configuration; see CONTRIBUTING.md, RELEASING.md, and package.json.
Project map
| Path | Responsibility |
|---|---|
src/renderer |
React workspace, conversations, settings, and local inference UI |
src/shared |
Shared UI, types, and communication contracts |
src/main |
Desktop lifecycle, task execution, storage, and system services |
src/main/preload.ts / src/main/preload/ |
Controlled IPC through contextBridge, grouped by domain under preload/ |
src/renderer/theme |
Theme contracts, component appearance, backgrounds, and generation |
SKILLs / MCPs |
Bundled skills and tool integrations |
.github/workflows |
Tests, installer validation, and releases |
The stack includes Electron, React, TypeScript, Vite, Tailwind CSS, Redux Toolkit, and SQLite. Refer to package.json and bun.lock for dependency versions.
Desktop architecture
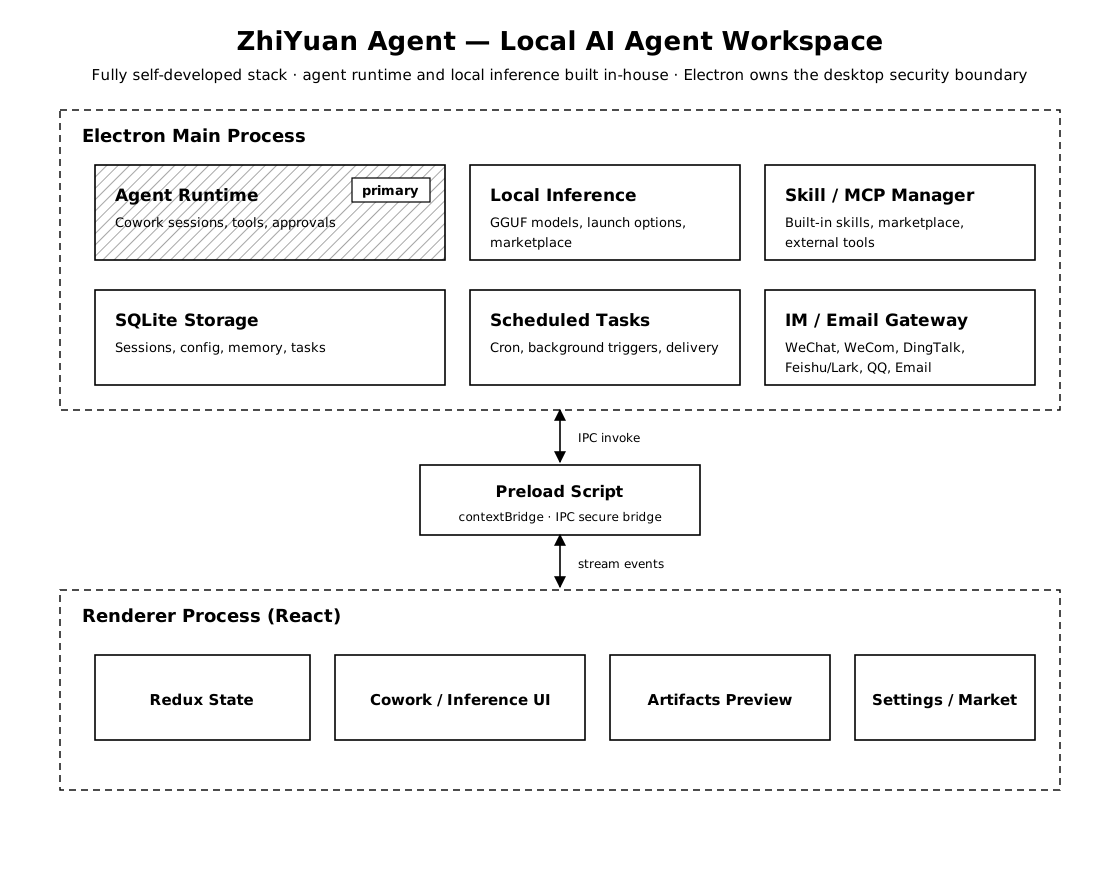
The renderer owns the UI, preload provides the communication boundary, and the main process owns sessions, execution, data, and service lifecycles. Task messages, tool status, and approval requests stream back to the UI. Dedicated services manage local inference, skills, MCP, and messaging channels.
Browser preview mode
Preview the renderer in a plain browser without Electron:
bun run web:preview
This starts a Vite dev server on port 5176 with a typed mock of the Electron preload API. Use it as the fast path for day-to-day renderer UI changes: hot reload, browser developer tools, responsive layouts, themes, and interactions. bun run web:preview:check runs Playwright against that server in light and dark (sessions, a streamed reply, every settings panel, skills, MCP, automation, local inference, IM, and dialogs) and fails on console errors. bun run preview:doc-screenshots writes 1280×800 documentation PNGs to docs/theme-previews/ (main interface, appearance, platform models, local inference). The mock covers the full preload contract: unimplemented calls return a typed default and warn once.
The mock is only active in browser mode (import.meta.env.DEV + no window.electron). Production builds and Electron runs use the real preload bridge. Verify affected IPC, system, native-window, and end-to-end behavior with bun run electron:dev; browser preview does not exercise those integrations. See CONTRIBUTING.md for the UI workflow.
Contribute
- Good first issues — best place to start
- Discussions — questions and showcases (not for bugs)
- Report a bug
- Suggest a feature
- Contributing guide · Code of Conduct ·
AGENTS.md - Security policy — report vulnerabilities privately; do not open public issues for unfixed security bugs
Star the repository to follow the project, or share a workflow in Discussions.
Acknowledgments and license
Thanks to AnySearch for supporting the built-in web search capability. Its integration lives in SKILLs/web-search.
ZhiYuan Agent is licensed under the GNU Affero General Public License v3.0.
Explore related projects
affaan-m/ECC
The agent harness performance optimization system. Skills, instincts, memory, security, and research-first development for Claude Code, Codex, Opencode, Cursor and beyond.
300,313 starsNousResearch/hermes-agent
The agent that grows with you
262,134 starsmultica-ai/andrej-karpathy-skills
A single CLAUDE.md file to improve Claude Code behavior, derived from Andrej Karpathy's observations on LLM coding pitfalls.
231,460 starsfirecrawl/firecrawl
Supercharge your AI agents with data from the web and beyond. Building the library for superintelligence. 🔥
200,178 stars