
rhyang2021/CogRouter
rhyang2021/CogRouter has 26 GitHub stars and 5 forks. GitHot measured 0 stars in 24 hours. Last checked 2026-11-15 01:14 UTC. Last push 2026-02-20.
Measured star growth
- in 24h
- 0
- in 7 days
- Collecting history
- in 15 days
- Collecting history
- in 1 month
- Collecting history
Net star changes over overlapping periods, not daily totals. Missing measurements are left blank. Stars measure attention, not software quality.
About
Source code for our paper: "Think Fast and Slow: Step-Level Cognitive Depth Adaptation for LLM Agents".
AIREADME.md
OriginalThink Fast and Slow: Step-Level Cognitive Depth Adaptation for LLM Agents
1Fudan University 2Tencent Hunyuan


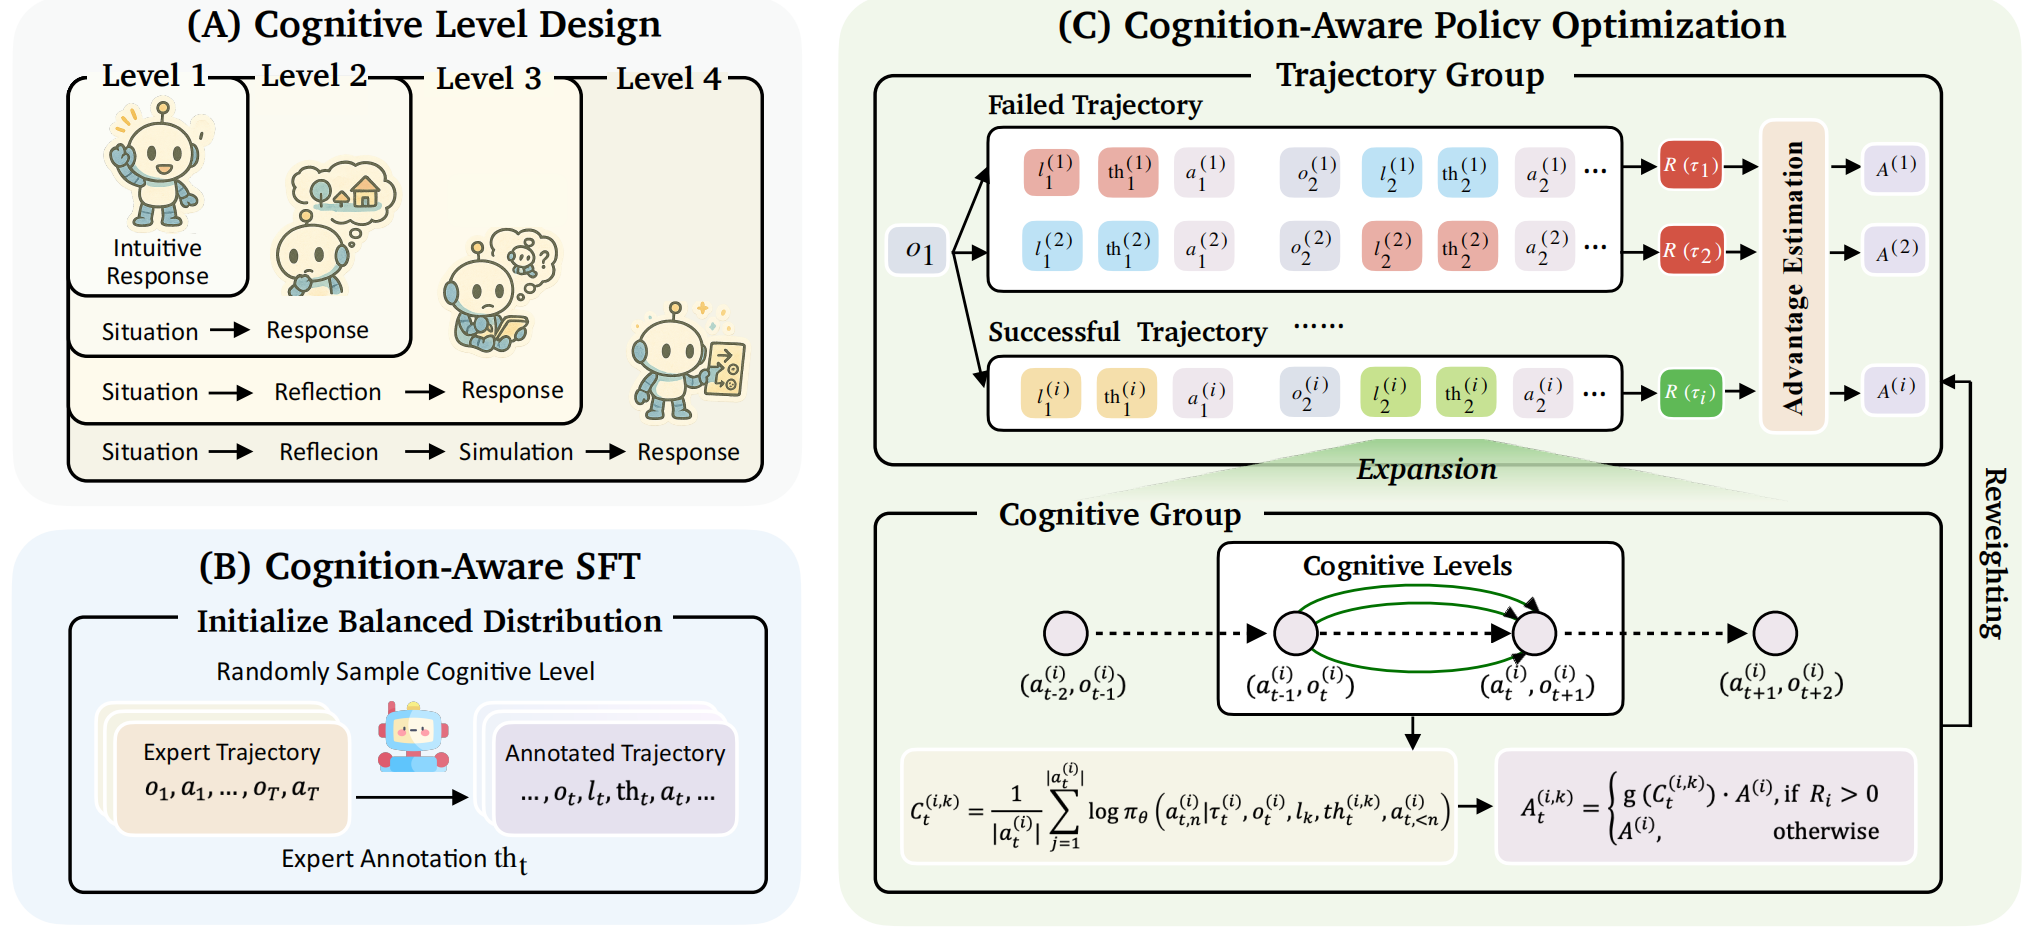
CogRouter trains agents to dynamically adapt cognitive depth at each step. Grounded in ACT-R theory, we design four hierarchical cognitive levels ranging from instinctive responses to strategic planning, and propose Cognition-aware Policy Optimization (CoPo) for step-level credit assignment via confidence-aware advantage reweighting.
Environment Setup
pip install -r requirements.txt
We recommend maintaining a separate conda environment for each environment.
ALFWorld
conda create -n copo-alfworld python=3.10 -y
conda activate copo-alfworld
pip install gymnasium==0.29.1
pip install stable-baselines3==2.6.0
pip install alfworld
Download PDDL & Game files (by default saved in ~/.cache/alfworld/):
alfworld-download -f
ScienceWorld
conda create -n copo-sciworld python=3.10 -y
conda activate copo-sciworld
pip install scienceworld
Install verl and related dependencies:
pip install -e .
Start Training
RL Training
bash examples/copo_trainer/run_alfworld.sh
bash examples/copo_trainer/run_sciworld.sh
Customize
Cognitive Level Prompts: Define or modify the hierarchical thinking level templates (Level 2–4) in
copo/prompt.py.CoPo Advantage Computation: Adjust the confidence-aware advantage reweighting logic in
copo/core_copo.py.New Environments:
- Create your environment package in
agent_system/environments/env_package/, following the gym interface with multi-threading support. - Write corresponding prompts in
agent_system/environments/prompts/. - Add an environment manager in
agent_system/environments/env_manager.py.
- Create your environment package in
Acknowledgement
We sincerely appreciate the infrastructure provided by veRL and verl-agent. We also thank ALFWorld, ScienceWorld, and other projects for offering interactive agent environments.
If you have any questions, please feel free to email me or drop me an issue.