
punit2911/MedQueryDoc-AI-Intelligent-Medical-Document-Assistant
punit2911/MedQueryDoc-AI-Intelligent-Medical-Document-Assistant has 60 GitHub stars and 0 forks. GitHot measured -1 stars in 24 hours. Last checked 2026-11-16 22:26 UTC. Last push 2026-11-14.
What you can do
- PDF-based medical document ingestion
- Vector similarity search using Pinecone
- Retrieval-Augmented Generation (RAG) pipeline
- Local LLaMA-2 model inference
Measured star growth
- in 24h
- -1
- in 7 days
- Collecting history
- in 15 days
- Collecting history
- in 1 month
- Collecting history
Net star changes over overlapping periods, not daily totals. Missing measurements are left blank. Stars measure attention, not software quality.
About
AI-powered medical document chatbot using LLaMA-2 and LangChain, enabling semantic search and question answering over PDF files via Pinecone vector indexing and a Flask-based interface.
AIREADME.md
Original🩺 MedQueryDoc AI
Intelligent Medical Document Assistant (LLaMA-2)
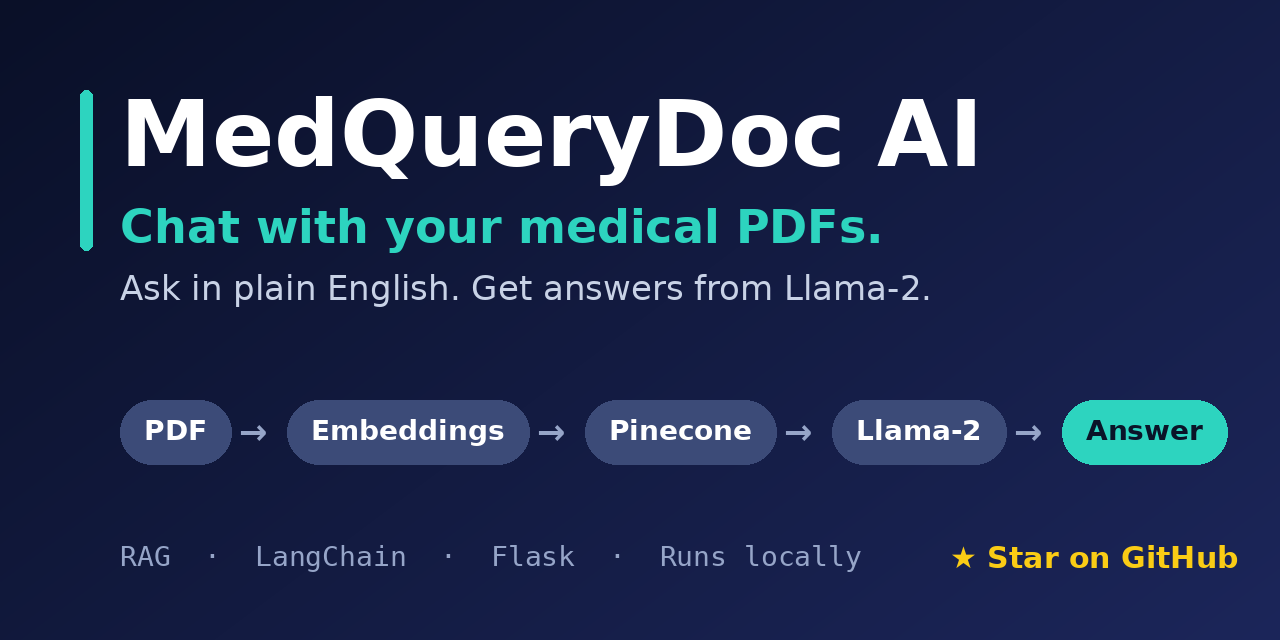
Chat with your medical PDFs. Ask in plain English. Get answers grounded in your documents.


📌 About the Project
This project is an AI-powered medical document question-answering system built using Large Language Models (LLMs) and vector-based information retrieval. It enables users to ask natural language questions and receive accurate, context-aware answers derived from medical PDF documents.
The system works by loading and splitting PDF documents into smaller chunks, generating vector embeddings using a Hugging Face embedding model, and storing them in Pinecone, a scalable vector database. During inference, user queries are matched against relevant document chunks using similarity search, and responses are generated using LLaMA-2 through a retrieval-augmented generation (RAG) pipeline.
This project demonstrates practical implementation of LLMs + LangChain + Vector Databases for real-world AI applications.
🧠 Key Features
- PDF-based medical document ingestion
- Vector similarity search using Pinecone
- Retrieval-Augmented Generation (RAG) pipeline
- Local LLaMA-2 model inference
- Interactive web interface using Flask
- Modular and extensible architecture
⚡ How It Works
PDF → Embeddings → Pinecone → LLaMA-2 → Answer
| Phase | Command | What happens |
|---|---|---|
| 1. Index once | python store_index.py |
Loads PDFs, splits text into chunks, generates embeddings, stores vectors in Pinecone |
| 2. Ask anytime | python app.py |
Retrieves the most relevant chunks and generates an answer with LLaMA-2 |
🛠️ Built With
- Python
- LangChain
- Flask
- Meta LLaMA-2
- Pinecone (Vector Database)
- Hugging Face Embeddings
🚀 Getting Started
Follow the steps below to set up and run the project locally.
⚙️ Installation Steps
1️⃣ Clone the Repository
git clone https://github.com/<your-username>/MedQueryDoc-AI-Intelligent-Medical-Document-Assistant.git
cd MedQueryDoc-AI-Intelligent-Medical-Document-Assistant
2️⃣ Create a Virtual Environment (Recommended)
If Conda is installed:
conda create -p ./venv python=3.10 -y
conda activate ./venv
Or using Python venv:
python -m venv venv
venv\Scripts\activate        # Windows
source venv/bin/activate     # macOS / Linux
3️⃣ Install Dependencies
pip install -r requirements.txt
🔐 API Key Setup
Create a .env file in the root directory and add your Pinecone credentials:
PINECONE_API_KEY=your_pinecone_api_key_here
⚠️ Note: Pinecone no longer requires an environment variable (
PINECONE_API_ENV) in the new SDK.
📄 Add Medical Documents
Create a data/ folder in the project root and add your PDF files:
data/
├── medical_doc_1.pdf
├── medical_doc_2.pdf
🧠 Model Setup
Download the quantized LLaMA-2 model and place it inside the model/ directory:
Model: llama-2-7b-chat.ggmlv3.q4_0.bin
Source: https://huggingface.co/TheBloke/Llama-2-7B-Chat-GGML
🧬 Index Documents into Pinecone
Before running the chatbot, index the documents:
python store_index.py
This step:
- Loads PDFs
- Splits text into chunks
- Generates embeddings
- Stores vectors in Pinecone
▶️ Run the Application
python app.py
Then open your browser and visit:
http://localhost:8080
🏗️ Project Architecture
├── app.py                 # Flask application
├── store_index.py         # PDF ingestion & vector indexing
├── src/
│   ├── helper.py          # PDF loading, chunking, embeddings
│   ├── prompt.py          # Prompt template
├── model/
│   └── llama-2-7b-chat.ggmlv3.q4_0.bin
├── templates/
│   └── chat.html
├── static/
│   └── style.css
├── assets/
│   └── social-preview.png # Demo banner used in this README
├── data/                  # PDF documents
└── .env
🚧 Future Enhancements
- Multilingual medical support
- Source citation in answers
- Document upload via UI
- Streaming responses
- Cloud-hosted inference
- Authentication & access control
⚠️ Disclaimer
This project is for informational and educational purposes only. It is not a medical device and is not a substitute for professional medical advice, diagnosis, or treatment. Always consult a qualified healthcare professional.
📜 License
This project is licensed under the GNU General Public License v3.0.
See the LICENSE file for more details.
⭐ Acknowledgements
This project builds upon open-source tools and research in the fields of LLMs, NLP, and vector databases. Special thanks to the open-source community for enabling practical AI innovation.
If you found this project useful, please ⭐ star the repo!