
pablocaeg/sloptotal
pablocaeg/sloptotal has 118 GitHub stars and 44 forks. GitHot measured +3 stars in 24 hours and +15 in 7 days. Last checked 2026-11-15 15:52 UTC. Last push 2026-11-03.
What you can do
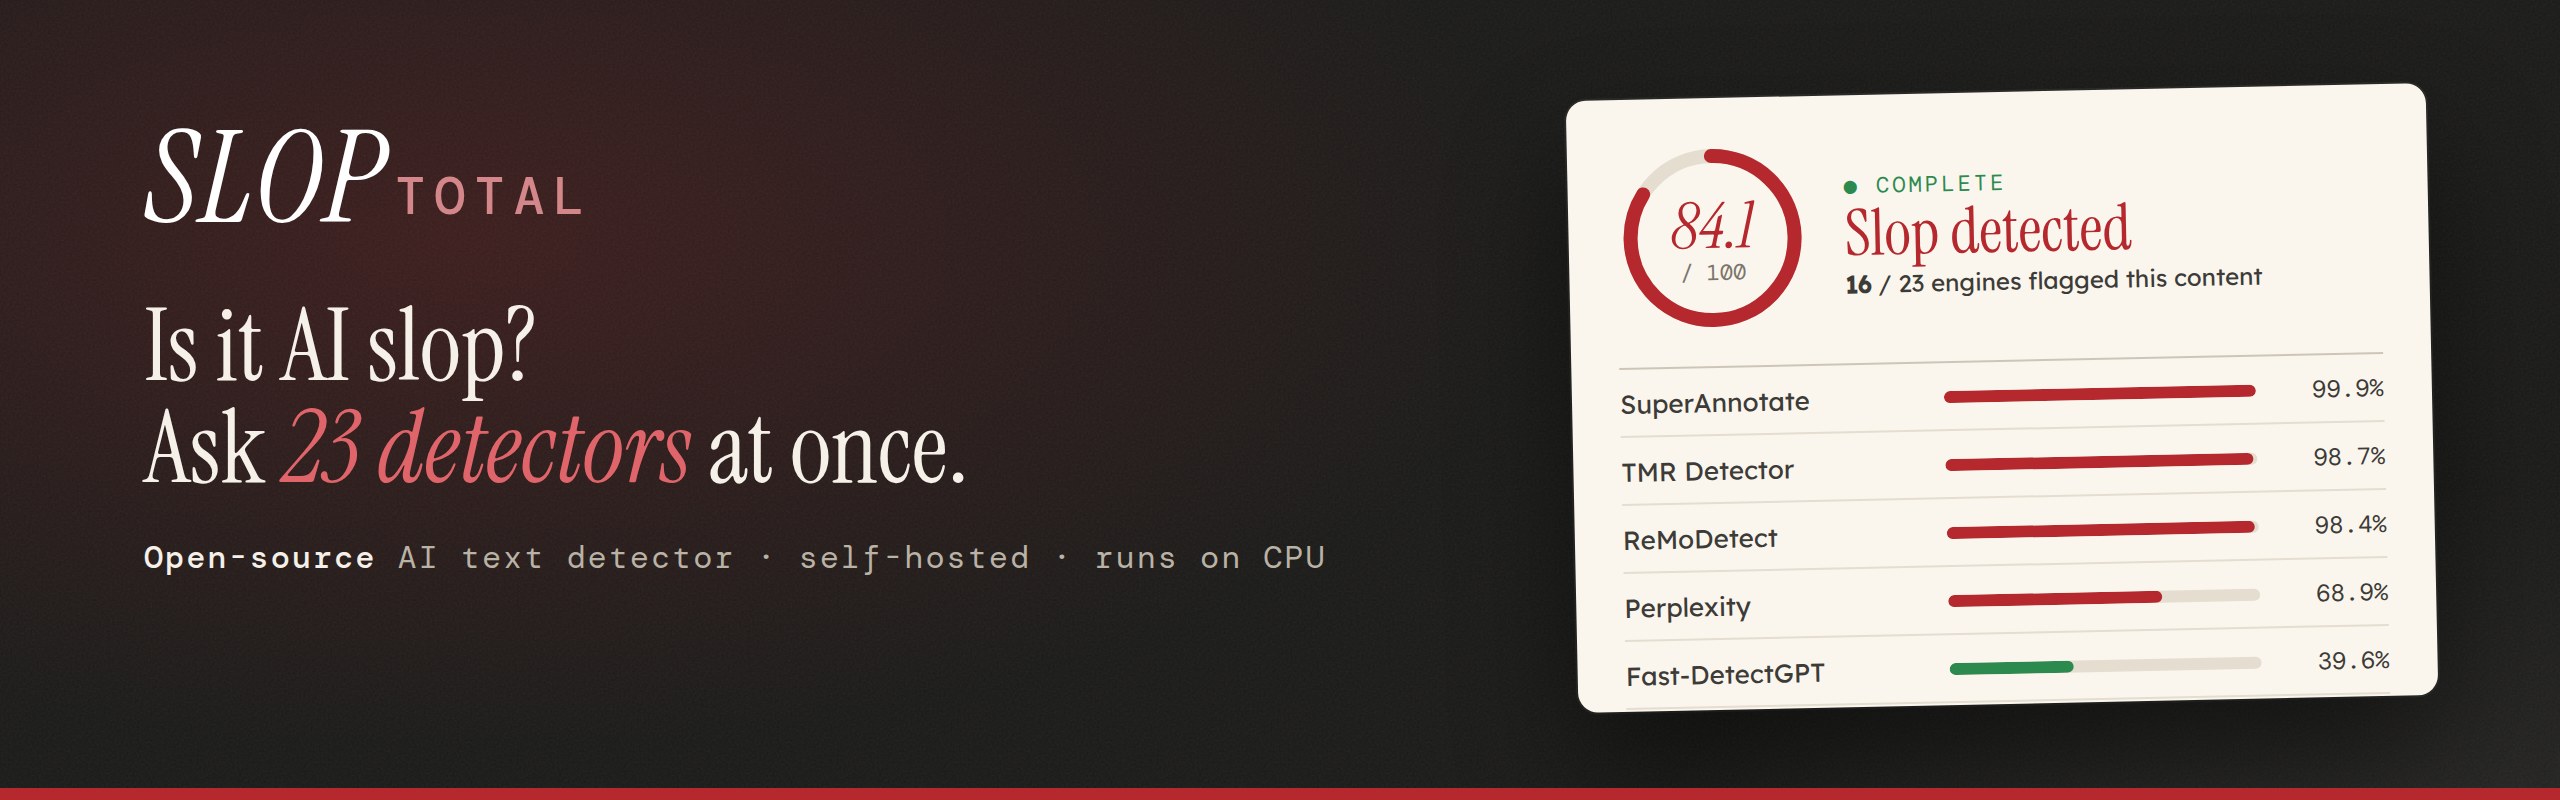
- 23 detection engines, one calibrated score. DeBERTa and RoBERTa classifiers, Binoculars, Fast-DetectGPT, GLTR, perplexity and burstiness tests, and stock-phrase heuristics. Results stream in as each engine finishes.
- Text, URLs and documents. Paste text, scan a web page (main content is extracted automatically), or upload .pdf, .docx, .txt or .md.
- Site check: was this website vibe-coded? Finds the fingerprints that Lovable, v0, Bolt, Base44, Replit, Same and Emergent leave in the sites they deploy, and shows the evidence for each one. How it works
- Per-paragraph heat map through the API, to see which parts read as AI.
Measured star growth
- in 24h
- +3
- in 7 days
- +15
- in 15 days
- Update delayed
- in 1 month
- Update delayed
Net star changes over overlapping periods, not daily totals. Missing measurements are left blank. Stars measure attention, not software quality.
About
Open-source AI text detector and ChatGPT detector: 23 engines, one calibrated score, every number measured on a public benchmark. Self-hosted, runs on CPU.
AIREADME.md
Original




English · 简体中文 · Русский · Español
SlopTotal
VirusTotal for AI-generated text. Paste text, drop in a PDF or Word file, or give it a URL. Twenty-three independent AI detectors (neural classifiers, statistical tests and linguistic heuristics) score it in parallel, and a calibrated ensemble turns their votes into one verdict you can inspect engine by engine. It runs on your own CPU, so nothing you scan leaves your machine.
It is a free, self-hosted, open-source alternative to hosted AI content detectors such as GPTZero, Originality.ai, Copyleaks, ZeroGPT and Humalingo. Instead of one number from one model, it shows you every model's opinion, and it publishes how accurate that is, failures included.
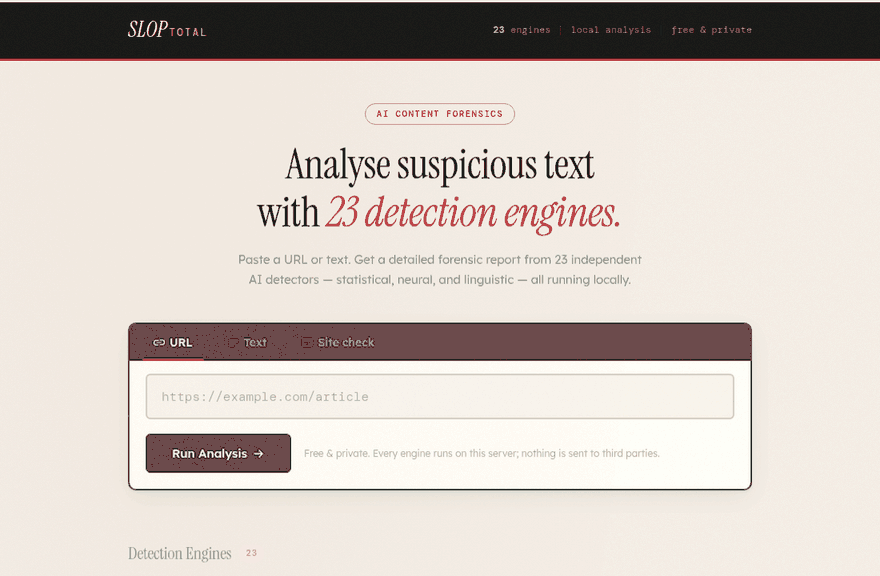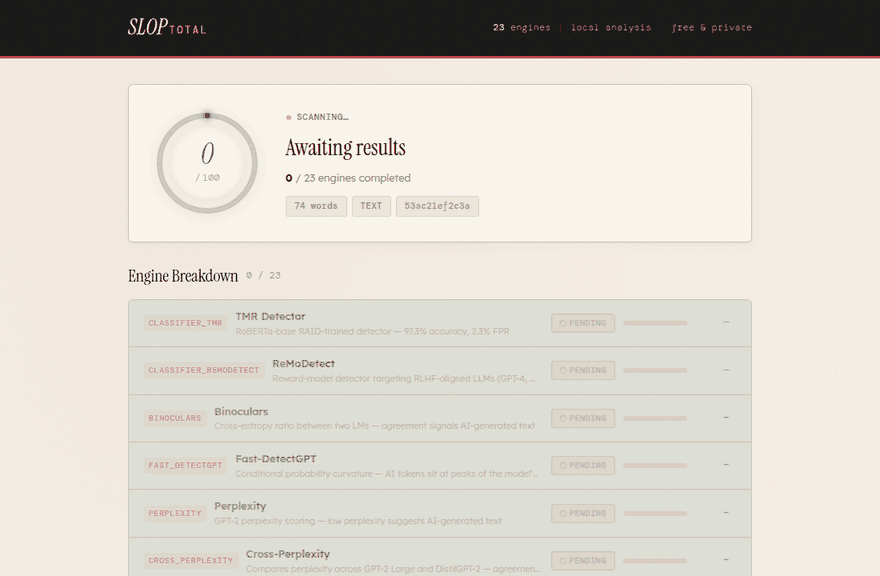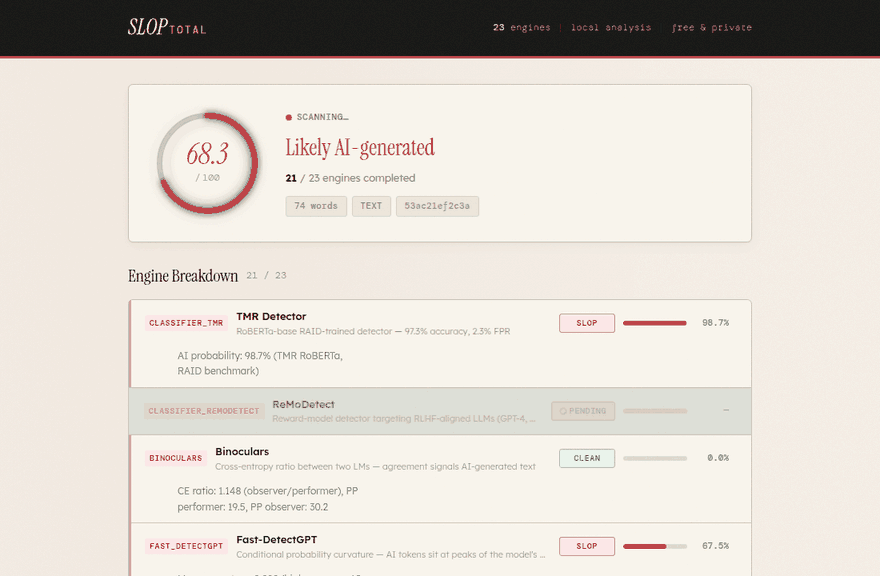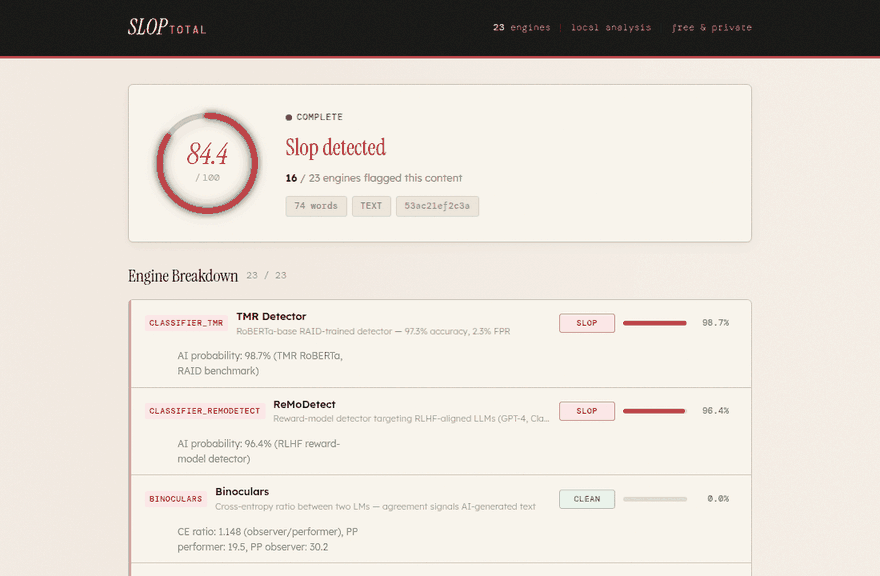
Try it: sloptotal.com · Run it: docker run -p 8000:8000 ghcr.io/pablocaeg/sloptotal
Features
- 23 detection engines, one calibrated score. DeBERTa and RoBERTa classifiers, Binoculars, Fast-DetectGPT, GLTR, perplexity and burstiness tests, and stock-phrase heuristics. Results stream in as each engine finishes.
- Text, URLs and documents. Paste text, scan a web page (main content is
extracted automatically), or upload
.pdf,.docx,.txtor.md. - Site check: was this website vibe-coded? Finds the fingerprints that Lovable, v0, Bolt, Base44, Replit, Same and Emergent leave in the sites they deploy, and shows the evidence for each one. How it works
- Per-paragraph heat map through the API, to see which parts read as AI.
- Measured, not claimed. Every accuracy number below comes with the corpus, the harness and the raw per-sample scores.
- Private by default. Self-hosted, no third-party AI APIs, no tracking, reports deleted after 30 days.
- CPU-only is fine. Auto-detects your hardware; a GPU is optional. Loaded models need about 8.3 GB of RAM (an estimate; see docs/MODELS.md).
- JSON API and a Chrome extension that marks AI-looking results in Google Search and LinkedIn.
Measured accuracy
Most detectors publish an accuracy figure without saying what it was measured on. SlopTotal is measured on SlopBench: 1,626 human texts, every one written before ChatGPT, and 1,626 AI texts on the same topics and at the same lengths from 14 current models, across 15 kinds of writing (news, Wikipedia, arXiv, Stack Exchange, Reddit, reviews, student essays, non-native English, fiction and literature published 1532-1915). Every number below is measured on kinds of writing the model was not tuned on.
| AUC | 0.942 |
| AI texts called "Likely AI" (55+) | 67% |
| Human texts called "Likely AI" (55+) | 1.7% |
| Human texts flagged at all (45+) | 3.9% |
| Literature published 1532-1915 flagged | 0 of 87 |
The score bands are anchored on that human text: 45 is where the top 5% of human writing begins, 55 the top 2%, 80 the top 0.5%. So "Likely AI" means fewer than 2 in 100 human texts score this high.
Other languages. Spanish, French, German, Italian, Portuguese, Dutch, Polish, Russian and Japanese are supported (AUC 0.91 to 0.997); Arabic and Korean are experimental; Hindi, Turkish and Chinese are not reliable yet, and the report says so.
What does not work. Essays by non-native English writers are still flagged more than native ones (15% of TOEFL essays called Likely AI, against none of 88 US school essays). Under about 80 words a score is a weak signal. AI text run through a "humanizer" is caught about half the time. Source code is outside what these engines do. All of it, per source, per model and per engine, is in the findings, including that the classifiers which top the RAID benchmark drop to AUC 0.75 on current models.
Quick start
Docker (fastest)
docker run -p 8000:8000 -v sloptotal-models:/app/models ghcr.io/pablocaeg/sloptotal
Open http://localhost:8000. The first scan downloads about 9 GB of models
(see docs/MODELS.md) into the sloptotal-models volume, so
later starts are quick. To build from source instead, run
docker compose -f docker/docker-compose.yml up.
From source
Requires Python 3.10+ (macOS ships 3.9, which is too old).
git clone https://github.com/pablocaeg/sloptotal.git
cd sloptotal
python3.11 -m venv venv && source venv/bin/activate
pip install -r requirements.txt
./scripts/start.sh    # or: uvicorn app.main:app --port 8000
Check that every engine loads and scores, end to end:
python scripts/smoke_test.py # against http://localhost:8000
Site check: detect sites built with AI app builders
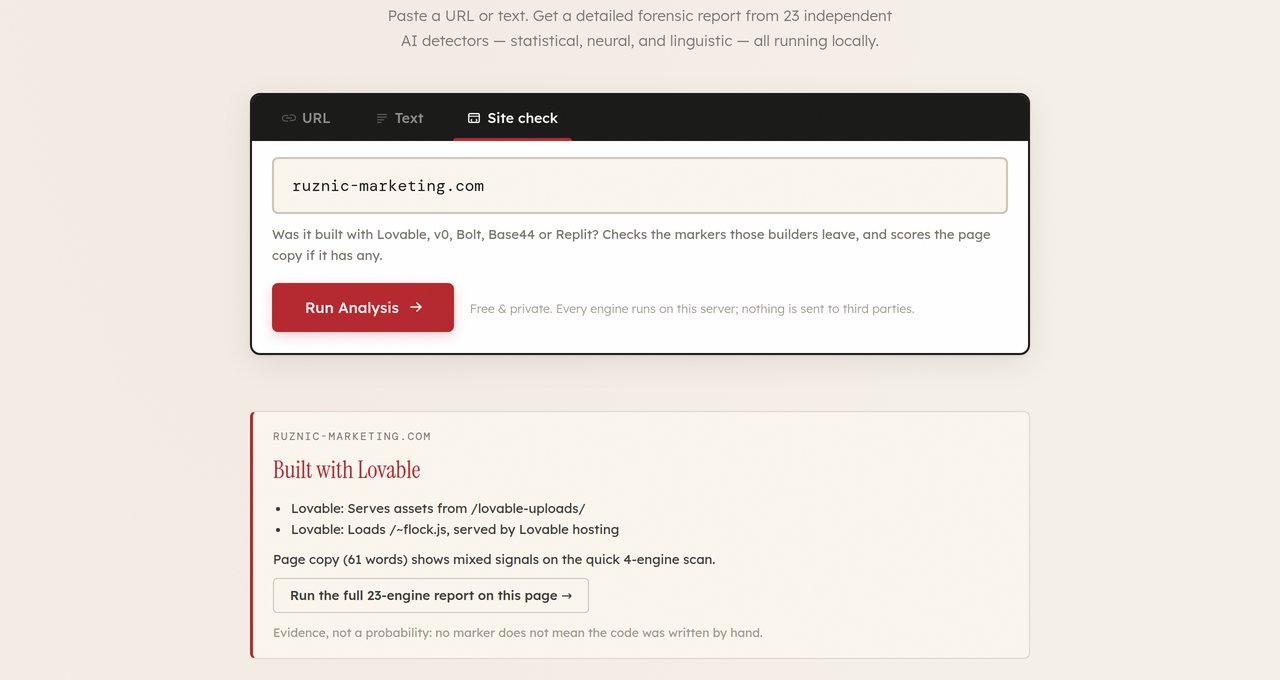
"Is this website vibe-coded?" checkers mostly score style (Tailwind class counts, missing security headers, buzzwords) and turn it into a percentage. Hand-written sites share all of those traits. SlopTotal looks only for markers the builders themselves leave in what they deploy, each one confirmed on live sites or in the builders' own templates:
| Builder | Fingerprints |
|---|---|
| Lovable | gptengineer.js runtime, /lovable-uploads/ assets, the Lovable badge, /~flock.js, *.lovable.app |
| v0 (Vercel) | <meta name="generator" content="v0.app"> from v0's layout template, *.vusercontent.net |
| Bolt | X-Powered-By: Bolt.new header, bolt.new/badge.js, *.bolt.host |
| Base44 | app.base44.com platform calls, base44_access_token, *.base44.app |
| Replit | Replit Agent dev banner, Replit badge, *.replit.app |
| Same | assets served from same-assets.com |
| Emergent | __emg_sid and __emg_vid cookies, emergent-main.js script, *.emergent.host |
A site with no marker may still have been written with AI: code exported from these tools and hosted elsewhere, or written in an AI editor, carries no fingerprint. So the result is evidence, not a probability. The page's copy is scored separately by the text engines.
curl -X POST http://localhost:8000/api/scan/site \
  -H "Content-Type: application/json" -d '{"url": "example.com"}'
API
| Endpoint | Method | What it does | Typical latency (CPU) |
|---|---|---|---|
/api/analyze |
POST | Full 23-engine report for text or url |
2-8 s |
/api/quick-score |
POST | 4 classifiers plus heuristics | 0.1-0.5 s |
/api/paragraph-score |
POST | Score per paragraph (heat map) | 1-3 s |
/api/scan/site |
POST | AI app builder fingerprints plus a copy score | 1-3 s |
/api/extract |
POST | Text from an uploaded .pdf / .docx / .txt (multipart file) |
< 1 s |
/api/scan/snippets |
POST | Batch of 1-30 short snippets | ~0.5 s |
/api/scan/urls |
POST | Batch of 1-10 URLs, page-type aware | 1-5 s |
/api/engines |
GET | Engine metadata | instant |
/api/report/{id} |
GET | A stored report | instant |
/api/report/{id}/feedback |
POST | Record who actually wrote the text: {"label": "human" | "ai" | "mixed" | "unsure"} |
instant |
/api/queue/status |
GET | Queue capacity | instant |
curl -X POST http://localhost:8000/api/analyze \
  -H "Content-Type: application/json" \
  -d '{"text": "Your text to analyze here..."}'
From Python, examples/python_client.py analyses a
text, prints the five engines scoring highest and runs a site check, waiting
in the queue when the server is busy:
python examples/python_client.py "Paste at least 50 characters of text here..." example.com
The response lists every engine with its score, verdict and a plain-language
detail line, plus overall_score (0-100) and overall_verdict.
From Node 18+, examples/node_client.mjs uses the
built-in fetch to analyse a text and print the overall score, the verdict and
the five engines scoring highest. Pass --base to point it at another server:
node examples/node_client.mjs "Paste at least 50 characters of text here..." --base http://localhost:8000
Detection Engines
Every engine links to its page on sloptotal.com, which carries its measured scores against both corpora. AUC below is the probability the engine ranks a random AI passage above a random human one: 1.0 is perfect, 0.5 is a coin flip.
Neural Classifiers
| Engine | Model | AUC | Notes |
|---|---|---|---|
| Desklib DeBERTa | DeBERTa-v3-large (435M) | 1.000 | Strongest separation in our own tests |
| SuperAnnotate | RoBERTa-large (355M) | 0.989 | No measurable bias against archaic prose |
| E5-Small | E5 + LoRA (33M) | 0.999 | Matches far larger models at 33M params |
| TMR Detector | RoBERTa-base (125M) | 1.000 | RAID-trained, so RAID scores flatter it |
| BERT-tiny RAID | BERT-tiny (4.4M) | 1.000 | Answers in milliseconds |
| ReMoDetect | DeBERTa (184M) | 0.941 | Targets RLHF-aligned LLMs |
| ChatGPT Detector | RoBERTa-base (125M) | 0.829 | ChatGPT-specific |
| Fakespot | RoBERTa-base (125M) | 0.999 | Accurate on modern text, but +0.533 bias on pre-1920 prose |
| OpenAI Detector | RoBERTa-base (125M) | 0.771 | The 2019 GPT-2 detector; weaker on modern LLMs |
Statistical Methods
| Engine | Method | AUC |
|---|---|---|
| Log-Rank | Average log-rank under GPT-2 | 0.909 |
| GLTR | Token rank distribution | 0.904 |
| Perplexity | GPT-2 perplexity scoring | 0.901 |
| Cross-Perplexity | Two-model perplexity comparison | 0.891 |
| Fast-DetectGPT | Conditional probability curvature | 0.890 |
| Binoculars | Cross-entropy ratio between two LMs | 0.836 |
| DivEye | Surprisal diversity | 0.730 |
Linguistic Heuristics
| Engine | Signal | AUC |
|---|---|---|
| Structural Analysis | Em-dash usage, sentence uniformity | 0.836 |
| Linguistic Markers | AI-preferred phrases ("delve", "tapestry"...) | 0.713 |
| Formulaic Patterns | Cliche openings and closings | 0.698 |
| Vocabulary Richness | Type-token ratio, hapax legomena | 0.583 |
| Readability Uniformity | Cross-paragraph consistency | 0.581 |
| Burstiness | Per-sentence perplexity variance | 0.582 |
| Sentiment & Hedging | Hedging and forced balance | 0.522 |
The linguistic heuristics are weak on their own. They are kept because they fail independently of the neural classifiers, which is what makes them useful as tiebreakers rather than as evidence.
Scoring
The overall score is a logistic model over the engine scores, fitted on SlopBench. The fitted parameters are in app/calibration.json, and every number in the fit's report, tests/eval/slopbench/FINDINGS.md, is measured on kinds of writing the fit never saw. docs/CALIBRATION.md explains each field in the JSON and how to regenerate it.
- Weights from a fit, not by hand. Each engine's score is turned into log-odds and weighted by the model, with weights kept non-negative. An engine earns weight only for what it adds once the others are known, so engines that fail together do not count twice. In English, 8 of the 23 engines carry weight (Structural, Desklib, Fakespot, SuperAnnotate, Formulaic, Readability, Binoculars and Burstiness). The other 15 add nothing on top of them, and every one is still shown in the report.
- Bands set on human text. The output is mapped so that 45 is where the top 5% of human texts begin, 55 the top 2% and 80 the top 0.5%.
- Short texts held back. Short English texts are pulled toward a neutral
score by
words / (words + 5); other languages use a fitted short-text term. Scripts written without spaces (Chinese, Japanese, Thai and others) skip it. - Other languages. A separate fit with a per-language offset, placed so 5% of human text scores above 45, and a support status: supported for German, Spanish, French, Italian, Japanese, Dutch, Polish, Portuguese and Russian; experimental for Arabic and Korean; not yet reliable for Hindi, Turkish and Chinese.
- Confidence from the score. Low under 80 words, in a language that is not yet reliable, or between 35 and 65; medium in an experimental language or between 15 and 80; high otherwise.
Up to v1.1 the score was a hand-weighted blend anchored on four classifiers. tests/eval/FINDINGS.md keeps that history, including the Fakespot bias against pre-1920 prose that led to it.
Configuration
SlopTotal detects CPU, RAM and GPU at startup and picks a profile. Everything
can be overridden with environment variables; see .env.example.
| Profile | When chosen (RAM) | CPU | GPU | Notes |
|---|---|---|---|---|
| Lite | below 8 GB | 2 cores | None | Fewer workers; still loads every model |
| Standard | 8 GB or more | 4 cores | None | Default for most laptops |
| Performance | 16 GB or more | 6+ cores | CUDA optional | Pool replicas, max throughput |
Profiles change workers and replicas, not which engines run. Every profile loads all models: about 8.3 GB of RAM once loaded (an estimate) and about 9 GB on disk. Per-engine memory and latency, measured on one machine, are in docs/MODELS.md.
NVIDIA GPU: requirements.txt installs the CPU-only torch wheel. To run the
models on the GPU, replace it with a CUDA build of the same torch version (keep
the version: upgrading torch can move scores):
pip uninstall -y torch
pip install torch==<installed version> --index-url https://download.pytorch.org/whl/cu130 --extra-index-url https://pypi.org/simple
python -c "import torch; print(torch.cuda.is_available())"   # True
cu130 needs an NVIDIA driver with CUDA 13 support and covers RTX 20xx through
50xx; pick another index from pytorch.org
for older cards. With CUDA and at least 4 GB of VRAM, startup selects the
performance profile and the banner shows Device: cuda. All models run in
fp32, so scores match the CPU to three decimals.
High-RAM CPU servers (e.g. 64 GB, no GPU): you automatically get the performance profile. With no CUDA, all inference stays on CPU but you can run more concurrent workers and model pool replicas:
# Tune for a 64 GB CPU-only server
export SLOPTOTAL_PROFILE=performance
export SLOPTOTAL_TORCH_THREADS=8
export SLOPTOTAL_FULL_WORKERS=8
export SLOPTOTAL_SNIPPET_WORKERS=6
export SLOPTOTAL_MAX_CONCURRENT_FULL=4
export SLOPTOTAL_POOL_FAKESPOT=2
export SLOPTOTAL_POOL_TMR=2
./scripts/start.sh
| Variable | Default | Purpose |
|---|---|---|
SLOPTOTAL_PROFILE |
auto | lite, standard or performance |
SLOPTOTAL_RETENTION_DAYS |
30 |
Delete reports after N days (0 keeps them) |
SLOPTOTAL_DIRECT_DAILY_LIMIT |
0 (no limit) |
Calls per client IP per UTC day that start an analysis from outside the first-party origins below; for a public instance |
SLOPTOTAL_FIRST_PARTY_ORIGINS |
sloptotal.com, the extension, localhost | Regex of browser origins allowed by CORS and not counted by the daily limit |
SLOPTOTAL_ALLOW_PRIVATE_URLS |
off | Let URL scans reach private or intranet hosts (blocked by default) |
SLOPTOTAL_DATA_DIR |
project-root data/ |
Directory for stored reports and the database |
SLOPTOTAL_DB_NAME |
sloptotal.db |
Database filename inside the data directory |
SLOPTOTAL_DB_TIMEOUT |
30.0 seconds |
SQLite connection timeout |
SLOPTOTAL_DB_BUSY_TIMEOUT |
5000 milliseconds |
SQLite busy timeout |
SLOPTOTAL_CACHE_ENABLED |
true |
Enable result caching (true, 1 or yes, case-insensitive) |
SLOPTOTAL_DEVICE |
auto-detected | Override inference device with cpu or cuda; otherwise CUDA is used when available |
SLOPTOTAL_RESERVED_CORES |
2 |
CPU cores reserved when calculating usable analyzer cores |
SLOPTOTAL_SHORT_LANE_WORDS |
350 |
Word-count threshold for the short-text lane |
SLOPTOTAL_SHORT_WORKERS |
4 |
Short-text worker count |
SLOPTOTAL_MAX_CONCURRENT_SHORT |
2 |
Concurrent short-text scan limit enforced by the queue manager |
SLOPTOTAL_MAX_CONCURRENT_SNIPPET |
4 (2 in lite) |
Concurrent snippet scan limit |
SLOPTOTAL_POOL_BERT_RAID |
1 (see below) |
BERT RAID model pool replicas |
SLOPTOTAL_POOL_E5 |
1 (see below) |
E5 model pool replicas |
SLOPTOTAL_POOL_FAKESPOT |
1 (see below) |
Fakespot model pool replicas |
SLOPTOTAL_POOL_TMR |
1 (see below) |
TMR model pool replicas |
HF_HOME |
./models |
Where model weights are cached |
Startup profiles populate unset settings before the analyzer reads its fallback
defaults. Explicit environment values take precedence. The lite profile sets
the snippet concurrency limit to 2; other profiles use 4. On CPU, the
performance profile sets all four classifier pools above to 2 when RAM is at least
32 GB; otherwise these pools use 1, including CUDA profiles.
FAQ
Can AI detectors be trusted? Not blindly. No detector, this one included, should be the only evidence for an accusation. That is why SlopTotal shows all 23 votes, how much they agree, and its measured false-positive rate. Short text (under about 80 words) and heavily edited AI text are unreliable for every detector.
Does it detect ChatGPT, Claude, Gemini, Llama and Mistral? The evaluation corpus includes GPT-4, ChatGPT, Llama and Mistral output. The classifiers were trained on a wider mix. Newer models are covered as far as they share those fingerprints; the evaluation harness lets you measure any model you care about.
Will it flag classic literature or formal writing? Not in our tests: none of the 26 passages from Austen, Melville, Kafka, Machiavelli and others is flagged. Pre-1920 prose is part of the evaluation precisely because naive detectors fail on it.
Is my text stored or shared? It is processed on the server you run. Reports are kept for 30 days (configurable) so report links work, and nothing is sent to an outside service.
Can it detect AI-generated code? No, and we do not claim it can: in testing the engines never flagged human code but never caught machine-written code either. The Site check reports which AI app builder produced a website, which is a different question.
Troubleshooting
| Symptom | Fix |
|---|---|
TypeError: unsupported operand type(s) for | at startup |
Python 3.9 or older; use 3.10+ |
An engine reports Model loading failed |
Check disk space and network for the first model download, then restart; python scripts/smoke_test.py shows which engine fails |
| First scan is slow | Models are loading; later scans take seconds |
| A URL scan says "private network address" | Intended; set SLOPTOTAL_ALLOW_PRIVATE_URLS=1 to scan intranet pages |
Project layout
app/            FastAPI backend: engines, ensemble, site fingerprints, API
web/            The web UI (Jinja2 templates, vanilla JS, no build step)
tests/          Unit tests (seconds, no downloads) and tests/eval/ accuracy harness
scripts/        smoke_test.py (end-to-end) and the model drift check
benchmarks/     Speed and load scripts
ARCHITECTURE.md covers the internals. AGENTS.md is a short brief for contributors and AI coding assistants.
Newer open detectors we measured
Detector models keep appearing on Hugging Face, each with its own accuracy claim. Before adding any, we score them on the same two corpora. September 2026, standalone, 180 RAID texts plus the 26 literary passages:
| Model | RAID AUC | Literary bias (lower is better) | Status |
|---|---|---|---|
| Gradient (DeBERTa-v3-large) | 0.998 | 0.033 | Next engine to add |
| Vanguard (ModernBERT-large) | 0.998 | 0.037 | Candidate; poorly calibrated at 0.5 |
| Earlybird-fast (82M) | 0.913 | 0.040 | Candidate for fast snippet scans |
| rasbt ModernBERT | 0.864 | 0.000 | Not added |
RAID-trained models score near 1.0 on RAID by construction and need a different test set first. The full table, the models we excluded and why, and the raw scores are in tests/eval/FINDINGS.md. The roadmap is in TODO.md.
Related projects and reading
- RAID benchmark (ACL 2024): adversarial AI text detection dataset used in our evaluation
- Detecting the Machine (2026): cross-architecture detector benchmark; ensembles beat single detectors
- EditLens: human vs AI-edited vs AI-generated classification
- GLTR: visual token-rank inspection, the inspiration for our GLTR engine
- distil-labs/distil-ai-slop-detector: a 270M Gemma detector that runs in the browser
- sloptotal-extension: the Chrome extension
Contributing
Contributions are welcome, especially new engines with measurements. Start with CONTRIBUTING.md.
- Good first issues: small tasks that name the files to change
- Report a bug
- Request a feature
- Propose a new engine
- Ask a question or share results
If SlopTotal is useful to you, a star helps other people find it.
License
MIT. Model weights keep their own licenses; see THIRD_PARTY_LICENSES.md.