
nagi-studio/nagi-bench
nagi-studio/nagi-bench has 78 GitHub stars and 35 forks. GitHot measured 0 stars in 24 hours. Last checked 2026-11-15 07:35 UTC. Last push 2026-11-12.
Measured star growth
- in 24h
- 0
- in 7 days
- Collecting history
- in 15 days
- Collecting history
- in 1 month
- Collecting history
Net star changes over overlapping periods, not daily totals. Missing measurements are left blank. Stars measure attention, not software quality.
About
One-shot LLM eval cases by NAGI STUDIO - same prompt, different agents (model + harness), runnable artifacts side by side.
AIREADME.en.md
Original
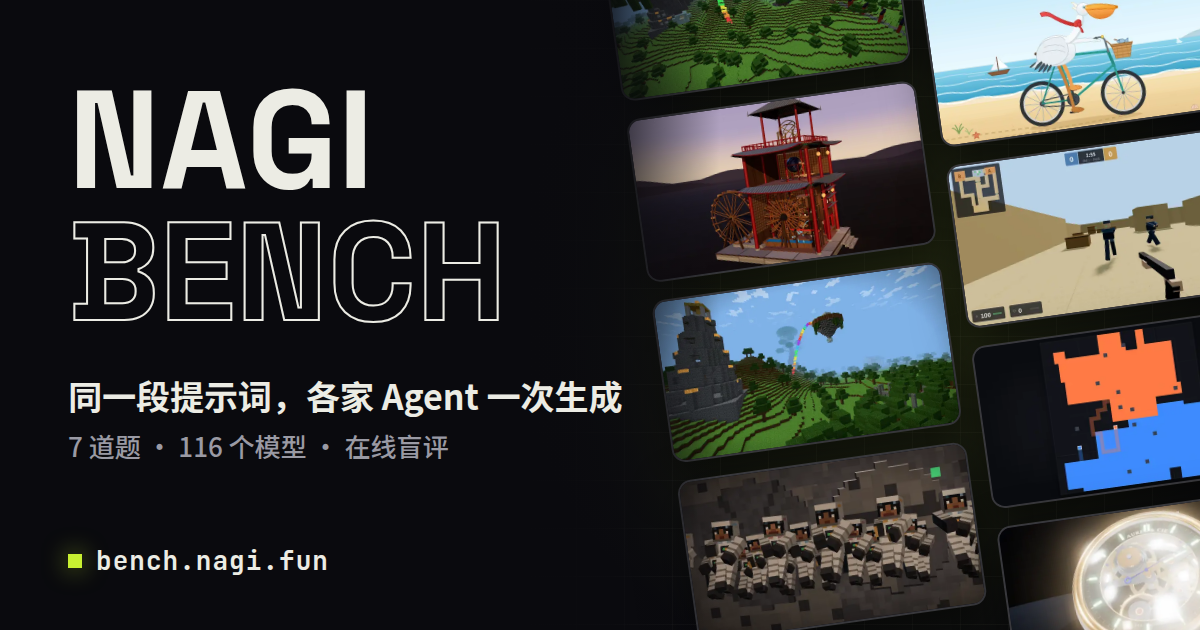
NAGI BENCH
Same prompt, different models, one shot, no retries.
One-shot LLM eval cases by NAGI STUDIO: model x harness x effort combinations take the same task, ship runnable artifacts side by side, and face anonymous blind votes.
中文 | English



Cases · How it works · Core idea · Registry · Contributing · License
Cases
Each case is one fixed prompt that every agent uses verbatim, in one shot. Click a thumbnail or case name to open its blind-vote page.
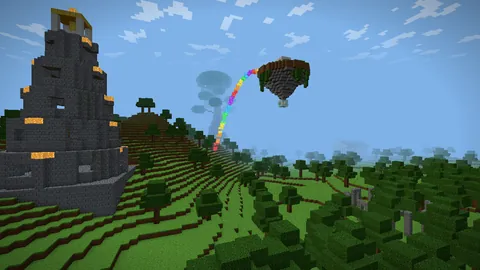 Mythos Craft · Single-file HTML A playable Minecraft-style 3D voxel world mythos-craft
|
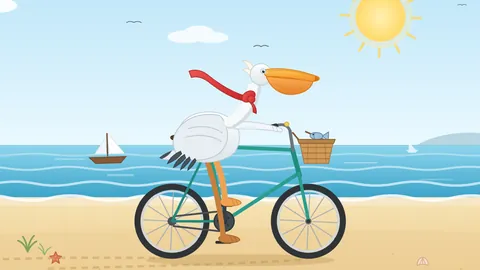 Pelican by the Sea · SVG The classic eval: draw a pelican riding a bicycle, in code pelican-cycling
|
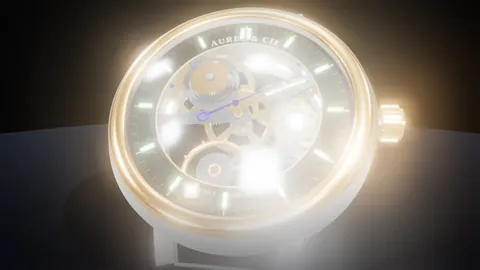 Skeleton Watch · Single-file HTML A rotatable, exploded-view 3D skeleton watch skeleton-watch
|
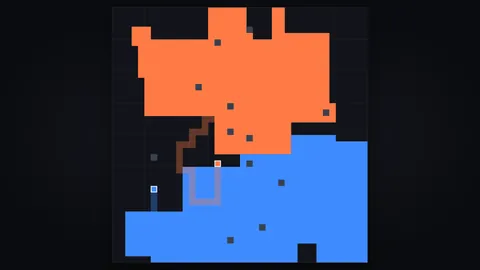 Turf War · JS agent Territory-grabbing agents battle head-to-head, ranked by wins, not votes turf-war
|
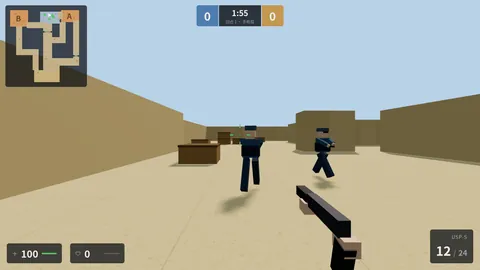 CS Dust2 5v5 · React project A from-scratch 3D FPS in React + three.js cs-dust2
|
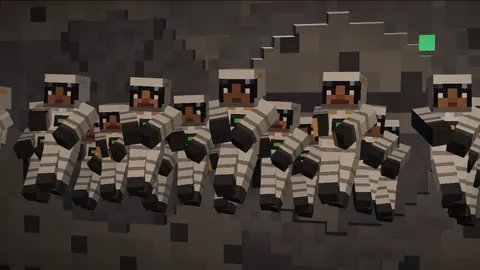 Zhang Beihai: Meteorite Bullet · Three.js project A long-horizon 3D film adapted from The Three-Body Problem beihai-meteorite
|
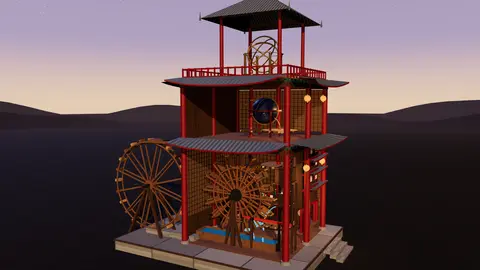 Water-Driven Clock Tower · 3D project A 30-second physics-driven 3D explainer of Su Song's water-powered astronomical clock tower water-clock-tower
|
Full prompts live in
cases.json.
How it works: Arena blind battles & leaderboard
- Arena (default): each case pits two anonymous artifacts against each other — vote A / B / Neither, and identities reveal only after you vote.
- Demo Show: switch top-right to browse everything, grouped by model; a model with several harnesses can be viewed singly or side by side.
- Community leaderboard: unlocks after 3 votes, ranked by Bradley-Terry scores (the LMSYS Chatbot Arena approach); "Neither" counts separately as both-bad. Votes feed a sitewide crowdsourced pool, guarded by Turnstile.
Core idea: Model + Harness = Agent
A model is just weights; wrap it in a runtime and it becomes an agent that can actually do the work. That agent is the unit this bench evaluates.
- Model: the weights and inference engine itself — GPT-5.5, Gemini 3.1 Pro, Claude Fable 5. Reasoning effort counts as part of the model: the same weights at high vs low effort feel like two different models, so judging a model while ignoring its effort isn't fair play. This bench defaults to max and labels the effort of every combination.
- Harness: the product/scaffolding wrapping the model — Codex CLI, Cursor, AntiGravity, the Claude web app. It controls tool calls, system prompts, context management and continuation strategy, and often shapes the outcome as much as the model does.
- So a different harness means a different agent and a separate entry (GPT-5.5 Pro and GPT-5.5 running in Codex CLI at xhigh are two agents from the same model family).
- Only the out-of-the-box harness is evaluated: do not load skills / plugins / MCP servers / custom system prompts — they shift the output as much as swapping the harness does and break comparability between agents. If maintainers agree an enhanced output is still worth preserving, the run may set
"evaluation": "showcase"and remain viewable only; it is excluded from Arena, voting, rankings, and qualification counts.
Registry
More than a hundred model x harness x effort combinations have run these cases, from Anthropic, OpenAI, Google, DeepSeek, xAI, Moonshot, Zhipu, Alibaba and more. Browse the artifacts at bench.nagi.fun; the full list is below.
Show the full Registry table (sorted by vendor and version, generated by CI)
This table is generated from
models/*.jsonbybun scripts/update-registry.ts; CI re-syncs it automatically after merge — contributors need not hand-edit it.
| Model / Vendor | Runs | Harness · Effort |
|---|---|---|
| Claude Opus 5.5 Anthropic |
39 | Claude Code · Max / xhigh / High / Medium / Low Kiro · High |
| Claude Sonnet 5.5 Anthropic |
17 | Claude Code · High / Max / xhigh |
| Claude Haiku 5.5 Anthropic |
06 | Claude Code · High |
| Claude Fable 5.2 Anthropic |
07 | Claude Code · High |
| Claude Fable 5.1 Anthropic |
06 | Claude Code · High |
| Claude Opus 5 Anthropic |
16 | Claude Code · Max / xhigh / High |
| Claude Fable 5 Anthropic |
11 | Claude Web App · Max Claude Code · High / Max / xhigh Cursor · High |
| Claude Sonnet 5 Anthropic |
01 | Claude Code · Max |
| Claude Opus 4.8 Anthropic |
08 | Claude Code · Max / xhigh |
| Claude Opus 4.7 Anthropic |
05 | Claude Code · Max Cursor · Max |
| Claude Opus 4.6 Anthropic |
04 | Claude Code · Max Cursor · Max |
| Claude Sonnet 4.6 Anthropic |
03 | Claude Code · Max Cursor · High |
| Claude Opus 4.5 Anthropic |
02 | Cursor · Thinking |
| Claude Haiku 4.5 Anthropic |
02 | Claude Code · Default |
| GPT-6.1 Sol OpenAI |
20 | Codex CLI · High / Max / xhigh |
| GPT-6 Astra OpenAI |
09 | Codex CLI · Max / xhigh Pi · xhigh |
| GPT-6 Sol OpenAI |
07 | Codex CLI · xhigh |
| GPT-5.6-Sol OpenAI |
11 | Codex CLI · ultra / max / xhigh |
| GPT-5.6-Terra OpenAI |
05 | Codex CLI · ultra / xhigh |
| GPT-5.5 Pro OpenAI |
03 | ChatGPT Web · Extended Pro |
| GPT-5.5 OpenAI |
03 | Codex CLI · xhigh |
| GPT-5.4 OpenAI |
06 | Cursor · xhigh Codex CLI · xhigh |
| GPT-5.3 Codex OpenAI |
02 | Cursor · xhigh |
| GPT-5.2 OpenAI |
02 | Cursor · xhigh |
| Gemini 3.8 Flash |
06 | AntiGravity · High |
| Gemini 3.7 Flash |
08 | AntiGravity · Low / Medium / High |
| Gemini 3.6 Flash |
05 | AntiGravity · High |
| Gemini 3.5 Flash |
06 | AntiGravity · High Cursor · Default Google AI Studio · High |
| Gemini 3.1 Pro |
11 | AntiGravity · High Cursor · Default Gemini Web · Deep Think Google AI Studio · High |
| DeepSeek V4.1 Flash 1017 DeepSeek |
18 | DeepSeek Harness · High / Low / Max |
| DeepSeek V4.1 Flash DeepSeek |
08 | DeepSeek Harness · High WorkBuddy · High |
| DeepSeek V4 Pro 0831 DeepSeek |
01 | DeepSeek Harness · Minimal |
| DeepSeek V4 Pro 0813 DeepSeek |
21 (showcase 01) |
DeepSeek Harness · High / Max DeepSeek Harness · Minimal · High Codex CLI · xhigh |
| DeepSeek-V4-Pro DeepSeek |
05 | Claude Code · Max Qoder · Max Open Code · High |
| DeepSeek V4 Flash 0731 DeepSeek |
05 (showcase 01) |
Claude Code · Max OMP · Default |
| DeepSeek V4 Flash DeepSeek |
02 | Claude Code · Max Reasonix · Max |
| Grok 4.7 xAI |
06 | Grok Build TUI · High |
| Grok 4.6 xAI |
06 | Grok Build TUI · High |
| Grok 4.5 xAI |
03 | Grok Build TUI · High |
| Grok Build xAI |
02 | Grok Build TUI · Max |
| Grok 4.3 xAI |
02 | Cursor · Default |
| Composer 2.5 xAI |
05 | Cursor · Max / Default Grok Build TUI · Default |
| Hy4 Tencent |
06 | WorkBuddy · High |
| Hy4 Preview Tencent |
09 (showcase 06) |
WorkBuddy · High / Default |
| Nex-N2-Pro Nex-AGI |
02 | Claude Code · Max |
| Mistral Medium 3.5 Mistral AI |
02 | Vibe · Thinking |
| ERNIE 4.5 Baidu |
05 | Wenxin Work Task Mode · Professional Skill |
| Doubao 2.1 Pro ByteDance |
05 | Doubao Work · High |
| Doubao Seed 2.0 Pro ByteDance |
01 | Doubao Web · Pro Mode |
| Doubao Seed 2.0 Mini ByteDance |
01 | Doubao Web · Fast Mode |
| MiMo V2.5 Xiaomi |
03 | MiMo Code · High |
| MiMo v2.5 Pro Xiaomi |
03 | Claude Code · Max MiMo Code · Max |
| MiMo v2.5 Pro UltraSpeed Xiaomi |
05 | Web · Default |
| Kimi K3.1 Pro Moonshot AI |
21 | Claude Code · High / Max Kimi Code · Max |
| Kimi K3 Moonshot AI |
12 | Claude Code · Max Kimi Code · Max Kimi Web · Max |
| Kimi K2.7-Code Moonshot AI |
04 | Kimi Code · Thinking Qoder · Default |
| Kimi K2.6 Moonshot AI |
02 | Kimi Code · Thinking |
| MiniMax M3 MiniMax |
03 | MiniMax Code Web · Thinking Qoder · Default |
| MiniMax M2.7 MiniMax |
01 | MiniMax Code Web · Thinking |
| GLM-5.3 Flash Zhipu AI |
11 | DeepSeek Harness · Max WorkBuddy · High |
| GLM-5.2 Zhipu AI |
05 | ZCode · Max Qoder · Max |
| GLM-5.1 Zhipu AI |
01 | ZCode · Max |
| GLM-5 Turbo Zhipu AI |
03 | ZCode · Thinking |
| Qwen3.8-Max-Preview Alibaba |
06 | Qoder · Default Qwen Studio Web · Thinking |
| Qwen3.8-Max Alibaba |
05 (showcase 05) |
Qwen Work Assistant · Auto |
| Qwen3.7-Max Alibaba |
03 | Qoder · Default |
| Qoder Ultimate Alibaba |
05 | Qoder · Default / Max |
| Qwen 3.8 27B Alibaba |
01 (showcase 01) |
OMP · Default |
| Qwen 3.6 27B Alibaba |
01 (showcase 01) |
OMP · Default |
| Step 3.7 Flash StepFun |
02 | Claude Code · High |
| Spark X2.5 iFlytek |
01 | Spark Web Harness · Reasoning |
| Spark X2 iFlytek |
01 | Web · Reasoning |
| Inkling Thinking Machines Lab |
02 | Tinker Web · xHigh |
| Inkling-Small Thinking Machines Lab |
03 | Tinker Web · xHigh |
Contributing a run
Contributions are data-only — no code changes: you add two files. Full rules live in AGENTS.md (the contributor / AI-agent guide).
Four steps:
- Generate: run the prompt from
cases.jsonverbatim in your harness, once (every skill / plugin disabled, no MCP, no custom system prompt). - Add the artifact: preferably at
outputs/<base-model>/<harness-effort>/<case-id>.<ext>(e.g.outputs/gpt-5-5-pro/chatgpt-web-extended-pro/pelican-cycling.svg). - Register it:
models/<agent-id>.json(new file for a new combination; add torunsfor an existing one) withartifactDirpointing at the artifact folder (example below). - Check and open a PR: run
bun scripts/validate-data.tsuntil it passes, then open a PR with the template's proof screenshot — your harness showing the model name and effort while generating (paste it into the PR; do not commit image files).
{
  "label": "GPT-5.5 Pro",
  "vendor": "OpenAI",
  "harness": "ChatGPT Web",
  "effort": "Extended Pro",
  "artifactDir": "gpt-5-5-pro/chatgpt-web-extended-pro",
  "order": 20,
  "runs": {
    "pelican-cycling": {
      "note": {
        "zh": "在哪个 Harness 里、什么思考档位、是否一次生成、是否有修复",
        "en": "Which harness, what effort level, one-shot or fixed"
      },
      "contributor": "your-github-username"
    }
  }
}
Rules (enforced by CI — the build fails otherwise):
agent-ids use dash-only lowercase letters / digits (e.g.doubao-seed-2-0-pro) and are stable identities; withoutartifactDir, artifacts default tooutputs/<agent-id>/;artifactDiruses one or two lowercase dash-case path segments (preferably<base-model>/<harness-effort>); it is only the file location and does not affect vote or leaderboard identity;- a bilingual provenance
noteis required per run — it is where this repo's credibility comes from (which harness, what effort, one-shot or fixed); - every declared run must have its artifact;
- multiple versions of the same combination x case go in an array under
runs.<case-id>, and every version after the first needs a distinctfilename (e.g.pelican-cycling-2.svg); - set
contributorto your GitHub username — the site shows your avatar linked to your profile next to the run; - skill/plugin/non-standard outputs require maintainer approval plus
"evaluation": "showcase", must disclose the setup in both notes, and stay permanently excluded from blind voting and rankings; - fill in
harnessandefforttruthfully for new combinations: the case page renders Harness / Effort metadata chips from these fields and auto-matches brand icons for the model, vendor and harness (via lobe-icons) — contributors never touch icons.
PRs get data validation from CI; merges to main rebuild the site automatically (usually instant, at most 6 hours).
If you are an AI agent (Claude Code / Codex / Cursor, etc.), expand this
- The unit you contribute is one Agent = a model × the harness you run in. The
<agent-id>(lowercase letters / digits / dashes) encodes that pairing — e.g.gpt-5-5-pro,claude-fable-5-cc(cc = Claude Code). The same model in a different harness is a different Agent with a different id. The<agent-id>is the vote and leaderboard identity; do not rename it just to reorganize files. - There are six cases right now, defined in
cases.jsonand listed under "Cases" above. The prompt lives incases.json— use it verbatim, do not paraphrase. Note:turf-wardoes not accept artifact PRs — to keep earlier policies unscoutable, every run is executed and submitted personally by the maintainer Nagi (@Nagi-ovo); open an issue to request a model. - To find what's missing: read
cases.json(all cases) andmodels/*.json(what each Agent has run) — a<case-id>absent from an Agent's json is an open slot; any row in the script-generated Registry table above whose "Runs" count is below the number of cases is an Agent missing a case; a brand-new Agent can fill every open case. - Then follow the two-file flow above, write a bilingual
note(how the artifact was produced — one-shot or fixed), and runbun scripts/validate-data.tsuntil it passes before opening a PR.
Repo layout and local commands
outputs/<artifact-dir>/<case-id>.<ext>  raw model artifacts (HTML / SVG), filename = case id
models/<agent-id>.json                  agent registry: label / vendor / harness / effort / artifactDir / order / run notes
cases.json                              case definitions (bilingual prompts, maintainer-owned)
scripts/validate-data.ts                data validation (CI runs it on every PR)
scripts/update-registry.ts              README Registry table generation (CI auto-syncs after merge)
bun scripts/validate-data.ts   # the same data validation CI runs (run this before submitting)
bun scripts/update-registry.ts # optional: preview the Registry tables locally; CI syncs them after merge
The site and vote-backend source lives in the private nagi-bench-site repo, deployed on Cloudflare Pages; this repo is the site's data source.
License
- Code (
scripts/and other code files): MIT - Benchmark data and artifacts (
cases.json,models/,outputs/): CC BY 4.0. Please credit "NAGI BENCH (https://bench.nagi.fun/)".