
mqcomplab/MDANCE
mqcomplab/MDANCE has 146 GitHub stars and 15 forks. GitHot measured 0 stars in 24 hours. Last checked 2026-11-09 20:49 UTC. Last push 2026-11-02.
MDANCE: Hyper-efficient tools to process molecular dynamics simulations.
Measured star growth
- in 24h
- 0
- in 7 days
- Collecting history
- in 15 days
- Collecting history
- in 1 month
- Collecting history
Net star changes over overlapping periods, not daily totals. Missing measurements are left blank. Stars measure attention, not software quality.
README.md
OriginalMDANCE: Molecular Dynamics Analysis with N-ary Clustering Ensembles
A transformative framework for analyzing molecular dynamics simulations through advanced clustering algorithms
Installation • The Problem • Our Solution • Key Features • Quick Start • Publications • Contributing
The Problem
Molecular Dynamics (MD) simulations generate terabytes of conformational data, but extracting meaningful biological insights remains challenging. Traditional clustering methods struggle with:
- Exponential complexity - MD datasets are massive.
- Poor initialization - leading to suboptimal clustering.
- Pathway ambiguity - difficulty identifying dominant biological pathways.
- Native structure prediction - accurately identifying biologically relevant states.
- Pairwise similarity limitations - traditional methods only compare pairs of objects, causing performance bottlenecks.
- Stochastic variability - lack of reproducibility across clustering runs.
Our Solution
MDANCE introduces a novel n-ary similarity framework that transforms how we analyze MD trajectories. Our algorithms provide:
- Linear scaling - from O(N²) to O(N) complexity.
- Deterministic results - reproducible science.
- Biological relevance - algorithms designed for structural biology.
- Unprecedented accuracy - validated against experimental structures.
- Extended similarity techniques - swift identification of high and low-density regions in linear time.
Key Features
🪄 NANI - Smart k-means Initialization
Breakthrough: Deterministic centroid initialization using n-ary comparisons to identify high-density regions and select diverse initial conformations.
Key Advantages:
- Solves the seed selection challenge in k-means clustering.
- Creates compact, well-separated clusters that accurately find metastable states.
- Provides consistent cluster populations across replicates.
- Dramatically reduces runtime: clusters 1.5 million HP35 frames in ~40 minutes.
🧩 HELM - Scalable Hierarchical Clustering
Breakthrough: Combines k-means efficiency with hierarchical flexibility using n-ary difference functions.
Performance:
- Retains k-means computational efficiency while enabling arbitrary partitions.
- Successfully analyzes simulations with over 1.5 million frames.
- Achieves in ~34 minutes what traditional HAC requires 29 hours for 1.5 million frames.
- Builds hierarchy without expensive pairwise distance matrices.
🌳 DIVINE - Deterministic Divisive Clustering
Breakthrough: Top-down hierarchical clustering framework that recursively splits clusters based on n-ary similarity principles.
Key Features:
- Completely avoids O(N²) pairwise distance matrices.
- Deterministic anchor initialization with NANI.
- Multiple cluster selection criteria including weighted variance metric.
- Single-pass design enables efficient resolution exploration.
- Matches or exceeds bisecting k-means quality with reduced runtime.
🌿 mdBIRCH - Online Clustering for MD Data
Innovation: Adapts BIRCH CF-tree to molecular dynamics data with RMSD-calibrated merge tests.
Key Capabilities:
- Online clustering that processes frames as they arrive.
- Merge test calibrated directly to RMSD for physical interpretability.
- Completely avoids pairwise distance matrices.
- Scales near-linearly with number of frames.
- Two practical protocols: RMSD-anchored runs and blind sweep analysis.
- Processes hundreds of thousands of frames on a single CPU core in seconds.
🔍 SHINE - Pathway Analysis
Transformative: Hierarchical clustering that identifies dominant biological pathways from enhanced sampling data.
Key Advantages:
- Streamlines analysis of pathway ensembles from multiple MD simulations.
- Integrates n-ary similarity with cheminformatics-inspired tools.
- Identifies most representative pathway within each pathway class.
- Provides insight into dominant biomolecular transformation mechanisms.
- Lower computational cost than Fréchet distance approaches.
- Successfully applied to alanine dipeptide and adenylate kinase systems.
🌈 PRISM - Pathway Representation & Clustering
Innovation: Pathway Representation via Intrinsic Structural Medoids enables efficient clustering of multiple molecular pathways.
Key Capabilities:
- Summarizes each pathway by a compact set of representative conformations (structural medoids).
- Clusters pathways using hierarchical agglomerative clustering based on weighted average Hausdorff distance.
- Three construction strategies for medoid selection: global sharing, per-pathway independent, or two-stage refinement.
- Enables efficient analysis of enhanced sampling and multiple pathway ensembles.
- Designed for multi-trajectory pathway comparison and classification.
🎯 eQual - O(N) Clustering
Innovation: Transforms O(N²) Radial Threshold Clustering into O(N) algorithm with novel seed selection and tie-breaking.
Key Features:
- Uses k-means++ for efficient seed selection.
- Employs extended similarity indices for deterministic results.
- Eliminates memory-intensive pairwise RMSD matrices.
- Produces compact and well-separated clusters matching RTC quality.
🏆 PRIME - Native Structure Prediction
|
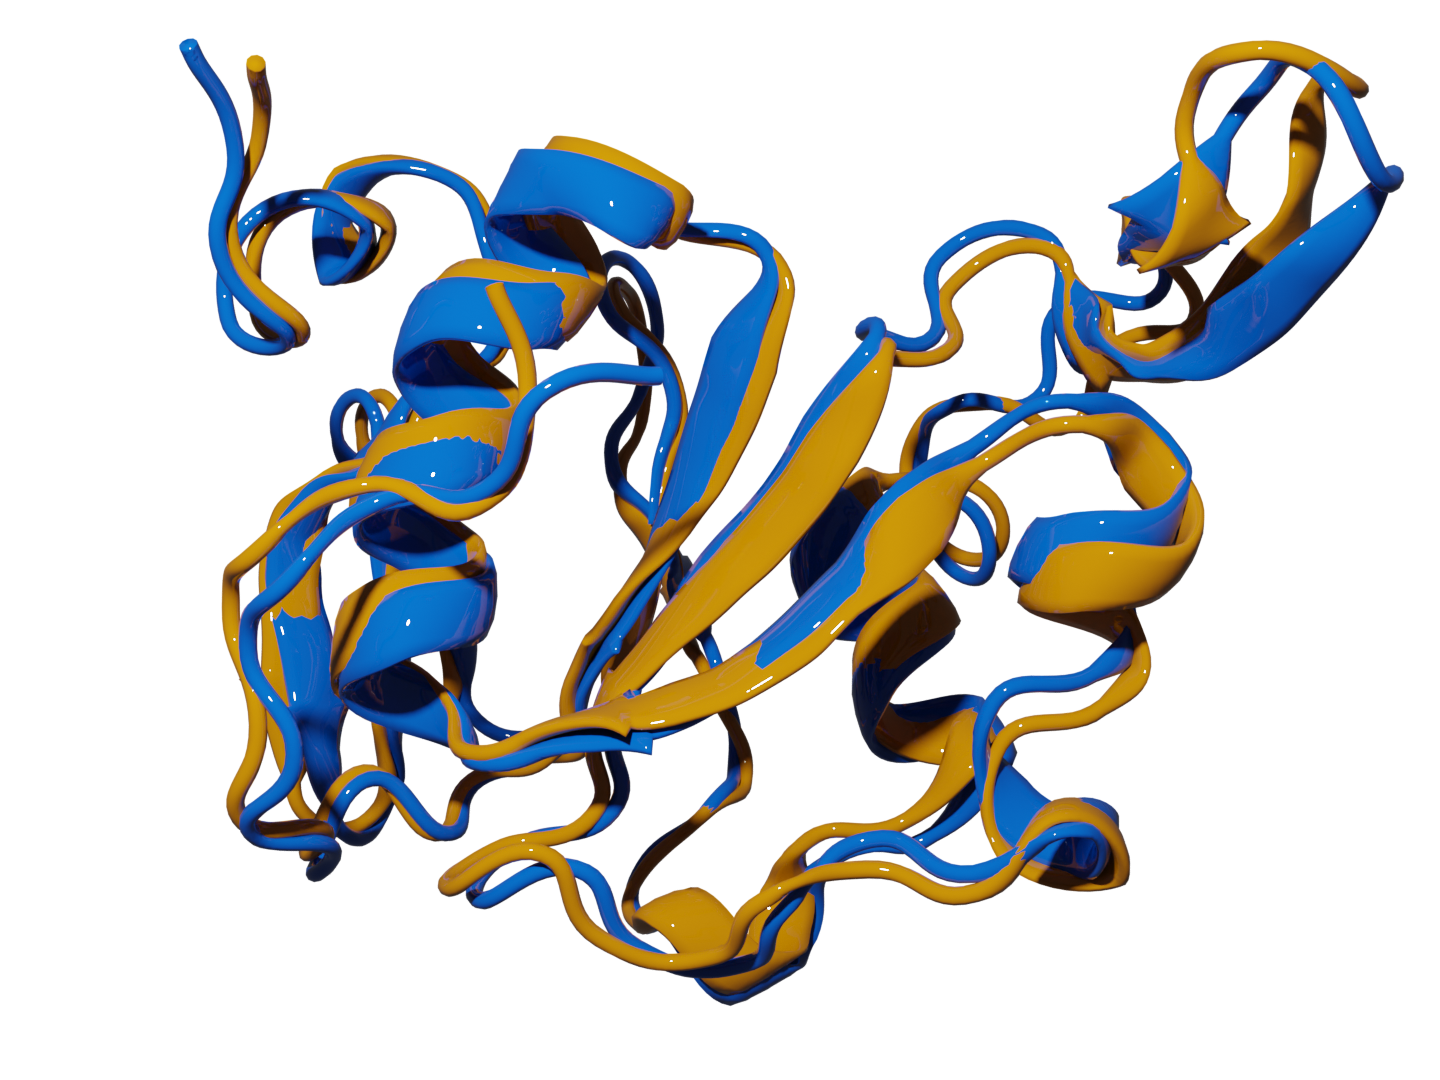
Game Changer: Predicts native protein structures from simulation data with unprecedented accuracy. Scientific Validation: PRIME (Protein Retrieval via Integrative Molecular Ensembles) perfectly mapped all structural motifs in benchmark studies and consistently identified native structures within 2Å RMSD of experimental data. |
|
Algorithm Comparison
| Algorithm | Complexity | Type | Key Feature | Best Use Case |
|---|---|---|---|---|
| NANI | O(N) | Initialization | Deterministic centroids | k-means improvement |
| HELM | O(N) | Hybrid hierarchical | k-means + hierarchical fusion | Large-scale analysis |
| DIVINE | O(N) | Divisive hierarchical | Top-down splitting | Multi-resolution analysis |
| mdBIRCH | O(N) | Online clustering | Streaming data processing | Large-scale trajectories |
| SHINE | O(N) | Hierarchical | Pathway analysis | Enhanced sampling |
| PRISM | O(N) | Hierarchical | Structural medoid representation | Multi-pathway comparison |
| eQual | O(N) | Flat clustering | Linear RTC replacement | General purpose |
| PRIME | O(N) | Post-processing | Native structure prediction | Structure validation |
Quick Start
Installation
pip install mdance
Basic Usage
import mdance
import numpy as np

# Load your MD trajectory data
data = np.load('trajectory.npy')

# Use NANI for optimal clustering initialization
from mdance.cluster.nani import KmeansNANI
nani = KmeansNANI(data, n_clusters=5, metric='MSD')
optimal_centroids = nani.initiate_kmeans()

# Cluster with standard *k*-means
from sklearn.cluster import KMeans
kmeans = KMeans(5, init=optimal_centroids[:5], n_init=1)
labels = kmeans.fit_predict(data)
Tutorials
- NANI Tutorial - Smart k-means initialization.
- HELM Tutorial - Scalable hierarchical clustering.
- DIVINE Tutorial - Deterministic divisive clustering.
- mdBIRCH Tutorial - Online clustering for streaming MD data.
- SHINE Tutorial - Pathway analysis.
- PRISM Tutorial - Pathway representation and clustering.
- eQual Tutorial - Linear-time clustering.
- PRIME Tutorial - Native structure retrieval.
Publications
Our methods are backed by peer-reviewed research:
- NANI: J. Chem. Theory Comput. 2024; J. Chem. Inf. Model. 2026
- HELM: J. Chem. Inf. Model. 2025
- DIVINE: J. Chem. Inf. Model. 2026
- mdBIRCH: J. Chem. Theory Comput. 2026
- SHINE: J. Chem. Inf. Model. 2025
- PRISM: Digital Discovery 2026
- eQual: J. Chem. Inf. Model. 2025
- PRIME: J. Chem. Theory Comput. 2024
If you use MDANCE, please cite the paper of each method you use. BibTeX entries for all papers are in CITATION.bib.
Impact
MDANCE is enabling researchers to:
- Accelerate drug discovery by rapidly identifying biologically relevant conformations.
- Understand disease mechanisms through precise pathway analysis.
- Validate computational models against experimental structures.
- Scale analyses to massive simulation datasets.
Contributing
We welcome collaborations and contributions! Whether you're a:
- Computational biologist with novel analysis needs.
- Method developer interested in extending our framework.
- Structural biologist with challenging datasets.
Get involved:
- Open an issue for bug reports or feature requests.
- Submit a pull request for improvements.
- Reach out to discuss research collaborations.
Funding
This research was supported by the National Institute of General Medical Sciences of the National Institutes of Health under award number R35GM150620.
Explore related projects
tensorflow/tensorflow
An Open Source Machine Learning Framework for Everyone
201,427 starshuggingface/transformers
🤗 Transformers: the model-definition framework for state-of-the-art machine learning models in text, vision, audio, and multimodal models, for both inference and training.
168,711 starsAUTOMATIC1111/stable-diffusion-webui
Stable Diffusion web UI
165,261 starsComfy-Org/ComfyUI
The most powerful and modular diffusion model GUI, api and backend with a graph/nodes interface. The fastest local inference engine in the world.
145,835 stars